Pass4Test NCA-GENM 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1tmvRRbUAQAeOdgdQNwLp85JlvIXejmYg
우리 Pass4Test에서는 여러분을 위하여 정확하고 우수한 서비스를 제공하였습니다. 여러분의 고민도 덜어드릴 수 있습니다. 빨리 성공하고 빨리NVIDIA NCA-GENM인증시험을 패스하고 싶으시다면 우리 Pass4Test를 장바구니에 넣으시죠 . Pass4Test는 여러분의 아주 좋은 합습가이드가 될것입니다. Pass4Test로 여러분은 같고 싶은 인증서를 빠른시일내에 얻게될것입니다.
| Section | Weight | Objectives |
|---|---|---|
| Multimodal Data | 15% | - Applications and use cases - Handling and integrating text, image, and audio data |
| Data Analysis & Visualization | 10% | - Visualization techniques for multimodal data - Data preprocessing and feature engineering |
| Software Development & Engineering | 15% | - Integration and deployment of multimodal AI systems - Python libraries for multimodal AI |
| Performance Optimization | 10% | - Monitoring and improving system efficiency - Techniques for optimizing AI performance |
| Experimentation | 25% | - A/B testing - Experimental design - Model evaluation and comparison - Hypothesis testing |
| Trustworthy AI | 5% | - Ethical considerations in AI development - Ensuring fairness and transparency |
| Core ML & AI Knowledge | 20% | - Basic concepts and terminology - Key algorithms and techniques |
최근 IT 업종에 종사하는 분들이 점점 늘어가는 추세하에 경쟁이 점점 치열해지고 있습니다. IT인증시험은 국제에서 인정받는 효력있는 자격증을 취득하는 과정으로서 널리 알려져 있습니다. Pass4Test의 NVIDIA인증 NCA-GENM덤프는IT인증시험의 한 과목인 NVIDIA인증 NCA-GENM시험에 대비하여 만들어진 시험전 공부자료인데 높은 시험적중율과 친근한 가격으로 많은 사랑을 받고 있습니다.
질문 # 42
You have developed a multimodal model that predicts stock prices using news articles (text), historical stock data (time-series), and company financial reports (tabular data). You want to deploy this model using NVIDIA Triton Inference Server. Assume you have preprocessed the data and have individual models for each modality. What is the recommended approach to configure Triton for efficient and scalable multimodal inference?
정답:C
설명:
Using Triton's Ensemble Modeling feature (B) is the most efficient approach. It allows you to define a pipeline that includes preprocessing, individual modality models, and fusion logic within a single Triton model, simplifying deployment and management. This approach optimizes inter-model communication and reduces client-side overhead.
질문 # 43
You are building a multimodal model that takes images and text descriptions as input to generate new images. You want to evaluate the impact of different image encoders (ResNet50, Efficient Net) on the generated image quality and relevance to the text prompt. Which evaluation metric(s) would be MOST appropriate for this task?
정답:C
설명:
FID measures the distance between the feature distributions of generated and real images, indicating image quality and diversity. CLIP Score measures the similarity between the generated image and the text prompt, evaluating relevance. IS more suitable for evaluating unimodal image generation. Perplexity and BLEU score are for text generation.
질문 # 44
You want to evaluate the performance of an AI model. Which of the following is a method for AI model evaluation?
정답:B
설명:
Valid model evaluation requires measuring performance on held-out data the model has not seen during training - this is the foundational principle behind train/validation/test splits and cross-validation, and it exists specifically to estimate how the model will generalize to genuinely new data, rather than how well it memorized patterns specific to its training set. Option B correctly describes this: sampling from a portion of the dataset explicitly excluded from training and calculating accuracy on it.
Options C and D both violate this principle by evaluating on the training set itself, which produces optimistically biased performance estimates: a model - particularly an overparameterized deep learning model - can achieve very high training accuracy or very low training loss simply by memorizing training examples (overfitting) without that performance transferring to new data at all. Reporting training-set accuracy (C) or training-set loss (D) as an evaluation of "performance" conflates fit-to-training-data with generalization, the central failure mode that held-out evaluation is designed to catch. Option A describes a qualitative, subjective process - interviewing developers - that provides no quantitative, reproducible performance measurement and is not a recognized model evaluation methodology.
This principle extends further in rigorous experimentation: a validation set used repeatedly for hyperparameter tuning can itself become "leaked" through repeated selection, which is why a separate, untouched test set is typically reserved for final, one-time performance reporting.
Reference: Experimentation domain - held-out evaluation, train/validation/test methodology, avoiding overfitting bias in reported metrics.
질문 # 45
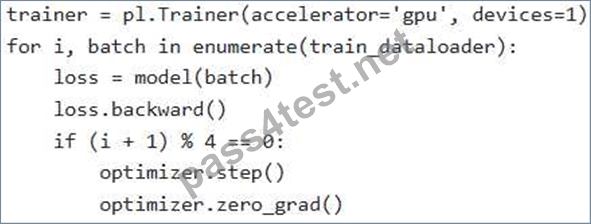
Consider the following Python code snippet using PyTorch Lightning and a Hugging Face Transformers model for multimodal classification. Which of the following code snippets is MOST appropriate to perform gradient accumulation in this context, assuming you want to accumulate gradients over 4 batches?



정답:D
설명:
PyTorch Lightning provides a built-in argument in the 'Trainer' class to easily enable gradient accumulation. Setting will accumulate gradients over 4 batches before performing an optimizer step.
질문 # 46
You are building a multimodal model to predict stock prices using financial news articles (text), historical stock prices (time-series), and company logos (images). You have preprocessed the data and are ready to train your model. Which of the following architectures would be MOST suitable for effectively integrating these three modalities?
정답:A,C
설명:
Combining a Transformer for text, an LSTM for time-series, and a CNN for images with a late fusion approach allows each modality to be processed by a suitable architecture and then combined to generate a final prediction. Using transformers in each modality with shared Transformer decoder can efficiently integrate and predict stock prices using cross modal attention . A simple feedforward network is unlikely to capture the temporal dependencies in the time-series data or the complex relationships between modalities. Ensembling independent models doesn't allow for cross-modal learning. Converting all data into text might lose valuable information from the other modalities. Therefore, hybrid architecture combining transformers, LSTMs, and CNNs with cross-modal attention or late fusion would be most effective.
질문 # 47
......
Pass4Test 안에는 아주 거대한IT업계엘리트들로 이루어진 그룹이 있습니다. 그들은 모두 관련업계예서 권위가 있는 전문가들이고 자기만의 지식과 지금까지의 경험으로 최고의 IT인증관련자료를 만들어냅니다. Pass4Test의 NCA-GENM문제와 답은 정확도가 아주 높으며 한번에 패스할수 있는 100%로의 보장도를 자랑하며 그리고 또 일년무료 업데이트를 제공합니다.
NCA-GENM최신 덤프데모 다운로드: https://www.pass4test.net/NCA-GENM.html
참고: Pass4Test에서 Google Drive로 공유하는 무료 2026 NVIDIA NCA-GENM 시험 문제집이 있습니다: https://drive.google.com/open?id=1tmvRRbUAQAeOdgdQNwLp85JlvIXejmYg