P.S. Free 2026 Microsoft AI-103 dumps are available on Google Drive shared by Dumpkiller: https://drive.google.com/open?id=1oQW82ZFTk_SzbGphtYYit87aeUgA7W8e
Many job-hunters want to gain the competition advantages and become the hottest people which the companies rush to get. But if they want to realize that they must boost some valuable AI-103 certificate to raise their values and positions. The AI-103 certificate enjoys a high reputation among the labor market circle and is widely recognized as the proof of excellent talents and if you are one of them and you want to pass the test smoothly you can choose our AI-103 Practice Questions.
| Section | Objectives |
|---|---|
| Topic 1: Implement Natural Language Processing Solutions | - Translation and multilingual support - Text analytics and summarization - Language understanding and intent recognition |
| Topic 2: Plan and Manage Azure AI Solutions | - Responsible AI principles and governance - Azure AI resource provisioning and configuration - Model selection and lifecycle management |
| Topic 3: Implement Computer Vision Solutions | - OCR and document intelligence - Image classification and object detection |
| Topic 4: Knowledge Mining and Information Retrieval | - Indexing and semantic search - Azure AI Search configuration - RAG (Retrieval Augmented Generation) patterns |
| Topic 5: Develop Generative AI Applications and Agents | - AI agents architecture
|
>> AI-103 Reliable Braindumps Book <<
With Dumpkiller, you can trust that you're accessing authentic and error-free AI-103 exam practice questions. These questions are available in three different formats: PDF questions files, desktop practice test software, and web-based practice test software. All three formats contain genuine AI-103 Practice Questions that will effectively prepare you for the final exam.
NEW QUESTION # 156
You have a Microsoft Foundry project that uses Azure Al Search to ground an agent in internal documentation.
After a recent content update, users report that the agent ' s answers have become less accurate.
You need to identify whether the retrieved content is negatively influencing the model ' s generated responses.
Which observability signal should you review?
Answer: D
Explanation:
The correct observability signal is B. groundedness evaluation metrics . In a RAG solution, the key diagnostic question is whether the generated answer is supported by the retrieved context. Microsoft Foundry' s built-in evaluator reference defines Groundedness as the metric that measures how grounded the response is in the retrieved context, with scoring that indicates whether the model's claims are supported by the provided source material.
This matches the issue after a content update. If retrieved chunks are stale, misleading, incomplete, or poorly aligned with the user query, groundedness results can show that generated responses are not reliably supported by the retrieved documentation. The RAG evaluator guidance explains that groundedness focuses on whether the response avoids content outside the grounding context, while other process metrics such as retrieval evaluate how relevant the retrieved chunks are. Latency traces are useful for performance troubleshooting, not response accuracy. Indexer status can reveal ingestion failures, but it does not show whether retrieved content is influencing generated answers negatively. Prediction drift is a model monitoring concept and is not the primary signal for RAG grounding quality. Reference topics: Microsoft Foundry observability, RAG evaluators, groundedness, retrieved context, and response quality evaluation.
Topic 1, Case Study Contoso, Ltd
Overview
Contoso, Ltd is a multinational retail company that builds, deploys, and manages generative Al and agent- based solutions by using Microsoft Foundry.
Identity Environment:
Contoso uses Microsoft Entra ID for identity management, authentication, and authorization capabilities that enable agents to access organizational resources and services.
Contoso recently formed a new Al engineering team named Agent1Dev Team to optimize and maintain existing Al solutions.
The team collaborates with solution architects, DevOps engineers, and security engineers to design, implement, monitor, and secure Al applications.
Contoso also has a team named Agent1Test Team that is responsible for validating Al solutions before the solution deployments.
Generative Environment:
Contoso has a Microsoft Foundry deployment that contains two projects named Project1 and Project2.
Project1
Project1 contains a customer support agent named Agent1 that assists customers with product inquiries and troubleshooting requests.
Agent1 has the following configurations:
* Agent1 uses a base model deployment.
* A safety evaluation pipeline is NOT enabled.
* Tool invocation approval workflows are NOT enabled.
* Conversation memory constraints are NOT configured.
Agent1 interacts with customers by using digital support channels and answers general questions about Contoso products.
Project1 is deployed to an Azure region located in the European Union (EU).
Agent1Dev Team will use Project1 to optimize and maintain Agent1.
Project2
Project2 contains a deployed video generation model. The marketing department at Contoso has access to Project2 and plans to use the model to develop a video creation solution.
Development of the solution is incomplete.
Data Environment:
Contoso stores product-related information in Azure resources that support Al applications.
The Azure environment contains an Azure Blob Storage account named storage1 that stores product detail sheets for all the Contoso products.
The product sheets include specifications, feature descriptions, and product support information that Agent1 can use to answer customer questions. The product sheets are stored in the PDF format.
Problem Statement:
Contoso identifies the following issues:
* Agent1 has only general knowledge of the Contoso products.
* A recent chat interaction with Agent1 was analyzed for sentiment. The results of the analysis have NOT been processed yet.
* Agent1 does NOT use the detailed product information in the product sheets stored in storage1 when responding to customer questions.
* The finance department at Contoso reports that vendor invoices must be reviewed manually to ensure that the invoices match the terms defined in the vendor contracts. The invoices contain tables, logos, and varied layouts that make the documents difficult to process consistently.
Requirement:
Planned Changes:
Contoso plans to implement the following changes:
* Implement a solution for Project1 that analyzes the vendor invoices by evaluating both the visual layout and the textual content of the invoices, so that the invoice details can be verified against the vendor contract terms.
* Update the base model deployment used by Agent1 and standardize the model version to ensure continuity and consistent responses.
* Enable Agent1 to retrieve and use the detailed product information from the product sheets stored in storage1.
* Implement an indexing solution for the product sheets that Agent1 can use to answer customer questions.
* Complete the development of the video creation solution.
Technical Requirements:
Contoso identifies the following technical requirements:
* The model deployment used by Agent1 must support scalable, high-throughput generative Al workloads and dynamically scale to handle variable customer support traffic, without requiring reserved throughput capacity.
* The product sheets must be processed by using an indexing pipeline that enables semantic and vector search, so that Agent1 can retrieve the relevant product information.
* Responses generated by using the product sheet information must be relevant, complete, and accurate.
* Agent1 must be able to use the product sheets to answer natural language questions about product details.
* The model version used by Agent1 must remain consistent to ensure stable responses.
* The data processed by the model must remain within the EU.
Safety and Compliance Requirements:
Contoso identifies the following security and compliance requirements:
* API keys must NOT be used to access Foundry-deployed models.
* Access to the Azure resources must follow the principle of least privilege.
* The developers at Contoso must authenticate to Microsoft Foundry resources by using Microsoft Entra authentication.
* Access to Project1 must be assigned to the members of Agent1Dev Team by using a security group named SC_Agent1_Dev.
* Access to Project1 must be assigned to the members of Agent1Test Team by using a security group named SC_Agent1_Test.
* Agent1 must never reveal customer information, even if a document that contains customer data is added erroneously to the product sheet repository in storage1.
* The product sheets might contain images that include embedded text. Agent1 must be protected from malicious instructions potentially hidden within the images.
Business Information:
Contoso identifies the following business requirements:
* Users that interact with Agent1 must have a personalized experience in future interactions, including the ability for Agent1 to retain conversation context and recall relevant information from previous interactions.
* Agent1 must answer questions only about the products sold by Contoso.
NEW QUESTION # 157
You need to recommend a solution to support the planned changes and technical requirements for Agent1 to use the product information stored in storage1.
What should you include in the recommendation?
Answer: B
NEW QUESTION # 158
Hotspot Question
You have a Python application collects customer comments before posting them to a public forum.
You need to send a text comment to Azure AI Content Safety and return the self-harm severity from the response.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.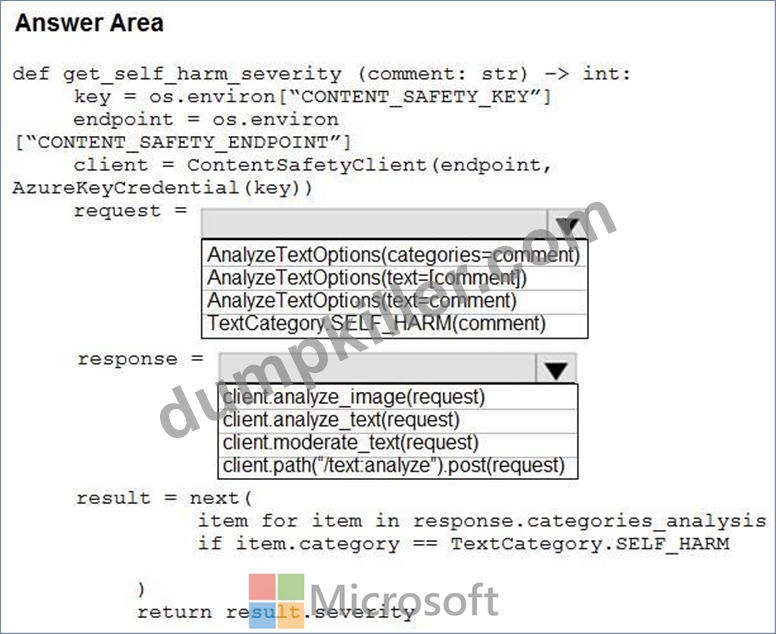
Answer:
Explanation: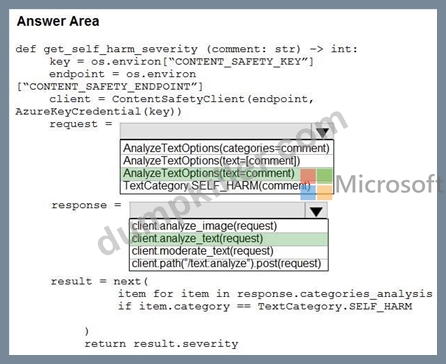
Explanation:
Box 1: AnalyzeTextOptions(text=comment)
To set up the request in your Python script, you must use AnalyzeTextOptions(text=comment), passing the text as a single string rather than a list.
Example:
Build the request options focusing on Text analysis
# You can optionally restrict analysis to specific categories
request_options = AnalyzeTextOptions(
text=user_comment,
categories=[TextCategory.SELF_HARM]
Box 2: client.analyze_text(request)
You must use client.analyze_text(request)
1. Send the request: Call client.analyze_text(request) to retrieve the multi-severity results.
2. Extract the self-harm result: Locate the self-harm categories from the response list.
3. Return the severity: Access the .severity attribute
Reference:
https://learn.microsoft.com/en-us/python/api/overview/azure/ai-contentsafety-readme
NEW QUESTION # 159
You have a Microsoft Foundry project that contains an agent.
The agent uses a knowledge source built from documents stored in Azure Blob Storage. The documents include digitally scanned PDFs that contain multipage tables.
You have an ingestion job that extracts only plain text, causing loss of table structure, headings, and page-number metadata.
Users frequently ask questions that require the retrieval of specific table rows across the pages.
You need to configure an ingestion job for a Retrieval Augmented Generation (RAG) pipeline that performs optical character recognition (OCR) on scanned PDFs, preserves tables and headings as structure-aware chunks, and stores page-number metadata with each chunk.
How should you configure the ingestion job?
Answer: A
Explanation:
Use OCR and page-level chunking.
Structure Preservation: OCR combined with document layout analysis (such as layout-aware or page-level chunking) detects visual structures like tables, headers, and reading order.
Row-Level Granularity: Page-level chunking retains the boundaries and context of multipage tables, enabling the RAG system to isolate and retrieve specific rows effectively.
Metadata Enrichment: Processing documents page-by-page allows the ingestion pipeline to automatically tag each extracted text chunk with its source page-number metadata.
Incorrect:
[not C]
Use page-level OCR extraction and store each page as a single chunk:
While this captures page numbers, storing an entire page as a single chunk introduces too much noise. It prevents the model from pinpointing specific table rows and often exceeds the optimal context window size for precise RAG retrieval.
[Not D]
Use basic parsing and fixed-size chunking:
Basic parsing cannot read digitally scanned PDFs, resulting in empty or completely garbled text.
Furthermore, fixed-size chunking splits text at arbitrary character limits, which destroys table structures and splits individual rows across different chunks.
Reference:
https://pub.towardsai.net/unlocking-key-technologies-in-document-parsing-81bfe20d741b
NEW QUESTION # 160
Hotspot Question
You have a Microsoft Foundry project that contains an agent named PaymentAgent.
PaymentAgent includes a function tool that issues customer refunds by using an external API.
You are creating a workflow in YAML.
You need to ensure that the workflow pauses for human approval and continues with the refund step only after approval is granted.
How should you complete the workflow definition? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.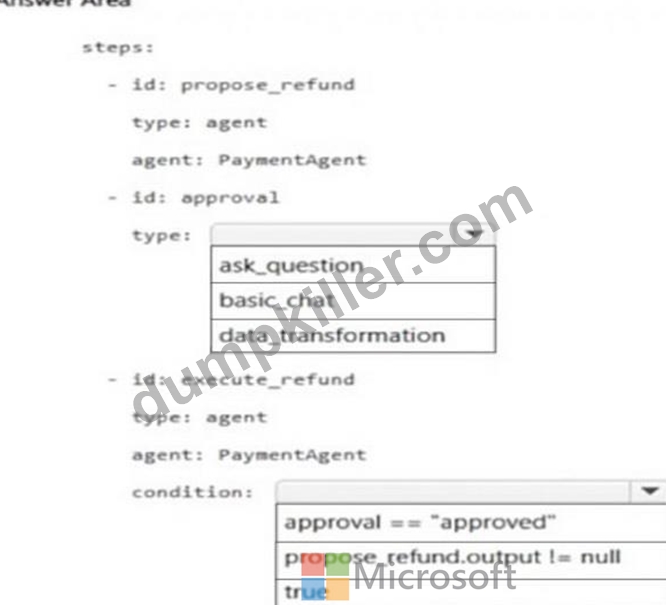
Answer:
Explanation: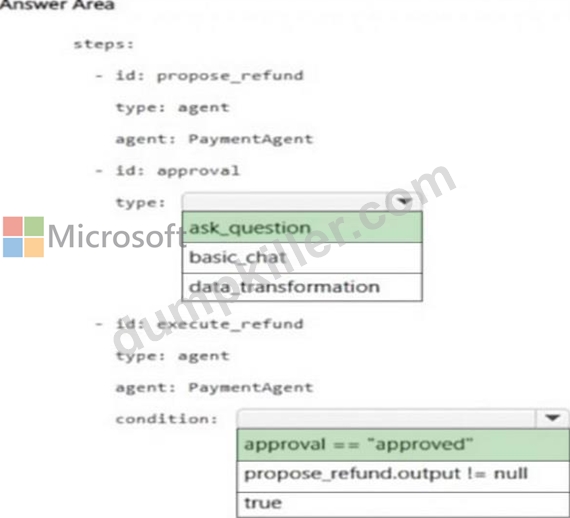
NEW QUESTION # 161
......
Our experts group collects the latest academic and scientific research results and traces the newest industry progress in the update of the AI-103 study materials. Then the expert team processes them elaborately and compiles them into the test bank. Our system will timely and periodically send the latest update of the AI-103 Study Materials to our clients. So the clients can enjoy the results of the latest innovation and achieve more learning resources. The credits belong to our diligent and dedicated professional innovation team and our experts.
Vce AI-103 Torrent: https://www.dumpkiller.com/AI-103_braindumps.html
DOWNLOAD the newest Dumpkiller AI-103 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1oQW82ZFTk_SzbGphtYYit87aeUgA7W8e