P.S. Free 2026 Linux Foundation CKAD dumps are available on Google Drive shared by BraindumpsPass: https://drive.google.com/open?id=1h7zOahqYlGfD8-rt5und9aH2WkBQsmHL
BraindumpsPass has been going through all ups and downs tested by the market, and now our CKAD exam questions have become perfectly professional. We never circumvent the difficulties of our CKAD study materials happened on the road as long as there is bright at the end, and it is the satisfactory results you want. And we have helped so many of our customers achieve their certifications according to our CKAD learning guide.
| Certification Vendor: | Linux Foundation |
|---|---|
| Exam Name: | Certified Kubernetes Application Developer (CKAD) Exam |
| Exam Number: | CKAD |
| Real Exam Qty: | 15-20 |
| Available Languages: | English, Simplified Chinese, Japanese |
| Certificate Validity Period: | 2 years |
| Exam Price: | $445 USD |
| Passing Score: | 66% |
| Exam Duration: | 120 minutes |
| Exam Format: | Hands-on tasks, Command-line based, Performance-based |
| Related Certifications: | Certified Kubernetes Administrator (CKA) Certified Kubernetes Security Specialist (CKS) |
| Recommended Training: | Introduction to Kubernetes Kubernetes for Developers (LFD259) |
| Exam Registration: | Official Registration |
| Sample Questions: | Linux Foundation CKAD Sample Questions |
| Exam Way: | Online, remotely proctored |
| Pre Condition: | No formal prerequisites |
| Official Syllabus URL: | https://training.linuxfoundation.org/certification/certified-kubernetes-application-developer-ckad/ |
Our company according to the situation reform on conception, question types, designers training and so on. Our latest CKAD exam torrent was designed by many experts and professors. You will have the chance to learn about the demo for if you decide to use our CKAD quiz prep. We can sure that it is very significant for you to be aware of the different text types and how best to approach them by demo. At the same time, our CKAD Quiz torrent has summarized some features and rules of the cloze test to help customers successfully pass their CKAD exams.
The CKAD certification is highly valued in the industry and is recognized as a benchmark for Kubernetes application development skills. It is designed to help developers demonstrate their expertise in the field and gain recognition for their skills and knowledge. Linux Foundation Certified Kubernetes Application Developer Exam certification is also useful for employers who are looking to hire skilled Kubernetes developers and want to ensure that their candidates have the necessary skills and knowledge to perform the job.
Linux Foundation Certified Kubernetes Application Developer (CKAD) exam is a certification exam that tests a candidate's ability to design, build, configure, and expose cloud-native applications for Kubernetes. It is a performance-based exam that is conducted in a live environment, and candidates need to solve a set of challenges using a command-line interface. CKAD Exam is designed to test a candidate's knowledge of Kubernetes and its ecosystem, and their ability to leverage its features to create and deploy cloud-native applications.
NEW QUESTION # 237
You are building a Kubernetes application that involves a microservice architecture with multiple pods for each service. One of your services requires a sidecar container to handle logging and monitoring. How would you design the pod structure and define the relationships between the application container and the sidecar container?
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Define Pod Specification:
- Create a pod definition file (e.g., 'pod.yaml').
- Include the 'apiVersion', 'kind', 'metadata' (name, labels), and 'spec' sections.
2. Define Application Container:
- Within the 'spec.containerS section, define the primary application container:
- 'name': Provide a descriptive name for the application container (e.g., 'app').
- Simage: Specify the Docker image for the application.
- 'ports': Define any ports that the application exposes.
- 'resources': (Optional) Specify resource requests and limits for the application container.
3. Define Sidecar Container.
- Add another container definition within the 'spec-containers' section for the sidecar:
- 'name': Provide a name for the sidecar container (e.g., Slogger').
- 'image': Specify the Docker image for the sidecar container (e.g., "busybox'
- 'command': Define the command to run within the sidecar. This might involve using a logging agent, monitoring tool, or any other custom script.
- 'volumeMountss: (Optional) If the sidecar needs access to shared data, mount volumes here.
4. Define Shared Volumes (Optional):
- If necessary, create a 'spec-volumes' section to define any shared volumes that both containers can access. This might include:
- 'emptyDir': For temporary data that only exists within the pod.
- 'persistentVolumeClaim': To use a persistent volume claim for shared data that persists beyond pod restarts.
5. Configure Container Relationships:
- Ensure that the 'name' of the application container and sidecar container is the same as the 'name' used in the 'volumeMounts' section.
Example YAML: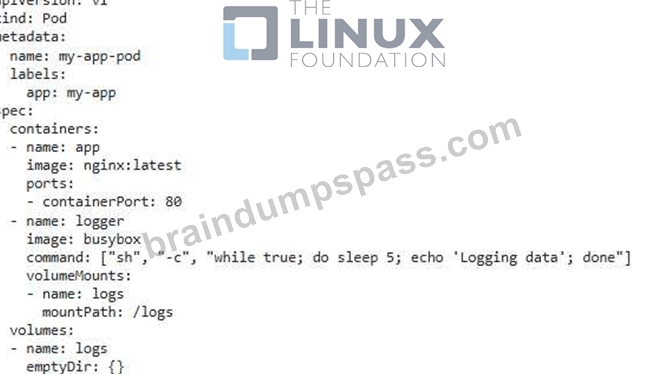
- The pod named 'my-app-pod' includes two containers: 'app' (the primary application) and 'logger' (the sidecar). - The 'loggers container uses a 'command' to simulate logging activity. - Both containers can access the 'logs' volume, which is an empty directory. Important Note: - The sidecar container should ideally be configured to interact with the application container. This might involve using shared volumes, environment variables, or inter-process communication mecnanisms to facilitate data exchange or Signal passing. - Remember to adapt the example to your specific application requirements, choosing the appropriate container images, commands, and volumes.]
NEW QUESTION # 238
You are tasked with deploying a stateful application, a distributed database, that requires persistent storage and consistent ordering of pods. The application's pods need to communicate With each other using a specific port (5432). How would you configure a StatefulSet to achieve this?
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Create the StatefulSet YAML: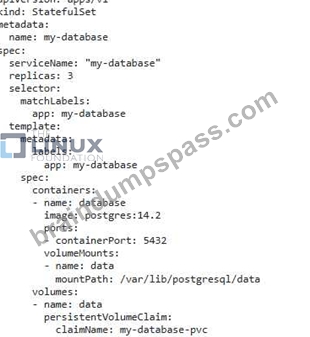
2. Create a PersistentVolumeClaim (PVC):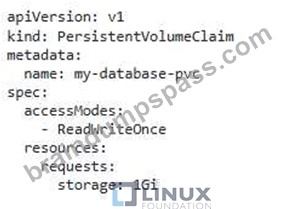
3. Apply the StatefulSet and PVC: bash kubectl apply -f statefulset.yaml kubectl apply -f pvc.yaml 4. Check the StatefuISet and Pods: bash kubectl get statefulsets my-database kubectl get pods -l app=my-database - StatefulSet This defines the desired state for the database pods, ensuring tneir order and persistent storage. - serviceName: This field defines the service name used to access the database instances. - replicas: Defines the desired number of database instances (3 in this example). - selector: Matches pods with the "app: my-database" label. - template: Defines the pod template to use for each instance. - containers: Contains the database container definition. - ports: Exposes the database's internal port (5432) to the outside world. - volumeMounts: Mounts the persistent volume claim to the container's storage directory. - volumes: Defines the volume to use, in this case, a persistent volume claim. - persistentVolumeClaim: Links the StatefulSet to the PVC- - PVC (my-database-pvc): Requests a persistent volume of 1 Gi for each database pod. This ensures data persistence between restarts. - accessM0des: ReadWriteOnce: Allows only one pod to access the volume at a time. - resources-requests-storage: Specifies the storage request for each PVC- This setup ensures that each database pod: - Has a unique name based on its ordinal position within the StatefulSet - Has persistent storage using the PVC. - Can communicate with otner pods through the defined service. - Maintains consistent ordering, essential for distributed database functionality
NEW QUESTION # 239
You're tasked with deploying a containerized application that handles sensitive customer datm The security policy mandates that only containers With specific security profiles can access the dat a. How would you implement Pod Security Standards (PSS) in your Kubernetes cluster to enforce this requirement?
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Define Pod Security Policies:
- Create a Pod Security Policy (PSP) resource using a YAML file.
- Define the allowed security profiles based on your security requirements.
- You can restrict things like:
- Container privileges (root or non-root)
- Allowed capabilities (e.g., 'SYS_ADMINS)
- Security context constraints (e.g., read-only root filesystem)
- Access to host resources (e.g., devices, networking)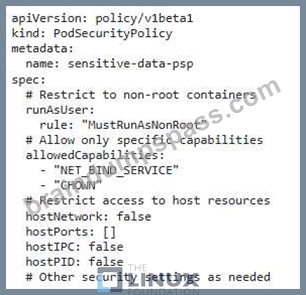
2. Apply the Pod Security Policy: - Use 'kubectl apply -f sensitive-data-psp.yamr to apply the PSP to your cluster. 3. Modify Your Deployment (or other workload) to IJse the PSP: - Update the Deployment (or other workload) YAML file to include a 'securitycontext' field that references the PSP you created. - Ensure that the container image and configuration adhere to the constraints defined in the PSP.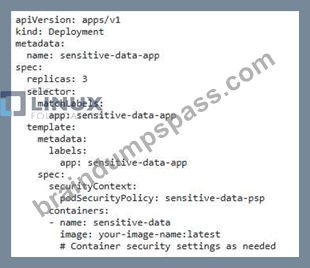
4. Verify Deployment: - Use ' kubectl get pods -l app=sensitive-data-app' to ensure your pods are running. - The poos should now adhere to the specified security constraints defined by the PSP 5. Enforcement: - Kubernetes will prevent pods from running if they violate the constraints defined in the PSP - This provides a layer of security enforcement for sensitive applications. Note: PSPs are deprecated in Kubernetes 1.25 and are replaced by Pod Security Admission. For newer Kubernetes versions, you would use Pod Security Admission to enforce these security constraints. ]
NEW QUESTION # 240
You are developing a microservice that communicates with a message broker to process asynchronous events. You want to implement a robust and reliable communication pattern using Kubemetes. How can you set up a Kubernetes deployment for this scenario?
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Deploy the Message Broker:
- Deploy the message broker of your choice (e.g., RabbitMQ, Kafka, etc.) using a 'Deployment and a 'Service'
- Configure the broker with the necessary settings, such as authentication, security, and message queues.
2 Create a Microservice Deployment
- Create a ' Deployments for your microservice.
- Define a container that runs your microservice application and includes the necessary dependencies tor interacting with the message broker
3. Use a ConfigMap for Broker Credentials:
- Create a 'ConfigMap' to store sensitive information like the brokers connection string, username, and password.
- Mount this 'ConfigMap' as a volume into the microservice container.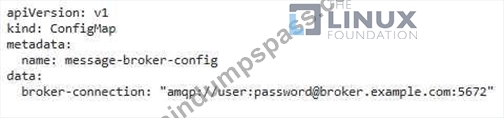
4. Configure Communication with the Broker: - Configure your microservice to connect to the message broker using the credentials from the mounted 'configMap' - Set up a consumer to receive messages from the appropriate queue and a producer to send messages to the required queue. 5. Utilize a Service for Broker Connectivity: - Create a 'Service' of type 'ClusterlP' that exposes the message broker within the Kubernetes cluster. - Ensure that the microservice container can access the broker through this service. 6. Consider a Sidecar Container: - Optionally, you can use a sidecar container to manage communication with the broker. - The sidecar container can act as a proxy or middleware, handling connections, authentication, and other tasks related to message broker communication. 7. Implement Robust Communication: - Implement retries and backoff mechanisms in your code to handle temporary network failures or broker outages. - Consider using a dedicated message broker client library that provides features like message acknowledgement, transaction support, and fault tolerance. Note: This approach ensures reliable communication between the microservice and the message broker. The use of a 'ConfigMap' for credentials, a dedicated service for broker connectivity, and the optional sidecar container contribute to a robust and scalable solution for asynchronous event processing.
NEW QUESTION # 241
You have a custom resource definition (CRD) named that represents a database resource in your Kubernetes cluster. You want to create a custom operator that automates the creation and management of these database instances. The operator should handle the following:
- Creation: When a new 'database.example.com' resource is created, the operator should provision a new PostgreSQL database instance on the cluster-
- Deletion: When a 'database.example_com' resource is deleted, the operator should clean up the corresponding PostgreSQL database instance.
- Scaling: If the 'spec-replicas' field of the 'database-example.com' resource is updated, the operator should scale the number of database instances accordingly.
Provide the necessary Kubernetes resources, custom operator code, and steps to implement this operator. You should use the 'Operator Framework' to build and deploy this operator
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Create the CRD: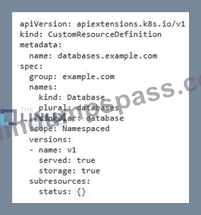
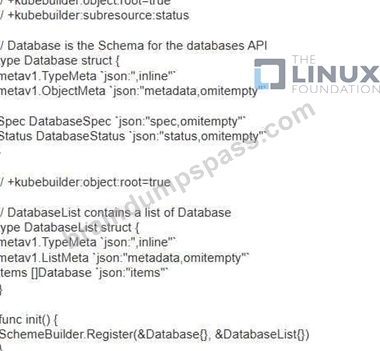
- Apply this YAML file to your cluster using ' kubectl apply -f database-crd.yamr. 2. Create the Operator Project: - IJse the Operator Framework' to initialize a new operator project bash operator-sdk init -domain example.com -repo example.com/database-operator --version VO.O. I -license apache2 - Replace 'example_com' with your desired domain name. 3. Define the Custom Resource: - Create a 'database_types.go' file in the 'api/vl' directory of your project. - Define the 'Database' resource as a custom resource struct Go package v1 import ( metavl "k8s.iofapimachinery/pkg/apis/meta/v1" // DatabaseSpec defines the desired state of Database type DatabaseSpec struct { If Replicas specifies the number of database instances to run.
// Password is the password for the database users.
} // DatabaseStatus defines the observed state of Database type DatabaseStatus struct { // Replicas is the actual number of database instances running.
// Ready indicates if the database is ready to accept connections.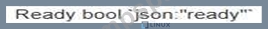
}
4. Implement the Controller Logic: - Create a 'database_controller.go' file in the 'controllers' directory- - Implement the logic for creating, deleting, and scaling database instances.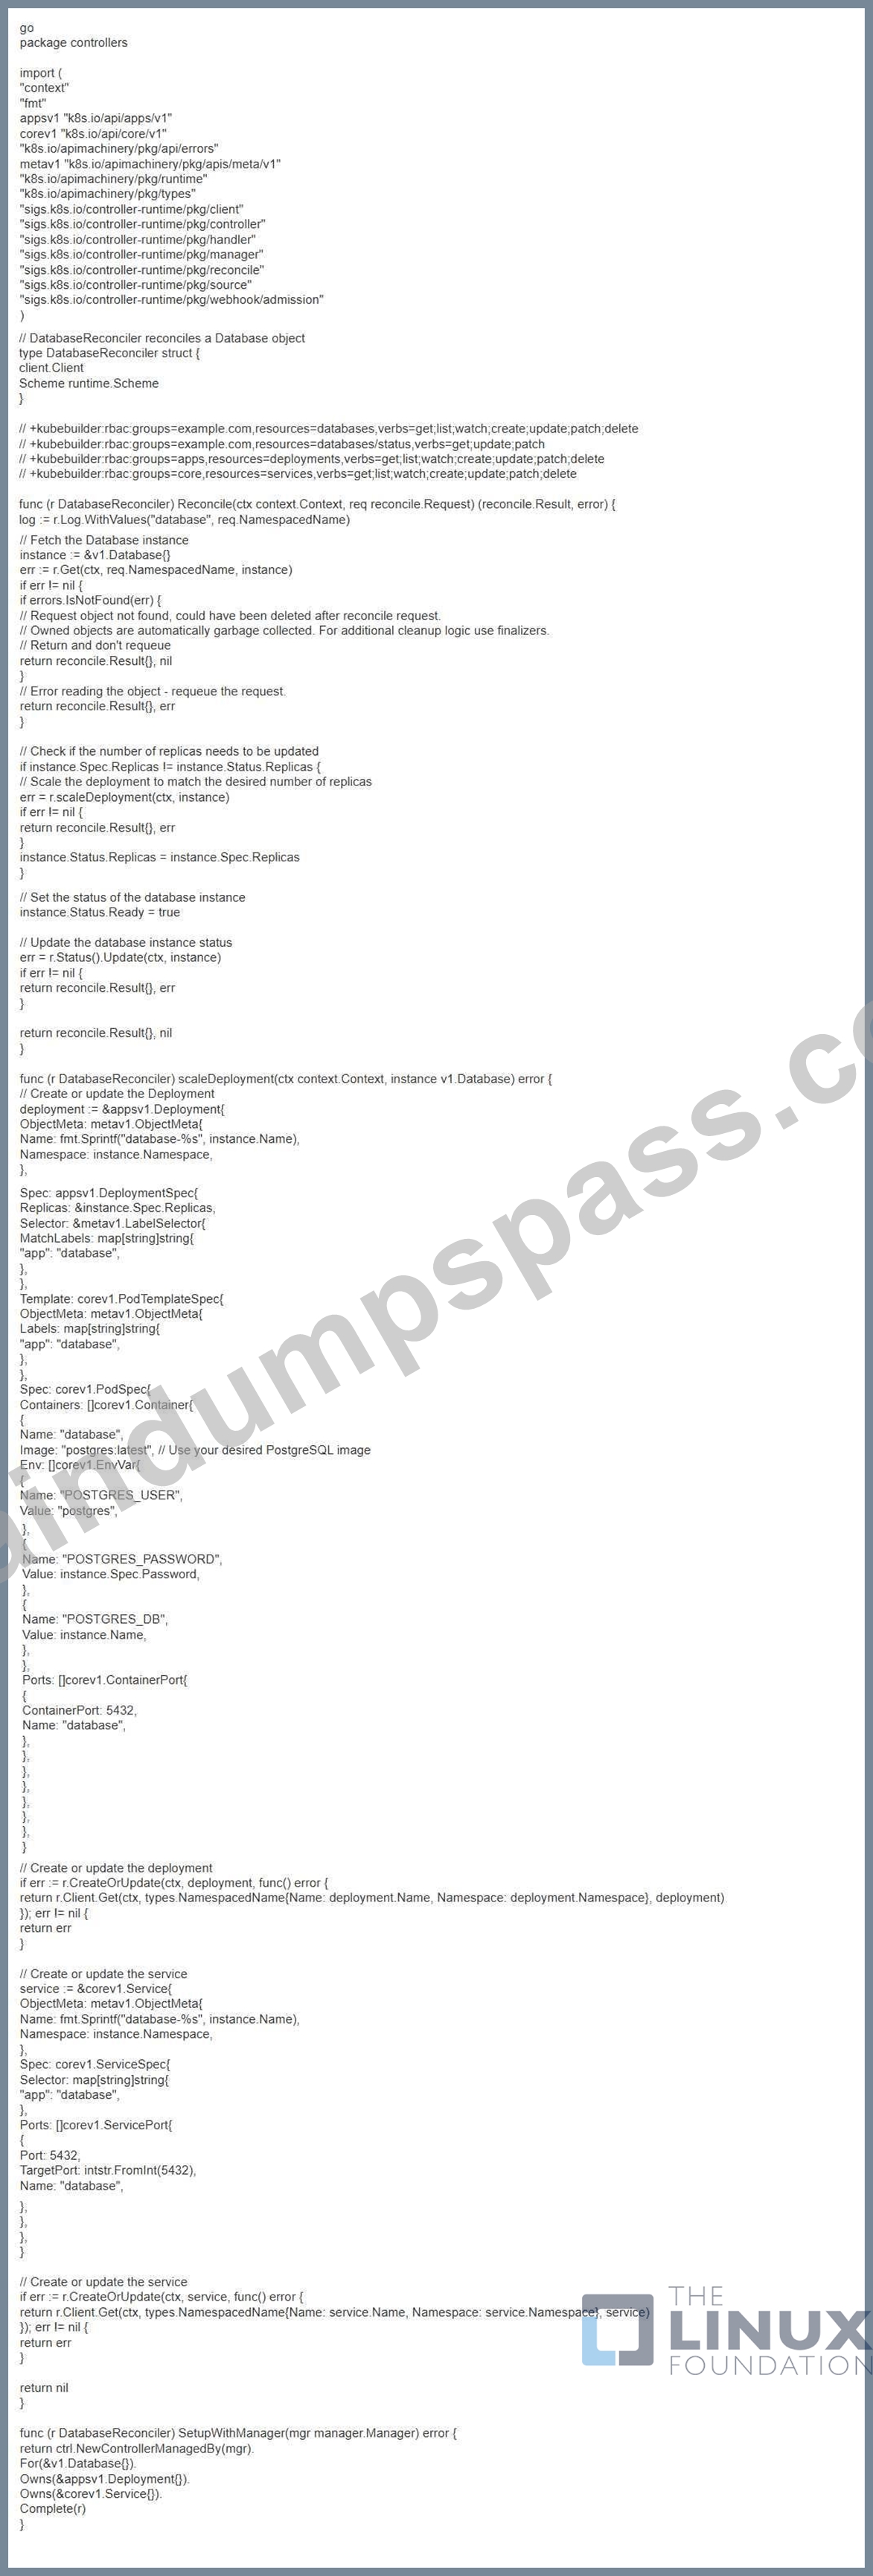
5. Build and Deploy the Operator: - Build the operator using the 'operator-sdk build' command: bash operator-sdk build example.com/database-operator:vO.O.I --local - Deploy the operator to your Kubernetes cluster: bash kubectl apply -f deploy/operator.yaml 6. Test the Operator: - Create a new 'database-example-com' resource: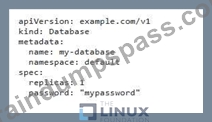
- Apply the YAML file to your cluster: bash kubectl apply -f my-database.yaml - Verify that the operator creates a PostgreSQL database instance. - Test scaling the database by updating the 'spec.replicas' field of the 'database.example.com' resource. - Delete the 'database.example.com' resource and verify that the operator cleans up the database instance. This step-by-step guide demonstrates a basic example of a custom operator using the Operator Framework. You can Kustomize this operator further to handle more complex operations and integrate with other Kubernetes resources. ,
NEW QUESTION # 242
......
Valid CKAD Test Sample: https://www.braindumpspass.com/Linux-Foundation/CKAD-practice-exam-dumps.html
What's more, part of that BraindumpsPass CKAD dumps now are free: https://drive.google.com/open?id=1h7zOahqYlGfD8-rt5und9aH2WkBQsmHL