BTW, DOWNLOAD part of Test4Engine MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1EUbYKqfzfhvJ9Z45OqPwT1iyLDAVBoC7
Provided you get the certificate this time with our MLA-C01 practice materials, you may have striving and excellent friends and promising colleagues just like you. It is also as obvious magnifications of your major ability of profession, so MLA-C01 practice materials may bring underlying influences with positive effects. The promotion or acceptance will be easy. So it is quite rewarding investment. Propulsion occurs when using our MLA-C01 practice materials. They can even broaden amplitude of your horizon in this line. Of course, knowledge will accrue to you from our MLA-C01 practice materials.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Exam Price: | 150 USD |
| Passing Score: | 1000-2000 scaled score (passing score approximately 720) |
| Certificate Validity Period: | 3 years |
| Available Languages: | Simplified Chinese, Japanese, Korean, English, Traditional Chinese |
| Exam Duration: | 170 minutes |
| Related Certifications: | AWS Certified Solutions Architect - Associate AWS Certified Data Engineer - Associate AWS Certified Developer - Associate |
| Real Exam Qty: | 85 |
| Exam Format: | Multiple response, Multiple choice |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored (Pearson VUE) or in-person testing center |
| Pre Condition: | Recommended: 2+ years of ML engineering experience, familiarity with AWS ML services |
| Official Syllabus URL: | https://aws.amazon.com/certification/certified-machine-learning-engineer-associate/ |
>> Free MLA-C01 Test Questions <<
A AWS Certified Machine Learning Engineer - Associate will not only expand your knowledge but it will polish your abilities as well to advance successfully in the world of Amazon. Real Amazon MLA-C01 Exam QUESTIONS certification increases your commitment and professionalism by giving you all the knowledge necessary to work in a professional setting. We have heard from thousands of people who say that using the authentic and Reliable MLA-C01 Exam Dumps was the only way they were able to pass the MLA-C01.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 174
An ML engineer has an Amazon Comprehend custom model in Account A in the us-east-1 Region. The ML engineer needs to copy the model to Account # in the same Region.
Which solution will meet this requirement with the LEAST development effort?
Answer: C
Explanation:
Amazon Comprehend provides the ImportModel API operation, which allows you to copy a custom model between AWS accounts. By creating a resource-based IAM policy on the model in Account A, you can grant Account B the necessary permissions to access and import the model. This approach requires minimal development effort and is the AWS-recommended method for sharing custom models across accounts.
NEW QUESTION # 175
Case Study
A company is building a web-based AI application by using Amazon SageMaker. The application will provide the following capabilities and features: ML experimentation, training, a central model registry, model deployment, and model monitoring.
The application must ensure secure and isolated use of training data during the ML lifecycle. The training data is stored in Amazon S3.
The company needs to use the central model registry to manage different versions of models in the application.
Which action will meet this requirement with the LEAST operational overhead?
Answer: A
NEW QUESTION # 176
A company has built more than 50 models and deployed the models on Amazon SageMaker Al as real-time inference endpoints. The company needs to reduce the costs of the SageMaker Al inference endpoints. The company used the same ML framework to build the models. The company ' s customers require low-latency access to the models.
Select and order the correct steps from the following list to reduce the cost of inference and keep latency low.
Select each
step one time or not at all. (Select and order FIVE.)
Create an endpoint configuration that references a multi-model container.
. Create a SageMaker Al model with multi-model endpoints enabled.
. Deploy a real-time inference endpoint by using the endpoint configuration.
. Deploy a serverless inference endpoint configuration by using the endpoint configuration.
Spread the existing models to multiple different Amazon S3 bucket paths.
. Upload the existing models to the same Amazon S3 bucket path.
. Update the models to use the new endpoint ID. Pass the model IDs to the new endpoint.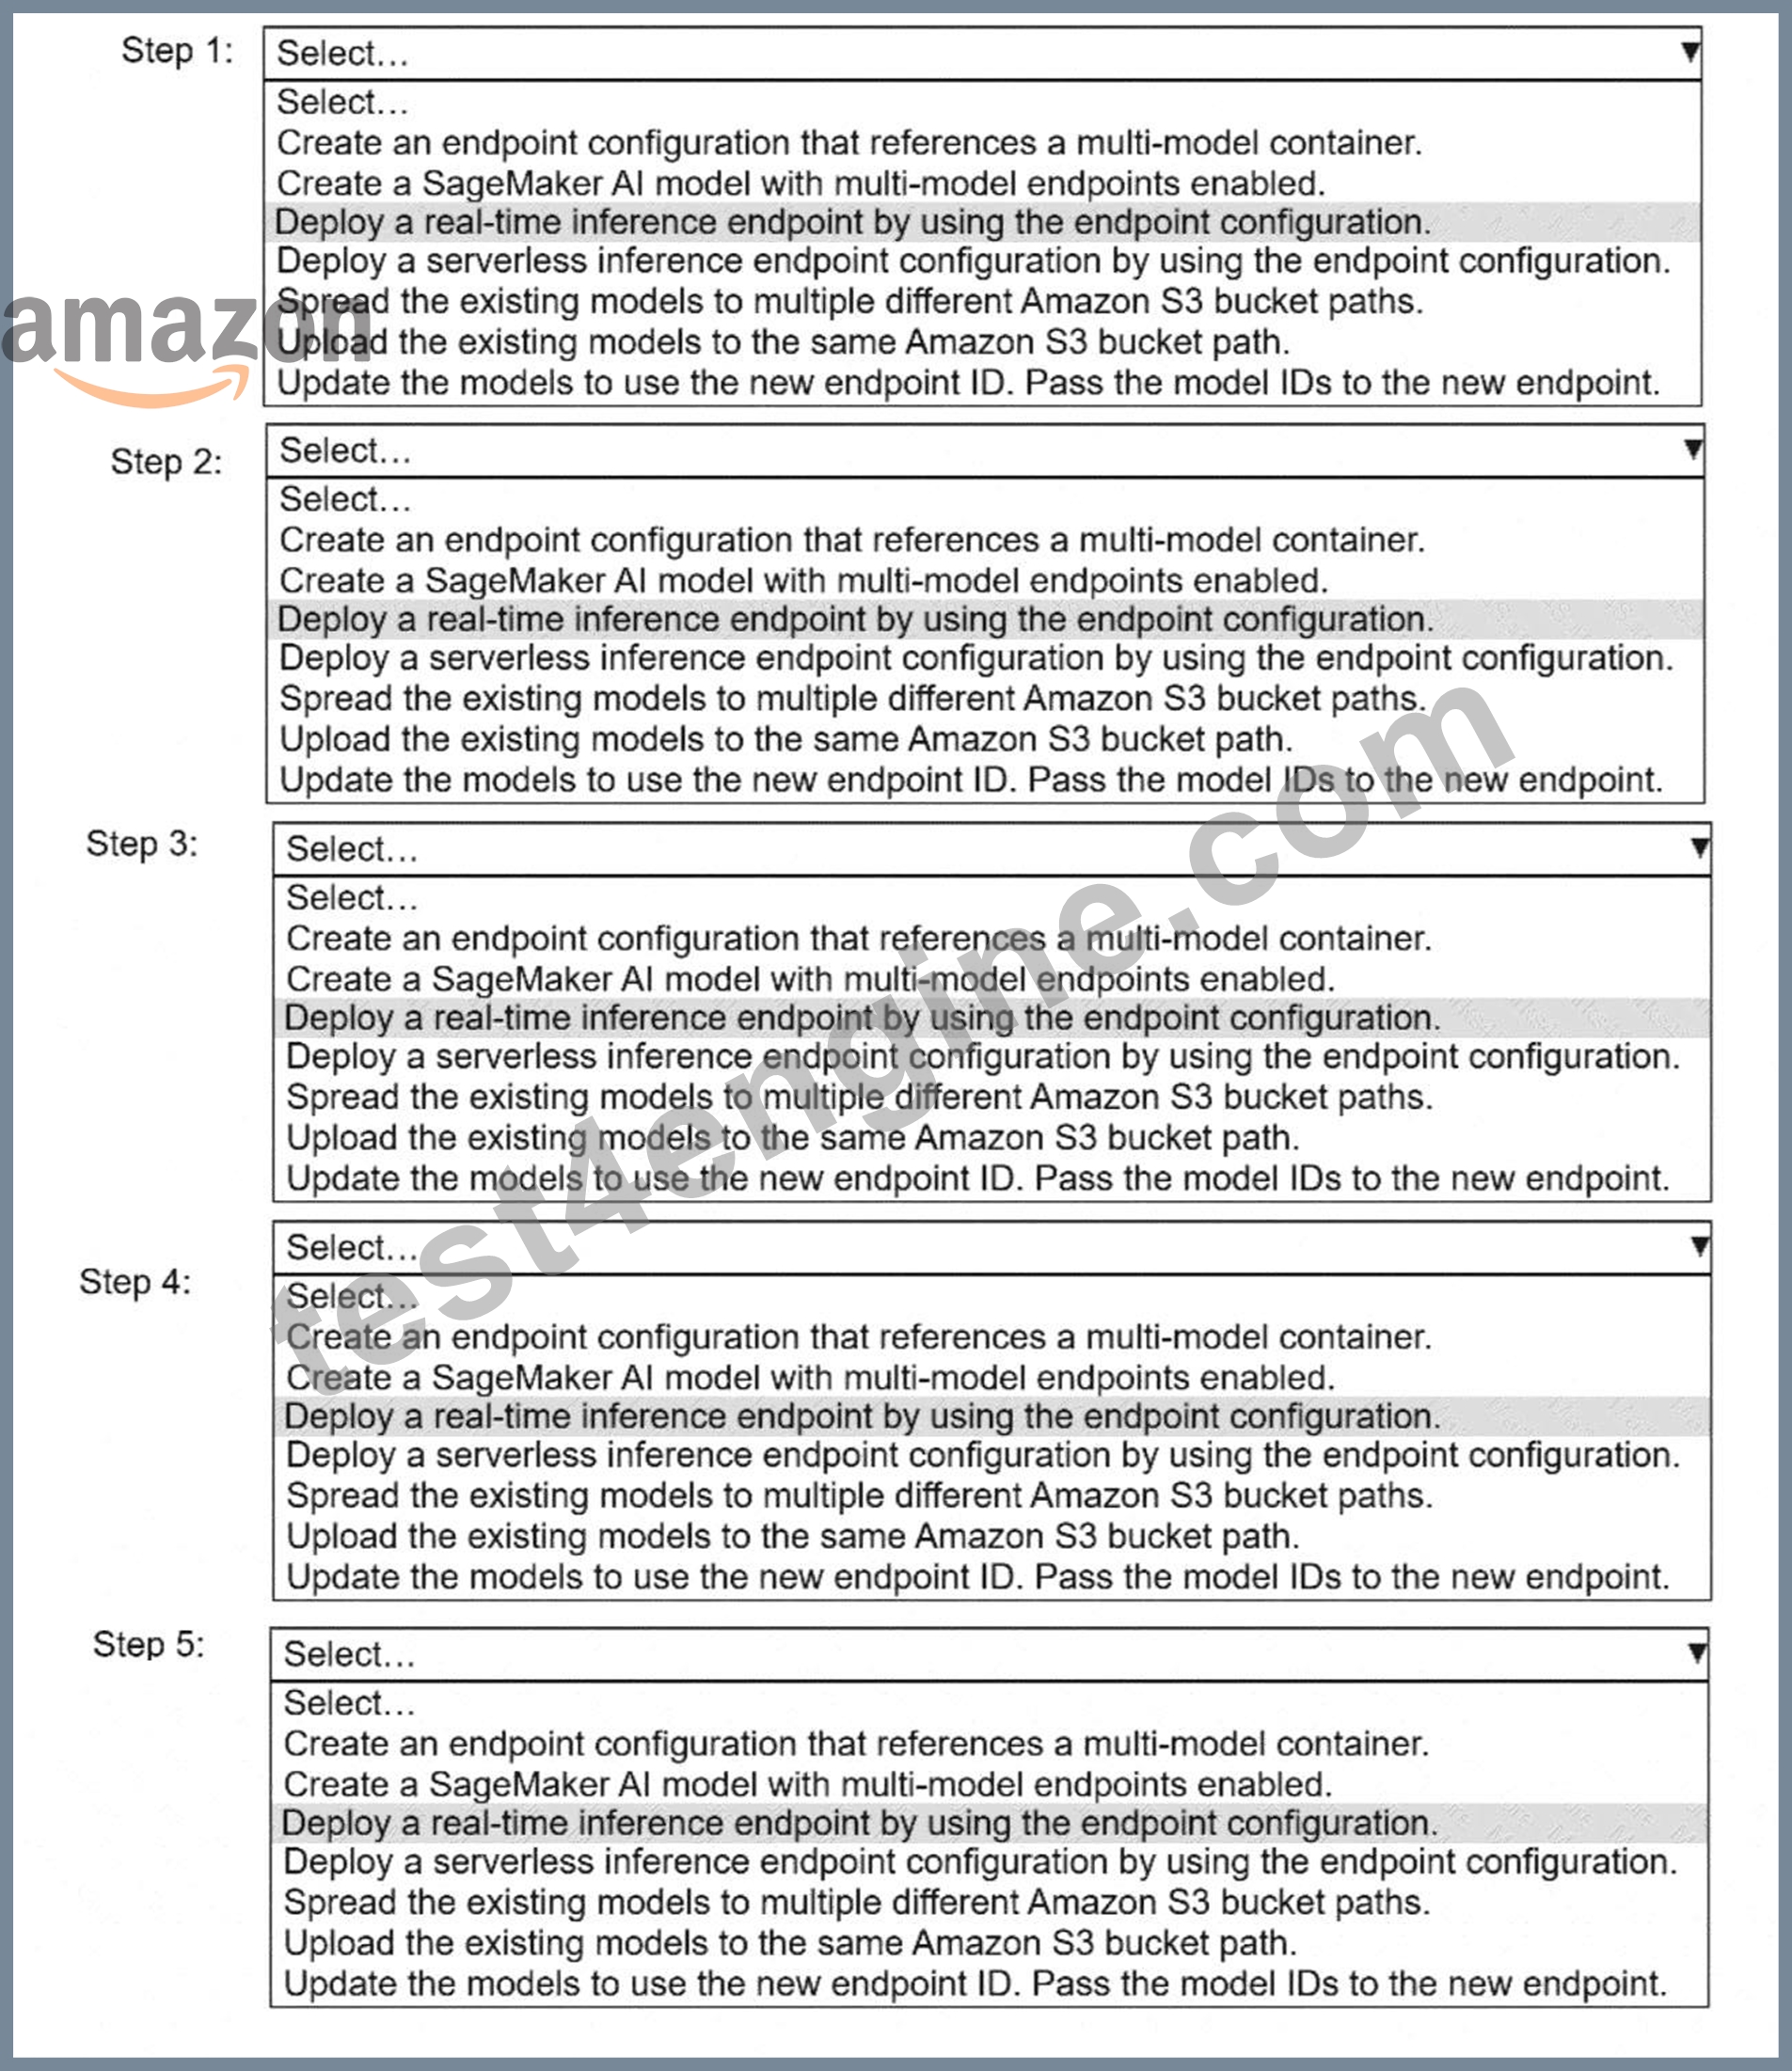
Answer:
Explanation: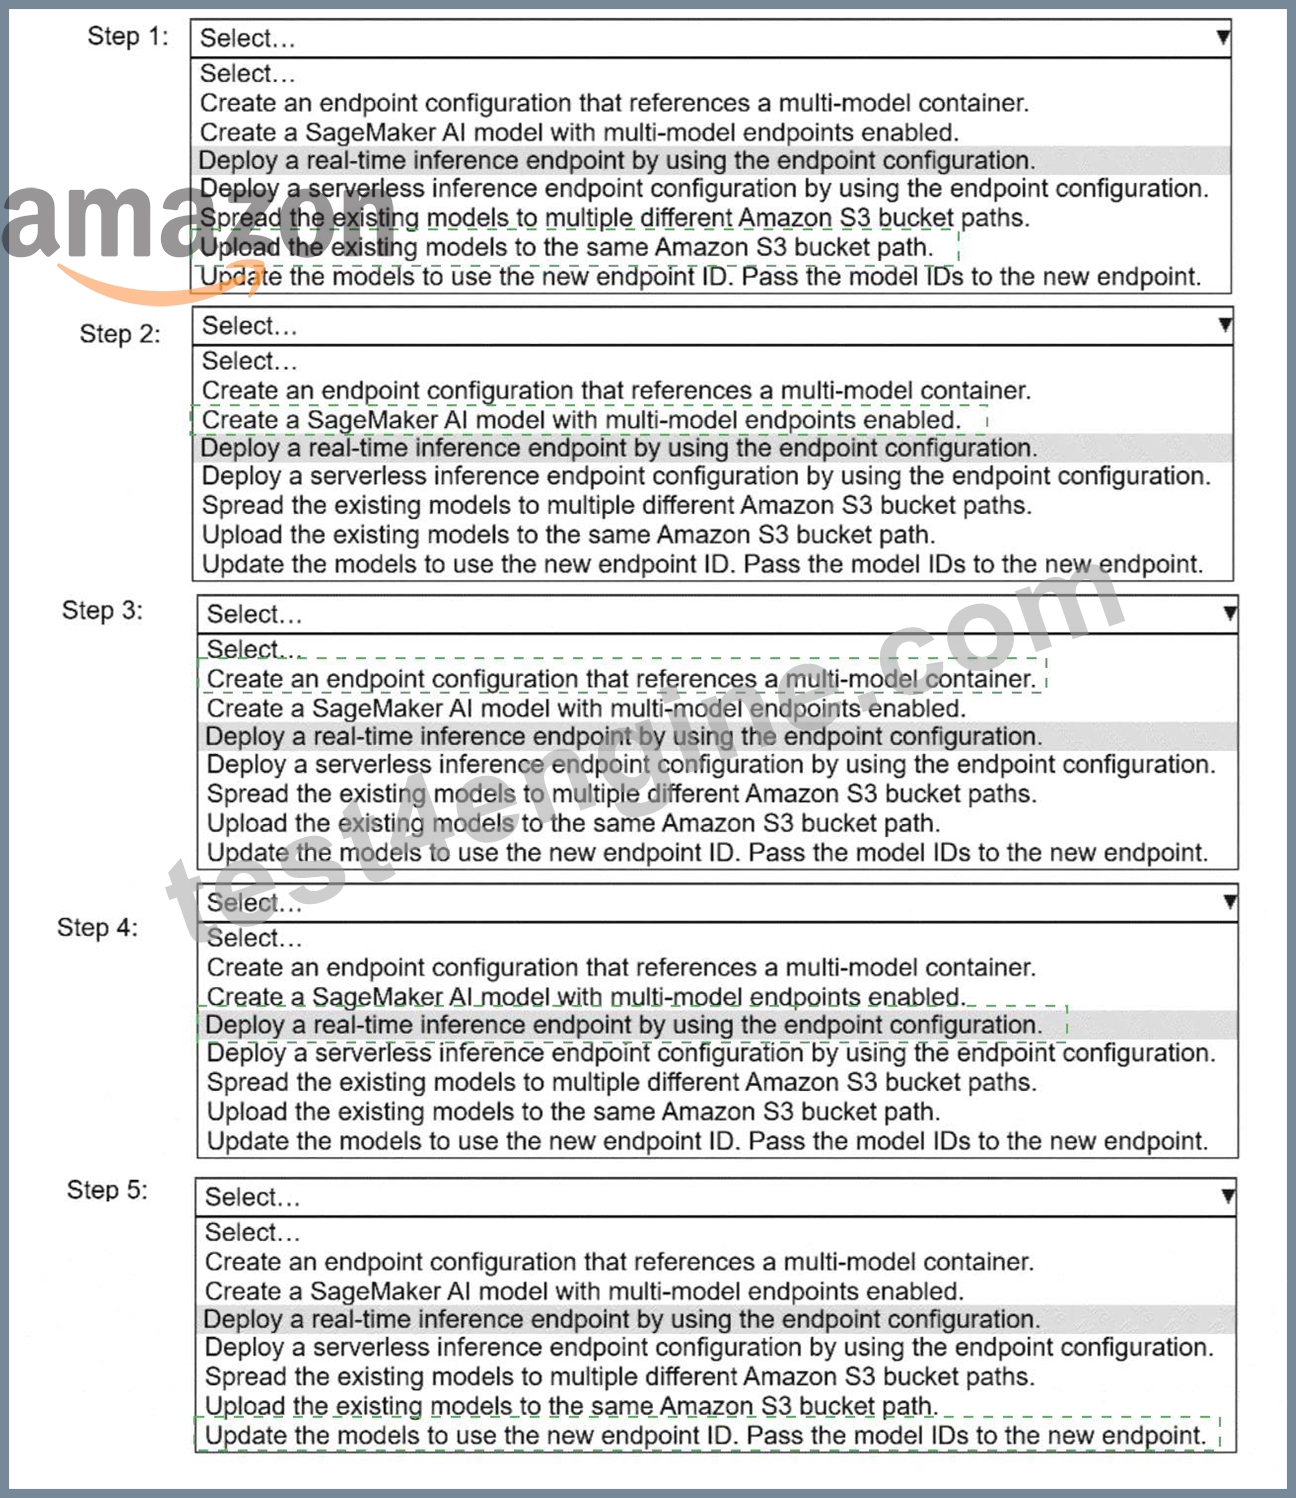
Explanation:
Step 1
Upload the existing models to the same Amazon S3 bucket path.
Multi-model endpoints require all models to be stored under a single S3 prefix so SageMaker can dynamically load them on demand.
Step 2
Create a SageMaker AI model with multi-model endpoints enabled.
This creates a SageMaker model resource that uses a multi-model-capable container (for example, XGBoost, PyTorch, or TensorFlow MME-compatible containers).
Step 3
Create an endpoint configuration that references a multi-model container.
The endpoint configuration defines:
Instance type
Initial instance count
The multi-model container reference
Step 4
Deploy a real-time inference endpoint by using the endpoint configuration.
Real-time endpoints ensure low-latency inference, which is a strict customer requirement.
Step 5
Update the models to use the new endpoint ID. Pass the model IDs to the new endpoint.
Each inference request specifies a model ID so SageMaker knows which model to load from S3.
NEW QUESTION # 177
An ML engineer is working on an ML model to predict the prices of similarly sized homes. The model will base predictions on several features The ML engineer will use the following feature engineering techniques to estimate the prices of the homes:
* Feature splitting
* Logarithmic transformation
* One-hot encoding
* Standardized distribution
Select the correct feature engineering techniques for the following list of features. Each feature engineering technique should be selected one time or not at all (Select three.)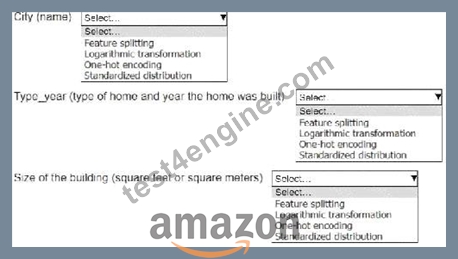
Answer:
Explanation: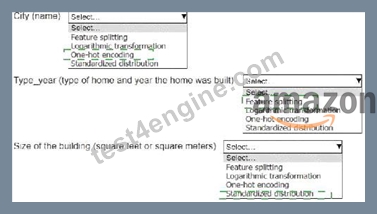
Explanation:
* City (name):One-hot encoding
* Type_year (type of home and year the home was built):Feature splitting
* Size of the building (square feet or square meters):Standardized distribution
* City (name): One-hot encoding
* Why?The "City" is a categorical feature (non-numeric), so one-hot encoding is used to transform it into a numeric format. This encoding creates binary columns for eachunique category (e.g., cities like "New York" or "Los Angeles"), which the model can interpret.
* Type_year (type of home and year the home was built): Feature splitting
* Why?"Type_year" combines two pieces of information into one column, which could confuse the model. Feature splitting separates this column into two distinct features: "Type of home" and
"Year built," enabling the model to process each feature independently.
* Size of the building (square feet or square meters): Standardized distribution
* Why?Size is a continuous numerical variable, and standardization (scaling the feature to have a mean of 0 and a standard deviation of 1) ensures that the model treats it fairly compared to other features, avoiding bias from differences in feature scale.
By applying these feature engineering techniques, the ML engineer can ensure that the input data is correctly formatted and optimized for the model to make accurate predictions.
NEW QUESTION # 178
A company uses an ML model to recommend videos to users. The model is deployed on Amazon SageMaker AI. The model performed well initially after deployment, but the model's performance has degraded over time.
Which solution can the company use to identify model drift in the future?
Answer: C
Explanation:
AWS recommends Amazon SageMaker Model Monitor for detecting data drift and model drift in deployed models. Model Monitor works by comparing live inference data against a baseline, which must first be created from the training dataset.
AWS documentation clearly specifies the required order:
* Create a baseline using training data statistics
* Create a monitoring schedule to compare incoming data against the baseline Option A reverses this order and is therefore incorrect. Option C is incorrect because SageMaker Clarify focuses on bias and explainability, not ongoing drift detection. Option D is reactive and does not provide continuous monitoring.
Model Monitor integrates with Amazon CloudWatch, enabling automated alerts and downstream retraining workflows. This proactive approach allows companies to detect degradation early and maintain model quality.
Therefore, Option B is the correct and AWS-verified answer.
NEW QUESTION # 179
......
Latest MLA-C01 Test Testking: https://www.test4engine.com/MLA-C01_exam-latest-braindumps.html
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by Test4Engine: https://drive.google.com/open?id=1EUbYKqfzfhvJ9Z45OqPwT1iyLDAVBoC7