DOWNLOAD the newest Exam4Tests AI-300 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1CUaMZw1xxwzi1J2-_nChgQxRCSdNWCae
As everybody knows, the most crucial matter is the quality of Operationalizing Machine Learning and Generative AI Solutions study question for learners. We have been doing this professional thing for many years. Let the professionals handle professional issues. So as for us, we have enough confidence to provide you with the best AI-300 exam questions for your study to pass it. With many years work experience, we have fast reaction speed to market change and need. In this way, we have the Latest AI-300 Test Guide. You don’t worry about that how to keep up with the market trend, just follow us. In addition to the industry trends, the AI-300 test guide is written by lots of past materials’ rigorous analyses. Only with strict study, we write the latest and the specialized study materials. We can say that our AI-300 exam questions are the most suitable for examinee to pass the exam.
| Section | Objectives |
|---|---|
| Topic 1: Implement secure and scalable AI systems | - Scalability and performance optimization
|
| Topic 2: Design and implement generative AI solutions | - RAG (Retrieval Augmented Generation) solutions
|
| Topic 3: Operationalizing machine learning solutions | - Deployment and monitoring
|
| Topic 4: Plan and design AI solutions using Azure AI services | - Responsible AI design
|
Success in the AI-300 test of the Microsoft AI-300 credential is essential in today's industry to verify the skills and get well-paying jobs in reputed firms around the whole globe. Earning the Operationalizing Machine Learning and Generative AI Solutions AI-300 Certification sharpens your skills and helps you to accelerate your career in today's cut throat competition in the Microsoft industry. It is not easy to clear the AI-300 exam on the maiden attempt.
NEW QUESTION # 122
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You manage a Retrieval-Augmented Generation (RAG) application built on Microsoft Foundry.
The application retrieves documents from an indexed knowledge base and generates answers for internal users.
Recent feedback indicates that answers are fluent but sometimes include information that is not supported by the documents that were retrieved.
You need to evaluate whether a proposed change improves RAG answer quality by using supported and measurable techniques.
Solution: Review user feedback comments collected after deployment to determine whether answers appear more accurate.
Does the solution meet the goal?
Answer: A
Explanation:
Correct:
* Review user feedback comments collected after deployment to determine whether answers appear more accurate.
Relying solely on user feedback comments is not the proper immediate action for evaluating this specific issue but it is still the best choice.
Evaluate whether your proposed change improves the Retrieval-Augmented Generation (RAG) system by reducing hallucinations (unsupported information), you need to measure faithfulness and context relevance using automated, quantifiable metrics.
The proper course of action is to implement an LLM-as-a-Judge framework using an open-source evaluation library like Ragas or TruLens.
Recommended Evaluation Plan
Establish a baseline: Run your current RAG pipeline through a test dataset of 50-100 representative user queries.
Capture the outputs: Save the user query, the exact retrieved document snippets, and the generated response for every test.
Apply the change: Deploy your proposed modification (e.g., altered prompt, different temperature, or re-ranking algorithm).Run the evaluation: Pass the test dataset through the updated pipeline to generate a new set of responses.
Compare the metrics: Use the framework to score both sets of data and mathematically verify if the change reduced unsupported claims.
Incorrect:
* Compare embedding vector dimensions used by the retrieval pipeline before and after the change.
Comparing embedding vector dimensions is not a valid or effective method for measuring RAG answer quality. Vector dimensions (e.g., 1536 or 3072) are static architectural properties of your embedding model. They do not reflect factual accuracy, semantic grounding, or the rate of hallucinations in your text generation.
* Measure token throughput and average response latency before and after applying the proposed change.
Measuring token throughput and latency is not the correct action to solve this specific problem.
Reference:
https://www.getmaxim.ai/articles/how-to-evaluate-your-rag-system/
NEW QUESTION # 123
A team develops and manages a conversational assistant by using Microsoft Foundry.
The team must be able to validate that the assistant does not produce hateful responses before the application is exposed to any users.
You need to evaluate the model output for hateful responses as part of a repeatable validation process.
Which evaluator should you configure first?
Answer: D
Explanation:
The Content Safety evaluator in Microsoft Foundry is specifically designed to detect hate speech, violence, sexual content, and self-harm content in model outputs, making it the most direct evaluator for the requirement of preventing hateful responses. It uses Azure AI Content Safety service under the hood, which is trained to classify content across these harmful categories with high accuracy. Protected Material (option A) evaluates whether outputs contain copyrighted or licensed material - not hate speech. Groundedness (option B) measures factual accuracy against a source context - completely irrelevant to hate detection. Indirect Attacks (option C) evaluates whether the model was manipulated via prompt injection to produce harmful content - this is a robustness metric, not a direct output quality measure. Content Safety must be configured first because detecting hate is the primary safety concern explicitly identified in the requirement.
Microsoft Learn Reference Topic: Content safety evaluators in Microsoft Foundry - Detect harmful content in AI model outputs
NEW QUESTION # 124
When comparing prompt variants, the team plans to assess whether the generated responses are grammatically correct.
You need to evaluate the quality of the language from the generated responses.
Which evaluator should you use?
Answer: B
Explanation:
In Microsoft Foundry ' s built-in evaluation framework, each evaluator measures a specific dimension of language quality. Fluency evaluates the grammatical correctness, sentence structure, and overall linguistic smoothness of generated text. A high fluency score means the response reads naturally, with proper grammar, punctuation, and sentence construction - regardless of factual accuracy or relevance to the topic. Coherence (option A) measures whether ideas flow logically from one sentence to the next - it is about logical structure, not grammar. Textual Similarity (option B) measures how closely the generated text matches a reference text using metrics like ROUGE or BLEU - it is a comparison metric, not a standalone quality dimension. Groundedness (option C) measures whether claims are supported by the provided context - it is a factual fidelity metric. For grammatical correctness specifically, Fluency is the correct evaluator.
Microsoft Learn Reference Topic: Built-in AI evaluators in Microsoft Foundry - Fluency, Coherence, Groundedness, and Similarity
NEW QUESTION # 125
A data science team trains a model that depends on features that are stored in a managed feature store.
The model is registered in Azure Machine Learning and will be deployed to a real-time endpoint.
After deployment, the model must:
* Retrieve feature values dynamically at inference time.
* Use the same feature definitions that were used during training.
* Run without manual configuration changes across environments.
You need to define feature store entities so that feature retrieval behaves as expected when the model is deployed.
Which feature store entity should you select for each requirement? To answer, move the appropriate feature store entities to the correct requirements. You may use each feature store entity once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.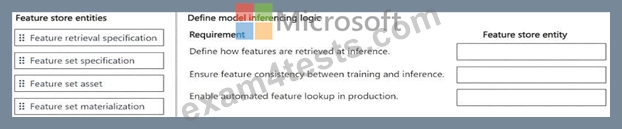
Answer:
Explanation: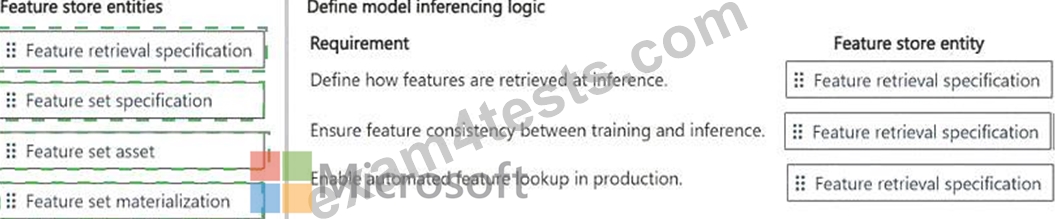
Explanation:
Define how features are retrieved at inference: Feature retrieval specification Ensure feature consistency between training and inference: Feature retrieval specification Enable automated feature lookup in production: Feature retrieval specification The feature retrieval specification is the key model-level contract for all three requirements. Microsoft defines it as a portable specification containing the exact list of features associated with a model, including the relevant feature store, feature set, and feature-set version . The same specification participates in both training and inference, making it the connective artifact across the model lifecycle.
During training, the feature retrieval specification is used to obtain the required feature values and generate training data. Microsoft requires the specification to be packaged with the model artifact when the model depends on feature-store features. At online inference time, the scoring script loads this packaged specification, resolves the feature list, and initializes online feature lookup before calling the feature store to retrieve current values.
This also prevents training-serving inconsistencies because the deployed model carries the feature dependencies and specific feature-set versions established during training, rather than relying on manually reconstructed production configuration. Microsoft explicitly states that packaging the retrieval specification with the model minimizes changes between training and inference workflows.
A feature set specification defines feature sources and transformations, a feature set asset provides managed versioning, and materialization precomputes feature values. None of those alone defines the model ' s complete retrieval contract at inference.
Study Guide Reference: Implement machine learning model lifecycle and operations - package a feature retrieval specification with the model artifact and operationalize feature-store-backed models.
NEW QUESTION # 126
You manage an Azure Machine Learning workspace named Workspace1 and an Azure Blob Storage accessed by using the URL https://storage1.blob.core.wmdows.net/data1.
You plan to create an Azure Blob datastore in Workspace1. The datastore must target the Blob Storage by using Azure Machine Learning Python SDK v2. Access authorization to the datastore must be limited to a specific amount of time.
You need to select the parameters of the Azure Blob Datastore class that will point to the target datastore and authorize access to it.
Which parameters should you use? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.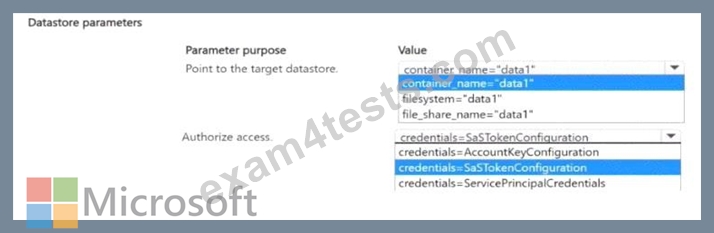
Answer:
Explanation: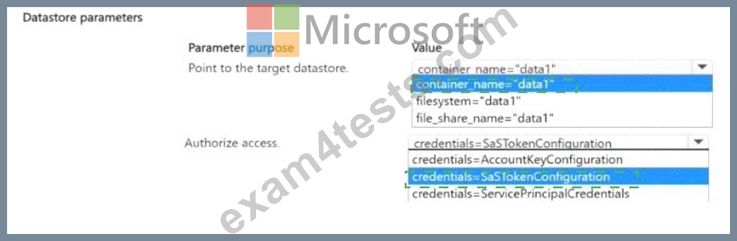
Explanation: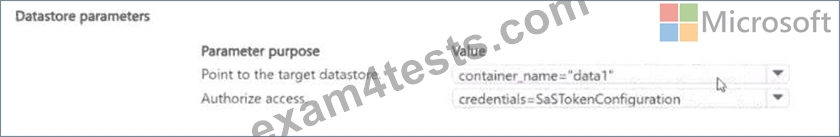
NEW QUESTION # 127
......
There are a number of distinctions of our AI-300 Exam Questions that make it superior to those offered in the market. Firstly, you will find that there are three different vesions of our AI-300 learning guide: the PDF, Software and APP online. Though the content is the same, but the displays are all different. And you can study in all kind of conditions if you have three of them. Secondly, the prices of every version are favourable. And you can buy the Value Pack with discounted price.
AI-300 Lead2pass Review: https://www.exam4tests.com/AI-300-valid-braindumps.html
2026 Latest Exam4Tests AI-300 PDF Dumps and AI-300 Exam Engine Free Share: https://drive.google.com/open?id=1CUaMZw1xxwzi1J2-_nChgQxRCSdNWCae