2026 Latest Exam4PDF NCP-BC-7.5 PDF Dumps and NCP-BC-7.5 Exam Engine Free Share: https://drive.google.com/open?id=1IzPQJKkDi2VcDhunBWSF5bU6X5eKsJNs
If you have decided to improve yourself IT ability by passing Nutanix exam tests, choosing our NCP-BC-7.5 exam braindumps will be definitely right decision. Our Exam4PDF promises that you can pass test at your first time to participate in the NCP-BC-7.5 Dumps Torrent and enhance yourself by practicing exam questions.
| Section | Objectives |
|---|---|
| Prism Central Management | - Cluster and Site Management - DR Monitoring and Operations |
| Recovery Operations | - Test Recovery Workflows - Recovery Plans and Orchestration - Failover and Failback Procedures |
| Data Protection and Backup Integration | - Backup Solutions Integration - Snapshot Management |
| Disaster Recovery Fundamentals | - DR Concepts (RPO, RTO, SLAs) - Business Continuity Principles |
| Nutanix Disaster Recovery Architecture | - Nutanix Leap Overview - Replication Types (Sync/Async) - Protection Domains |
>> New NCP-BC-7.5 Braindumps Ebook <<
To keep pace with the times, we believe science and technology can enhance the way people study on our NCP-BC-7.5 exam materials. Especially in such a fast-pace living tempo, we attach great importance to high-efficient learning our NCP-BC-7.5 Study Guide. Therefore, our NCP-BC-7.5 study materials base on the past exam papers and the current exam tendency, and design such an effective simulation function to place you in the real exam environment.
NEW QUESTION # 36
An administrator notices that storage utilization continues to increase at both the primary and recovery sites after implementing a third-party backup solution that uses protection policies. Which configuration should be reviewed first?
Answer: A
Explanation:
Storage consumption in a BCDR environment is directly governed by two factors: the frequency of recovery points (RPO) and the length of time those points are kept (Retention). When a third-party backup solution integrates with Nutanix Protection Policies, it often takes over the management of the snapshot lifecycle.
If storage utilization is increasing unexpectedly at both sites, the most likely cause is that recovery points are not being expired or purged at the expected rate. The administrator should first review the retention settings within the backup solution. If the retention period is set too long, or if the backup software is failing to send the " delete " command to Prism after its local catalog is updated, snapshots will accumulate on both the primary and recovery Nutanix clusters, leading to a steady growth in storage consumption. Other factors like network segmentation (Option C) or encryption (Option B) affect traffic paths and security but do not directly influence the quantity of data stored on the disks. Recovery validation (Option A) might use temporary storage but should not cause a continuous, long-term increase. Therefore, aligning the retention policy of the backup software with the available cluster capacity is the primary troubleshooting step.
NEW QUESTION # 37
After a failover and stabilization of workloads at the recovery AZ, an administrator removes several VMs from the protection policy because they are no longer required. Which action should be performed as part of post-failover cleanup to prevent unnecessary storage consumption?
Answer: C
Explanation:
Post-failover cleanup is a vital operational step to ensure that the environment remains optimized and that resources are not being wasted on workloads that are no longer part of the production environment. When virtual machines are removed from a Protection Policy after a failover, the orchestration engine stops creating new recovery points for them; however, the existing schedule metadata and historical snapshots may still consume space on both the primary and recovery clusters. Reconfiguring the replication schedule (Option B) is the specific task that refreshes the policy ' s state and forces the system to re-evaluate the storage requirements for the remaining entities. This action ensures that the background cleanup processes (managed by Cerebro and Curator) can properly identify and purge the snapshots associated with the removed VMs once their retention period has passed. Failing to reconfigure the schedule or the associated protection policy can leave " orphaned " snapshots in the storage tier, leading to a steady increase in storage utilization over time. By reconfiguring the schedule, the administrator confirms the new steady-state of the DR environment, ensuring that storage is only consumed by the active, required workloads.
NEW QUESTION # 38
An administrator is troubleshooting a hung replication. When checking the replication status, the complete percent and bytes completed do not increase. The administrator checks the Stargate logs on the destination cluster and confirms the writes are failing with " nfs status 28 " . Checking the container info on the destination cluster, free space on the container is 0. The administrator confirms that there is sufficient space available in the storage pool. What could be the reason for free space on the container to be 0?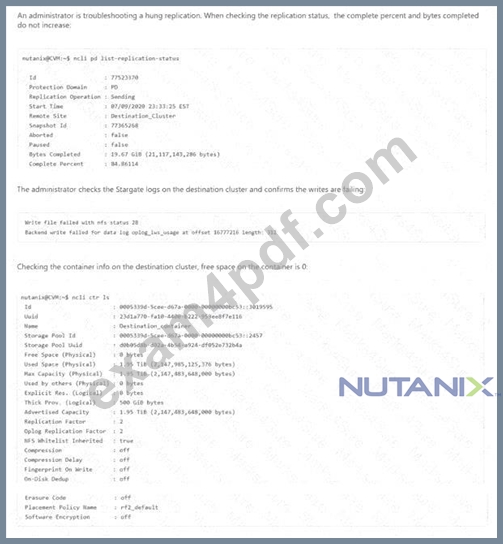
Answer: C
Explanation:
In a Nutanix environment, " Advertised Capacity " is a logical limit (a quota) that an administrator can set on a specific storage container. Even if the physical storage pool has terabytes of free space, if a container ' s advertised capacity is reached, the hypervisor and the Nutanix services will perceive the container as being
100% full.
In this troubleshooting scenario, the " nfs status 28 " error code is a standard indicator for " No space left on device " . Since the administrator confirmed the pool is healthy, the logical limit on the container is the only remaining bottleneck. Replication jobs will " hang " because the destination Stargate service cannot write the incoming data blocks to a container that reports zero free space. To resolve this, the administrator must either increase the advertised capacity value in Prism or remove the limit entirely to allow the container to consume the available physical space in the pool. This highlights a common configuration " trap " where logical quotas-intended for multi-tenant management-can inadvertently block critical BCDR processes like replication if not monitored or sized correctly according to the protected VM growth.
NEW QUESTION # 39
A company is recovering a 3-tier application (Database, Middleware, Web). The administrator executes the Recovery Plan. The Web tier VMs start up but applications immediately crash because they cannot connect to the Database tier. Which setting in the Recovery Plan should the administrator have configured to prevent this execution failure?
Answer: A
Explanation:
Orchestrating the recovery of multi-tier applications requires more than just powering on virtual machines; it requires managing the dependencies between application layers. In a standard 3-tier architecture, the Middleware and Web tiers typically depend on the Database being fully operational and ready to accept connections before they can successfully initialize. If a Recovery Plan powers on all tiers too quickly or simultaneously, the " upstream " services will fail to find their database backend, leading to the application crashes described in the scenario.
The Nutanix Recovery Plan provides " execution stages " to handle this boot ordering. However, even if tiers are in separate stages, a VM reaching a " Power On " state in the hypervisor does not mean the application services (like SQL or Oracle) are fully booted and ready for traffic. To address this, the administrator should configure " optional inter-stage delays " . This setting allows the administrator to define a specific wait time (in seconds) between the completion of one stage (e.g., Database power-on) and the start of the next (e.g., Middleware power-on). This delay gives the database engine enough time to finish its internal checks, mount its databases, and open its network ports. By incorporating these surgical delays, the administrator ensures a reliable, automated recovery where each tier only attempts to start once its required dependencies are fully operational at the destination site.
NEW QUESTION # 40
A VM is protected in an Async Protection Policy and added to a Recovery Plan. An administrator is attempting to perform a planned failover of the VM. How many recovery points are created and replicated during the planned failover process?
Answer: B
Explanation:
A Planned Failover in Nutanix Disaster Recovery is an orchestrated workflow designed to migrate workloads with zero data loss. However, the behavior of recovery point creation depends on the current state of synchronization and the type of replication policy. For standard Asynchronous (Async) Protection Policies, the system typically relies on the established schedule to maintain recovery point consistency. In many automated workflows, especially during a test or a specific " planned " trigger, the administrator might assume a new snapshot is generated; however, if the system is designed to use the most recent " consistent " state, it may rely on the last successfully replicated recovery point to initiate the restore.
Technically, if a new point were to be created, it would require the VM to be shut down at the source to ensure application consistency-a process that is part of the planned failover sequence. If the policy is configured to use existing data for speed, it bypasses new creation to minimize the maintenance window. This emphasizes the importance of verifying that replication is " In-Sync " or " Healthy " before starting a planned failover. If the last recovery point is several hours old, the " planned " move could result in a significant rollback unless the administrator manually triggers a synchronization task prior to the failover event.
Understanding this behavior ensures that BCDR administrators can accurately predict data states following a controlled migration between sites.
NEW QUESTION # 41
......
If you buy our Software version of the NCP-BC-7.5 study questions, you can enjoy the similar real exam environment for that this version has the advantage of simulating the real exam. In addition, the software version of our NCP-BC-7.5 learning guide is not limited to the number of the computer. As long as you use it on the Windows system, then you can enjoy the convenience of this version brings. So do not hesitate and buy our Software version of NCP-BC-7.5 Preparation exam, you will benefit a lot from it.
Reliable NCP-BC-7.5 Test Braindumps: https://www.exam4pdf.com/NCP-BC-7.5-dumps-torrent.html
DOWNLOAD the newest Exam4PDF NCP-BC-7.5 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1IzPQJKkDi2VcDhunBWSF5bU6X5eKsJNs