DOWNLOAD the newest LatestCram Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1zQy12Jaz_dTiC1YF7u2fBH0QvRd6XXz9
Maybe most of people prefer to use the computer when they are study, but we have to admit that many people want to learn buy the paper, because they think that studying on the computer too much does harm to their eyes. Databricks-Generative-AI-Engineer-Associate test questions have the function of supporting printing in order to meet the need of customers. You can print our Databricks-Generative-AI-Engineer-Associate Exam Question on papers after you have downloaded it successfully. It not only can help you protect your eyes, but also it will be very convenient for you to make notes. We believe that you will like our Databricks-Generative-AI-Engineer-Associate exam prep.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> Training Databricks-Generative-AI-Engineer-Associate Online <<
To deliver on the commitments of our Databricks-Generative-AI-Engineer-Associate test prep that we have made for the majority of candidates, we prioritize the research and development of our Databricks-Generative-AI-Engineer-Associate test braindumps, establishing action plans with clear goals of helping them get the Databricks-Generative-AI-Engineer-Associate certification. You can totally rely on our products for your future learning path. In fact, the overload of learning seems not to be a good method, once you are weary of such a studying mode, it’s difficult for you to regain interests and energy. Therefore, we should formulate a set of high efficient study plan to make the Databricks-Generative-AI-Engineer-Associate Exam Dumps easier to operate.
NEW QUESTION # 44
A Generative AI Engineer is deploying a customer-facing, fine-tuned LLM on their public website. Given the large investment the company put into fine-tuning this model, and the proprietary nature of the tuning data, they are concerned about model inversion attacks. Which of the following Databricks AI Security Framework (DASF) risk mitigation strategies are most relevant to this use case?
Answer: B
Explanation:
Model inversion attacks occur when an attacker uses the model's outputs to reconstruct the sensitive training data used during the fine-tuning process. To mitigate this in a public-facing application, implementing AI Guardrails is the most relevant strategy. Guardrails act as a programmable "filter" between the LLM and the end-user. They can be configured to detect if a model's response contains patterns that look like proprietary training data or PII (Personally Identifiable Information). While ACLs (B) and ABAC (D) protect the model's infrastructure (who can invoke the API), they do not inspect the content of the output, which is where the inversion attack actually manifests. Databricks provides integrated guardrail capabilities (via Mosaic AI Gateway) specifically to enforce compliance and prevent the leakage of sensitive internal knowledge that may have been baked into the model weights during fine-tuning.
NEW QUESTION # 45
A Generative AI Engineer has been reviewing issues with their company ' s LLM-based question-answering assistant and has determined that a technique called prompt chaining could help alleviate some performance concerns. However, to suggest this to their team, they have to clearly explain how it works and how it can benefit their question-answering assistant. Which explanation do they communicate to the team?
Answer: D
Explanation:
Prompt chaining is a fundamental design pattern in LLM application development used to handle complexity.
Instead of sending a single, massive, and highly complex prompt to an LLM-which often results in reasoning errors or hallucinations-chaining breaks the logic into a sequence of smaller, targeted steps. For example, a legal assistant might first chain a step to " identify the legal jurisdiction, " followed by a step to " extract relevant statutes, " and finally a step to " summarize the findings. " This modularity improves reliability because each prompt has a narrower focus, making it easier for the model to follow instructions accurately. While it may actually increase latency (contradicting B) and cost (contradicting D) due to multiple API calls, the primary engineering benefit is the significant boost in the quality and robustness of the output.
It also allows for intermediate validation and error handling between steps, which is impossible in a single- call architecture.
NEW QUESTION # 46
A company has a typical RAG-enabled, customer-facing chatbot on its website.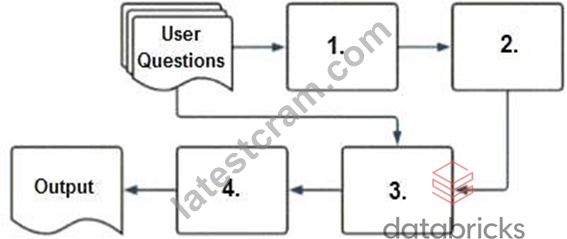
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
Answer: D
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1):The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2):The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3):The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4):Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
* B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence isembedding model, vector search, context-augmented prompt, response- generating LLM, which is option A.
NEW QUESTION # 47
A Generative AI Engineer is building a Generative AI system that suggests the best matched employee team member to newly scoped projects. The team member is selected from a very large team. The match should be based upon project date availability and how well their employee profile matches the project scope. Both the employee profile and project scope are unstructured text.
How should the Generative Al Engineer architect their system?
Answer: B
Explanation:
Problem Context: The problem involves matching team members to new projects based on two main factors:
Availability: Ensure the team members are available during the project dates.
Profile-Project Match: Use the employee profiles (unstructured text) to find the best match for a project's scope (also unstructured text).
The two main inputs are the employee profiles and project scopes, both of which are unstructured. This means traditional rule-based systems (e.g., simple keyword matching) would be inefficient, especially when working with large datasets.
Explanation of Options: Let's break down the provided options to understand why D is the most optimal answer.
Option A suggests embedding project scopes into a vector store and then performing retrieval using team member profiles. While embedding project scopes into a vector store is a valid technique, it skips an important detail: the focus should primarily be on embedding employee profiles because we're matching the profiles to a new project, not the other way around.
Option B involves using a large language model (LLM) to extract keywords from the project scope and perform keyword matching on employee profiles. While LLMs can help with keyword extraction, this approach is too simplistic and doesn't leverage advanced retrieval techniques like vector embeddings, which can handle the nuanced and rich semantics of unstructured data. This approach may miss out on subtle but important similarities.
Option C suggests calculating a similarity score between each team member's profile and project scope. While this is a good idea, it doesn't specify how to handle the unstructured nature of data efficiently. Iterating through each member's profile individually could be computationally expensive in large teams. It also lacks the mention of using a vector store or an efficient retrieval mechanism.
Option D is the correct approach. Here's why:
Embedding team profiles into a vector store: Using a vector store allows for efficient similarity searches on unstructured data. Embedding the team member profiles into vectors captures their semantics in a way that is far more flexible than keyword-based matching.
Using project scope for retrieval: Instead of matching keywords, this approach suggests using vector embeddings and similarity search algorithms (e.g., cosine similarity) to find the team members whose profiles most closely align with the project scope.
Filtering based on availability: Once the best-matched candidates are retrieved based on profile similarity, filtering them by availability ensures that the system provides a practically useful result.
This method efficiently handles large-scale datasets by leveraging vector embeddings and similarity search techniques, both of which are fundamental tools in Generative AI engineering for handling unstructured text.
Technical Reference:
Vector embeddings: In this approach, the unstructured text (employee profiles and project scopes) is converted into high-dimensional vectors using pretrained models (e.g., BERT, Sentence-BERT, or custom embeddings). These embeddings capture the semantic meaning of the text, making it easier to perform similarity-based retrieval.
Vector stores: Solutions like FAISS or Milvus allow storing and retrieving large numbers of vector embeddings quickly. This is critical when working with large teams where querying through individual profiles sequentially would be inefficient.
LLM Integration: Large language models can assist in generating embeddings for both employee profiles and project scopes. They can also assist in fine-tuning similarity measures, ensuring that the retrieval system captures the nuances of the text data.
Filtering: After retrieving the most similar profiles based on the project scope, filtering based on availability ensures that only team members who are free for the project are considered.
This system is scalable, efficient, and makes use of the latest techniques in Generative AI, such as vector embeddings and semantic search.
NEW QUESTION # 48
A Generative AI Engineer is managing prompt templates using MLflow v3.x for a document summarization pipeline. A regulatory audit requires the team to demonstrate exactly which prompt version was used to generate outputs on a specific date three months ago, including the exact prompt text and any variables used at that time.
Which combination of MLflow v3.x capabilities allows the engineer to satisfy this audit requirement?
Answer: C
Explanation:
The Prompt Registry preserves identifiable prompt versions, allowing the team to recover the exact template associated with a historical execution. Linking inference activity to the prompt's name and version establishes which registered template the application actually used. MLflow also supports lineage between prompt versions, application versions, and execution traces. However, satisfying the entire audit requires retaining the actual runtime variable values or the fully rendered prompt in the relevant execution records. Registry history alone preserves the template, not every value substituted into it. Therefore, D is the best option, provided the logging captures those inputs. Model webhooks, experiment tags, or table history alone do not provide the same explicit prompt-version lineage and complete historical reconstruction. Databricks documentation
NEW QUESTION # 49
......
Our company has the highly authoritative and experienced team. In order to let customers enjoy the best service, all Databricks-Generative-AI-Engineer-Associate exam prep of our company were designed by hundreds of experienced experts. Our Databricks-Generative-AI-Engineer-Associate test questions will help customers learn the important knowledge about exam. If you buy our products, it will be very easy for you to have the mastery of a core set of knowledge in the shortest time, at the same time, our Databricks-Generative-AI-Engineer-Associate Test Torrent can help you avoid falling into rote learning habits. You just need to spend 20 to 30 hours on study, and then you can take your exam. In addition, the authoritative production team of our Databricks-Generative-AI-Engineer-Associate exam prep will update the study system every day in order to make our customers enjoy the newest information.
Reliable Databricks-Generative-AI-Engineer-Associate Exam Pattern: https://www.latestcram.com/Databricks-Generative-AI-Engineer-Associate-exam-cram-questions.html
BONUS!!! Download part of LatestCram Databricks-Generative-AI-Engineer-Associate dumps for free: https://drive.google.com/open?id=1zQy12Jaz_dTiC1YF7u2fBH0QvRd6XXz9