Pass Certified-Data-Engineer-Professional Guarantee, Valid Certified-Data-Engineer-Professional Exam Answers

Whereas the other two Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam questions formats are concerned both are the easy-to-use and compatible mock Certified-Data-Engineer-Professional exam that will give you a real-time environment for quick Databricks Exams preparation. Now choose the right Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam questions format and start this career advancement journey.
| Section | Objectives |
|---|
| Topic 1: Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Simplify data layout decisions and optimize query performance using liquid clustering
- 4. Design and implement scalable data models using Delta Lake to manage large datasets
|
| Topic 2: Cost & Performance Optimization | - Optimize cost and performance
- 1. Apply Change Data Feed to address streaming table limitations and improve latency
- 2. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 3. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 4. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 5. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
|
| Topic 3: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Topic 4: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
|
| Topic 5: Data Sharing and Federation | - Share and federate data
- 1. Configure Lakehouse Federation with appropriate governance across supported source systems
- 2. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Topic 6: Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Topic 7: Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Use row filters and column masks to protect sensitive table data
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
|
| Topic 8: Monitoring and Alerting | - Monitoring
- 1. Use Query Profile and Spark UI to monitor workloads
- 2. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 3. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 4. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
|
| Topic 9: Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 2. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 3. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 4. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 5. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 6. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 7. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 8. Create pipeline components using control flow operators such as if/else and foreach
- Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
|
| Topic 10: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
>> Pass Certified-Data-Engineer-Professional Guarantee <<
Excellent Certified-Data-Engineer-Professional Prep Guide is Best Study Braindumps for Certified-Data-Engineer-Professional exam
To help customers pass the Databricks Certified-Data-Engineer-Professional exam successfully. SureTorrent with 365 days updates. Valid Certified-Data-Engineer-Professional Certified-Data-Engineer-Professional exam dumps, exam cram and exam dumps demo. You can download these at a preferential price. We continually improve the versions of our Certified-Data-Engineer-Professional Exam Guide so as to make them suit all learners with different learning levels and conditions.
Databricks Certified Data Engineer Professional Sample Questions (Q244-Q249):
NEW QUESTION # 244
A Delta table of weather records is partitioned by date and has the below schema:
date DATE, device_id INT, temp FLOAT, latitude FLOAT, longitude FLOAT
To find all the records from within the Arctic Circle, you execute a query with the below filter:
latitude > 66.3
Which statement describes how the Delta engine identifies which files to load?
- A. All records are cached to an operational database and then the filter is applied
- B. All records are cached to attached storage and then the filter is applied
- C. The Parquet file footers are scanned for min and max statistics for the latitude column
- D. The Delta log is scanned for min and max statistics for the latitude column
- E. The Hive metastore is scanned for min and max statistics for the latitude column
Answer: D
Explanation:
This is the correct answer because Delta Lake uses a transaction log to store metadata about each table, including min and max statistics for each column in each data file. The Delta engine can use this information to quickly identify which files to load based on a filter condition, without scanning the entire table or the file footers. This is called data skipping and it can improve query performance significantly. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; [Databricks Documentation], under "Optimizations - Data Skipping" section.
In the Transaction log, Delta Lake captures statistics for each data file of the table. These statistics indicate per file:
- Total number of records
- Minimum value in each column of the first 32 columns of the table
- Maximum value in each column of the first 32 columns of the table
- Null value counts for in each column of the first 32 columns of the table When a query with a selective filter is executed against the table, the query optimizer uses these statistics to generate the query result. it leverages them to identify data files that may contain records matching the conditional filter.
For the SELECT query in the question, The transaction log is scanned for min and max statistics for the price column.
NEW QUESTION # 245
The data engineering team maintains the following code:
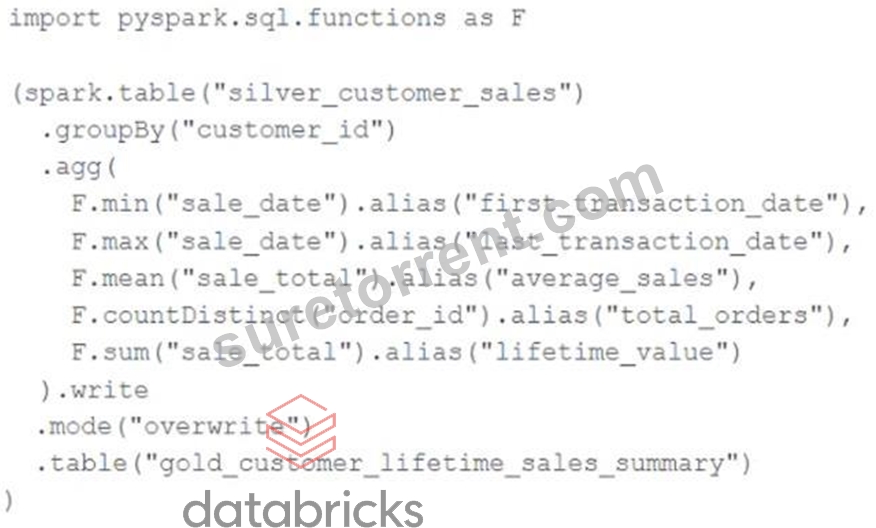
Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. An incremental job will detect if new rows have been written to the silver_customer_sales table; if new rows are detected, all aggregates will be recalculated and used to overwrite the gold_customer_lifetime_sales_summary table.
- B. An incremental job will leverage running information in the state store to update aggregate values in the gold_customer_lifetime_sales_summary table.
- C. The gold_customer_lifetime_sales_summary table will be overwritten by aggregated values calculated from all records in the silver_customer_sales table as a batch job.
- D. A batch job will update the gold_customer_lifetime_sales_summary table, replacing only those rows that have different values than the current version of the table, using customer_id as the primary key.
- E. The silver_customer_sales table will be overwritten by aggregated values calculated from all records in the gold_customer_lifetime_sales_summary table as a batch job.
Answer: C
Explanation:
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids. The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed.
NEW QUESTION # 246
A data engineering workspace was automatically enabled for Unity Catalog, creating a workspace catalog. New team members report they can create tables in the default schema but cannot access table in other schemas within the same workspace catalog. Why are the new team members unable to access tables in other schemas?
- A. Tables in other schemas require additional BROWSEprivileges that new users don't receive automatically
- B. New users only receive CREATE TABLE privileges on the default schema.
- C. Workspace catalog permissions are not subject to inheritance rules.
- D. Workspace users receive USE CATALOG and specific privileges on default schema only.
Answer: D
Explanation:
When a workspace catalog is automatically created, new users are granted USE CATALOG and limited privileges on the default schema only. Access to other schemas requires explicit grants, so users cannot see or query tables in those schemas without additional permissions.
NEW QUESTION # 247
The data architect has decided that once data has been ingested from external sources into the Databricks Lakehouse, table access controls will be leveraged to manage permissions for all production tables and views.
The following logic was executed to grant privileges for interactive queries on a production database to the core engineering group.
GRANT USAGE ON DATABASE prod TO eng;
GRANT SELECT ON DATABASE prod TO eng;
Assuming these are the only privileges that have been granted to the eng group and that these users are not workspace administrators, which statement describes their privileges?
- A. Group members have full permissions on the prod database and can also assign permissions to other users or groups.
- B. Group members are able to query and modify all tables and views in the prod database, but cannot create new tables or views.
- C. Group members are able to list all tables in the prod database but are not able to see the results of any queries on those tables.
- D. Group members are able to query all tables and views in the prod database, but cannot create or edit anything in the database.
- E. Group members are able to create, query, and modify all tables and views in the prod database, but cannot define custom functions.
Answer: D
Explanation:
The GRANT USAGE ON DATABASE prod TO eng command grants the eng group the permission to use the prod database, which means they can list and access the tables and views in the database. The GRANT SELECT ON DATABASE prod TO eng command grants the eng group the permission to select data from the tables and views in the prod database, which means they can query the data using SQL or DataFrame API. However, these commands do not grant the eng group any other permissions, such as creating, modifying, or deleting tables and views, or defining custom functions. Therefore, the eng group members are able to query all tables and views in the prod database, but cannot create or edit anything in the database.
NEW QUESTION # 248
An organization processes customer data from web and mobile applications. Data includes names, emails, phone numbers, and location history. Data arrives both as batch files (from SFTP daily) and streaming JSON events (from Kafka in real-time).
To comply with data privacy policies, the following requirements must be met:
- Personally Identifiable Information (PII) such as email, phone
number, and IP address must be masked or anonymized before storage.
- Both batch and streaming pipelines must apply consistent PII
handling.
- Masking logic must be auditable and reproducible.
- The masked data must remain usable for downstream analytics.
How should the data engineer design a compliant data pipeline on Databricks that supports both batch and streaming modes, applies data masking to PII, and maintains traceability for audits?
- A. Load batch data with notebooks and ingest streaming data with SQL Warehouses; use Unity Catalog column masks on Silver tables to redact fields after storage.
- B. Allow PII to be stored unmasked in Bronze for lineage tracking, then apply masking logic in Gold tables used for reporting.
- C. Ingest both batch and streaming data using Lakeflow Declarative Pipelines, and apply masking via Unity Catalog column masks at read time to avoid modifying the data during ingestion.
- D. Use Lakeflow Declarative Pipelines for batch and streaming ingestion, define a PII masking function, and apply it during Bronze ingestion before writing to Delta Lake.
Answer: D
Explanation:
Databricks recommends applying data masking or anonymization before persisting PII to ensure compliance with privacy regulations such as GDPR and HIPAA. In a Lakeflow Declarative Pipeline, developers can define custom Python or SQL-based masking functions to standardize PII handling across both batch and streaming inputs.
This approach ensures that data entering the Delta Lake is already anonymized, guaranteeing consistent and auditable behavior. By applying masking during ingestion (in the Bronze layer), audit trails are preserved through pipeline event logs.
While Unity Catalog column masks (option C) can enforce dynamic masking at query time, they do not prevent PII storage. Thus, option D aligns with the best practice of securing PII before storage, while still supporting reproducibility and analytics usability.
NEW QUESTION # 249
......
Certified-Data-Engineer-Professional guide torrent is authoritative. Over the years, our study materials have helped tens of thousands of candidates successfully pass the exam. Certified-Data-Engineer-Professional certification training is prepared by industry experts based on years of research on the syllabus. These experts are certificate holders who have already passed the certification. They have a keen sense of smell for the test. Therefore, Certified-Data-Engineer-Professional Certification Training is the closest material to the real exam questions. With our study materials, you don't have to worry about learning materials that don't match the exam content.
Valid Certified-Data-Engineer-Professional Exam Answers: https://www.suretorrent.com/Certified-Data-Engineer-Professional-exam-guide-torrent.html
- Test Certification Certified-Data-Engineer-Professional Cost 🚈 Valid Certified-Data-Engineer-Professional Dumps Demo ⚜ Certified-Data-Engineer-Professional Reliable Exam Cram 🐄 Enter ⮆ www.prep4away.com ⮄ and search for [ Certified-Data-Engineer-Professional ] to download for free 🎼Certified-Data-Engineer-Professional Exam Paper Pdf
- New Certified-Data-Engineer-Professional Exam Discount 🔧 New Certified-Data-Engineer-Professional Exam Discount 🐥 Certified-Data-Engineer-Professional Test Pattern 🦒 Open ➽ www.pdfvce.com 🢪 and search for ⇛ Certified-Data-Engineer-Professional ⇚ to download exam materials for free 🧜Certified-Data-Engineer-Professional Reliable Test Topics
- VCE Certified-Data-Engineer-Professional Dumps 🎱 New Certified-Data-Engineer-Professional Braindumps Free 🏨 New Certified-Data-Engineer-Professional Braindumps Free 🥬 Open website ( www.practicevce.com ) and search for ▛ Certified-Data-Engineer-Professional ▟ for free download 🦀New Certified-Data-Engineer-Professional Exam Discount
- Exam Certified-Data-Engineer-Professional Registration 👓 Certified-Data-Engineer-Professional Reliable Test Topics 🐓 Reliable Certified-Data-Engineer-Professional Test Review ☝ Search for ➤ Certified-Data-Engineer-Professional ⮘ and download it for free immediately on 【 www.pdfvce.com 】 🎇Certified-Data-Engineer-Professional Test Pattern
- Databricks - Efficient Pass Certified-Data-Engineer-Professional Guarantee 📑 Enter ➽ www.vceengine.com 🢪 and search for 《 Certified-Data-Engineer-Professional 》 to download for free 🍯VCE Certified-Data-Engineer-Professional Dumps
- 2026 Pass Certified-Data-Engineer-Professional Guarantee: Databricks Certified Data Engineer Professional - Trustable Databricks Valid Certified-Data-Engineer-Professional Exam Answers 🏫 Download 「 Certified-Data-Engineer-Professional 」 for free by simply searching on ➽ www.pdfvce.com 🢪 🔖Certified-Data-Engineer-Professional Exam Paper Pdf
- Latest Certified-Data-Engineer-Professional Exam Price ⬇ Exam Certified-Data-Engineer-Professional Overview 🧙 Valid Certified-Data-Engineer-Professional Dumps Demo 🎠 Download ⇛ Certified-Data-Engineer-Professional ⇚ for free by simply entering ➤ www.prepawayexam.com ⮘ website 💨Valid Certified-Data-Engineer-Professional Test Pass4sure
- Test Certification Certified-Data-Engineer-Professional Cost 💓 Valid Braindumps Certified-Data-Engineer-Professional Files 🌖 Certified-Data-Engineer-Professional Training Solutions 🥉 Easily obtain free download of ( Certified-Data-Engineer-Professional ) by searching on ▷ www.pdfvce.com ◁ 🐨New Certified-Data-Engineer-Professional Braindumps Free
- Databricks - Efficient Pass Certified-Data-Engineer-Professional Guarantee 🐮 Simply search for ⇛ Certified-Data-Engineer-Professional ⇚ for free download on ➤ www.prepawayexam.com ⮘ 👐Certified-Data-Engineer-Professional Training Solutions
- Databricks - Efficient Pass Certified-Data-Engineer-Professional Guarantee 🧢 Easily obtain free download of 《 Certified-Data-Engineer-Professional 》 by searching on ☀ www.pdfvce.com ️☀️ 🤺Certified-Data-Engineer-Professional Test King
- Valid Certified-Data-Engineer-Professional Test Pass4sure ⚒ VCE Certified-Data-Engineer-Professional Dumps ⚫ Reliable Certified-Data-Engineer-Professional Exam Tips 🔲 Easily obtain free download of ➽ Certified-Data-Engineer-Professional 🢪 by searching on ⮆ www.exam4labs.com ⮄ ❕Certified-Data-Engineer-Professional Training Solutions
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes