참고: ExamPassdump에서 Google Drive로 공유하는 무료, 최신 DP-100 시험 문제집이 있습니다: https://drive.google.com/open?id=1I8Z5SpBs5e5XJkbVk6srBrru5mpHS3qJ
목표가 있다면 목표를 향해 끊임없이 달려야 멋진 인생이 됩니다. 지금의 현황에 만족하여 아무런 노력도 하지 않는다면 언젠가는 치열한 경쟁을 이겨내지 못하게 될것입니다. IT업종에 종사중이시라면 다른분들이 모두 취득하는 자격증쯤은 마련해야 되지 않겠습니까? Microsoft인증 DP-100시험은 요즘 가장 인기있는 자격증 시험의 한과목입니다. IT업계에서 살아남으려면ExamPassdump에서Microsoft인증 DP-100덤프를 마련하여 자격증에 도전하여 자기의 자리를 찾아보세요.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Train and deploy models | 25-30% | - Train models
|
| Topic 2: Optimize language models for AI applications | 25-30% | - Evaluate and improve models
|
| Topic 3: Design and prepare a machine learning solution | 20-25% | - Manage compute resources
|
| Topic 4: Explore data and run experiments | 20-25% | - Implement pipelines
|
Microsoft DP-100덤프를 구매하시기전에 사이트에서 해당 덤프의 무료샘플을 다운받아 덤프품질을 체크해보실수 있습니다. DP-100덤프를 구매하시면 구매일로부터 1년내에 덤프가 업데이트될때마다 업데이트된 버전을 무료로 제공해드립니다.Microsoft DP-100덤프 업데이트 서비스는 덤프비용을 환불받을시 자동으로 종료됩니다.
질문 # 457
You create an Azure Machine Learning workspace and install the MLflow library.
You need to tog different types of data by using the MLflow library.
Which method should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.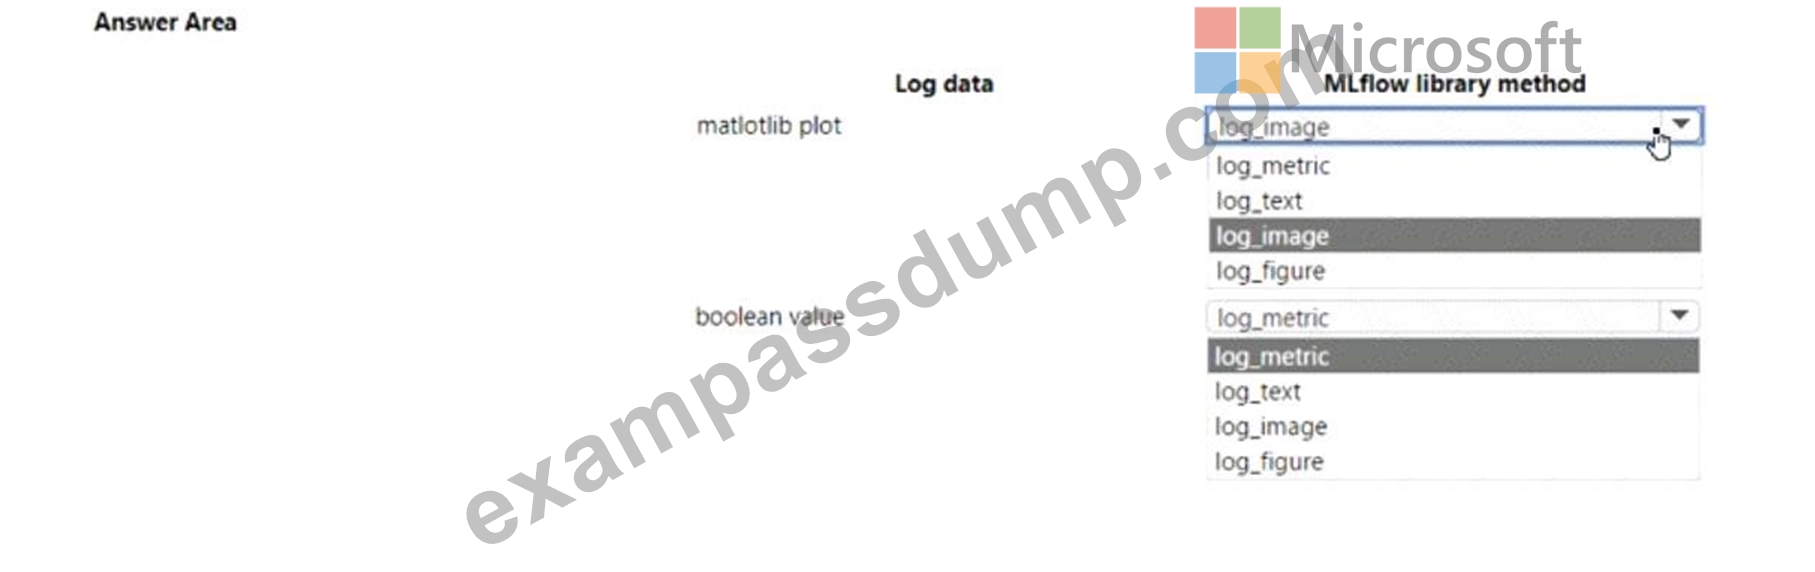
정답:
설명:
Explanation
질문 # 458
You need to define an evaluation strategy for the crowd sentiment models.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
정답:
설명: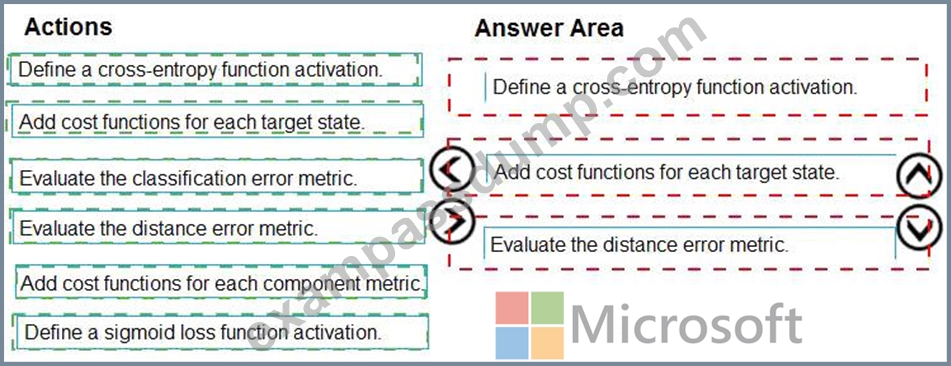
Explanation:
Step 1: Define a cross-entropy function activation
When using a neural network to perform classification and prediction, it is usually better to use cross-entropy error than classification error, and somewhat better to use cross-entropy error than mean squared error to evaluate the quality of the neural network.
Step 2: Add cost functions for each target state.
Step 3: Evaluated the distance error metric.
References:
https://www.analyticsvidhya.com/blog/2018/04/fundamentals-deep-learning-regularization-techniques/
질문 # 459
You are evaluating a Python NumPy array that contains six data points defined as follows:
data = [10, 20, 30, 40, 50, 60]
You must generate the following output by using the k-fold algorithm implantation in the Python Scikit-learn machine learning library:
train: [10 40 50 60], test: [20 30]
train: [20 30 40 60], test: [10 50]
train: [10 20 30 50], test: [40 60]
You need to implement a cross-validation to generate the output.
How should you complete the code segment? To answer, select the appropriate code segment in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.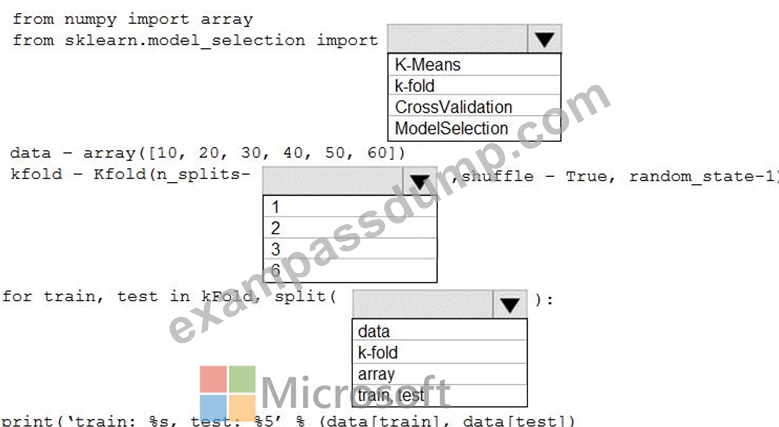
정답:
설명:
References:
https://scikit-learn.org/stable/modules/generated/sklearn.model_selection.KFold.html
질문 # 460
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
An IT department creates the following Azure resource groups and resources: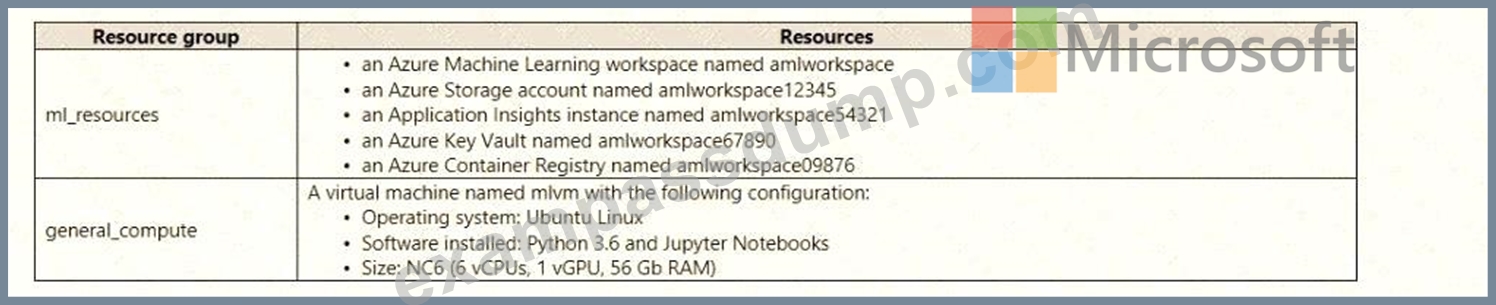
The IT department creates an Azure Kubernetes Service (AKS)-based inference compute target named aks- cluster in the Azure Machine Learning workspace.
You have a Microsoft Surface Book computer with a GPU. Python 3.6 and Visual Studio Code are installed.
You need to run a script that trains a deep neural network (DNN) model and logs the loss and accuracy metrics.
Solution: Install the Azure ML SDK on the Surface Book. Run Python code to connect to the workspace and then run the training script as an experiment on local compute.
정답:B
설명:
Need to attach the mlvm virtual machine as a compute target in the Azure Machine Learning workspace.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/concept-compute-target
질문 # 461
You use Azure Machine Learning Studio to build a machine learning experiment.
You need to divide data into two distinct datasets.
Which module should you use?
정답:B
설명:
Explanation/Reference:
Explanation:
Partition and Sample with the Stratified split option outputs multiple datasets, partitioned using the rules you specified.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/partition-and-sample
질문 # 462
......
Microsoft인증 DP-100시험을 어떻게 공부하면 패스할수 있을지 고민중이시면 근심걱정 버리시고ExamPassdump 의 Microsoft인증 DP-100덤프로 가보세요. 문항수가 적고 적중율이 높은 세련된Microsoft인증 DP-100시험준비 공부자료는ExamPassdump제품이 최고입니다.
DP-100자격증문제: https://www.exampassdump.com/DP-100_valid-braindumps.html
2026 ExamPassdump 최신 DP-100 PDF 버전 시험 문제집과 DP-100 시험 문제 및 답변 무료 공유: https://drive.google.com/open?id=1I8Z5SpBs5e5XJkbVk6srBrru5mpHS3qJ