2026 Latest Prep4sures AI-300 PDF Dumps and AI-300 Exam Engine Free Share: https://drive.google.com/open?id=1jjH4ZTNz2aytO0EFIMVH6WZXhVzCWYXi
The crucial thing when it comes to appearing a competitive exam like AI-300 knowing your problem-solving skills. And to do that you are going to need help from a AI-300 practice questions or braindumps. This is exactly what is delivered by our AI-300 test materials. The AI-300 Exam Dumps cover every topic of the actual Microsoft certification exam. The AI-300 exam questions are divided into various groups and the candidate can solve these questions to test his skills and knowledge.
| Section | Objectives |
|---|---|
| Implement secure and scalable AI systems | - Scalability and performance optimization
|
| Operationalizing machine learning solutions | - ML lifecycle management
|
| Plan and design AI solutions using Azure AI services | - Requirements gathering and solution architecture
|
| Design and implement generative AI solutions | - Large language model integration
|
>> New Soft AI-300 Simulations <<
Many candidates failed exam before. They have no confidence for next exam and they also hesitate if they have to purchase valid AI-300 brain dumps materials or if dumps are actually valid. Now I advise you download our free demo before you are determined to buy. Our free demo is a little of the real test, you can see several questions answers and explanations. You will know the validity of Microsoft AI-300 Brain Dumps materials.
NEW QUESTION # 24
You manage an Azure Machine Learning workspace. You design a training job that is configured with a serverless compute. The serverless compute must have a specific instance type and count You need to configure the serverless compute by using Azure Machine Learning Python SDK v2. What should you do?
Answer: D
NEW QUESTION # 25
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2.
The default datastore of workspace1 contains a folder named sample_data.
The folder structure contains the following content: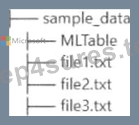
You write Python SDK v2 code to materialize the data from the files in the sample_data folder into a Pandas data frame.
You need to complete the Python SDK v2 code to use the MLTable folder as the materialization blueprint.
How should you complete the code? To answer, select the appropriate options in the answer area . NOTE:
Each correct selection is worth one point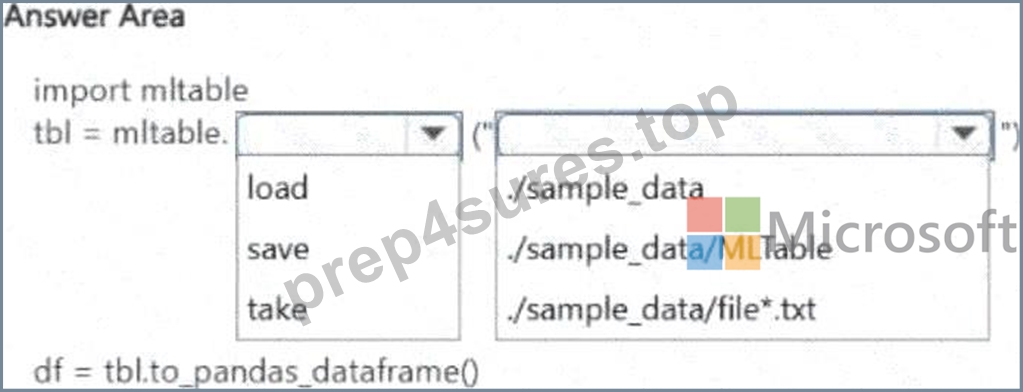
Answer:
Explanation: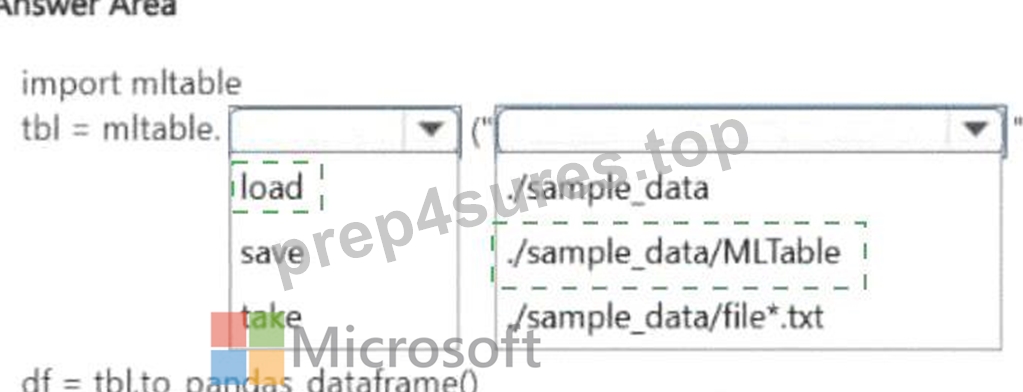
Explanation:
The MLTable format in Azure Machine Learning Python SDK v2 is a structured abstraction over tabular data sources. It stores a YAML file alongside data files, describing how to read and transform the data. To materialize this into a Pandas DataFrame, you use the mltable library: first call mltable.load with the path to the MLTable folder to load the definition, then call to_pandas_dataframe() on the returned object. The path parameter should point to the folder containing the MLTable YAML file on the default datastore. MLTable abstracts the storage location and transformation steps, making the code storage-agnostic - the same code works whether data lives in Blob Storage, ADLS Gen2, or a local path. The SDK v2 approach with MLTable is the recommended pattern for governed, reusable data access in Azure Machine Learning.
Microsoft Learn Reference Topic: Create and use MLTable data assets in Azure Machine Learning Python SDK v2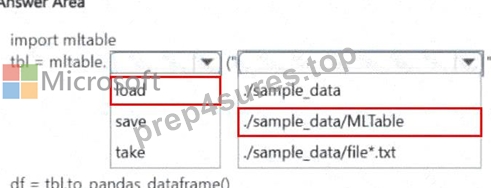
NEW QUESTION # 26
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals.
You have an Azure Machine Learning workspace. You connect to a terminal session from the Notebooks page in Azure Machine Learning studio.
You plan to add a new Jupyter kernel that will be accessible from the same terminal session.
You need to perform the task that must be completed before you can add the new kernel.
Solution: Delete the Python 3.6 - AzureML kernel.
Does the solution meet the goal?
Answer: B
Explanation:
No. Removing the existing Python 3.6 - AzureML kernel is not a prerequisite for adding a new kernel. Azure Machine Learning supports multiple installed Jupyter kernels on the same compute instance, and notebooks can select among those kernels without requiring one existing kernel to be removed first. Microsoft states that the notebook environment automatically discovers all Jupyter kernels installed on the connected compute instance.
The supported new-kernel workflow begins by creating a separate environment, for example with conda create --name newenv, and activating it. The required pip and ipykernel packages are then installed in the environment before registering it with Jupyter by using python -m ipykernel install --user --name newenv.
Deleting an existing AzureML kernel provides no technical benefit to that workflow. Microsoft also explicitly cautions users not to delete Conda environments or Jupyter kernels they did not create , because doing so can interfere with built-in Jupyter/JupyterLab functionality on the compute instance.
Therefore, the existing Python 3.6 kernel should remain untouched; the new kernel should be installed alongside it in its own environment.
Study Guide Reference: Design and implement an MLOps infrastructure - Jupyter kernel management, Conda environments, Azure Machine Learning compute instances, and development environment isolation.
NEW QUESTION # 27
Drag and Drop Question
You build and manage a model by using Azure Machine Learning workspace.
Before you deploy the model, you must create a Responsible AI dashboard in Azure Machine Learning studio. The dashboard must provide observation of the following:
- metrics that show real-world impact on an outcome of interest due to
taking a treatment policy
- examples with minimal changes to a particular data point such that
the model's prediction changes
You need to implement the components for the Responsible AI dashboard.
Which components should you implement? To answer, move the appropriate components to the correct observations. You may use each component once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.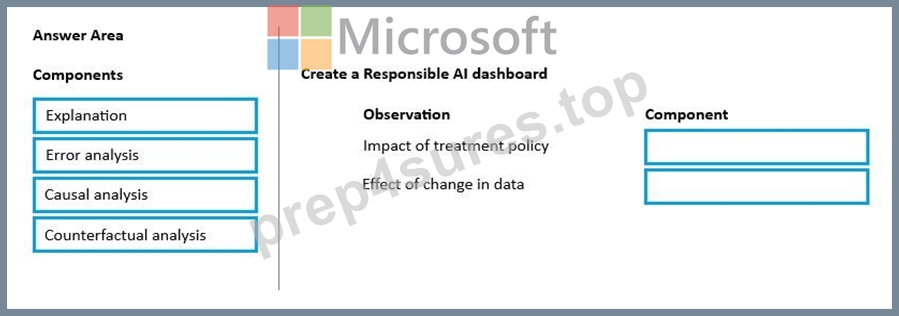
Answer:
Explanation: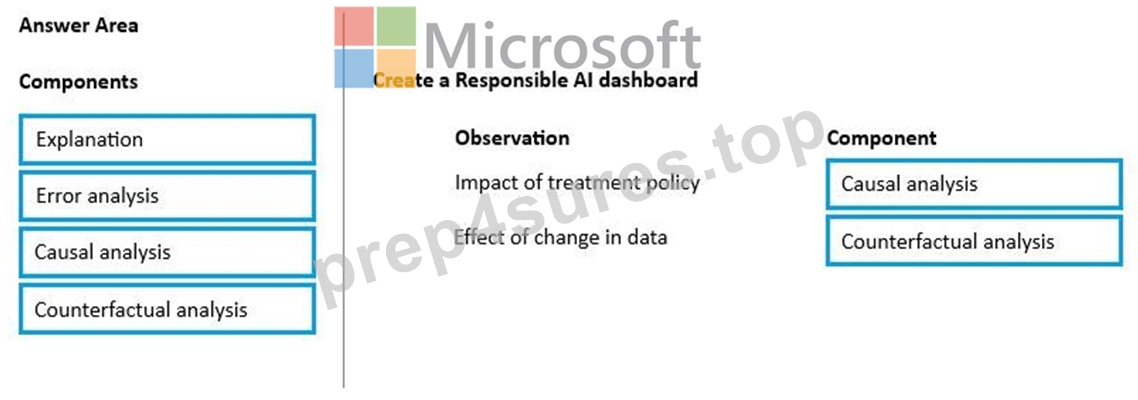
Explanation:
Box 1: Causal analysis
To observe metrics that show the real-world impact on an outcome of interest due to taking a treatment policy, you must implement the Causal analysis component.
Real-World Intervention: Causal analysis specifically uses historical data to evaluate how changing a particular feature (the treatment) directly impacts a real-world outcome.
Policy Making: It generates policy insights by showing which treatment policy is most effective for a specific cohort to optimize your outcome of interest.
Box 2: Counterfactual analysis
You must implement Counterfactual analysis.
The Counterfactual what-if component of the Azure Machine Learning Responsible AI dashboard is designed specifically to "interrogate" a model. It calculates the exact feature tweaks necessary to reverse or modify a specific forecast:
Minimizing Changes: It generates a set of examples demonstrating the smallest possible adjustments to a data point that cause the model's prediction to flip.
Actionable Scenarios: It surfaces the closest data points with opposing or alternative predictions, allowing you to easily test "what-if" scenarios.Why Other Components Do Not Match Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/concept-responsible-ai-dashboard
NEW QUESTION # 28
Drag and Drop Question
You have several machine learning models registered in an Azure Machine Learning workspace.
You must use the Fairlearn dashboard to assess fairness in a selected model.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.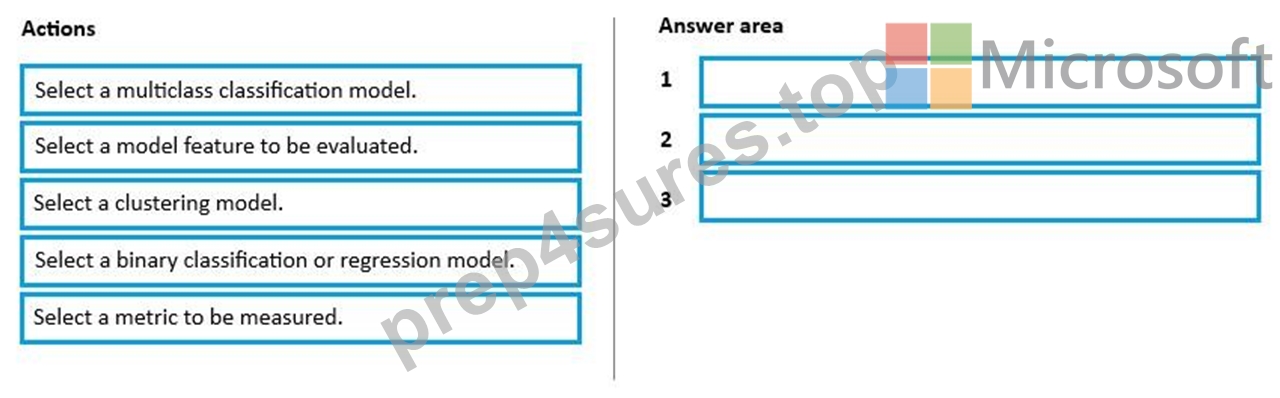
Answer:
Explanation: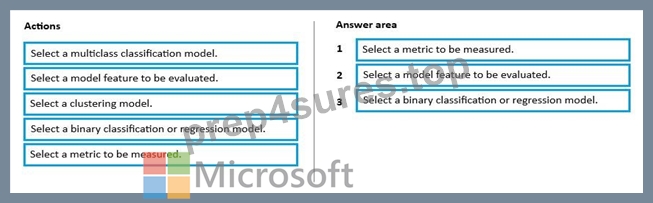
Explanation:
Step 1: Select a metric to measured
You need to choose a baseline performance or fairness metric (such as accuracy rate, precision, or demographic parity) along which the dashboard evaluates the model's overall behavior and cross-group disparities.
Step 2: Select a model feature to evaluated
You must specify a sensitive feature (such as age, gender, or race) to split the data into different subgroups and evaluate potential disparities across them.
Step 3: Select a binary classification or regression model
The Fairlearn package is specifically designed to assess and mitigate unfairness in binary classification and regression tasks. It does not natively support clustering or multiclass models for group fairness assessments in this wizard.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/concept-fairness-ml?view=azureml-api-2
NEW QUESTION # 29
......
If you fail in the exam with our AI-300 quiz prep we will refund you in full at one time immediately. If only you provide the proof which include the exam proof and the scanning copy or the screenshot of the failure marks we will refund you immediately. If any problems or doubts about our AI-300 exam torrent exist, please contact our customer service personnel online or contact us by mails and we will reply you and solve your doubts immediately. Before you buy our product, you can download and try out it freely so you can have a good understanding of our AI-300 Quiz prep. Please feel safe to purchase our AI-300 exam torrent any time as you like. We provide the best service to the client and hope the client can be satisfied.
Latest AI-300 Test Answers: https://www.prep4sures.top/AI-300-exam-dumps-torrent.html
2026 Latest Prep4sures AI-300 PDF Dumps and AI-300 Exam Engine Free Share: https://drive.google.com/open?id=1jjH4ZTNz2aytO0EFIMVH6WZXhVzCWYXi