BTW, DOWNLOAD part of PassReview DP-600 dumps from Cloud Storage: https://drive.google.com/open?id=1t2_TAlPKkODb7_DGSiMWJ6h-_siKaaIU
The DP-600 practice test of PassReview is created and updated after feedback from thousands of professionals. Additionally, we also offer up to free DP-600 exam dumps updates. These free updates will help you study as per the Microsoft DP-600 latest examination content. Our valued customers can also download a free demo of our Microsoft DP-600 exam dumps before purchasing.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> DP-600 Reliable Test Syllabus <<
Our DP-600 exam torrents can pacify your worries and even help you successfully pass it. The shortage of necessary knowledge of the exam may make you waver, while the abundance of our DP-600 study materials can boost your confidence increasingly. Besides, considering the current status of practice materials market based on exam candidates’ demand, we only add concentrated points into our DP-600 Exam tool to save time and cost for you.
NEW QUESTION # 116
You have a Fabric tenant that contains a workspace named Workspace_DEV. Workspace_DEV contains the semantic models shown in the following table.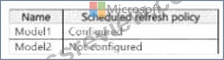
Workspace_DEV contains the dataflows shown in the following table.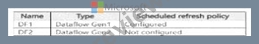
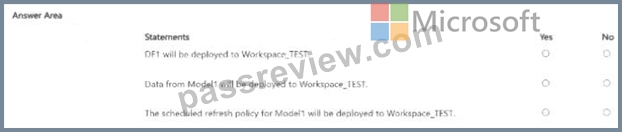
Answer:
Explanation: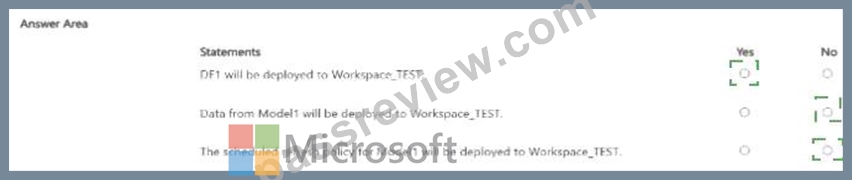
Explanation: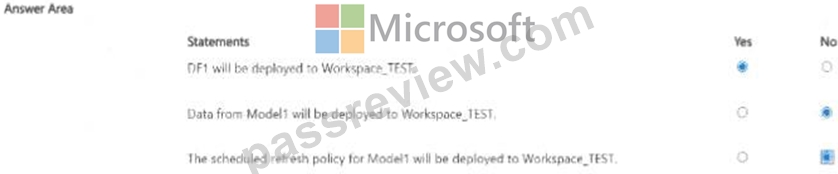
DF1 will be deployed to Workspace_TEST: Yes
Data from Model1 will be deployed to Workspace_TEST: No
The scheduled refresh policy for Model1 will be deployed to Workspace_TEST: No DF1 is a Dataflow Gen1 with a configured scheduled refresh policy, so it will be deployed to Workspace_TEST.
Data from Model1 will not be deployed as Model1 ' s scheduled refresh policy is not configured, indicating it is not set up for deployment.
The scheduled refresh policy for Model1 will not be deployed since it is listed as " Not configured. "
NEW QUESTION # 117
You have a Microsoft Power Bl report named Report1 that uses a Fabric semantic model.
Users discover that Report1 renders slowly.
You open Performance analyzer and identify that a visual named Orders By Date is the slowest to render. The duration breakdown for Orders By Date is shown in the following table.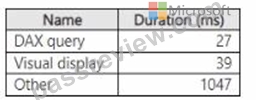
What will provide the greatest reduction in the rendering duration of Report1?
Answer: B
Explanation:
Based on the duration breakdown provided, the major contributor to the rendering duration is categorized as "Other," which is significantly higher than DAX Query and Visual display times. This suggests that the issue is less likely with the DAX calculation or visual rendering times and more likely related to model performance or the complexity of the visual. However, of the options provided, optimizing the DAX query can be a crucial step, even if "Other" factors are dominant. Using DAX Studio, you can analyze and optimize the DAX queries that power your visuals for performance improvements. Here's how you might proceed:
Open DAX Studio and connect it to your Power BI report.
Capture the DAX query generated by the Orders By Date visual.
Use the Performance Analyzer feature within DAX Studio to analyze the query.
Look for inefficiencies or long-running operations.
Optimize the DAX query by simplifying measures, removing unnecessary calculations, or improving iterator functions.
Test the optimized query to ensure it reduces the overall duration.
NEW QUESTION # 118
You have a Fabric tenant that contains a complex semantic model. The model is based on a star schema and contains many tables, including a fact table named Sales. You need to create a diagram of the model. The diagram must contain only the Sales table and related tables. What should you use from Microsoft Power Bl Desktop?
Answer: B
NEW QUESTION # 119
You need to migrate the Research division data for Productline2. The solution must meet the data preparation requirements. How should you complete the code? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.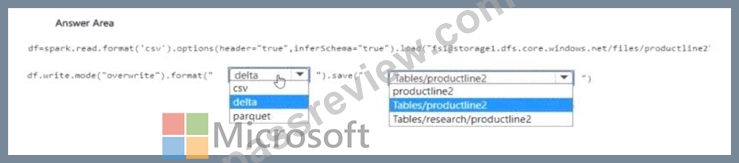
Answer:
Explanation: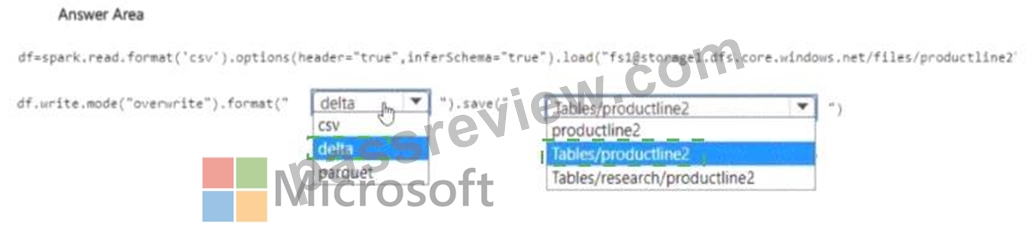
Explanation: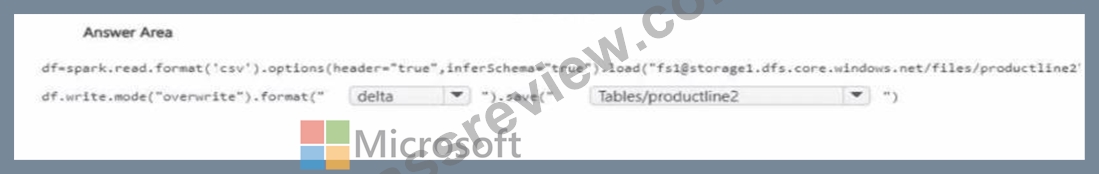
Comprehensive Detailed Explan ation
From the case study:
Research division data for Productline2 is currently in CSV format in storage2.
Requirement: "All the Research division data in the lakehouses must be presented as managed tables in Lakehouse explorer." In Fabric lakehouses, managed tables are stored in Delta format inside the Tables folder.
Step 1: Reading the source
df = spark.read. format ( " csv " ) \
options(header= " true " , inferSchema= " true " ) \
load( " abfss://storage1.dfs.core.windows.net/files/productline2 " )
This correctly ingests the CSV source from ADLS Gen2.
Step 2: Writing to Lakehouse as a managed table
You must write the data in Delta format to ensure it is queryable and managed within the lakehouse.
The correct path is under Tables/ , because this is where Fabric automatically manages Lakehouse managed tables .
The target table should be named productline2 , so the correct path is:
df.write.mode( " overwrite " ). format ( " delta " ).save( " Tables/productline2 " ) Why not other options?
CSV or Parquet formats would not create a managed Lakehouse table; they would just create files.
Writing to productline2 directly (without Tables/ ) would store unmanaged files in the Lakehouse Files area, not managed tables.
Writing to Tables/research/productline2 adds an unnecessary subdirectory and is not the standard structure for managed tables.
Correct Final Code
df.write.mode( " overwrite " ). format ( " delta " ).save( " Tables/productline2 " ) References Managed tables in Microsoft Fabric Lakehouse Delta Lake support in Fabric Spark write to Lakehouse
NEW QUESTION # 120
You have a Fabric workspace that contains a Dataflow Gen2 query. The query returns the following data.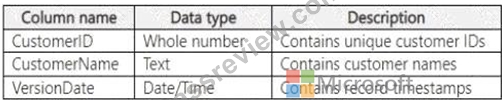
You need to filter the results to ensure that only the latest version of each customer ' s record is retained. The solution must ensure that no new columns are loaded to the semantic model.
Which four actions should you perform in sequence in Power Query Editor? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.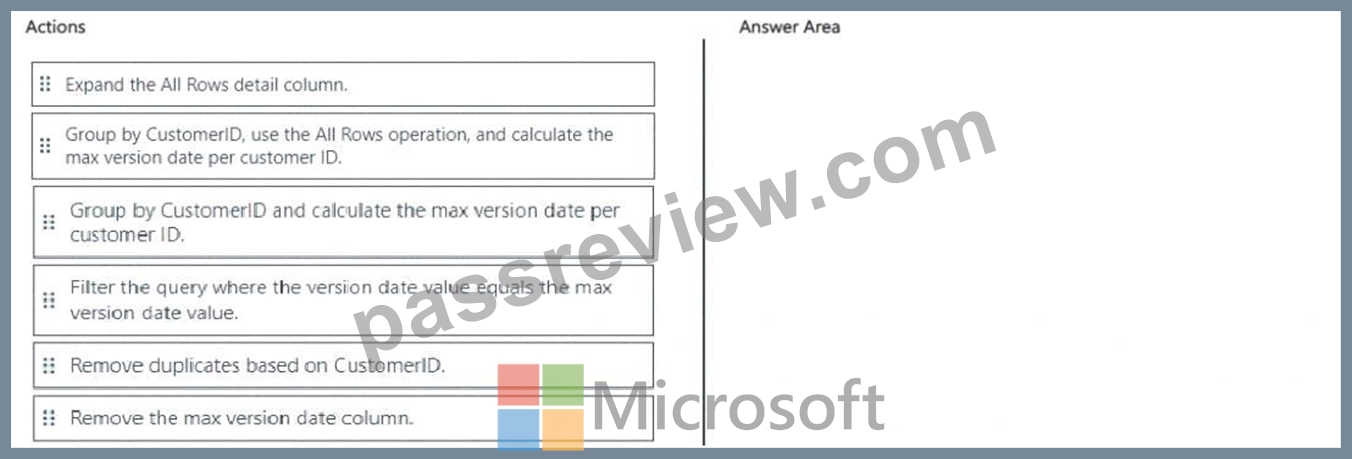
Answer:
Explanation: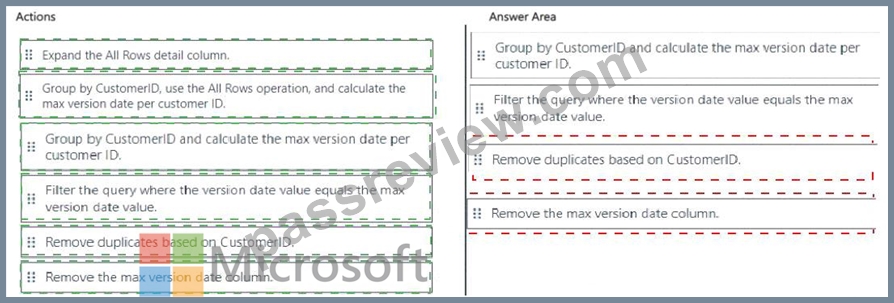
Explanation: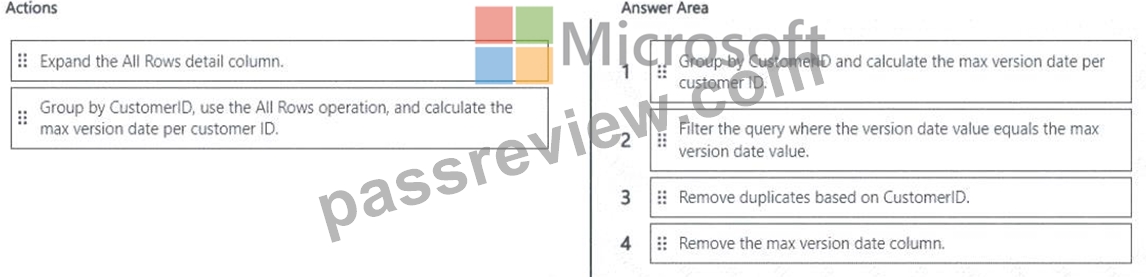
Comprehensive Detailed Explanation
We have a table with:
CustomerID # unique ID
CustomerName # customer's name
VersionDate # timestamp representing version history
The requirement:
Keep only the latest record per customer.
Ensure no new technical columns (like max version date) remain in the semantic model.
Step 1: Identify latest version per customer
We need to determine the latest VersionDate for each CustomerID.
Use Group By CustomerID and calculate Max of VersionDate.
This creates a mapping of CustomerID # latest VersionDate.
Step 2: Filter to keep only latest records
Join or filter original data so that only rows with VersionDate = Max(VersionDate) are retained.
This ensures that only the most recent record is kept per customer.
Step 3: Remove the helper column
The column holding Max VersionDate is only needed for filtering.
It must be removed because the requirement is that no new columns are loaded to the semantic model.
Step 4: Remove duplicates
As a final safeguard, remove duplicates by CustomerID, ensuring that each customer appears only once.
Final Ordered Actions
Group by CustomerID and calculate the max version date per customer ID.
Filter the query where the version date value equals the max version date value.
Remove the max version date column.
Remove duplicates based on CustomerID.
NEW QUESTION # 121
......
After clients pay successfully for our DP-600 guide torrent, they will receive our mails sent by our system in 5-10 minutes. Then they can dick the mail and log in to use our software to learn immediately. For that time is extremely important for the learners, everybody hope that they can get the efficient learning. So clients can use our DP-600 Test Torrent immediately is the great merit of our DP-600 exam questions. When you begin to use, you can enjoy the various functions and benefits of our DP-600 practice guide such as it can simulate the exam and boosts the timing function.
DP-600 Actual Braindumps: https://www.passreview.com/DP-600_exam-braindumps.html
What's more, part of that PassReview DP-600 dumps now are free: https://drive.google.com/open?id=1t2_TAlPKkODb7_DGSiMWJ6h-_siKaaIU