BTW, DOWNLOAD part of TestPassed Databricks-Certified-Data-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1SGm0QpZR8F3ZdS_VHqcKQKZbLM7vMSrl
Choose the right format of Databricks Databricks-Certified-Data-Engineer-Associate actual questions and start Databricks-Certified-Data-Engineer-Associate preparation today. Top Notch Databricks Databricks-Certified-Data-Engineer-Associate Actual Dumps Are Ready for Download. Now is the ideal time to prepare for and crack the Databricks Databricks-Certified-Data-Engineer-Associate Exam. To do this, you just need to enroll in the Databricks-Certified-Data-Engineer-Associate examination and start preparation with top-notch and updated Databricks Databricks-Certified-Data-Engineer-Associate actual exam dumps.
Becoming a Databricks Certified Data Engineer Associate provides several benefits to candidates. Firstly, it validates their skills and knowledge in data engineering, making them more competitive in the job market. Secondly, it demonstrates their commitment to staying current with the latest technologies and their dedication to professional development. Finally, it provides them with access to a community of Databricks-certified professionals, which can help them network and collaborate with other data engineers.
The GAQM Databricks-Certified-Data-Engineer-Associate (Databricks Certified Data Engineer Associate) Certification Exam is designed to test the skills of data engineers who work with Databricks to build and maintain data pipelines. Databricks-Certified-Data-Engineer-Associate exam covers a wide range of topics, including data modeling, data ingestion, data transformation, and data analysis. Successful completion of the exam demonstrates that a candidate has the skills and knowledge required to work effectively as a data engineer with Databricks.
>> Databricks-Certified-Data-Engineer-Associate Dump Torrent <<
By overcoming your mistakes before the actual Databricks Databricks-Certified-Data-Engineer-Associate exam, you can avoid making those same errors during the Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) real test. With customizable Databricks-Certified-Data-Engineer-Associate practice tests, you can adjust the duration and quantity of Databricks-Certified-Data-Engineer-Associate Practice Questions. This self-assessment Databricks-Certified-Data-Engineer-Associate exam display your marks, helping you improve your performance while tracking your progress.
Passing the Databricks Certified Data Engineer Associate Exam demonstrates that the candidate has the skills and knowledge necessary to design, build, and maintain data pipelines and data warehouses using Databricks. It is an important certification for data engineers who want to advance their careers and demonstrate their expertise in using Databricks to solve complex data engineering problems. With the explosive growth of data in today's business environment, the demand for skilled data engineers is higher than ever, and the Databricks Certified Data Engineer Associate Exam is an excellent way to stand out in a crowded job market.
NEW QUESTION # 126
Which of the following describes a benefit of creating an external table from Parquet rather than CSV when using a CREATE TABLE AS SELECT statement?
Answer: B
NEW QUESTION # 127
A data analyst has created a Delta table sales that is used by the entire data analysis team. They want help from the data engineering team to implement a series of tests to ensure the data is clean. However, the data engineering team uses Python for its tests rather than SQL.
Which of the following commands could the data engineering team use to access sales in PySpark?
Answer: C
Explanation:
The data engineering team can use the spark.table method to access the Delta table sales in PySpark. This method returns a DataFrame representation of the Delta table, which can be used for further processing or testing. The spark.table method works for any table that is registered in the Hive metastore or the Spark catalog, regardless of the file format1. Alternatively, the data engineering team can also use the DeltaTable.
forPath method to load the Delta table from its path2. References: 1: SparkSession | PySpark 3.2.0 documentation 2: Welcome to Delta Lake's Python documentation page - delta-spark 2.4.0 documentation
NEW QUESTION # 128
A data engineer runs a statement every day to copy the previous day's sales into the table transactions. Each day's sales are in their own file in the location "/transactions/raw".
Today, the data engineer runs the following command to complete this task: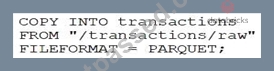
After running the command today, the data engineer notices that the number of records in table transactions has not changed.
Which of the following describes why the statement might not have copied any new records into the table?
Answer: D
Explanation:
The COPY INTO statement is an idempotent operation, which means that it will skip any files that have already been loaded into the target table1. This ensures that the data is not duplicated or corrupted by multiple attempts to load the same file. Therefore, if the data engineer runs the same command every day without specifying the names of the files to be copied with the FILES keyword or a glob pattern with the PATTERN keyword, the statement will only copy the first file that matches the source location and ignore the rest. To avoid this problem, the data engineer should either use the FILES or PATTERN keywords to filter the files to be copied based on the date or some other criteria, or delete the files from the source location after they are copied into the table2. References: 1: COPY INTO | Databricks on AWS 2: Get started using COPY INTO to load data | Databricks on AWS
NEW QUESTION # 129
A data engineer has realized that the data files associated with a Delta table are incredibly small. They want to compact the small files to form larger files to improve performance.
Which of the following keywords can be used to compact the small files?
Answer: C
Explanation:
The keyword that can be used to compact the small files associated with a Delta table is OPTIMIZE. The OPTIMIZE command performs file compaction on a Delta table by rewriting a set of small files into a set of larger files1. This can improve the performance of queries that scan the table by reducing the number of files that need to be read and the amount of metadata that needs to be processed1. The OPTIMIZE command can also optionally sort the data within each file by a given set of columns, which can further improve the query performance by enabling data skipping and predicate pushdown1. The OPTIMIZE command can be applied to the whole table or to a specific partition of the table1.
The other keywords are not suitable for compacting the small files associated with a Delta table. REDUCE is a keyword used in the SQL syntax for aggregating data using a user-defined function2. COMPACTION is not a valid keyword in SQL or Python. REPARTITION is a keyword used in the Python syntax for changing the number of partitions of a DataFrame or an RDD3. VACUUM is a keyword used to remove files that are no longer referenced by a Delta table and are older than a retention threshold4.
1: OPTIMIZE | Databricks on AWS
2: REDUCE | Databricks on AWS
3: repartition | Databricks on AWS
4: VACUUM | Databricks on AWS
NEW QUESTION # 130
A Data Engineer is building a simple data pipeline using Delta Live Tables (DLT) in Databricksto ingest customer data. The raw customer data is stored in a cloud storage location in JSON format. The task is to create a DLT pipeline that reads the rawJSON data and writes it into a Delta table for further processing.
Which code snippet will correctly ingest the raw JSON data and create a Delta table using DLT?
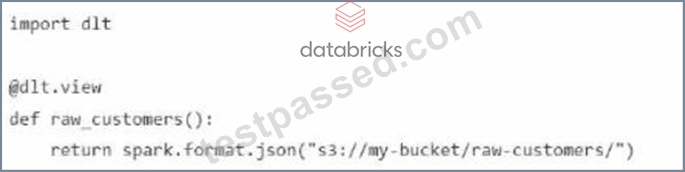
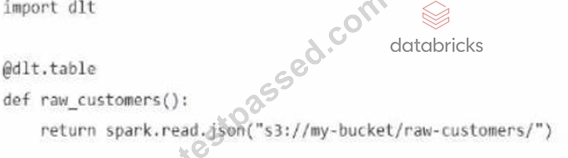
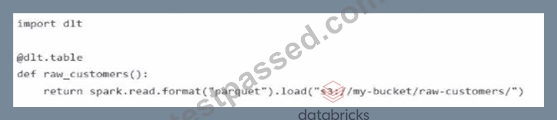
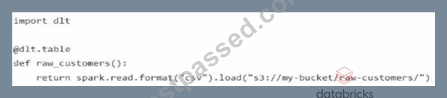
Answer: B
NEW QUESTION # 131
......
Databricks-Certified-Data-Engineer-Associate Actual Tests: https://www.testpassed.com/Databricks-Certified-Data-Engineer-Associate-still-valid-exam.html
P.S. Free 2026 Databricks Databricks-Certified-Data-Engineer-Associate dumps are available on Google Drive shared by TestPassed: https://drive.google.com/open?id=1SGm0QpZR8F3ZdS_VHqcKQKZbLM7vMSrl