BONUS!!! Download part of BraindumpsPass Databricks-Generative-AI-Engineer-Associate dumps for free: https://drive.google.com/open?id=1Bsp_EulrPCbCsieNcykMyJR4I1NrpZGu
It is well known that the best way to improve your competitive advantages in this modern world is to increase your soft power, such as graduation from a first-tier university, fruitful experience in a well-known international company, or even possession of some globally recognized Databricks-Generative-AI-Engineer-Associate certifications, which can totally help you highlight your resume and get a promotion in your workplace to a large extend. As a result, our Databricks-Generative-AI-Engineer-Associate Study Materials raise in response to the proper time and conditions while an increasing number of people are desperate to achieve success and become the elite.
| Section | Objectives |
|---|---|
| Topic 1: Retrieval-Augmented Generation (RAG) | - Vector databases and embeddings
|
| Topic 2: Responsible AI and Governance | - Model governance
|
| Topic 3: Foundations of Generative AI | - Generative AI Concepts
|
| Topic 4: Databricks Mosaic AI Platform | - MLflow for GenAI
|
| Topic 5: Prompt Engineering | - Prompt evaluation
|
>> Databricks-Generative-AI-Engineer-Associate Actual Test <<
If you still feel nervous for the exam, our Databricks-Generative-AI-Engineer-Associate Soft test engine will help you to release your nerves. Databricks-Generative-AI-Engineer-Associate Soft test engine can stimulate the real environment, and you can know the general process of exam by using the exam dumps. What’s more, we provide you with free update for one year, and you can get the latest information for the Databricks-Generative-AI-Engineer-Associate Learning Materials in the following year. We have online service stuff, if you have any questions about the Databricks-Generative-AI-Engineer-Associate exam braindumps, just contact us.
NEW QUESTION # 23
A Generative Al Engineer is tasked with improving the RAG quality by addressing its inflammatory outputs.
Which action would be most effective in mitigating the problem of offensive text outputs?
Answer: B
Explanation:
Addressing offensive or inflammatory outputs in a Retrieval-Augmented Generation (RAG) system is critical for improving user experience and ensuring ethical AI deployment. Here's whyDis the most effective approach:
* Manual data curation: The root cause of offensive outputs often comes from the underlying data used to train the model or populate the retrieval system. By manually curating the upstream data and conducting thorough reviews before the data is fed into the RAG system, the engineer can filter out harmful, offensive, or inappropriate content.
* Improving data quality: Curating data ensures the system retrieves and generates responses from a high-quality, well-vetted dataset. This directly impacts the relevance and appropriateness of the outputs from the RAG system, preventing inflammatory content from being included in responses.
* Effectiveness: This strategy directly tackles the problem at its source (the data) rather than just mitigating the consequences (such as informing users or restricting access). It ensures that the system consistently provides non-offensive, relevant information.
Other options, such as increasing the frequency of data updates or informing users about behavior expectations, may not directly mitigate the generation of inflammatory outputs.
NEW QUESTION # 24
A Generative Al Engineer is creating an LLM system that will retrieve news articles from the year 1918 and related to a user's query and summarize them. The engineer has noticed that the summaries are generated well but often also include an explanation of how the summary was generated, which is undesirable.
Which change could the Generative Al Engineer perform to mitigate this issue?
Answer: B
Explanation:
To mitigate the issue of the LLM including explanations of how summaries are generated in its output, the best approach is to adjust the training or prompt structure. Here's why Option D is effective:
* Few-shot Learning: By providing specific examples of how the desired output should look (i.e., just the summary without explanation), the model learns the preferred format. This few-shot learning approach helps the model understand not only what content to generate but also how to format its responses.
* Prompt Engineering: Adjusting the user prompt to specify the desired output format clearly can guide the LLM to produce summaries without additional explanatory text. Effective prompt design is crucial in controlling the behavior of generative models.
Why Other Options Are Less Suitable:
* A: While technically feasible, splitting the output by newline and truncating could lead to loss of important content or create awkward breaks in the summary.
* B: Tuning chunk sizes or changing embedding models does not directly address the issue of the model's tendency to generate explanations along with summaries.
* C: Revisiting document ingestion logic ensures accurate source data but does not influence how the model formats its output.
By using few-shot examples and refining the prompt, the engineer directly influences the output format, making this approach the most targeted and effective solution.
NEW QUESTION # 25
A Generative AI Engineer I using the code below to test setting up a vector store: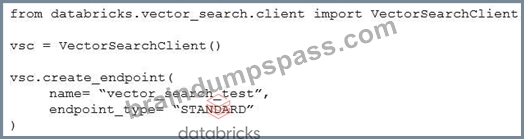
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: C
Explanation:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
NEW QUESTION # 26
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error:
Python
from langchain.chains import LLMChain
from langchain_community.llms import OpenAI
from langchain_core.prompts import PromptTemplate
prompt_template = " Tell me a {adjective} joke "
prompt = PromptTemplate(input_variables=[ " adjective " ], template=prompt_template)
# ... (Error-prone section)
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
Answer: B
NEW QUESTION # 27
A Generative Al Engineer is developing a RAG application and would like to experiment with different embedding models to improve the application performance.
Which strategy for picking an embedding model should they choose?
Answer: C
Explanation:
The task involves improving a Retrieval-Augmented Generation (RAG) application's performance by experimenting with embedding models. The choice of embedding model impacts retrieval accuracy,which is critical for RAG systems. Let's evaluate the options based on Databricks Generative AI Engineer best practices.
* Option A: Pick an embedding model trained on related domain knowledge
* Embedding models trained on domain-specific data (e.g., industry-specific corpora) produce vectors that better capture the semantics of the application's context, improving retrieval relevance. For RAG, this is a key strategy to enhance performance.
* Databricks Reference:"For optimal retrieval in RAG systems, select embedding models aligned with the domain of your data"("Building LLM Applications with Databricks," 2023).
* Option B: Pick the most recent and most performant open LLM released at the time
* LLMs are not embedding models; they generate text, not embeddings for retrieval. While recent LLMs may be performant for generation, this doesn't address the embedding step in RAG. This option misunderstands the component being selected.
* Databricks Reference: Embedding models and LLMs are distinct in RAG workflows:
"Embedding models convert text to vectors, while LLMs generate responses"("Generative AI Cookbook").
* Option C: Pick the embedding model ranked highest on the Massive Text Embedding Benchmark (MTEB) leaderboard hosted by HuggingFace
* The MTEB leaderboard ranks models across general tasks, but high overall performance doesn't guarantee suitability for a specific domain. A top-ranked model might excel in generic contexts but underperform on the engineer's unique data.
* Databricks Reference: General performance is less critical than domain fit:"Benchmark rankings provide a starting point, but domain-specific evaluation is recommended"("Databricks Generative AI Engineer Guide").
* Option D: Pick an embedding model with multilingual support to support potential multilingual user questions
* Multilingual support is useful only if the application explicitly requires it. Without evidence of multilingual needs, this adds complexity without guaranteed performance gains for the current use case.
* Databricks Reference:"Choose features like multilingual support based on application requirements"("Building LLM-Powered Applications").
Conclusion: Option A is the best strategy because it prioritizes domain relevance, directly improving retrieval accuracy in a RAG system-aligning with Databricks' emphasis on tailoring models to specific use cases.
NEW QUESTION # 28
......
Our Databricks-Generative-AI-Engineer-Associate study materials boost the self-learning and self-evaluation functions so as to let the clients understand their learning results and learning process , then find the weak links to improve them. Through the self-learning function the learners can choose the learning methods by themselves and choose the contents which they think are important. Through the self-evaluation function the learners can evaluate their mastery degree of our Databricks-Generative-AI-Engineer-Associate Study Materials and their learning process. The two functions can help the learners adjust their learning arrangements and schedules to efficiently prepare the exam.
Reliable Databricks-Generative-AI-Engineer-Associate Test Dumps: https://www.braindumpspass.com/Databricks/Databricks-Generative-AI-Engineer-Associate-practice-exam-dumps.html
P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by BraindumpsPass: https://drive.google.com/open?id=1Bsp_EulrPCbCsieNcykMyJR4I1NrpZGu