What's more, part of that Pass4SureQuiz AI-300 dumps now are free: https://drive.google.com/open?id=1qCOYJVAZvperQNPI_o4Nm53cFq4h6EgF
Our company has collected the frequent-tested knowledge into our practice materials for your reference according to our experts’ years of diligent work. So our AI-300 exam materials are triumph of their endeavor. By resorting to our AI-300 Practice Guide, we can absolutely reap more than you have imagined before. We have clear data collected from customers who chose our AI-300 training engine, the passing rate is 98-100 percent.
| Section | Objectives |
|---|---|
| Topic 1: Design and implement generative AI solutions | - Large language model integration
|
| Topic 2: Implement secure and scalable AI systems | - Scalability and performance optimization
|
| Topic 3: Plan and design AI solutions using Azure AI services | - Requirements gathering and solution architecture
|
| Topic 4: Operationalizing machine learning solutions | - ML lifecycle management
|
With so many years' development, we can keep stable high passing rate for Microsoft AI-300 exam. You will only spend dozens of money and 20-30 hours' preparation on our Microsoft AI-300 Test Questions, passing exam is easy for you. Microsoft AI-300 exam cram PDF will be the right shortcut for your exam.
NEW QUESTION # 183
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2. You create a General Purpose v2 Azure storage account named mlstorage1. The storage account includes a publicly accessible container named mlcontainer1. The container stores 10 blobs with files in the CSV format.
You must develop Python SDK v2 code to create a data asset referencing all blobs in the container named mlcontainer1.
You need to complete the Python SDK v2 code.
How should you complete the code? To answer, select the appropriate options in the answer area. NOTE:
Each correct selection is worth one point.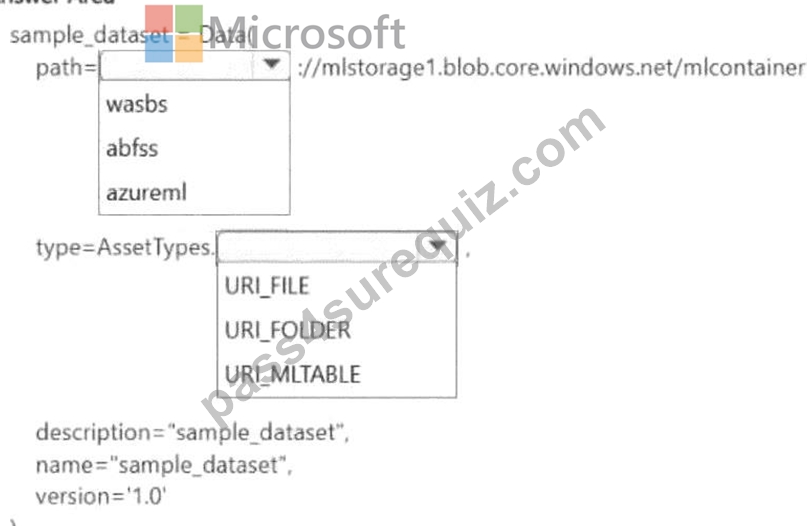
Answer:
Explanation: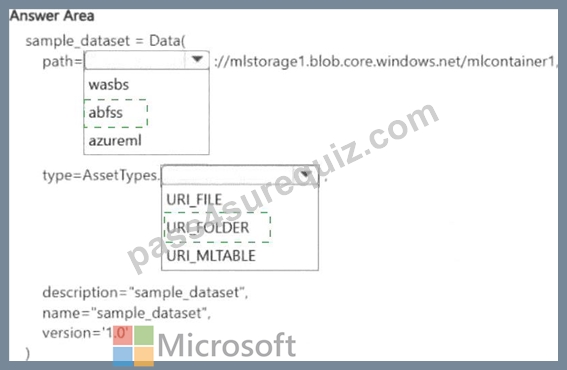
Explanation:
Because you want to reference all blobs in a container rather than a single file, the correct asset type is AssetTypes.URI_FOLDER. This type points to a directory-level URI, allowing Azure ML to traverse all files within it. For a publicly accessible Azure Blob Storage container, the URI follows the pattern
https://storage_account.blob.core.windows.net/container_name/. You then create the Data object with the correct type, path, name, and version parameters, and register it in the workspace using ml_client.data.
create_or_update. Do not use AssetTypes.URI_FILE, which references a single file. Do not use AssetTypes.
MLTABLE unless you have an MLTable YAML descriptor. URI_FOLDER is the correct choice for referencing a collection of CSV blobs in an Azure Blob Storage container, allowing Azure ML to discover and process all files within the specified path.
Microsoft Learn Reference Topic: Create and manage data assets in Azure Machine Learning Python SDK v2
- URI_FOLDER
NEW QUESTION # 184
Hotspot Question
You manage a Retrieval-Augmented Generation (RAG) system that uses Azure AI Search to retrieve documents from an indexed knowledge base.
The system must support the following retrieval requirements:
- Queries that include exact policy identifiers must return matching
documents even when semantic similarity is low.
- Natural-language questions must prioritize semantically relevant
documents even when keywords are not an exact match.
You need to configure the retrieval approach to meet the requirements.
How should you configure the retrieval behavior for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.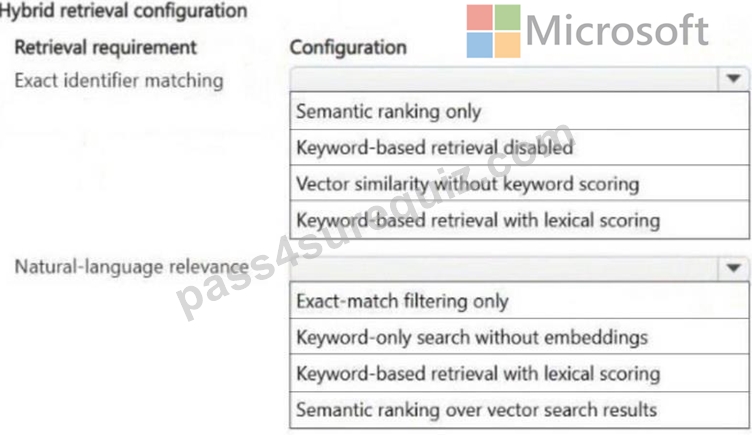
Answer:
Explanation: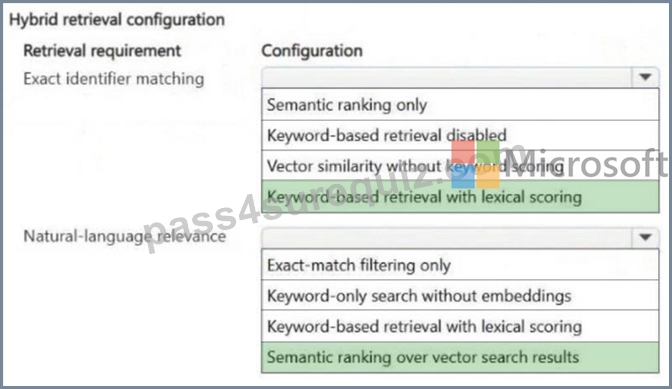
NEW QUESTION # 185
-
A team is developing a Retrieval-Augmented Generation (RAG) system.
The team requires improvements to the system ' s retrieval quality to ensure accurate, grounded responses.
You need to assess RAG performance before you can suggest an improvement strategy.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.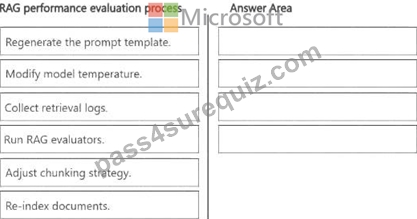
Answer:
Explanation: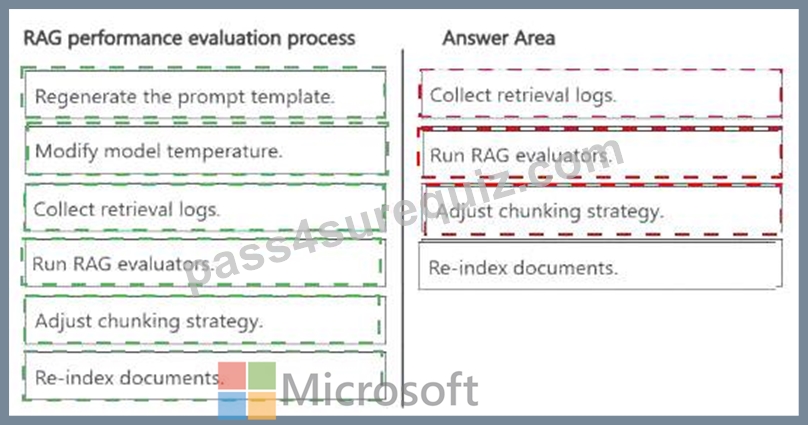
Explanation:
Correct sequence:
* Collect retrieval logs.
* Run RAG evaluators.
* Adjust chunking strategy.
* Re-index documents.
The process should begin by collecting retrieval logs . Retrieval diagnostics provide the evidence needed to understand which queries were issued, which document chunks were returned, and whether relevant content is being surfaced. Without retrieval telemetry, optimization becomes speculative rather than measurable.
Next, run RAG evaluators . Microsoft Foundry provides retrieval-oriented evaluators that assess how relevant retrieved context is to a query. The Retrieval evaluator measures contextual relevance without requiring ground truth, while the Document Retrieval evaluator can calculate metrics such as Fidelity and NDCG when labeled retrieval ground truth exists. These measurements help establish the retrieval-quality baseline before modifications are made.
After identifying retrieval deficiencies, adjust the chunking strategy . Microsoft specifically recommends reviewing chunk size and chunking methodology when retrieval returns irrelevant or incomplete passages.
Chunks that are too small can lose context, while oversized chunks can introduce irrelevant material and reduce retrieval precision.
Finally, re-index the documents so the revised chunking configuration is reflected in the searchable corpus.
Changing temperature or regenerating the prompt template primarily affects generation behavior rather than correcting the underlying retrieval pipeline.
Study Guide Reference: Implement generative AI quality assurance and observability - RAG evaluation, retrieval telemetry, retrieval-quality metrics, chunk optimization, indexing, and grounded-response assessment.
NEW QUESTION # 186
You use an Azure Machine Learning workspace.
You must monitor cost at the endpoint and deployment level.
You have a trained model that must be deployed as an online endpoint. Users must authenticate by using Microsoft Entra ID.
What should you do?
Answer: A
NEW QUESTION # 187
You run Azure Machine Learning training experiments. The training scripts directory contains 100 files that includes a file named .amlignore. The directory also contains subdirectories named ./outputs and ./logs.
There are 20 files in the training scripts directory that must be excluded from the snapshot to the compute targets. You create a file named .gitignore in the root of the directory. You add the names of the 20 files to the .gitignore file. These 20 files continue to be copied to the compute targets.
You need to exclude the 20 files.
What should you do?
Answer: A
Explanation:
To exclude the 20 files from the training snapshot, you must add the file names to the .amlignore file located in the root of your training scripts directory.
Why the Files Are Still Copying
Azure Machine Learning training experiments use a specific order of precedence when creating a directory snapshot for compute targets:
.amlignore takes absolute priority: If an .amlignore file exists in the directory, Azure ML only respects the rules inside it. It completely ignores any .gitignore file present.
.gitignore is a fallback: Azure ML only respects .gitignore rules if an .amlignore file does not exist in the directory. Because you have both files, the .gitignore file is being completely bypassed.
Reference:
https://learn.microsoft.com/en-us/python/api/azureml-core/azureml.core.experiment.experiment
NEW QUESTION # 188
......
You can finish practicing all the contents in our AI-300 practice materials within 20 to 30 hours, and you will be confident enough to attend the exam for our AI-300 exam dumps are exact compiled with the questions and answers of the real exam. What's more, during the whole year after purchasing, you will get the latest version of our AI-300 Study Materials for free. You can see that there are only benefits for you to buy our AI-300 learning guide, so why not just have a try right now?
AI-300 Valid Exam Vce: https://www.pass4surequiz.com/AI-300-exam-quiz.html
DOWNLOAD the newest Pass4SureQuiz AI-300 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1qCOYJVAZvperQNPI_o4Nm53cFq4h6EgF