人生のチャンスを掴むことができる人は殆ど成功している人です。ですから、ぜひJpshikenというチャンスを掴んでください。JpshikenのHPのHPE7-S02試験トレーニング資料はあなたがHPのHPE7-S02認定試験に合格することを助けます。この認証を持っていたら、あなたは自分の夢を実現できます。そうすると人生には意義があります。
| Section | Objectives |
|---|---|
| Topic 1: Server Deployment and Configuration | - Initial setup and provisioning - Firmware and system configuration tools (iLO, SPP) |
| Topic 2: Storage and Networking Integration | - Networking configuration and connectivity options - SAN and direct-attached storage integration |
| Topic 3: Solution Design and Implementation | - Workload sizing and architecture planning - High availability and redundancy design |
| Topic 4: Troubleshooting and Support | - Performance monitoring and diagnostics - Hardware and firmware troubleshooting |
| Topic 5: HPE Compute Architecture and Solutions | - Compute solution positioning and use cases - HPE ProLiant server families overview |
私たちのHPE7-S02練習問題は実際に自分の魅力を持っているため、世界中のユーザーを引き付けました。HPE7-S02練習問題のように、あらゆる面でユーザーのニーズを真剣に検討する練習問題がないです。HPE7-S02練習問題を利用すれば、HPE7-S02試験に合格することは夢ではないです。従って、ためらわなくて、HPE7-S02練習問題を購入し、勉強し始めましょう!
質問 # 56
A customer wants to manage the full lifecycle of their HPE ProLiant Gen11 servers - including firmware updates, monitoring, and remote console access - from a single cloud-based console without deploying an on-premises management appliance. Which HPE solution should the integrator recommend?
正解:A
質問 # 57
A customer uses HPE Synergy servers as VMware ESXi hosts, assigned to clusters. What is one action that is enabled by your importing the ESXi clusters in HPE OneView for vCenter?
正解:B
解説:
This matches VMware Proactive HA with HPE OneView for VMware vCenter. HPE describes this feature as preventing VM downtime by automatically migrating affected workloads before possible hardware degradation disrupts service. HPE's own OV4VC training outline also lists enabling VMware Proactive HA as a management function and separately lists cluster import/grow/shrink as provisioning functions.
質問 # 58
You are demonstrating HPE AI Essentials to a customer. You want to show running a DAG (workflow).
Which framework or page should you access?
正解:A
解説:
D is correct. Airflow is the HPE AI Essentials framework used to define, schedule, and execute directed acyclic graphs. A DAG expresses a workflow as tasks plus dependencies, so the Airflow interface is the appropriate place to demonstrate launching and monitoring a workflow. The UI exposes DAG state, task instances, execution history, schedules, and operational details that make the orchestration behavior visible during a customer demonstration.
NVIDIA AI Enterprise is the broader enterprise AI software suite and includes components such as NIM and NeMo, but it is not the HPE AI Essentials DAG scheduler. MLflow is used for experiment tracking and model lifecycle activities. Ray is a distributed computing framework used for scalable Python and AI workloads; it does not provide the Airflow DAG-management interface requested here.
A useful demonstration can show both control and observability: trigger a DAG, inspect task dependency order, observe task status, and review logs or retries. That makes the distinction between workflow orchestration and the underlying execution frameworks clear.
References/topics: Advanced HPE Compute Solutions, Rev. 26.21, Module 4 "Airflow" and the objective
"Demonstrate HPE AI Essentials"; HPE AI Essentials Software Airflow documentation.
質問 # 59
You are planning to demonstrate how you can use KServe to run NIMs on HPE Private Cloud AI.
You have downloaded the CodeLlama-70B-Instruct model to a volume in your namespace named demo-model. The objects that you are planning to deploy are shown below: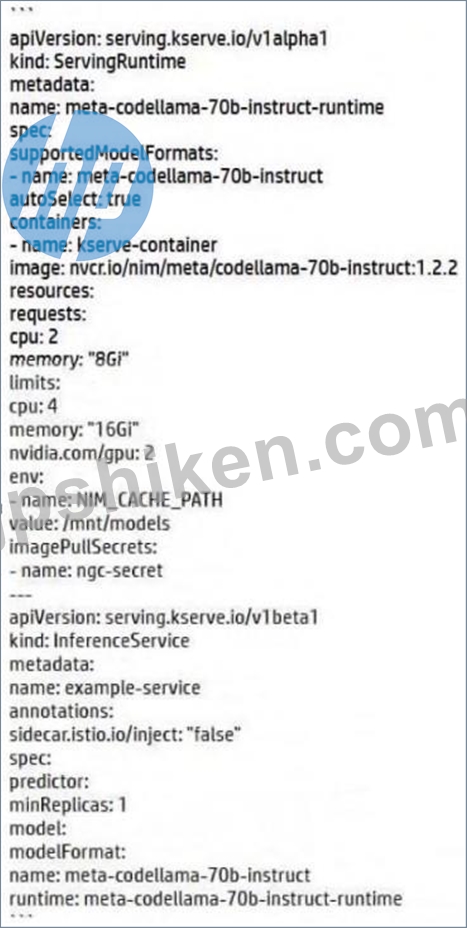
What change should you make to the objects?
正解:C
解説:
The model is already downloaded to a PVC, so the InferenceService must reference that PVC with storageUri. KServe then mounts the model storage for the predictor; you do not change the model format or ServingRuntime. More precisely, this belongs under the predictor's model spec as storageUri.
質問 # 60
An HPE Private Cloud AI customer wants to prevent Airflow from consuming too many resources on the cluster.
What is one approach you can take to fulfill this request?
正解:D
解説:
D is correct. Airflow pools provide a direct mechanism for controlling task concurrency. Each pool has a defined number of slots, and tasks assigned to that pool consume slots while they execute. Reducing the number of slots in the default pool therefore limits the number of tasks that can run simultaneously and places an upper bound on how aggressively Airflow can consume cluster resources across concurrent DAG activity.
Option A is not the supported control in this scenario; the Airflow UI does not serve as the general editor for executor-pod CPU and memory sizing. Option B is the opposite of the stated objective because enabling autoscaling can increase executor capacity in response to demand. Option C suggests changing framework values for executor resources, but HPE's Airflow integration historically constrains those settings and the exam-tested method for limiting aggregate workload pressure is pool concurrency.
This is a scheduling-level safeguard rather than a Kubernetes quota. In a production environment, pool slots can be combined with platform quotas and workload resource requests to create layered control over resource consumption.
References/topics: Advanced HPE Compute Solutions, Rev. 26.21, Module 4 "Airflow" and Module 7 resource troubleshooting; HPE AI Essentials Airflow documentation, pool slots and maximum simultaneous jobs.
質問 # 61
......
HPE7-S02試験はJpshikenの教材を準備し、高品質で合格率が高く、実際のHPE7-S02試験を十分に理解しており、HPE7-S02学習教材を長年にわたって作成した専門家によって完了します。彼らは、HPE7-S02試験の準備をするときに受験者が本当に必要とするものを非常によく知っています。また、実際のHPE7-S02試験の状況を非常によく理解しています。実際の試験がどのようなものかをお知らせします。HPE7-S02試験問題のソフトバージョンを試すことができます。これにより、実際の試験をシミュレートできます。
HPE7-S02模擬練習: https://www.jpshiken.com/HPE7-S02_shiken.html