BONUS!!! Download part of FreePdfDump Professional-Machine-Learning-Engineer dumps for free: https://drive.google.com/open?id=122ilufz61myJYSXOJVq0MEu0tM77U3ep
Google trained experts have made sure to help the potential applicants of Google Professional-Machine-Learning-Engineer certification to pass their Google Professional-Machine-Learning-Engineer exam on the first try. Our PDF format carries real Google Professional Machine Learning Engineer exam dumps. You can use this format of Google Professional-Machine-Learning-Engineer Actual Questions on your smart devices.
| Section | Weight | Objectives |
|---|---|---|
| Monitor and optimize AI solutions | 16% | - Optimize cost, latency, and resource usage - Monitor data quality and pipeline health - Troubleshoot and maintain production systems - Monitor model performance, fairness, and drift |
| Train and deploy models | 20% | - Use Vertex AI deployment features and infrastructure - Implement generative AI deployment patterns - Configure training jobs and environments - Deploy models for online, batch, and streaming prediction |
| Collaborate to manage data and models | 16% | - Organize and prepare enterprise data
- Manage datasets and features in Vertex AI |
| Architect low-code AI solutions | 12% | - Apply responsible AI principles to low-code designs - Identify use cases for low-code/no-code AI tools - Design solutions using Vertex AI Studio, Model Garden, and Agent Builder |
| Scale prototypes into AI models | 18% | - Select appropriate model architectures and frameworks - Design and run experiments - Optimize model performance and generalization - Work with foundation models and generative AI techniques |
| Automate and orchestrate ML pipelines | 18% | - Implement CI/CD for ML systems - Design end-to-end ML workflows - Use Vertex AI Pipelines, TFX, and other orchestration tools - Automate retraining and model updates |
>> Professional-Machine-Learning-Engineer Exam Questions And Answers <<
You can use your smart phones, laptops, the tablet computers or other equipment to download and learn our Professional-Machine-Learning-Engineer learning dump. Moreover, our customer service team will reply the clients’ questions patiently and in detail at any time and the clients can contact the online customer service even in the midnight. The clients at home and abroad can purchase our Professional-Machine-Learning-Engineer Certification Questions online. Our service covers all around the world and the clients can receive our Professional-Machine-Learning-Engineer study practice guide as quickly as possible.
NEW QUESTION # 210
You are designing an architecture with a serverless ML system to enrich customer support tickets with informative metadata before they are routed to a support agent. You need a set of models to predict ticket priority, predict ticket resolution time, and perform sentiment analysis to help agents make strategic decisions when they process support requests. Tickets are not expected to have any domain-specific terms or jargon.
The proposed architecture has the following flow: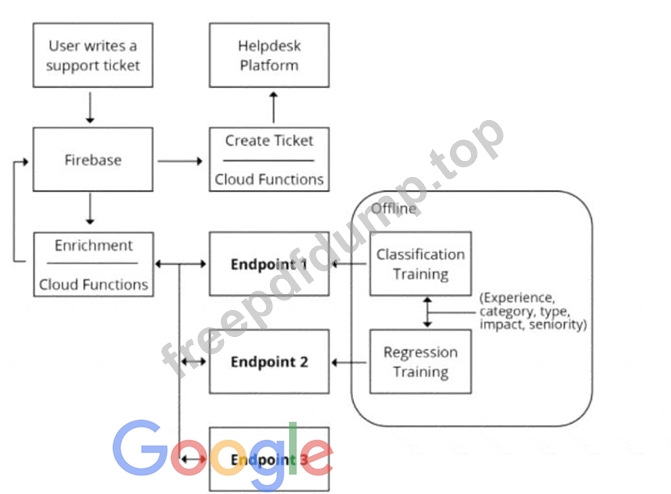
Which endpoints should the Enrichment Cloud Functions call?
Answer: B
Explanation:
Vertex AI is a unified platform for building and deploying ML models on Google Cloud. It supports both custom and AutoML models, and provides various tools and services for ML development, such as Vertex Pipelines, Vertex Vizier, Vertex Explainable AI, and Vertex Feature Store. Vertex AI can be used to create models for predicting ticket priority and resolution time, as these are domain-specific tasks that require custom training data and evaluation metrics. Cloud Natural Language API is a pre-trained service that provides natural language understanding capabilities, such as sentiment analysis, entity analysis, syntax analysis, and content classification. Cloud Natural Language API can be used toperform sentiment analysis on the support tickets, as this is a general task that does not require domain-specific knowledge or jargon. The other options are not suitable for the given architecture. AutoML Natural Language and AutoML Vision are services that allow users to create custom natural language and vision models using their own data and labels. They are not needed for sentiment analysis, as Cloud Natural Language API already provides this functionality. Cloud Vision API is a pre-trained service that provides image analysis capabilities, such as object detection, face detection, text detection, and image labeling. It is not relevant for the support tickets, as they are not expected to have any images. References:
* Vertex AI documentation
* Cloud Natural Language API documentation
NEW QUESTION # 211
You work for a credit card company and have been asked to create a custom fraud detection model based on historical data using AutoML Tables. You need to prioritize detection of fraudulent transactions while minimizing false positives. Which optimization objective should you use when training the model?
Answer: A
Explanation:
In this scenario, the goal is to create a custom fraud detection model using AutoML Tables. Fraud detection is a type of binary classification problem, where the model needs to predict whether a transaction is fraudulent or not. The optimization objective is a metric that defines how the model is trained and evaluated. AutoML Tables allows you to choose from different optimization objectives for binary classification problems, such as Log loss, Precision at a Recall value, AUC PR, and AUC ROC.
To choose the best optimization objective for fraud detection, we need to consider the characteristics of the problem and the data. Fraud detection is a problem where the positive class (fraudulent transactions) is very rare compared to the negative class (legitimate transactions). This means that the data is highly imbalanced, and the model needs to be sensitive to the minority class. Moreover, fraud detection is a problem where the cost of false negatives (missing a fraudulent transaction) is much higher than the cost of false positives (flagging a legitimate transaction as fraudulent). This means that the model needs to have high recall (the ability to detect all fraudulent transactions) while maintaining high precision (the ability to avoid false alarms).
Given these considerations, the best optimization objective for fraud detection is the one that maximizes the area under the precision-recall curve (AUC PR) value. The AUC PR value is a metric that measures the trade- off between precision and recall for different probability thresholds. A higher AUC PR value means that the model can achieve high precision and high recall at the same time. The AUC PR value is also more suitable for imbalanced data than the AUC ROC value, which measures the trade-off between the true positive rate and the false positive rate. The AUC ROC value can be misleading for imbalanced data, as it can give a high score even if the model has low recall or low precision.
Therefore, option C is the correct answer. Option A is not suitable, as Log loss is a metric that measures the difference between the predicted probabilities and the actual labels, and does not account for the trade-off between precision and recall. Option B is not suitable, as Precision at a Recall value is a metric that measures the precision at a fixed recall level, and does not account for the trade-off between precision and recall at different thresholds. Option D is not suitable, as AUC ROC is a metric that can be misleading for imbalanced data, as explained above.
References:
AutoML Tables documentation
Optimization objectives for binary classification
Precision-Recall Curves: How to Easily Evaluate Machine Learning Models in No Time ROC Curves and Area Under the Curve Explained (video)
NEW QUESTION # 212
A Machine Learning Specialist is required to build a supervised image-recognition model to identify a cat. The ML Specialist performs some tests and records the following results for a neural network-based image classifier:
Total number of images available = 1,000
Test set images = 100 (constant test set)
The ML Specialist notices that, in over 75% of the misclassified images, the cats were held upside down by their owners.
Which techniques can be used by the ML Specialist to improve this specific test error?
Answer: D
NEW QUESTION # 213
Your data science team has requested a system that supports scheduled model retraining, Docker containers, and a service that supports autoscaling and monitoring for online prediction requests. Which platform components should you choose for this system?
Answer: D
Explanation:
* Option A is incorrect because Vertex AI Pipelines and App Engine do not meet all the requirements of the system. Vertex AI Pipelines is a service that allows you to create, run, andmanage ML workflows using TensorFlow Extended (TFX) components or custom components1. App Engine is a service that allows you to build and deploy scalable web applications using standard or flexible environments2. However, App Engine does not support Docker containers in the standard environment, and does not provide a dedicated service for online prediction and monitoring of ML models3.
* Option B is correct because Vertex AI Pipelines, Vertex AI Prediction, and Vertex AI Model Monitoring meet all the requirements of the system. Vertex AI Prediction is a service that allows you to deploy and serve ML models for online or batch prediction, with support for autoscaling and custom containers4. Vertex AI Model Monitoring is a service that allows you to monitor the performance and fairness of your deployed models, and get alerts for any issues or anomalies5.
* Option C is incorrect because Cloud Composer, BigQuery ML, and Vertex AI Prediction do not meet all the requirements of the system. Cloud Composer is a service that allows you to create, schedule, and
* manage workflows using Apache Airflow. BigQuery ML is a service that allows you to create and use ML models within BigQuery using SQL queries. However, BigQuery ML does not support custom containers, and Vertex AI Prediction does not support scheduled model retraining or model monitoring.
* Option D is incorrect because Cloud Composer, Vertex AI Training with custom containers, and App Engine do not meet all the requirements of the system. Vertex AI Training is a service that allows you to train ML models using built-in algorithms or custom containers. However, Vertex AI Training does not support online prediction or model monitoring, and App Engine does not support Docker containers in the standard environment or online prediction and monitoring of ML models3.
References:
* Vertex AI Pipelines overview
* App Engine overview
* Choosing an App Engine environment
* Vertex AI Prediction overview
* Vertex AI Model Monitoring overview
* [Cloud Composer overview]
* [BigQuery ML overview]
* [BigQuery ML limitations]
* [Vertex AI Training overview]
NEW QUESTION # 214
You developed a Vertex Al ML pipeline that consists of preprocessing and training steps and each set of steps runs on a separate custom Docker image Your organization uses GitHub and GitHub Actions as CI/CD to run unit and integration tests You need to automate the model retraining workflow so that it can be initiated both manually and when a new version of the code is merged in the main branch You want to minimize the steps required to build the workflow while also allowing for maximum flexibility How should you configure the CI/CD workflow?
Answer: A
Explanation:
The best option for automating the model retraining workflow is to use GitHub Actions and Cloud Build.
GitHub Actions is a service that can create and run workflows for continuous integration and continuous delivery (CI/CD) on GitHub. GitHub Actions can run tests, build and deploy code, andtrigger other actions based on events such as code changes, pull requests, or manual triggers. Cloud Build is a service that can create and run scalable and reliable pipelines to build, test, and deploy software on Google Cloud. Cloud Build can build custom Docker images, push the images to Artifact Registry, and launch the pipeline in Vertex AI Pipelines. Vertex AI Pipelines is a service that can orchestrate machine learning (ML) workflows using Vertex AI. Vertex AI Pipelines can run preprocessing and training steps on custom Docker images, and evaluate, deploy, and monitor the ML model. By using GitHub Actions and Cloud Build, users can leverage the power and flexibility of Google Cloud to automate the model retraining workflow, while minimizing the steps required to build the workflow.
The other options are not as good as option D, for the following reasons:
* Option A: Triggering a Cloud Build workflow to run tests, build custom Docker images, push the images to Artifact Registry, and launch the pipeline in Vertex AI Pipelines would require more configuration and maintenance than using GitHub Actions and Cloud Build. Cloud Build is a service that can create and run pipelines to build, test, and deploy software on Google Cloud, but it is not designed to integrate with GitHub or other source code repositories. To trigger a Cloud Build workflow from GitHub, users would need to set up a webhook, a Cloud Pub/Sub topic, and a Cloud Function1. Moreover, Cloud Build does not support manual triggers, which limits the flexibility of the workflow2.
* Option B: Triggering GitHub Actions to run the tests, launching a job on Cloud Run to build custom Docker images, pushing the images to Artifact Registry, and launching the pipeline in Vertex AI Pipelines would require more steps and resources than using GitHub Actions and Cloud Build. Cloud Run is a service that can run stateless containers on a fully managed environment or on Anthos. Cloud Run can build custom Docker images, but it is not optimized for this task. Users would need to write a Dockerfile, a cloudbuild.yaml file, and a Cloud Run service configuration file, and use the gcloud command-line tool to build and deploy the image3. Moreover, Cloud Run is designed for serving HTTP requests, not for running ML pipelines, which can have different performance and scalability requirements.
* Option C: Triggering GitHub Actions to run the tests, building custom Docker images, pushing the images to Artifact Registry, and launching the pipeline in Vertex AI Pipelines would require more skills and tools than using GitHub Actions and Cloud Build. GitHub Actions can run tests and build code, but it is not specialized for building Docker images. Users would need to install and configure Docker on the GitHub Actions runner, write a Dockerfile, and use the docker command-line tool to build and push the image. Moreover, GitHub Actions has limitations on the disk space, memory, and CPU of the runner, which can affect the speed and reliability of the image building process.
References:
* Building CI/CD for Vertex AI pipelines: The first solution
* Cloud Build
* GitHub Actions
* Vertex AI Pipelines
* Triggering builds from GitHub
* Triggering builds manually
* Building containers
* Cloud Run
* [Building and testing Docker images with GitHub Actions]
* [Usage limits, billing, and administration]
NEW QUESTION # 215
......
On the pages of our Professional-Machine-Learning-Engineer study tool, you can see the version of the product, the updated time, the quantity of the questions and answers, the characteristics and merits of the product, the price of our product, the discounts to the client, the details and the guarantee of our Professional-Machine-Learning-Engineer study torrent, the methods to contact us, the evaluations of the client on our product, the related exams and other information about our Google Professional Machine Learning Engineer test torrent. Thus you could decide whether it is worthy to buy our product or not after you understand the features of details of our product carefully on the pages of our Professional-Machine-Learning-Engineer Study Tool on the website.
Latest Professional-Machine-Learning-Engineer Exam Simulator: https://www.freepdfdump.top/Professional-Machine-Learning-Engineer-valid-torrent.html
2026 Latest FreePdfDump Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=122ilufz61myJYSXOJVq0MEu0tM77U3ep