BTW, DOWNLOAD part of TestPDF Databricks-Certified-Data-Engineer-Professional dumps from Cloud Storage: https://drive.google.com/open?id=1ccgcojJRxmBg2qdrwngmiBWxcJBnSpEi
Quitters never win and winners never quit. If you are determined to clear Databricks-Certified-Data-Engineer-Professional exam and obtain a certification you shouldn't give up because of one failure. If you are willing, our Databricks Databricks-Certified-Data-Engineer-Professional valid exam simulations file can help you clear exam and regain confidence. Every year there are thousands of candidates choosing our products and obtain certifications so that our Databricks-Certified-Data-Engineer-Professional valid exam simulations file is famous for its high passing-rate in this field. If you want to pass exam one-shot, you shouldn't miss our files.
| Section | Weight | Objectives |
|---|---|---|
| Monitoring and Troubleshooting | 16% | - Troubleshooting - Monitoring - Performance Optimization |
| Data Processing | 28% | - Structured Streaming - ETL Pipelines - Data Transformation - Spark SQL |
| Data Modeling and Storage | 20% | - File Formats - Storage Optimization - Data Modeling |
| Databricks Lakehouse Platform | 24% | - Unity Catalog - Lakehouse Architecture - Data Management - Delta Lake |
| Data Quality and Governance | 12% | - Data Quality - Data Lineage - Governance |
>> Valid Exam Databricks Databricks-Certified-Data-Engineer-Professional Book <<
TestPDF is one of the only few platforms offering updated Databricks exam preparatory products for the Databricks-Certified-Data-Engineer-Professional at an affordable rate. Our Databricks Databricks-Certified-Data-Engineer-Professional exam questions preparation products help you know your weaknesses before the actual Databricks Certified Data Engineer Professional Exam exam. Databricks Databricks-Certified-Data-Engineer-Professional Exam Questions preparation materials are affordable for everyone. Moreover, we give you free updates for 365 days. TestPDF offers reliable, updated Databricks Exam Questions at an affordable price and also gives a 30% discount on all Databricks exam questions.
NEW QUESTION # 90
A Data Engineer is building a simple data pipeline using Lakeflow Declarative Pipelines (LDP) in Databricks to ingest customer data. The raw customer data is stored in a cloud storage location in JSON format. The task is to create Lakeflow Declarative Pipelines that read the raw JSON data and write it into a Delta table for further processing. Which code snippet will correctly ingest the raw JSON data and create a Delta table using LDP?
Answer: C
Explanation:
The correct method to define a table using Lakeflow Declarative Pipelines (LDP) is with the
@dlt.table decorator, which persists the output as a managed Delta table. When ingesting raw JSON data, spark.read.json() or spark.read.format("json").load() is the standard approach. This reads JSON- formatted files from the source and stores them in Delta format automatically managed by Databricks.
NEW QUESTION # 91
The data engineering team maintains the following code: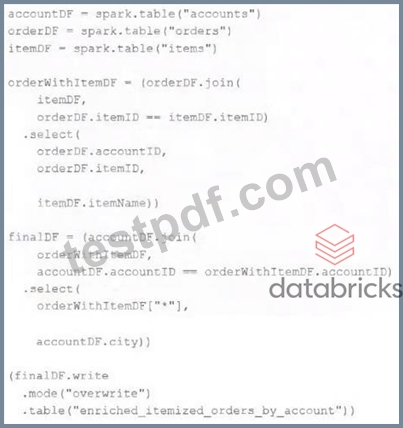
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
Answer: D
Explanation:
This is the correct answer because it describes what will occur when this code is executed. The code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables.
NEW QUESTION # 92
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.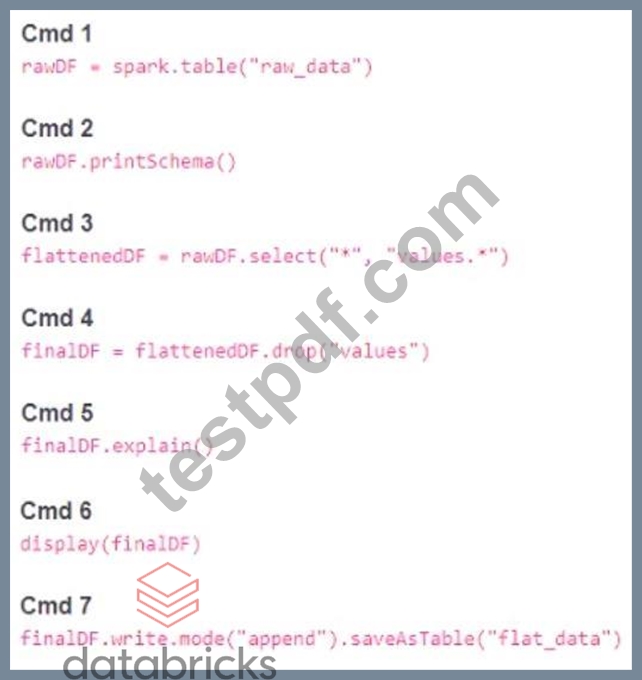
Which command should be removed from the notebook before scheduling it as a job?
Answer: E
Explanation:
When scheduling a Databricks notebook as a job, it's generally recommended to remove or modify commands that involve displaying output, such as using the display() function. Displaying data using display() is an interactive feature designed for exploration and visualization within the notebook interface and may not work well in a production job context.
The finalDF.explain() command, which provides the execution plan of the DataFrame transformations and actions, is often useful for debugging and optimizing queries. While it doesn't display interactive visualizations like display(), it can still be informative for understanding how Spark is executing the operations on your DataFrame.
NEW QUESTION # 93
A data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs. A DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens.
Which statement describes the contents of the workspace audit logs concerning these events?
Answer: C
Explanation:
The events are that a data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs, and a DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens. The workspace audit logs are logs that record user activities in a Databricks workspace, such as creating, updating, or deleting objects like clusters, jobs, notebooks, or tables. The workspace audit logs also capture the identity of the user who performed each activity, as well as the time and details of the activity.
Because these events are managed separately, User A will have their identity associated with the job creation events and User B will have their identity associated with the job run events in the workspace audit logs.
NEW QUESTION # 94
What describes a primary technical challenge in ensuring consistent PII masking across all nodes in large-scale, distributed Databricks batch and streaming pipelines?
Answer: B
Explanation:
Consistent PII masking in distributed batch and streaming pipelines requires centrally defined and governed masking logic. Standardizing masking functions and enforcing them through Unity Catalog ensures that the same rules are applied uniformly across all datasets and execution paths, preventing inconsistencies across nodes and workloads.
NEW QUESTION # 95
......
This Databricks-Certified-Data-Engineer-Professional certification assists you to put your career on the right track and helps you to achieve your career goals in a short time period. There are several personal and professional benefits that you can gain after passing the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) certification exam. The prominent Databricks-Certified-Data-Engineer-Professional certification benefits include validation of skills and knowledge, more career opportunities, instant rise in salary, quick promotion, etc.
Databricks-Certified-Data-Engineer-Professional Actual Exam: https://www.testpdf.com/Databricks-Certified-Data-Engineer-Professional-exam-braindumps.html
P.S. Free & New Databricks-Certified-Data-Engineer-Professional dumps are available on Google Drive shared by TestPDF: https://drive.google.com/open?id=1ccgcojJRxmBg2qdrwngmiBWxcJBnSpEi