The Microsoft AI-200 Certification Exam is one of the top-rated career advancement certifications in the market. With the Developing AI Cloud Solutions on Azure AI-200 certification exam everyone can validate their skills and knowledge after passing the AI-200 text. The Microsoft Developing AI Cloud Solutions on Azure certification exam will recognize your expertise and knowledge in the market. You will get solid proof of your proven skill set. There are other countless benefits that you can gain after passing the Microsoft Developing AI Cloud Solutions on Azure certification exam.
| Section | Weight | Objectives |
|---|---|---|
| Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
| Integrate backend services and build event-driven architectures | 25% | - Build serverless APIs and workflows
|
| Develop AI solutions using Azure data services | 30% | - Implement vector-enabled databases
|
| Develop containerized AI solutions on Azure | 25% | - Implement container hosting environments
|
In order to facilitate the wide variety of users' needs the AI-200 study guide have developed three models with the highest application rate in the present - PDF, software and online. Online mode of another name is App of study materials, it is developed on the basis of a web browser, as long as the user terminals on the browser, can realize the application which has applied by the AI-200 simulating materials of this learning model, users only need to open the App link, you can quickly open the learning content in real time in the ways of the AI-200 study materials.
NEW QUESTION # 121
You deploy a new revision of an app in Azure Container Apps.
You need to gradually shift production traffic to the revision while monitoring performance. In addition, you need to be able to quickly roll back. Which two actions should you perform?
Each correct answer presents part of the solution. Choose two.
NOTE: Each correct selection is worth one point.
Answer: C,E
Explanation:
Detailed Explanation: Gradual production rollout requires more than one revision to remain active and a mechanism to divide traffic between them. Multiple revision mode permits concurrent active revisions, and traffic splitting lets a specified percentage of requests flow to the new revision while the remainder stays on the proven revision. This also enables rapid rollback by returning traffic to the prior revision. Increasing replicas or restarting a revision changes capacity or process state, not release traffic distribution.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | Azure Container Apps revisions
NEW QUESTION # 122
Hotspot Question
You are developing a Retrieval-Augmented Generation (RAG) solution for a company.
AI responses and embedding vectors are cached in Redis.
The solution must meet the following requirements:
- AI responses must expire exactly 24 hours after they are cached.
- Cached embeddings must always reflect the current source data.
You need to configure Redis to meet the requirements.
NOTE: Each correct selection is worth one point.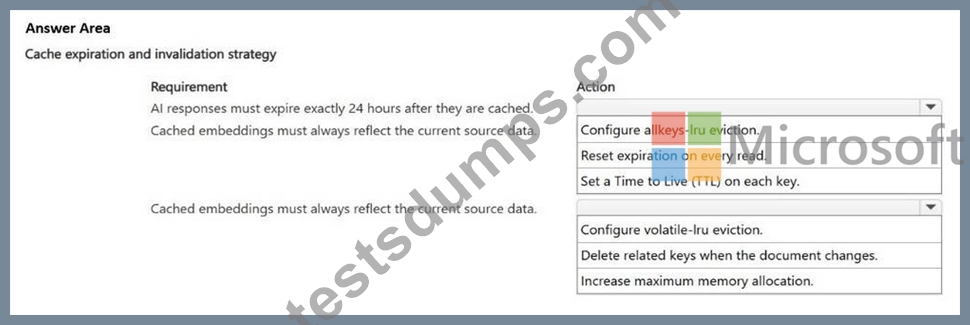
Answer:
Explanation: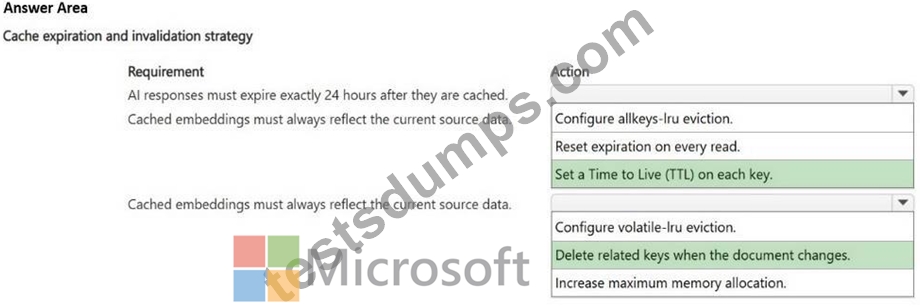
Explanation:
Box 1: Set a Time for Live (TTL) on each key.
To configure Redis to expire your AI responses exactly 24 hours after caching, you must apply a Time-To-Live (TTL) of 86,400 seconds to the specific keys holding those responses.
Box 2: Delete related keys when the document changes
You must invalidate or update those cached keys when source data changes to prevent your RAG system from retrieving stale information.
Incorrect:
Configuring allkeys-lru (Least Recently Used) is not recommended to ensure your cached embeddings or AI responses reflect current source data.allkeys-lru is an eviction policy. It only deletes data when Redis reaches its maximum memory limit, and it targets keys that haven't been accessed recently. It does not verify if the underlying source data has changed, meaning users will get dangerously outdated (hallucinated) AI responses if the source document is updated but the cached response remains in memory.
Reference:
https://zenvanriel.com/ai-engineer-blog/ai-caching-strategies/
NEW QUESTION # 123
An AI application retrieves configuration values from App Configuration. The application uses static configuration.
You need to implement a solution that supports dynamic configuration updates and minimizes latency for application requests.
What should you do?
Answer: D
Explanation:
You should cache configuration values with a refresh interval.
Enables Dynamic Configuration: Azure App Configuration providers natively support a cache- polling mechanism. Once the refresh interval expires, the application checks for updates and reloads configuration values automatically without requiring an application restart.
Minimizes Latency: By pulling configuration values from a local, in-memory cache for all intermediary requests, you completely bypass the network latency of making a remote API call to Azure on every single application request.
Prevents Throttling: Relying on cached values prevents your application from exhausting your App Configuration resource's request quota.
Reference:
https://learn.microsoft.com/en-us/azure/azure-app-configuration/howto-best-practices
NEW QUESTION # 124
You are developing an application that must extract structured field data (invoice number, total, vendor name) from scanned invoices in multiple layouts.
You need a solution that requires no custom model training.
What should you use?
Answer: C
Explanation:
Use the Azure AI Document Intelligence prebuilt invoice model . The prebuilt invoice model is specifically designed to analyze invoices and extract structured fields and line items without requiring an organization to train a custom model. Microsoft documents support for fields including InvoiceId , VendorName , InvoiceTotal , InvoiceDate, CustomerName, AmountDue, tax information, addresses, and invoice line items.
Because the model is pretrained to recognize common invoice structures, it can process invoices that use different layouts and formats while returning normalized structured output. This directly satisfies the requirement to extract invoice number, total, and vendor information from scanned documents while minimizing development and training effort.
The Azure AI Vision Read API performs OCR and can extract printed or handwritten text, but it does not provide invoice-specific semantic field extraction. Custom named entity recognition would require training and is designed for text entity extraction rather than document-layout understanding. A Document Intelligence custom neural model can handle organization-specific forms and layouts, but it requires custom model training, directly violating the requirement.
Therefore, the prebuilt invoice model provides the required combination of OCR, document understanding, structured extraction, and zero custom training.
Study Guide references: Azure AI Document Intelligence # prebuilt invoice model; structured field extraction; OCR; invoice fields and line items.
NEW QUESTION # 125
You are investigating high latency in an AI search application that processes millions of requests daily.
Telemetry is stored in Azure Monitor Logs.
You must create a KQL query that correlates information from the AppRequests table and the AppDependencies table. The query must meet the following requirements:
* Include only data from the last 24 hours.
* Filter for failed requests only.
* Calculate the average duration of dependencies, grouped by operation.
The query must follow best practice to optimize the performance by minimizing the initial data scan.
You need to create the query.
In which order should perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.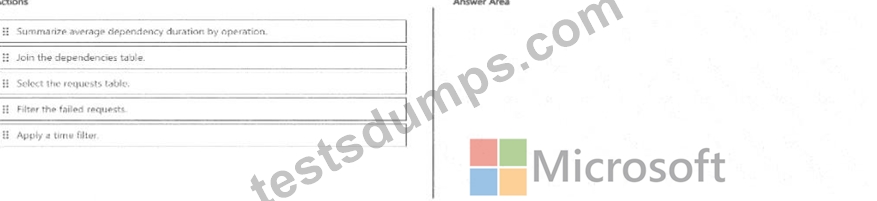
Answer:
Explanation: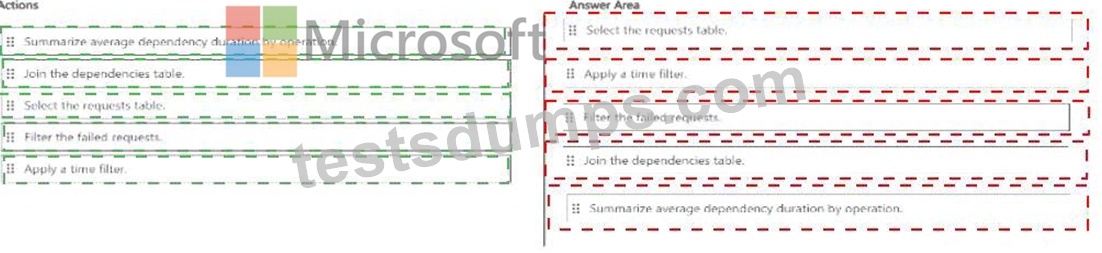
Explanation: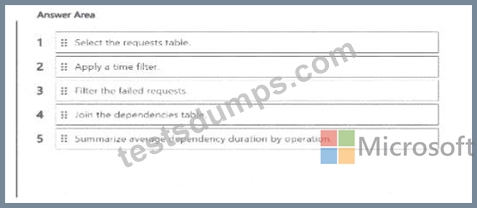
Verified answer: 1) Select the requests table; 2) apply the 24-hour time filter; 3) filter failed requests; 4) join the dependencies table; 5) summarize average dependency duration by operation.
Detailed Explanation: KQL performs best when high-selectivity filters are applied as early as possible, especially the time predicate that limits the amount of data scanned. Starting from AppRequests, restricting to the last 24 hours, and then filtering failures reduces the left-side dataset before the join. The dependency table is then correlated with those requests, and aggregation is performed last to calculate average dependency duration by operation. Joining or summarizing before the time and failure filters would process more data than necessary.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Optimize log queries in Azure Monitor
NEW QUESTION # 126
......
In informative level, we should be more efficient. In order to take the initiative, we need to have a strong ability to support the job search. And how to get the test AI-200 certification in a short time, which determines enough qualification certificates to test our learning ability and application level. We hope to be able to spend less time and energy to take into account the test AI-200 Certification, but the qualification examination of the learning process is very wasted energy, so how to achieve the balance? The AI-200 exam prep can be done to help you pass the AI-200 exam.
AI-200 Latest Exam Camp: https://www.testsdumps.com/AI-200_real-exam-dumps.html