The ExamsReviews is one of the top-rated and reliable platforms that has been helping the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam candidates for many years. Over this long time period, these Databricks-Certified-Data-Engineer-Professional questions have helped countless Databricks-Certified-Data-Engineer-Professional exam candidates. They all got help from the top-rated Databricks-Certified-Data-Engineer-Professional Practice Test questions and easily passed their dream Databricks Databricks-Certified-Data-Engineer-Professional certification exam and now they have become certified Databricks-Certified-Data-Engineer-Professional professionals and doing jobs in top world brands.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Cost & Performance Optimisation | 13% | - Apply cost management best practices - Improve query and pipeline performance - Optimize compute and storage resources |
| Topic 2: Ensuring Data Security and Compliance | 10% | - Secure data at rest and in transit - Ensure data privacy and compliance - Implement access control and permissions |
| Topic 3: Data Transformation, Cleansing, and Quality | 10% | - Enforce data quality standards - Apply data cleansing and validation rules - Implement schema evolution and management |
| Topic 4: Data Sharing and Federation | 5% | - Manage cross-platform data access - Use Delta Sharing for secure data sharing - Implement Lakehouse Federation |
| Topic 5: Monitoring and Alerting | 10% | - Track data lineage and metrics - Monitor pipeline performance and health - Set up alerts and notifications |
| Topic 6: Data Ingestion & Acquisition | 7% | - Handle incremental and batch data loads - Ingest data from diverse sources - Use Auto Loader and structured streaming |
| Topic 7: Debugging and Deploying | 10% | - Deploy using Asset Bundles, CLI, and APIs - Implement CI/CD and DevOps practices - Troubleshoot and debug pipelines |
| Topic 8: Data Governance | 7% | - Enforce data policies and standards - Manage data assets and metadata - Use Unity Catalog for governance |
| Topic 9: Developing Code for Data Processing using Python and SQL | 22% | - Implement complex data processing logic - Use Databricks-specific libraries and APIs - Write efficient and maintainable code |
| Topic 10: Data Modelling | 6% | - Implement dimensional and relational models - Design Medallion Architecture - Optimize table design and partitioning |
>> Exam Databricks-Certified-Data-Engineer-Professional Blueprint <<
We even guarantee our customers that they will pass Databricks Databricks-Certified-Data-Engineer-Professional Exam easily with our provided study material and if they failed to do it despite all their efforts they can claim a full refund of their money (terms and conditions apply). The third format is the desktop software format which can be accessed after installing the software on your Windows computer or laptop. The Databricks Certified Data Engineer Professional Exam has three formats so that the students don't face any serious problems and prepare themselves with fully focused minds.
NEW QUESTION # 230
A data engineer wants to refactor the following DLT code, which includes multiple table definitions with very similar code.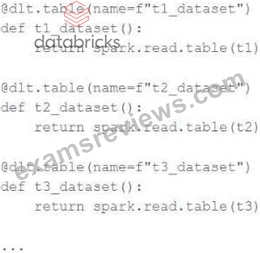
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.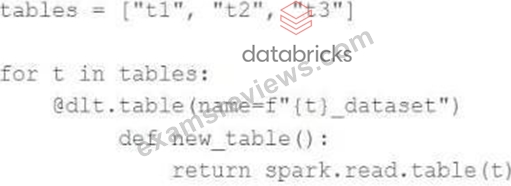
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for these tables.
How can the data engineer fix this?
Answer: C
Explanation:
In the provided refactored code, the for loop dynamically attempts to define multiple tables, but the use of a loop within the DLT (@dlt.table) decorator does not work properly because it results in a single function reference being overwritten for each iteration. This leads to an incorrect DAG because all the table definitions end up pointing to the last iteration of the loop.
NEW QUESTION # 231
The data engineering team is migrating an enterprise system with thousands of tables and views into the Lakehouse. They plan to implement the target architecture using a series of bronze, silver, and gold tables. Bronze tables will almost exclusively be used by production data engineering workloads, while silver tables will be used to support both data engineering and machine learning workloads. Gold tables will largely serve business intelligence and reporting purposes. While personal identifying information (PII) exists in all tiers of data, pseudonymization and anonymization rules are in place for all data at the silver and gold levels.
The organization is interested in reducing security concerns while maximizing the ability to collaborate across diverse teams.
Which statement exemplifies best practices for implementing this system?
Answer: D
Explanation:
This is the correct answer because it exemplifies best practices for implementing this system. By isolating tables in separate databases based on data quality tiers, such as bronze, silver, and gold, the data engineering team can achieve several benefits. First, they can easily manage permissions for different users and groups through database ACLs, which allow granting or revoking access to databases, tables, or views. Second, they can physically separate the default storage locations for managed tables in each database, which can improve performance and reduce costs. Third, they can provide a clear and consistent naming convention for the tables in each database, which can improve discoverability and usability.
NEW QUESTION # 232
A junior data engineer has configured a workload that posts the following JSON to the Databricks REST API endpoint 2.0/jobs/create.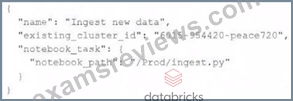
Assuming that all configurations and referenced resources are available, which statement describes the result of executing this workload three times?
Answer: E
Explanation:
Databricks jobs create will create a new job with the same name each time it is run.
In order to overwrite the extsting job you need to run databricks jobs reset
NEW QUESTION # 233
A data team's Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.
Original query: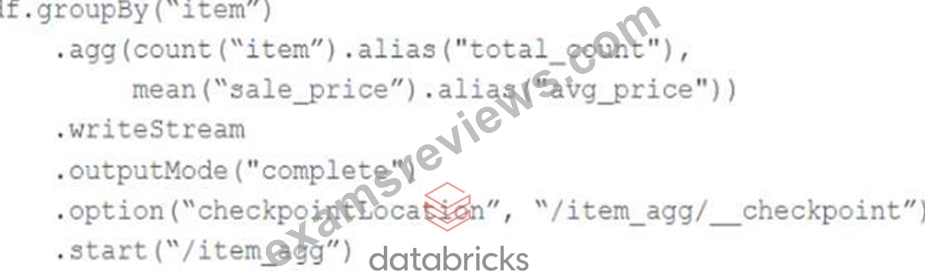
Proposed query: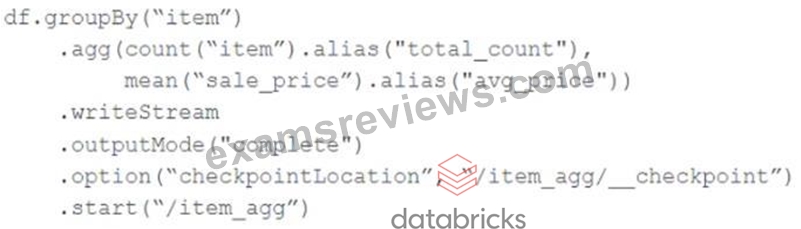
Which step must also be completed to put the proposed query into production?
Answer: D
Explanation:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
NEW QUESTION # 234
A data engineer has configured their Databricks Asset Bundle with multiple targets in databricks.yml and deployed it to the production workspace. Now, to validate the deployment, they need to invoke a job named my_project_job specifically within the prod target context.
Assuming the job is already deployed, they need to trigger its execution while ensuring the target- specific configuration is respected. Which command will trigger the job execution?
Answer: B
Explanation:
Databricks Asset Bundles (DABs) enable declarative configuration and deployment of Databricks resources such as jobs, pipelines, and dashboards across multiple environments.
Once deployed, jobs can be executed in a specific target context using the databricks bundle run command, which ensures all environment-specific configurations from the bundle definition (such as parameters, cluster settings, and workspace URLs) are respected.
The -t flag specifies the target environment (e.g., dev, staging, or prod). This ensures that the execution runs with the correct configuration defined under that target in databricks.yml.
Other options (A, B, and C) are invalid because they reference deprecated or incorrect command syntax that doesn't integrate with bundle targets. Therefore, D is the correct and verified answer.
NEW QUESTION # 235
......
What is your reason for wanting to be certified with Databricks-Certified-Data-Engineer-Professional? I believe you must want to get more opportunities. As long as you use Databricks-Certified-Data-Engineer-Professional learning materials and get a Databricks-Certified-Data-Engineer-Professional certificate, you will certainly be appreciated by the leaders. As you can imagine that you can get a promotion sooner or latter, not only on the salary but also on the position, so what are you waiting for? Just come and buy our Databricks-Certified-Data-Engineer-Professional study braindumps.
Databricks-Certified-Data-Engineer-Professional Latest Exam Discount: https://www.examsreviews.com/Databricks-Certified-Data-Engineer-Professional-pass4sure-exam-review.html