AI-500 practice materials stand the test of time and harsh market, convey their sense of proficiency with passing rate up to 98 to 100 percent. They are 100 percent guaranteed AI-500 practice materials. And our content of them are based on real exam by whittling down superfluous knowledge without delinquent mistakes. Our AI-500 practice materials comprise of a number of academic questions for your practice, which are interlinked and helpful for your exam. So their perfection is unquestionable.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Develop multi-agent solutions in Azure | 30-35% | - Design and implement agent memory, context management, and knowledge integration
|
| Topic 2: Secure, govern, and deploy multi-agent solutions | 20-25% | - Deploy multi-agent solutions to Azure
|
| Topic 3: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Evaluate solution quality
|
| Topic 4: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
>> Reliable AI-500 Test Book <<
It is worth mentioning that, the simulation test is available in our software version. With the simulation test, all of our customers will get accustomed to the AI-500 exam easily, and get rid of bad habits, which may influence your performance in the real AI-500 exam. In addition, the mode of AI-500 learning guide questions and answers is the most effective for you to remember the key points. During your practice process, the AI-500 Test Questions would be absorbed, which is time-saving and high-efficient. Considerate 24/7 service shows our attitudes, we always consider our candidates’ benefits and we guarantee that our AI-500 test questions are the most excellent path for you to pass the exam.
NEW QUESTION # 25
You have a Microsoft Foundry multi-agent customer support solution that retrieves grounding data from a shared vector index. The indexed corpus contains product runbooks in Markdown and support articles in HTML Both document types use a consistent hierarchical markup.
You discover that current fixed-size token chunking creates chunks that cross section boundaries.
You need to recommend a chunking approach for the ingestion pipeline. The solution must preserve existing document structure boundaries and minimize custom chunking code.
What should you recommend?
Answer: D
Explanation:
The corpus already contains reliable document hierarchy in Markdown and HTML, so the ingestion pipeline should preserve those author-defined boundaries rather than infer new ones from token counts or topic shifts.
Format-specific header splitters can divide Markdown by heading levels and HTML by structural headers, producing chunks that align with meaningful sections. This directly solves the current problem of fixed-size token chunks crossing section boundaries and requires less custom logic than building a semantic topic-shift chunker. Recursive character splitting can be configured with structure-aware separators, but it remains a more generic fallback when format-specific structure is already available. Microsoft Azure AI Search guidance recommends exploiting document structure such as headings when chunking. Therefore B is the most direct and maintainable approach. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Azure AI Search - structure-aware chunking and Markdown indexing
NEW QUESTION # 26
You have a Microsoft Foundry multi-agent assistant that uses a Retrieval-Augmented Generation (RAG)- enabled workflow. A retrieval agent returns document chunks to an answer agent, and the answer agent produces the final response.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in RAG evaluators that meet the following requirements:
* Identify final responses that include content that is NOT supported by the retrieved context.
* Assess whether the retrieved context chunks and final responses support the user query.
Which evaluator should you use for each requirement? To answer, drag the appropriate evaluators to the correct requirements. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.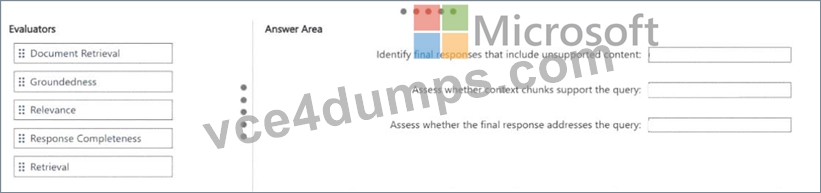
Answer:
Explanation: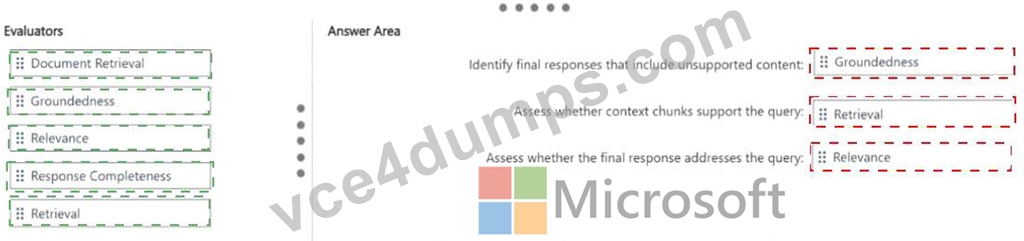
Explanation:
Unsupported final-response content: Groundedness; Context support for the query: Retrieval; Final- response support for the query: Relevance.
Groundedness detects whether the generated response contains claims that are not supported by the retrieved context, which directly matches the first requirement. Retrieval evaluates how relevant the provided context chunks are to the query when no document relevance ground truth is available. Relevance evaluates whether the final response directly and adequately answers the query. Microsoft Foundry separates these metrics so teams can diagnose whether a poor RAG result originated in retrieval or generation. Document Retrieval would require labeled retrieval ground truth, which the question explicitly says is absent. Response Completeness likewise depends on expected/ground-truth information. The supplied Groundedness, Retrieval, and Relevance mapping therefore matches the documented evaluator inputs and purposes. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
NEW QUESTION # 27
You have a Microsoft Foundry Agent Service solution that includes two agents You need to configure memory for the agents. The solution must meet the following requirements:
* Isolate the memory between end users
* Isolate the memory between the agent domains.
* Support the deletion of one user ' s memory without deleting other users ' memory.
Solution: You create one memory store per end user and configure both agents to use each user ' s memory store with a static scope value.
Does this meet the goal?
Answer: B
Explanation:
Creating one memory store for each end user separates users, but allowing both agents to use that user ' s store with the same static scope does not isolate the two agent domains. Memories produced by one agent can occupy the same logical collection as memories produced by the other agent. Microsoft Foundry Memory uses the `scope` parameter to partition a store, so a design that needs both user and domain isolation must preserve both dimensions, commonly through separate agent stores plus per-user scope. The per-user deletion requirement can also be handled more efficiently by deleting a user ' s scope rather than operating a separate store for every user. Because the proposed design fails agent-domain separation, it does not meet all requirements. Therefore B, No, is correct. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Create and use memory in Foundry Agent Service
NEW QUESTION # 28
You have a Microsoft Foundry resource that hosts Azure OpenAI model deployments for three projects. Each project is for a different business unit. The projects share the same Foundry resource.
You need to implement a Microsoft Cost Management view that separates the shared model spend by the project The solution must meet the following requirements:
* Use cost data that can be reconciled by using Azure Cost Management.
* Minimize manual tagging.
What should you use?
Answer: C
Explanation:
When multiple projects share one Foundry resource, grouping costs only by Azure resource cannot distinguish project consumption because the resource boundary is shared. Microsoft Foundry integrates with Azure Cost Management by attributing model usage to project metadata/tags, allowing a Cost Analysis view to filter shared resource spending by project. This supports showback or chargeback without requiring administrators to manually tag every usage event. Subscription-level service filters or meter grouping identify the service or billing meter but not which of the three business-unit projects generated the usage. Therefore a Foundry-resource-scoped Cost Analysis view filtered by the project tag is the configuration that both reconciles to Azure Cost Management and minimizes manual tagging. D remains correct. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - Manage costs
NEW QUESTION # 29
You need to implement an advanced prompt engineering strategy to resolve the Patient Intake agent issues.
The solution must prevent hardcoding new logic into the agent ' s core prompt.
What should you do?
Answer: D
Explanation:
The intake problem involves verbose, variable patient narratives and a requirement to avoid hardcoding new logic into the core prompt. Injecting dynamic context with curated few-shot examples gives the model representative demonstrations of how to identify clinically relevant symptoms while ignoring irrelevant narrative details. Microsoft AI-500 objectives explicitly include examples and dynamic context injection as advanced prompt-engineering techniques. Removing defensive guidance would weaken safety. Reducing the context window would not teach the model what information matters and could simply discard useful details.
Frequent full-model fine-tuning is operationally heavier and unnecessary for a behavior that can be demonstrated through curated examples. Dynamic few-shot context also allows the examples to be versioned and updated without rewriting the agent ' s base persona or application logic. Therefore C best addresses the extraction problem while preserving prompt lifecycle flexibility. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: AI-500 Study Guide - advanced prompt engineering
NEW QUESTION # 30
......
The cost of registering a AI-500 Certification is quite expensive, ranging between $100 and $1000. After paying such an amount, the candidate is sure to be on a tight budget. VCE4Dumps provides Microsoft AI-500 preparation material at very low prices compared to other platforms. We also assure you that the amount will not be wasted and you will not have to pay for the certification a second time. For added reassurance, we also provide up to 1 year of free updates. Free demo version of the actual product is also available so that you can verify its validity before purchasing.
AI-500 Test Simulator Online: https://www.vce4dumps.com/AI-500-valid-torrent.html