2026 Latest Dumpexams SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1C1XFCz6vwRCJbdHeWTCVR97kouKsg0ok
Many people may worry that the SPS-C01 guide torrent is not enough for them to practice and the update is slowly. We guarantee you that our experts check whether the SPS-C01 study materials is updated or not every day and if there is the update the system will send the update to the client automatically. So you have no the necessity to worry that you don’t have latest SPS-C01 Exam Torrent to practice. Before you buy our product, please understand the characteristics and the advantages of our Snowflake Certified SnowPro Specialty - Snowpark guide torrent in detail as follow.
| Section | Weight | Objectives |
|---|---|---|
| Performance and Best Practices | 10% | - Security and governance
|
| Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
|
| Snowpark API and Development | 30% | - Multi-language support
|
| Data Transformations and Operations | 35% | - DataFrame manipulation
|
By imparting the knowledge of the SPS-C01 exam to those ardent exam candidates who are eager to succeed like you, they treat it as responsibility to offer help. So please prepare to get striking progress if you can get our SPS-C01 Study Guide with following steps for your information. With our SPS-C01 learning materials for 20 to 30 hours, we can claim that you will be confident to go to write your SPS-C01 exam and pass it.
NEW QUESTION # 168
You have a Snowpark DataFrame 'employees' with columns 'employee_id' (INT), 'name' (STRING), 'department' (STRING), and 'salary' (DOUBLE). You want to create a new DataFrame that contains the top 3 highest-paid employees within each department. Which of the following approaches is the MOST efficient and correct way to achieve this using Snowpark Python?





Answer: A,D,E
Explanation:
The most efficient and correct approaches are A, C, and D. These options utilize window functions in Snowpark to efficiently rank employees within each department. Option A uses , which assigns a unique rank to each row within a partition, even if there are ties in salary. Option C uses 'rank()' , which assigns the same rank to rows with equal salary values, resulting in possible gaps in the ranking sequence. Option D uses , which assigns consecutive ranks without gaps, even if there are ties in salary. The most appropriate ranking function will depend on the specific ranking requirement but all three would provide top 3 employees. Option B is incorrect because Snowpark 'apply' does not support groupby operations effectively, resulting in an error. Finally E will only return 2 employees, which would make it incorrect.
NEW QUESTION # 169
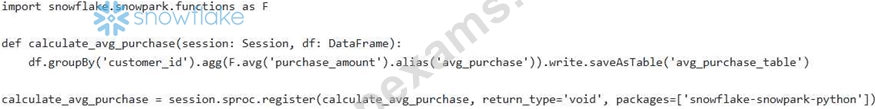
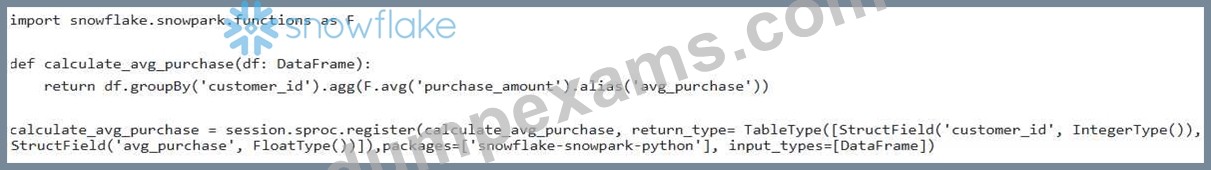
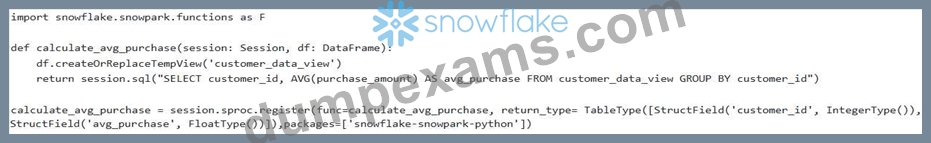
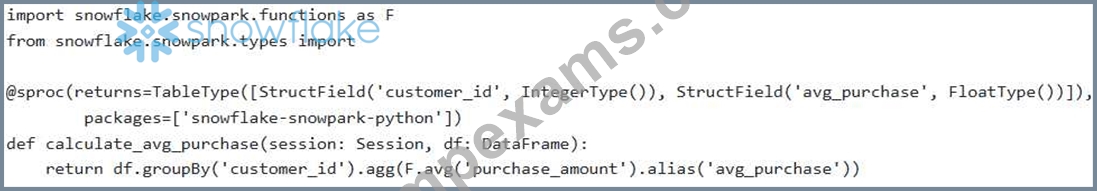
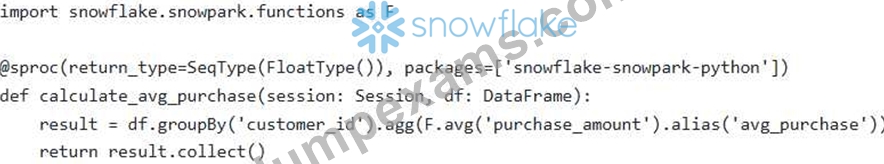
You have a Snowpark DataFrame named and want to create a stored procedure that calculates the average purchase amount for each customer. The stored procedure should accept the DataFrame as input, perform the aggregation, and return a new DataFrame with the results. Which of the following code snippets BEST demonstrates how to correctly define and deploy this stored procedure?
Answer: B
Explanation:
Option E is the most correct. It correctly registers the stored procedure using 'session.sproc.register' with the correct return type annotation for a DataFrame (using TableType and StructFields) and explicitly declares the input type to be DataFrame using 'input_types' parameter in registration. Option A uses the '@sproc' decorator which is the older API (still valid, but less explicit). Option B uses session.sql which is not appropriate for creating DataFrame based stored procedures. Option C is not correct because the return type SeqType(FloatType()) expects a sequence of float types instead of a DataFrame structure. Option D writes the result to a table, which is not the defined requirement to return a DataFrame.
NEW QUESTION # 170
You are developing a Snowpark application to process large datasets stored in Snowflake. You need to create a session using the 'snowflake.connector.connect' method. Which of the following code snippets correctly establishes a session with Snowflake, leveraging an external browser authentication mechanism, ensuring secure and reliable access to your data while minimizing exposed credentials in the code?





Answer: B
Explanation:
The correct answer is B. When using 'externalbrowser' authentication, providing the username and password in the connection string is not required, as the authentication is handled through the browser. Options A and C are incorrect because including a password with 'externalbrowser' is unnecessary and 'snowflake' is for Snowflake username/password authentication, respectively. Option D is incomplete because it doesn't specify an authenticator. Option E is missing the warehouse, database and schema, required for a functioning Snowpark session in most scenarios.
NEW QUESTION # 171
You are developing a secure UDF in Snowpark Python that needs to access sensitive data stored in an internal stage. The UDF should be accessible to users without granting them direct access to the stage. Which of the following security measures and code snippets are required to achieve this, assuming the stage is already created?
Answer: E
Explanation:
Secure UDFs are designed to execute with the privileges of the UDF owner, not the caller. allows secure access to stage credentials. Option B is incorrect because granting USAGE on the stage directly grants access to the data in the stage. Option C is a valid approach but unnecessary complex. Option D concerns external functions, not secure UDFs within Snowflake. Option E is incorrect because 'VOLATILE doesn't affect privilege handling.
NEW QUESTION # 172
You are working with a Snowpark DataFrame containing employee data, including columns 'employee_id', 'first_name', 'last_name', 'salary', and 'department'. You need to perform the following transformations: 1. Concatenate 'first_name' and into a new column called separating them with a space. 2. Increase each employee's salary by a percentage based on their 'department'. Department 'Sales' gets a 10% raise, 'Marketing' gets a 15% raise, and all other departments get a 5% raise. 3. Create a new column reflecting this raise. Which of the following Snowpark code snippets achieves these transformations correctly and efficiently? (Select all that apply)





Answer: B,D
Explanation:
Options A and C are correct. Option A uses 'concat for string concatenation and 'when' for conditional salary calculation, which is a standard and efficient approach in Snowpark. Option C uses a Snowflake expression to achieve the same conditional salary calculation, which can be more concise for complex conditions and may leverage Snowflake's optimization. Option B is incorrect, because the '+' string concatenation will not work; string concatenation in Snowpark should happen using the 'concat' function. Option D is less efficient because it uses a Python UDF, which involves serialization/deserialization overhead. Option E will not work because of syntax 'select(' 'Y does not exist, therefore the user will need to specify all the columns. Also, there is a column called ' ' which will break the processing.
NEW QUESTION # 173
......
Dumpexams is one of the leading platforms that has been helping Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam candidates for many years. Over this long time period we have helped SPS-C01 exam candidates in their preparation. They got help from Dumpexams Snowflake Certified SnowPro Specialty - Snowpark practice questions and easily got success in the final SPS-C01 Certification Exam. You can also trust Dumpexams SPS-C01 exam dumps and start preparation with complete peace of mind and satisfaction.
Dumps SPS-C01 Download: https://www.dumpexams.com/SPS-C01-real-answers.html
P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by Dumpexams: https://drive.google.com/open?id=1C1XFCz6vwRCJbdHeWTCVR97kouKsg0ok