Successful with Verified and Valid Databricks Certified-Data-Engineer-Professional Exam Questions [2026]

GuideTorrent is a trusted platform that is committed to helping Databricks Certified-Data-Engineer-Professional exam candidates in exam preparation. The Databricks Certified-Data-Engineer-Professional exam questions are real and updated and will repeat in the upcoming Databricks Certified-Data-Engineer-Professional Exam. By practicing again and again you will become an expert to solve all the Certified-Data-Engineer-Professional exam questions completely and before the exam time.
| Section | Objectives |
|---|
| Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Design dimensional models for analytical workloads with efficient querying and aggregation
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 2. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 3. Apply Change Data Feed to address streaming table limitations and improve latency
- 4. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 5. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
|
| Data Sharing and Federation | - Share and federate data
- 1. Configure Lakehouse Federation with appropriate governance across supported source systems
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
| Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use row filters and column masks to protect sensitive table data
- Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
|
| Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Query Profile and Spark UI to monitor workloads
|
| Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 2. Create pipeline components using control flow operators such as if/else and foreach
- 3. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 4. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 5. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 6. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 7. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 8. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
>> Clear Certified-Data-Engineer-Professional Exam <<
Databricks Certified-Data-Engineer-Professional Questions - Latest Preparation Material [2026]
After successful competition of the Databricks Certified-Data-Engineer-Professional certification, the certified candidates can put their career on the right track and achieve their professional career objectives in a short time period. For the recognition of skills and knowledge, more career opportunities, professional development, and higher salary potential, the Databricks Certified-Data-Engineer-Professional Certification Exam is the proven way to achieve these tasks quickly.
Databricks Certified Data Engineer Professional Sample Questions (Q217-Q222):
NEW QUESTION # 217
The data engineering team maintains a table of aggregate statistics through batch nightly updates. This includes total sales for the previous day alongside totals and averages for a variety of time periods including the 7 previous days, year-to-date, and quarter-to-date. This table is named store_saies_summary and the schema is as follows:

The table daily_store_sales contains all the information needed to update store_sales_summary.
The schema for this table is:
store_id INT, sales_date DATE, total_sales FLOAT
If daily_store_sales is implemented as a Type 1 table and the total_sales column might be adjusted after manual data auditing, which approach is the safest to generate accurate reports in the store_sales_summary table?
- A. Use Structured Streaming to subscribe to the change data feed for daily_store_sales and apply changes to the aggregates in the store_sales_summary table with each update.
- B. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and append new rows nightly to the store_sales_summary table.
- C. Implement the appropriate aggregate logic as a Structured Streaming read against the daily_store_sales table and use upsert logic to update results in the store_sales_summary table.
- D. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and use upsert logic to update results in the store_sales_summary table.
- E. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and overwrite the store_sales_summary table with each Update.
Answer: E
NEW QUESTION # 218
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed:
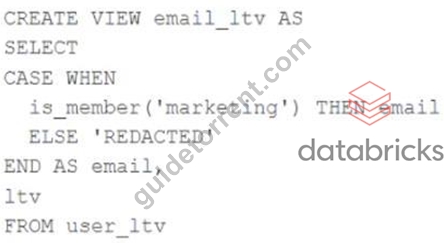
An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
- A. The email and ltv columns will be returned with the values in user itv.
- B. Three columns will be returned, but one column will be named "redacted" and contain only null values.
- C. Only the email and ltv columns will be returned; the email column will contain the string
"REDACTED" in each row. - D. Only the email and itv columns will be returned; the email column will contain all null values.
- E. The email, age. and ltv columns will be returned with the values in user ltv.
Answer: C
Explanation:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row.
NEW QUESTION # 219
A view is registered with the following code:
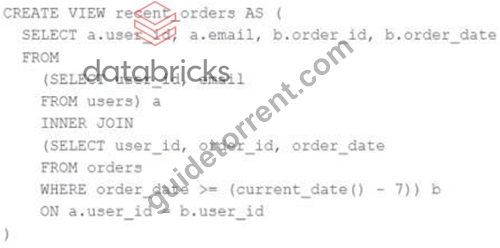
Both users and orders are Delta Lake tables.
Which statement describes the results of querying recent_orders?
- A. The versions of each source table will be stored in the table transaction log; query results will be saved to DBFS with each query.
- B. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query began.
- C. All logic will execute when the table is defined and store the result of joining tables to the DBFS; this stored data will be returned when the table is queried.
- D. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query finishes.
Answer: B
NEW QUESTION # 220
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in the geo_lookup table.
Before executing the code, running SHOW TABLES on the current database indicates the database contains only two tables: geo_lookup and sales.
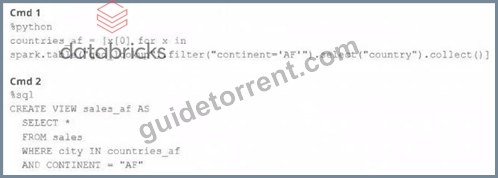
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
- A. Both commands will succeed. Executing show tables will show that countries at and sales at have been registered as views.
- B. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable representing a PySpark DataFrame.
- C. Cmd 1 will succeed. Cmd 2 will search all accessible databases for a table or view named countries af: if this entity exists, Cmd 2 will succeed.
- D. Both commands will fail. No new variables, tables, or views will be created.
- E. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable containing a list of strings.
Answer: E
Explanation:
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view.
Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variable as a parameter.
NEW QUESTION # 221
A data engineer is working in an interactive notebook with many transformations before outputting the result from display(df.collect() ). The notebook includes wide transformations and a cross join.
The data engineer is getting the following error: "The spark driver has stopped unexpectedly and is restarting. Your notebook will be automatically reattached." Which action should the data engineer take?
- A. Run the notebook on a single node cluster to keep driver from falling.
- B. Check into the Spark UI to see how many jobs are assigned to each stage as they are employing fewer executors.
- C. Look at the compute metrics UI to see if the executors have higher than 90% memory utilization.
- D. Rewrite their code to avoid putting memory pressure on the driver node.
Answer: D
Explanation:
Calling df.collect() on a large DataFrame forces all data to be loaded into the driver's memory.
With wide transformations and a cross join, this can easily exceed the driver's capacity, causing it to crash. The data engineer should rewrite the code to avoid collecting large datasets on the driver, using operations like display(df) or writing to storage instead.
NEW QUESTION # 222
......
Our Certified-Data-Engineer-Professional study materials boost high passing rate ss more than 98% and hit rate so that you needn't worry that you can't pass the test too much. We provide free tryout before the purchase to let you decide whether it is valuable or not by yourself. To further understand the merits and features of our Certified-Data-Engineer-Professional Practice Engine you could free download the free demo of our Certified-Data-Engineer-Professional exam questions, or visit our web page to know more related information. And you can pass your Certified-Data-Engineer-Professional exam with the least time and energy with our wonderful Certified-Data-Engineer-Professional exam questions.
Certified-Data-Engineer-Professional Valid Dumps Pdf: https://www.guidetorrent.com/Certified-Data-Engineer-Professional-pdf-free-download.html
- Latest Certified-Data-Engineer-Professional Exam Test 🐙 New Certified-Data-Engineer-Professional Test Review 🥥 Reliable Certified-Data-Engineer-Professional Dumps Sheet 🛩 Immediately open ✔ www.exam4labs.com ️✔️ and search for 【 Certified-Data-Engineer-Professional 】 to obtain a free download 🥟Instant Certified-Data-Engineer-Professional Access
- Newest Clear Certified-Data-Engineer-Professional Exam Help You to Get Acquainted with Real Certified-Data-Engineer-Professional Exam Simulation 😙 Search for 「 Certified-Data-Engineer-Professional 」 on [ www.pdfvce.com ] immediately to obtain a free download 🦇Certified-Data-Engineer-Professional PDF
- Valid Certified-Data-Engineer-Professional Exam Fee 🩸 Certified-Data-Engineer-Professional Latest Study Notes 👽 Latest Certified-Data-Engineer-Professional Exam Test 🌂 Enter ( www.vce4dumps.com ) and search for ➥ Certified-Data-Engineer-Professional 🡄 to download for free 🟨Dumps Certified-Data-Engineer-Professional Vce
- New Certified-Data-Engineer-Professional Dumps Free 🥑 Reliable Certified-Data-Engineer-Professional Test Testking 🧳 Examinations Certified-Data-Engineer-Professional Actual Questions 🚀 Go to website 「 www.pdfvce.com 」 open and search for 「 Certified-Data-Engineer-Professional 」 to download for free 😲Latest Certified-Data-Engineer-Professional Guide Files
- 2026 Clear Certified-Data-Engineer-Professional Exam 100% Pass | High Pass-Rate Certified-Data-Engineer-Professional Valid Dumps Pdf: Databricks Certified Data Engineer Professional 🌐 Search for ⏩ Certified-Data-Engineer-Professional ⏪ and easily obtain a free download on ➥ www.testkingpass.com 🡄 🎀Reliable Certified-Data-Engineer-Professional Dumps Sheet
- New Certified-Data-Engineer-Professional Test Review 😙 Reliable Certified-Data-Engineer-Professional Dumps Sheet ✡ Instant Certified-Data-Engineer-Professional Access ⏮ Copy URL ⮆ www.pdfvce.com ⮄ open and search for ➥ Certified-Data-Engineer-Professional 🡄 to download for free 🏜Certified-Data-Engineer-Professional Reliable Test Bootcamp
- Key Certified-Data-Engineer-Professional Concepts 🕓 Certified-Data-Engineer-Professional Latest Study Notes ⚔ Key Certified-Data-Engineer-Professional Concepts 🌙 The page for free download of ☀ Certified-Data-Engineer-Professional ️☀️ on ▶ www.dumpsmaterials.com ◀ will open immediately 😙Certified-Data-Engineer-Professional Free Study Material
- 100% Pass Databricks - Certified-Data-Engineer-Professional Updated Clear Exam 🤷 Search for 【 Certified-Data-Engineer-Professional 】 and download it for free on 【 www.pdfvce.com 】 website 💸Latest Certified-Data-Engineer-Professional Exam Test
- Examinations Certified-Data-Engineer-Professional Actual Questions 🙈 New Certified-Data-Engineer-Professional Test Prep 🗺 Certified-Data-Engineer-Professional New Exam Braindumps 😣 Search for ➥ Certified-Data-Engineer-Professional 🡄 on 【 www.easy4engine.com 】 immediately to obtain a free download 👰Valid Certified-Data-Engineer-Professional Exam Fee
- Download Real Databricks Certified-Data-Engineer-Professional Practice Test Questions And Start Preparation 💽 Go to website “ www.pdfvce.com ” open and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download for free ⛑Reliable Certified-Data-Engineer-Professional Dumps Sheet
- New Certified-Data-Engineer-Professional Test Prep 📁 New Certified-Data-Engineer-Professional Test Review 🥟 Key Certified-Data-Engineer-Professional Concepts 🦖 ▷ www.prepawayete.com ◁ is best website to obtain 【 Certified-Data-Engineer-Professional 】 for free download 🆗Examinations Certified-Data-Engineer-Professional Actual Questions
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, users.playground.ru, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, learn.csisafety.com.au, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, notefolio.net, Disposable vapes