P.S. Kostenlose 2026 Google Professional-Machine-Learning-Engineer Prüfungsfragen sind auf Google Drive freigegeben von DeutschPrüfung verfügbar: https://drive.google.com/open?id=1cUO_uk7QeIDsCRDX6uZKr8RjnbWLEngJ
DeutschPrüfung ist eine Website, die alle Informationen zur verschiedenen Google -Zertifizierungsprüfungen bieten kann. DeutschPrüfung kann die besten und neuesten Prüfungsressourcen für Sie bereitstellen. Wenn Sie DeutschPrüfung wählen, können Sie sich unbesorgt auf Ihre Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung vorbereiten. Unsere Prüfungsunterlagen garantieren Ihnen, dass Sie 100% die Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung bestehen können. Wenn nicht, geben wir Ihnen eine volle Rückerstattung oder akutualisieren schnell die Google Professional-Machine-Learning-Engineer Prüfungsfragen- und antworten. DeutschPrüfung kann Ihnen Hilfe bei der Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung sowie bei Ihrer zukünftigen Arbeit bieten. Zwar gibt es viele Möglichkeiten, die Ihnen zu Ihrem Ziel verhelfen, aber es ist die klügste Wahl, wenn Sie DeutschPrüfung wählen. Mit DeutschPrüfung können Sie mit wenigem Geld die Prüfung sicherer bestehen. Außerdem bieten wir Ihnen einjährigen kostenlosen Update-Service.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Scale prototypes into AI models | 18% | - Design and run experiments - Select appropriate model architectures and frameworks - Work with foundation models and generative AI techniques - Optimize model performance and generalization |
| Topic 2: Train and deploy models | 20% | - Configure training jobs and environments - Implement generative AI deployment patterns - Use Vertex AI deployment features and infrastructure - Deploy models for online, batch, and streaming prediction |
| Topic 3: Architect low-code AI solutions | 12% | - Apply responsible AI principles to low-code designs - Design solutions using Vertex AI Studio, Model Garden, and Agent Builder - Identify use cases for low-code/no-code AI tools |
| Topic 4: Collaborate to manage data and models | 16% | - Organize and prepare enterprise data
- Address data privacy, compliance, and governance |
| Topic 5: Automate and orchestrate ML pipelines | 18% | - Implement CI/CD for ML systems - Design end-to-end ML workflows - Use Vertex AI Pipelines, TFX, and other orchestration tools - Automate retraining and model updates |
| Topic 6: Monitor and optimize AI solutions | 16% | - Troubleshoot and maintain production systems - Optimize cost, latency, and resource usage - Monitor data quality and pipeline health - Monitor model performance, fairness, and drift |
>> Professional-Machine-Learning-Engineer Fragen&Antworten <<
Die Prüfungsfragen und Antworten zur Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung von DeutschPrüfung wird von unserem Expertenteam nach ihren umfangreichen Kenntnissen und Erfahrungen berarbeitet. Sie können die Bedürfnisse der Kandidaten abdecken. Sie finden vielleicht in anderen Büchern oder auf anderen Websites auch die Google Professional-Machine-Learning-Engineer Schulungsunterlagen. Aber die Schulungsunterlagen von DeutschPrüfung sind die umfassendste unter ihnen und zugleich kann Ihnen die beste Garantie geben. Bitte wählen Sie die Google Professional-Machine-Learning-Engineer Prüfungsfragen und Antworten von DeutschPrüfung.
236. Frage
You are developing an image recognition model using PyTorch based on ResNet50 architecture.
Your code is working fine on your local laptop on a small subsample. Your full dataset has 200k labeled images. You want to quickly scale your training workload while minimizing cost. You plan to use 4 V100 GPUs. What should you do?
Antwort: A
237. Frage
A company wants to classify user behavior as either fraudulent or normal. Based on internal research, a Machine Learning Specialist would like to build a binary classifier based on two features: age of account and transaction month. The class distribution for these features is illustrated in the figure provided.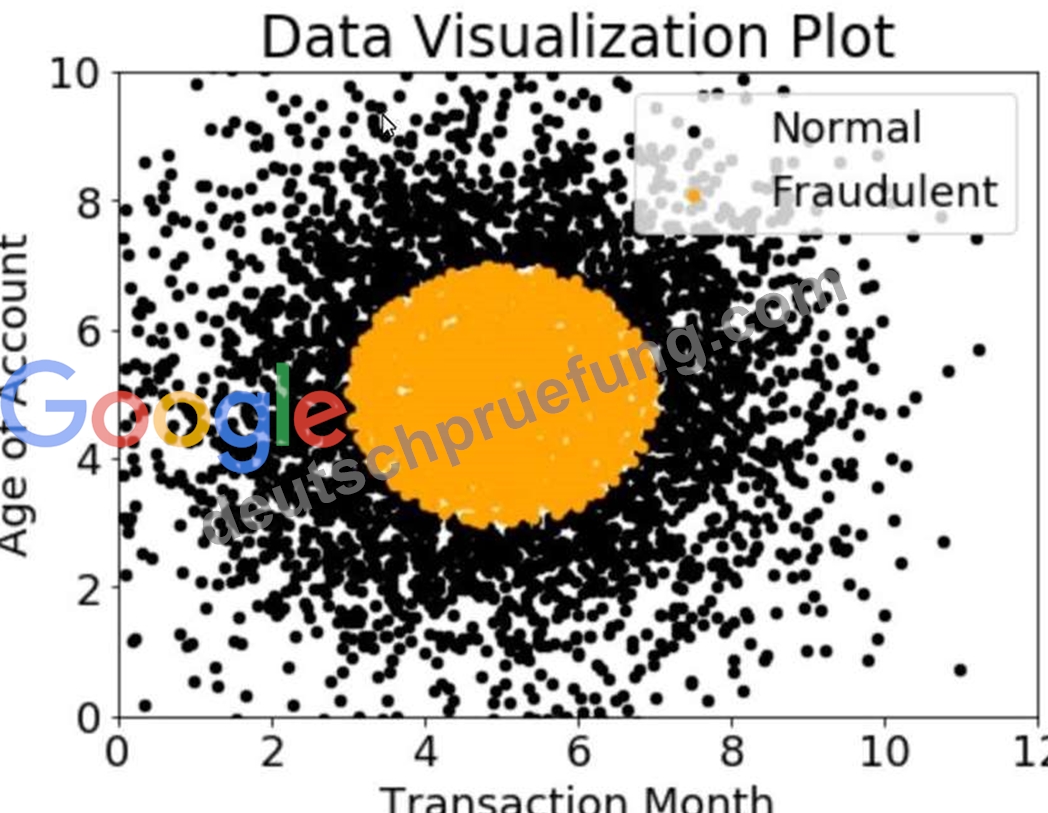
Based on this information, which model would have the HIGHEST accuracy?
Antwort: C
238. Frage
You work for a company that manages a ticketing platform for a large chain of cinemas. Customers use a mobile app to search for movies they're interested in and purchase tickets in the app. Ticket purchase requests are sent to Pub/Sub and are processed with a Dataflow streaming pipeline configured to conduct the following steps:
1. Check for availability of the movie tickets at the selected cinema.
2. Assign the ticket price and accept payment.
3. Reserve the tickets at the selected cinema.
4. Send successful purchases to your database.
Each step in this process has low latency requirements (less than 50 milliseconds). You have developed a logistic regression model with BigQuery ML that predicts whether offering a promo code for free popcorn increases the chance of a ticket purchase, and this prediction should be added to the ticket purchase process.
You want to identify the simplest way to deploy this model to production while adding minimal latency. What should you do?
Antwort: A
Begründung:
The simplest way to deploy a logistic regression model with BigQuery ML to production while adding minimal latency is to export the model in TensorFlow format, and add a tfx_bsl.public.beam.RunInference step to the Dataflow pipeline. This option has the following advantages:
* It allows the model prediction to be performed in real time, as part of the Dataflow streaming pipeline that processes the ticket purchase requests. This ensures that the promo code offer is based on the most recent data and customer behavior, and that the offer is delivered to the customer without delay.
* It leverages the compatibility and performance of TensorFlow and Dataflow, which are both part of the Google Cloud ecosystem. TensorFlow is a popular and powerful framework for building and deploying machine learning models, and Dataflow is a fully managed service that runs Apache Beam pipelines for data processing and transformation. By using the tfx_bsl.public.beam.RunInference step, you can easily integrate your TensorFlow model with your Dataflow pipeline, and take advantage of the parallelism and scalability of Dataflow.
* It simplifies the model deployment and management, as the model is packaged with the Dataflow pipeline and does not require a separate service or endpoint. The model can be updated by redeploying the Dataflow pipeline with a new model version.
The other options are less optimal for the following reasons:
* Option A: Running batch inference with BigQuery ML every five minutes on each new set of tickets issued introduces additional latency and complexity. This option requires running a separate BigQuery job every five minutes, which can incur network overhead and latency. Moreover, this option requires storing and retrieving the intermediate results of the batch inference, which can consume storage space and increase the data transfer time.
* Option C: Exporting the model in TensorFlow format, deploying it on Vertex AI, and querying the prediction endpoint from the streaming pipeline introduces additional latency and cost. This option requires creating and managing a Vertex AI endpoint, which is a managed service that provides various tools and features for machine learning, such as training, tuning, serving, and monitoring. However, querying the Vertex AI endpoint from the streaming pipeline requires making an HTTP request, which can incur network overhead and latency. Moreover, this option requires paying for the Vertex AI endpoint usage, which can increase the cost of the model deployment.
* Option D: Converting the model with TensorFlow Lite (TFLite), and adding it to the mobile app so that the promo code and the incoming request arrive together in Pub/Sub introduces additional challenges and risks. This option requires converting the model to a TFLite format, which is a lightweight and optimized format for running TensorFlow models on mobile and embedded devices. However, converting the model to TFLite may not preserve the accuracy or functionality of the original model, as some operations or features may not be supported by TFLite. Moreover, this option requires updating the mobile app with the TFLite model, which can be tedious and time-consuming, and may depend on the user's willingness to update the app. Additionally, this option may expose the model to potential security or privacy issues, as the model is running on the user's device and may be accessed or modified by malicious actors.
:
[Exporting models for prediction | BigQuery ML]
[tfx_bsl.public.beam.run_inference | TensorFlow Extended]
[Vertex AI documentation]
[TensorFlow Lite documentation]
239. Frage
You are responsible for building a unified analytics environment across a variety of on-premises data marts. Your company is experiencing data quality and security challenges when integrating data across the servers, caused by the use of a wide range of disconnected tools and temporary solutions. You need a fully managed, cloud-native data integration service that will lower the total cost of work and reduce repetitive work. Some members on your team prefer a codeless interface for building Extract, Transform, Load (ETL) process. Which service should you use?
Antwort: B
Begründung:
Cloud Data Fusion is a fully managed, cloud-native data integration service provided by Google Cloud Platform. It is designed to simplify the process of building and managing ETL pipelines across a variety of data sources and targets.
https://cloud.google.com/data-fusion
240. Frage
You work for a social media company. You need to detect whether posted images contain cars. Each training example is a member of exactly one class. You have trained an object detection neural network and deployed the model version to Al Platform Prediction for evaluation. Before deployment, you created an evaluation job and attached it to the Al Platform Prediction model version. You notice that the precision is lower than your business requirements allow. How should you adjust the model's final layer softmax threshold to increase precision?
Antwort: D
Begründung:
Precision and recall are two common metrics for evaluating the performance of a classification model. Precision measures the proportion of positive predictions that are correct, while recall measures the proportion of positive examples that are correctly predicted. Precision and recall are inversely related, meaning that increasing one will decrease the other, and vice versa. The trade-off between precision and recall depends on the goal and the cost of the classification problem1.
For the use case of detecting whether posted images contain cars, precision is more important than recall, as the social media company wants to minimize the number of false positives, or images that are incorrectly labeled as containing cars. A high precision means that the model is confident and accurate in its positive predictions, while a low recall means that the model may miss some positive examples, or images that actually contain cars. The cost of missing some positive examples is lower than the cost of making wrong positive predictions, as the latter may affect the user experience and the reputation of the social media company.
The softmax function is a function that transforms a vector of real numbers into a probability distribution over the possible classes. The softmax function is often used as the final layer of a neural network for multi-class classification problems, as it assigns a probability to each class, and the class with the highest probability is chosen as the prediction. The softmax function is defined as:
softmax (x_i) exp (x_i) / sum_j exp (x_j)
where x_i is the input value for class i, and softmax (x_i) is the output probability for class i.
The softmax threshold is a parameter that determines the minimum probability that a class must have to be chosen as the prediction. For example, if the softmax threshold is 0.5, then the class with the highest probability must have at least 0.5 to be selected, otherwise the prediction is none. The softmax threshold can be used to adjust the trade-off between precision and recall, as a higher threshold will increase the precision and decrease the recall, while a lower threshold will decrease the precision and increase the recall2.
For the use case of detecting whether posted images contain cars, the best way to adjust the model's final layer softmax threshold to increase precision is to decrease the recall. This means that the softmax threshold should be increased, so that the model will only make positive predictions when it is highly confident, and avoid making false positives. By increasing the softmax threshold, the model will become more selective and accurate in its positive predictions, and improve the precision metric. Therefore, decreasing the recall is the best option for this use case.
Reference:
Precision and recall - Wikipedia
How to add a threshold in softmax scores - Stack Overflow
241. Frage
......
Allein die Versprechung ist nicht genug. Deswegen bieten wir DeutschPrüfung den Kunden die allseitige und anspruchsvolle Service. Von der kostenfreien Probe vor dem Kauf der Google Professional-Machine-Learning-Engineer Prüfungsunterlagen, bis zur einjährigen kostenfreien Aktualisierungsdienst nach dem Kauf. Wir werden Ihnen die vertrauenswürdige Hilfe für jede Vorbereitungsstufe der Google Professional-Machine-Learning-Engineer Prüfung bieten. Falls Sie die Google Professional-Machine-Learning-Engineer Prüfung nicht wunschgemäß bestehen, geben wir Ihnen volle Rückerstattung zurück, um Ihren finanziellen Verlust zu kompensieren.
Professional-Machine-Learning-Engineer Deutsch Prüfungsfragen: https://www.deutschpruefung.com/Professional-Machine-Learning-Engineer-deutsch-pruefungsfragen.html
P.S. Kostenlose 2026 Google Professional-Machine-Learning-Engineer Prüfungsfragen sind auf Google Drive freigegeben von DeutschPrüfung verfügbar: https://drive.google.com/open?id=1cUO_uk7QeIDsCRDX6uZKr8RjnbWLEngJ