P.S. Free & New MLA-C01 dumps are available on Google Drive shared by TrainingDump: https://drive.google.com/open?id=1fZObwH-Y1WoPib7xSNWxhiubUDAHHoiJ
Our MLA-C01 study guide provides free trial services, so that you can learn about some of our topics and how to open the software before purchasing. During the trial period of our MLA-C01 study materials, the PDF versions of the sample questions are available for free download, and both the pc version and the online version can be illustrated clearly. You can contact us at any time if you have any difficulties on our MLA-C01 Exam Questions in the purchase or trial process. We will provide professional personnel to help you remotely on the MLA-C01 training guide.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
We have always taken care to provide the best Amazon MLA-C01 exam dumps to our customers. That's why we offer many other benefits with our product. We provide a demo version of the real product to our customers to clear their doubts about the truthfulness and accuracy of AWS Certified Machine Learning Engineer - Associate (MLA-C01) preparation material. You can try the product before you buy it.
NEW QUESTION # 43
A company regularly receives new training data from a vendor of an ML model. The vendor delivers cleaned and prepared data to the company's Amazon S3 bucket every 3-4 days.
The company has an Amazon SageMaker AI pipeline to retrain the model. An ML engineer needs to run the pipeline automatically when new data is uploaded to the S3 bucket.
Which solution will meet these requirements with the LEAST operational effort?
Answer: B
Explanation:
AWS best practices recommend event-driven architectures to automate ML workflows with minimal operational overhead. Amazon EventBridge natively integrates with Amazon S3 and Amazon SageMaker Pipelines, making it the most efficient solution for triggering retraining when new data arrives.
Amazon S3 automatically emits object creation events. By creating an EventBridge rule that listens for these events and targets a SageMaker Pipeline execution, the pipeline can start immediately when new training data is uploaded. This solution requires no custom code, no polling, and no infrastructure management.
Option A is incorrect because S3 lifecycle rules manage storage transitions, not workflow execution. Option B introduces custom code and periodic scanning, which increases operational complexity and cost. Option D (MWAA) is powerful but requires maintaining an Airflow environment and is unnecessary for a simple event- based trigger.
AWS documentation explicitly highlights EventBridge + SageMaker Pipelines as the recommended pattern for automated retraining workflows triggered by data arrival.
Therefore, Option C is the correct and AWS-verified answer.
NEW QUESTION # 44
An ML engineer is building a generative AI application on Amazon Bedrock by using large language models (LLMs).
Select the correct generative AI term from the following list for each description. Each term should be selected one time or not at all. (Select three.)
* Embedding
* Retrieval Augmented Generation (RAG)
* Temperature
* Token
Answer:
Explanation:
Explanation: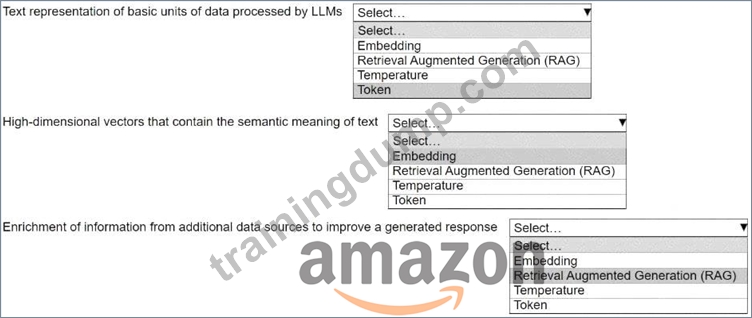
* Text representation of basic units of data processed by LLMs:Token
* High-dimensional vectors that contain the semantic meaning of text:Embedding
* Enrichment of information from additional data sources to improve a generated response:
Retrieval Augmented Generation (RAG)
Comprehensive Detailed Explanation
* Token:
* Description: A token represents the smallest unit of text (e.g., a word or part of a word) that an LLM processes. For example, "running" might be split into two tokens: "run" and "ing."
* Why?Tokens are the fundamental building blocks for LLM input and output processing, ensuring that the model can understand and generate text efficiently.
* Embedding:
* Description: High-dimensional vectors that encode the semantic meaning of text. These vectors are representations of words, sentences, or even paragraphs in a way that reflects their relationships and meaning.
* Why?Embeddings are essential for enabling similarity search, clustering, or any task requiring semantic understanding. They allow the model to "understand" text contextually.
* Retrieval Augmented Generation (RAG):
* Description: A technique where information is enriched or retrieved from external data sources (e.g., knowledge bases or document stores) to improve the accuracy and relevance of a model's generated responses.
* Why?RAG enhances the generative capabilities of LLMs by grounding their responses in factual and up-to-date information, reducing hallucinations in generated text.
By matching these terms to their respective descriptions, the ML engineer can effectively leverage these concepts to build robust and contextually aware generative AI applications on Amazon Bedrock.
NEW QUESTION # 45
An ML model is deployed in production. The model has performed well and has met its metric thresholds for months.
An ML engineer who is monitoring the model observes a sudden degradation. The performance metrics of the model are now below the thresholds.
What could be the cause of the performance degradation?
Answer: B
Explanation:
A sudden drop in model performance after a long period of stability is a classic indicator of data drift.
According to AWS ML documentation, production data distribution drift occurs when the statistical properties of incoming data change over time compared to the training dataset.
This drift can be caused by changes in user behavior, market conditions, seasonal trends, or upstream data pipelines. When drift occurs, the model's learned patterns no longer align with real-world data, leading to degraded accuracy and other performance metrics.
Lack of training data (Option A) and overfitting (Option D) are issues that typically manifest during initial training, not after months of stable production performance. Compute constraints (Option C) may affect latency but do not usually cause sustained accuracy degradation.
AWS recommends using SageMaker Model Monitor to detect such drift and trigger retraining workflows.
Therefore, drift in the production data distribution is the most likely cause of the observed performance degradation.
NEW QUESTION # 46
A company needs to perform feature engineering, aggregation, and data preparation. After the features are produced, the company must implement a solution on AWS to process and store the features. Which solution will meet these requirements?
Answer: C
Explanation:
Amazon SageMaker Feature Processing (via processing jobs) is used to perform feature engineering and data preparation. The engineered features can then be ingested into SageMaker Feature Store, which is a purpose-built service to manage and store ML features for reuse across training and inference. This combination directly addresses the company's requirements.
NEW QUESTION # 47
An ML engineer needs to use Amazon SageMaker Feature Store to create and manage features to train a model.
Select and order the steps from the following list to create and use the features in Feature Store. Each step should be selected one time. (Select and order three.)
* Access the store to build datasets for training.
* Create a feature group.
* Ingest the records.
Answer:
Explanation: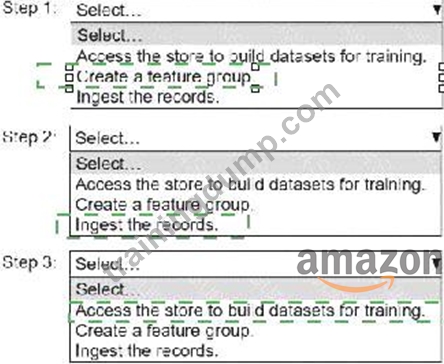
Explanation: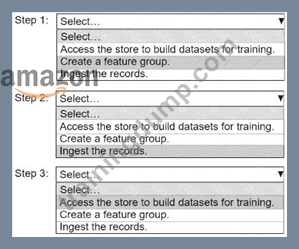
Step 1: Create a feature group.
Step 2: Ingest the records.
Step 3: Access the store to build datasets for training.
Step 1: Create a Feature Group
Why? A feature group is the foundational unit in SageMaker Feature Store, where features are defined, stored, and organized. Creating a feature group specifies the schema (name, data type) for the features and the primary keys for data identification.
How? Use the SageMaker Python SDK or AWS CLI to define the feature group by specifying its name, schema, and S3 storage location for offline access.
Step 2: Ingest the Records
Why? After creating the feature group, the raw data must be ingested into the Feature Store. This step populates the feature group with data, making it available for both real-time and offline use.
How? Use the SageMaker SDK or AWS CLI to batch-ingest historical data or stream new records into the feature group. Ensure the records conform to the feature group schema.
Step 3: Access the Store to Build Datasets for Training
Why? Once the features are stored, they can be accessed to create training datasets. These datasets combine relevant features into a single format for machine learning model training.
How? Use the SageMaker Python SDK to query the offline store or retrieve real-time features using the online store API. The offline store is typically used for batch training, while the online store is used for inference.
Order Summary:
Create a feature group.
Ingest the records.
Access the store to build datasets for training.
This process ensures the features are properly managed, ingested, and accessible for model training using Amazon SageMaker Feature Store.
NEW QUESTION # 48
......
The certification of Amazon MLA-C01 exam is what IT people want to get. Because it relates to their future fate. Amazon MLA-C01 exam training materials are the learning materials that each candidate must have. With this materials, the candidates will have the confidence to take the exam. Training materials in the TrainingDump are the best training materials for the candidates. With TrainingDump's Amazon MLA-C01 Exam Training materials, you will pass the exam easily.
MLA-C01 Reliable Exam Voucher: https://www.trainingdump.com/Amazon/MLA-C01-practice-exam-dumps.html
What's more, part of that TrainingDump MLA-C01 dumps now are free: https://drive.google.com/open?id=1fZObwH-Y1WoPib7xSNWxhiubUDAHHoiJ