BONUS!!! Japancert MLA-C01ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=14Qc1fKO2iWevIIjtmPG9SuY39WGYteXc
我々Japancertはお客様に満足させるための最高のサービスを提供します。あなたに安心させるため、我々はMLA-C01問題集のサンプルを無料で提供して、あなたはダウンロードしてやってみることができます。あなたはMLA-C01模擬問題集をご購入になってから、我々は一年間の無料更新サービスを提供します。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
理論の最新の発展に従って、MLA-C01練習教材が多くの専門家によって改訂されることを保証し、学生向けにカスタマイズされた学習コンテンツを専門的にJapancert編集します。つまり、MLA-C01試験を簡単かつ効率的に見つけることができます集中し、良い学術的成果を得る。さらに、MLA-C01試験ガイドは、お客様にサプリメントサービスモックテストを提供します。これにより、お客様はMLA-C01試験問題を勉強することにより、一生懸命勉強し、欠陥をチェックできます。
質問 # 39
An ML engineer needs to use Amazon SageMaker Feature Store to create and manage features to train a model.
Select and order the steps from the following list to create and use the features in Feature Store. Each step should be selected one time. (Select and order three.)
* Access the store to build datasets for training.
* Create a feature group.
* Ingest the records.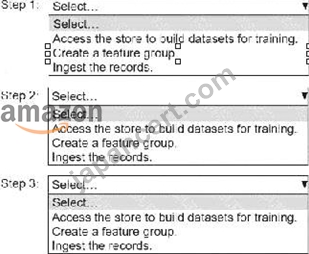
正解:
解説: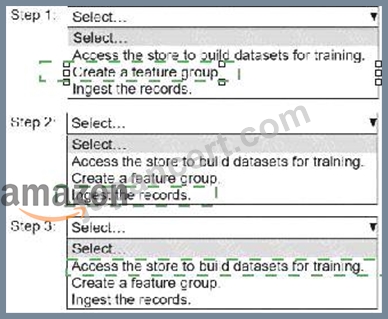
Explanation: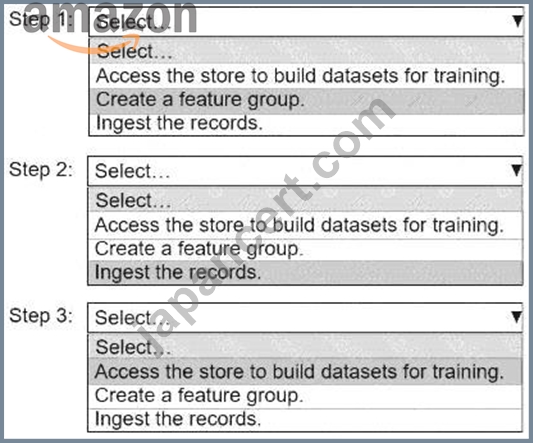
Step 1: Create a feature group.
Step 2: Ingest the records.
Step 3: Access the store to build datasets for training.
Step 1: Create a Feature Group
Why? A feature group is the foundational unit in SageMaker Feature Store, where features are defined, stored, and organized. Creating a feature group specifies the schema (name, data type) for the features and the primary keys for data identification.
How? Use the SageMaker Python SDK or AWS CLI to define the feature group by specifying its name, schema, and S3 storage location for offline access.
Step 2: Ingest the Records
Why? After creating the feature group, the raw data must be ingested into the Feature Store. This step populates the feature group with data, making it available for both real-time and offline use.
How? Use the SageMaker SDK or AWS CLI to batch-ingest historical data or stream new records into the feature group. Ensure the records conform to the feature group schema.
Step 3: Access the Store to Build Datasets for Training
Why? Once the features are stored, they can be accessed to create training datasets. These datasets combine relevant features into a single format for machine learning model training.
How? Use the SageMaker Python SDK to query the offline store or retrieve real-time features using the online store API. The offline store is typically used for batch training, while the online store is used for inference.
Order Summary:
Create a feature group.
Ingest the records.
Access the store to build datasets for training.
This process ensures the features are properly managed, ingested, and accessible for model training using Amazon SageMaker Feature Store.
質問 # 40
A company uses Amazon SageMaker for its ML workloads. The company's ML engineer receives a 50 MB Apache Parquet data file to build a fraud detection model. The file includes several correlated columns that are not required.
What should the ML engineer do to drop the unnecessary columns in the file with the LEAST effort?
正解:B
解説:
SageMaker Data Wrangler provides a no-code/low-code interface for preparing and transforming data, including dropping unnecessary columns. By creating a data flow and configuring a transform step, the ML engineer can easily remove correlated or unneeded columns from the Parquet file with minimal effort. This approach avoids the need for custom coding or managing additional infrastructure.
質問 # 41
A company uses a hybrid cloud environment. A model that is deployed on premises uses data in Amazon 53 to provide customers with a live conversational engine.
The model is using sensitive data. An ML engineer needs to implement a solution to identify and remove the sensitive data.
Which solution will meet these requirements with the LEAST operational overhead?
正解:A
解説:
Amazon Macie is a fully managed data security and privacy service that uses machine learning to discover and classify sensitive data in Amazon S3. It is purpose-built to identify sensitive data with minimal operational overhead. After identifying the sensitive data, you can use AWS Lambda functions to automate the process of removing or redacting the sensitive data, ensuring efficiency and integration with the hybrid cloud environment. This solution requires the least development effort and aligns with the requirement to handle sensitive data effectively.
質問 # 42
A company collects customer data daily and stores it as compressed files in an Amazon S3 bucket partitioned by date. Each month, analysts process the data, check data quality, and upload results to Amazon QuickSight dashboards.
An ML engineer needs to automatically check data quality before the data is sent to QuickSight, with the LEAST operational overhead.
Which solution will meet these requirements?
正解:D
解説:
AWS Glue Data Quality provides managed, declarative data quality checks with minimal configuration.
Combined with Glue crawlers, it enables automatic schema discovery and quality validation without custom code.
Option A uses native AWS services designed for this exact purpose, minimizing operational overhead.
Options B and C require custom code and maintenance. Option D is not designed for data validation.
AWS documentation explicitly recommends Glue Data Quality rules for scalable, automated data quality checks in analytics pipelines.
Therefore, Option A is the correct and AWS-aligned solution.
質問 # 43
An ML engineer is developing a neural network to run on new user data. The dataset has dozens of floating- point features. The dataset is stored as CSV objects in an Amazon S3 bucket. Most objects and columns are missing at least one value. All features are relatively uniform except for a small number of extreme outliers.
The ML engineer wants to use Amazon SageMaker Data Wrangler to handle missing values before passing the dataset to the neural network.
Which solution will provide the MOST complete data?
正解:C
解説:
The primary goal is to produce the most complete dataset while handling missing values and extreme outliers appropriately. Dropping samples (Option A) or columns (Option D) would reduce data completeness and potentially remove valuable information, which contradicts the requirement.
Imputation is therefore the correct approach. Between mean and median imputation, AWS ML best practices recommend using the median when features contain outliers. The mean is sensitive to extreme values and can be skewed significantly, leading to imputed values that are not representative of the typical data distribution.
In contrast, the median is robust to outliers, making it a better statistical estimator for central tendency in such datasets.
Amazon SageMaker Data Wrangler supports median imputation as a built-in transformation, enabling ML engineers to handle missing values consistently across large tabular datasets without custom code. This approach preserves all rows and columns while minimizing distortion caused by extreme values, which is particularly important for neural networks that are sensitive to input distributions.
Therefore, imputing missing values with the median value provides the most complete and statistically appropriate dataset for training.
質問 # 44
......
MLA-C01学習実践ガイドは、実際の試験を刺激する機能を強化します。クライアントは当社のソフトウェアを使用して、実際の試験を刺激し、実際のMLA-C01試験の速度、環境、プレッシャーに精通し、実際の試験の準備を整えることができます。仮想試験環境では、クライアントはMLA-C01の質問に答えるために速度を調整し、実際の戦闘能力を訓練し、実際のテストのプレッシャーに調整することができます。また、MLA-C01学習実践ガイドの習熟度を理解することもできます。
MLA-C01試験内容: https://www.japancert.com/MLA-C01.html
P.S.JapancertがGoogle Driveで共有している無料の2026 Amazon MLA-C01ダンプ:https://drive.google.com/open?id=14Qc1fKO2iWevIIjtmPG9SuY39WGYteXc