Three versions for Databricks-Certified-Professional-Data-Engineer exam cram are available, and you can choose the most suitable one according to your own needs. Databricks-Certified-Professional-Data-Engineer Online test engine supports all web browsers, and you can also have offline practice. One of the most outstanding features of Databricks-Certified-Professional-Data-Engineer Online test engine is that it has testing history and performance review, and you can have a general review of what you have learnt through this version. Databricks-Certified-Professional-Data-Engineer Soft test engine supports MS operating system as well as stimulates real exam environment, therefore it can build up your confidence. Databricks-Certified-Professional-Data-Engineer PDF version is printable, and you can study anytime.
| Section | Objectives |
|---|---|
| Topic 1: Data Modeling and Storage | - Design scalable data lakehouse architectures - Schema evolution and data partitioning strategies - Delta Lake table design and optimization |
| Topic 2: Data Ingestion and Transformation | - Handle batch and streaming data pipelines - Ingest data using Apache Spark and Databricks - Transform and clean datasets using Spark SQL and DataFrame APIs |
| Topic 3: Production Pipelines and Orchestration | - Pipeline reliability and fault tolerance - Automate ETL pipelines and scheduling - Build and manage workflows using Databricks Jobs |
| Topic 4: Security, Governance, Monitoring, and Optimization | - Implement Unity Catalog governance and access control - Monitor and optimize Spark workloads - Cost optimization and performance tuning |
>> Databricks-Certified-Professional-Data-Engineer Test Testking <<
Are you planning to attempt the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam of the Databricks-Certified-Professional-Data-Engineer certification? The first hurdle you face while preparing for the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam is not finding the trusted brand of accurate and updated Databricks-Certified-Professional-Data-Engineer exam questions. If you don't want to face this issue then you are at the trusted DumpsTests is offering actual and Latest Databricks-Certified-Professional-Data-Engineer Exam Questions that ensure your success in the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) certification exam on your maiden attempt.
NEW QUESTION # 116
Which of the following data workloads will utilize a Silver table as its source?
Answer: C
NEW QUESTION # 117
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings.
The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
Answer: D
Explanation:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. Thesestatistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.References: Databricks documentation on Delta Lake optimization techniques, including data skipping and statistics collection (https://docs.databricks.com/delta/optimizations
/index.html).
NEW QUESTION # 118
A data engineer needs to dynamically create a table name string using three Python varia-bles: region, store,
and year. An example of a table name is below when region = "nyc", store = "100", and year = "2021":
nyc100_sales_2021
Which of the following commands should the data engineer use to construct the table name in Py-thon?
Answer: D
NEW QUESTION # 119
A query is taking too long to run. After investigating the Spark UI, the data engineer discovered a significant amount of disk spill. The compute instance being used has a core-to-memory ratio of 1:2.
What are the two steps the data engineer should take to minimize spillage? (Choose 2 answers)
Answer: B,E
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Databricks recommends addressing disk spilling-which occurs when Spark tasks run out of memory-by increasing memory per core and controlling partition size. Selecting an instance type with a higher memory-to-core ratio (A) provides each task with more available RAM, directly reducing the chance of spilling to disk. Additionally, reducing spark.sql.files.maxPartitionBytes (D) creates smaller partitions, preventing any single task from holding too much data in memory. Increasing partition size (C) or disk capacity (B) does not solve memory bottlenecks, and bandwidth (E) affects network I/O, not spill behavior. Therefore, the correct actions are A and D.
NEW QUESTION # 120
Which of the following operations are not supported on a streaming dataset view?
spark.readStream.format("delta").table("sales").createOrReplaceTempView("streaming_view")
Answer: D
Explanation:
Explanation
The answer isSELECT * FROM streadming_view order by id Please Note: Sorting with Group by will work without any issues see below explanation for each option of the options, Graphical user interface, text, application Description automatically generated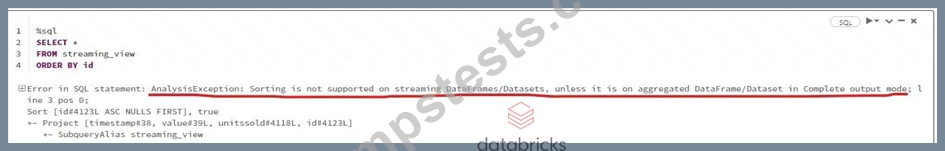
Certain operations are not allowed on streaming data, please see highlighted in bold.
https://spark.apache.org/docs/latest/structured-streaming-programming-guide.html#unsupported-operations
* Multiple streaming aggregations (i.e. a chain of aggregations on a streaming DF) are not yet supported on streaming Datasets.
* Limit and take the first N rows are not supported on streaming Datasets.
* Distinct operations on streaming Datasets are not supported.
* Deduplication operation is not supported after aggregation on a streaming Datasets.
* Sorting operations are supported on streaming Datasets only after an aggregation and in Complete Output Mode.
Note: Sorting without aggregation function is not supported.
Here is the sample code to prove this,
Setup test stream
Graphical user interface, text, application, email Description automatically generated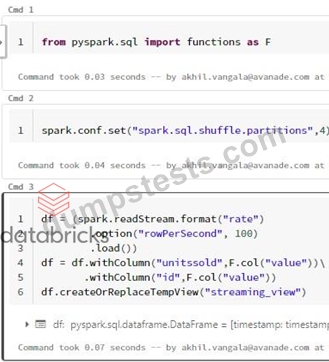
Sum aggregation function has no issues on stream
Graphical user interface, application Description automatically generated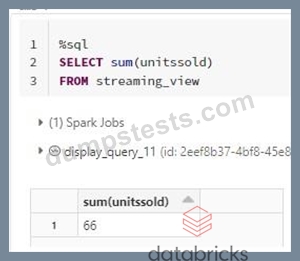
Max aggregation function has no issues on stream
Graphical user interface, application Description automatically generated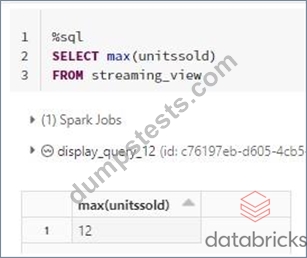
Group by with Order by has no issues on stream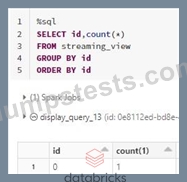
Group by has no issues on stream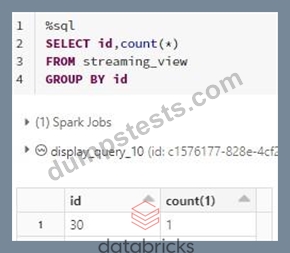
Table Description automatically generated
Order by without group by fails.
Graphical user interface, text, application Description automatically generated
NEW QUESTION # 121
......
For candidates who will buy Databricks-Certified-Professional-Data-Engineer exam braindumps online, the safety of the website is quite important. If you choose Databricks-Certified-Professional-Data-Engineer exam materials of us, we will ensure your safety. With professional technicians examining the website and exam dumps at times, the shopping environment is quite safe. In addition, we offer you instant download for Databricks-Certified-Professional-Data-Engineer Exam Braindumps, and we will send the download link and password to you within ten minutes after payment. And you can start your study immediately.
Databricks-Certified-Professional-Data-Engineer Exam Certification Cost: https://www.dumpstests.com/Databricks-Certified-Professional-Data-Engineer-latest-test-dumps.html