What's more, part of that PDFTorrent Certified-Data-Engineer-Professional dumps now are free: https://drive.google.com/open?id=17cnOx5liBz8NCdomlSi1OHPPaSw-FWp-
Do you want to find a high efficiency way to prepare for Certified-Data-Engineer-Professional exam test?As we all know, high efficiency will produce unbelievable benefits. With our Databricks Certified-Data-Engineer-Professional study pdf, you can make full use of your spare time. If you are tired of screen reading, you can print Certified-Data-Engineer-Professional Pdf Dumps into papers. You take your spare time to prepare and study. You will get your Certified-Data-Engineer-Professional exam certification with less time investment. Come on, everyone, Choose Certified-Data-Engineer-Professional test dumps, you will succeed.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
| Topic 2: Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations - Enforce data quality and quarantine bad data |
| Topic 3: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Topic 4: CI/CD, Testing, and Deployment | ~6% | - Deploy with Declarative Automation Bundles, CLI, and REST API - Implement testing and deployment pipelines |
| Topic 5: Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics - Implement reliable streaming pipelines |
| Topic 6: Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures - Use Spark UI, Query Profiler, and system tables |
| Topic 7: Data Modeling | ~10% | - Apply dimensional modeling techniques - Design scalable Delta Lake schemas and clustering |
| Topic 8: Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools - Optimize queries, clusters, and storage |
| Topic 9: Developing Code for Data Processing using Python and SQL | ~22% | - Manage dependencies, libraries, and UDFs - Implement scalable Python/SQL code and project structures - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader |
>> Reliable Certified-Data-Engineer-Professional Test Testking <<
A full Databricks Certified-Data-Engineer-Professional package is required to take each Success in Life. If you want to be successful, you need to prepare well for the Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional exam. Buying the right Databricks Certified-Data-Engineer-Professional Exam Preparation Materials is one way to prepare for it. With the right study tools, you can easily prepare for the Databricks Certified Data Engineer Professional. Whether you want to study Databricks Certified-Data-Engineer-Professional Exam or pass other Databricks Certified Data Engineer Professional exam, if you want to prepare for Databricks Certified-Data-Engineer-Professional exam, you can choose Databricks Certified-Data-Engineer-Professional Valid Exam Questions exam.
NEW QUESTION # 115
A departing platform owner currently holds ownership of multiple catalogs and controls storage credentials and external locations. A data engineer has been asked to ensure continuity: transfer catalog ownership to the platform team group, delegate ongoing privilege management, and retain the ability to receive and share data via Delta Sharing. Which role must be in place to perform these actions across the metastore?
Answer: C
Explanation:
Metastore Admins have the highest administrative privileges within a Unity Catalog metastore.
They can transfer ownership of any Unity Catalog object, including catalogs, schemas, tables, storage credentials, and external locations. Metastore Admins are also required to manage Delta Sharing configurations such as creating or transferring shares and recipients.
Account Admins, by contrast, only create metastores and cannot change ownership or manage Delta Sharing objects. Workspace Admins have privileges limited to workspace-level management, not cross-metastore access.
NEW QUESTION # 116
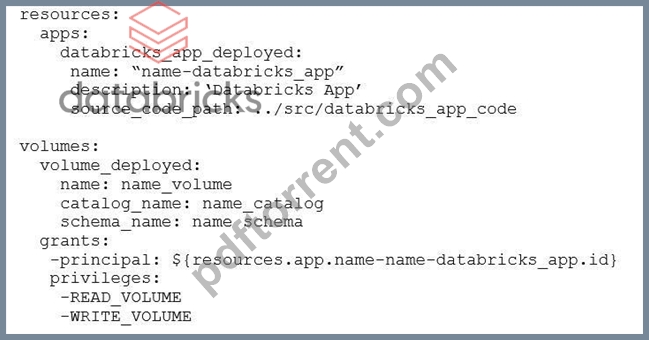
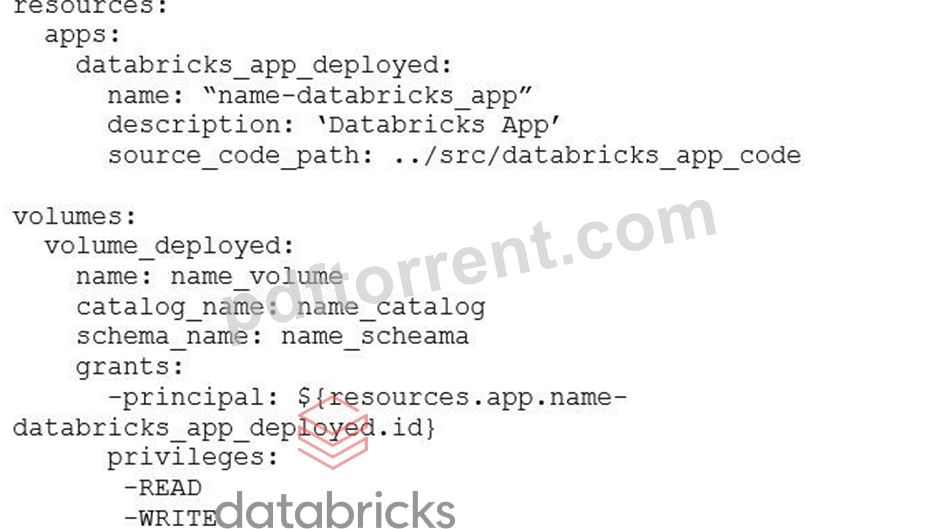
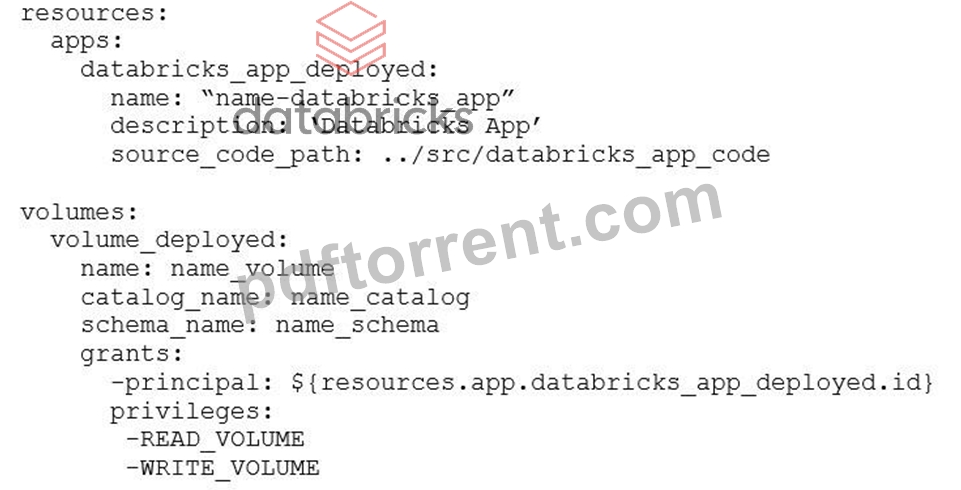
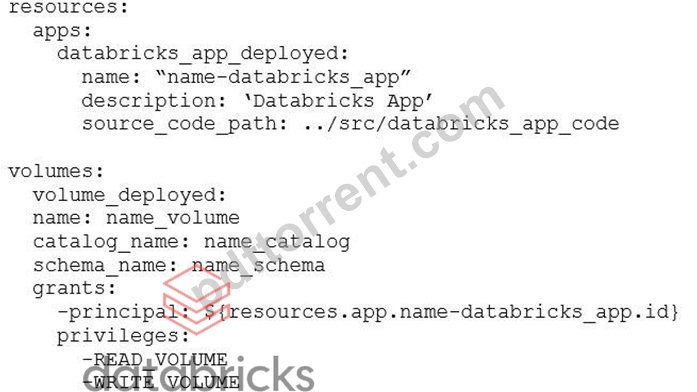
In a Databricks Asset Bundle project, in the file resources/app.yml, the data engineer would like to deploy a Databricks Apps databricks_app_deployed and Volume volume_deployed and grant the Service Principal behind Databricks Apps permissions to READ and WRITE to the Volume.
How should the data engineer achieve the deployment?
Answer: C
Explanation:
This configuration correctly references the service principal created for the Databricks App using the deployed app resource identifier, and it grants the required READ and WRITE privileges at the Volume level. The privileges are specified using the correct Volume-specific permissions, ensuring the Databricks App can securely access the Volume after deployment.
NEW QUESTION # 117
A data engineer is using Lakeflow Declarative Pipeline to propagate row deletions from a source bronze table (user_bronze) to a target silver table (user_silver). The engineer wants deletions in user_bronze to automatically delete corresponding rows in user_silver during pipeline execution.
Which configuration ensures deletions in the bronze table are propagated to the silver table?
Answer: B
Explanation:
According to Databricks documentation, Change Data Feed (CDF) allows pipelines to read incremental data changes, including inserts, updates, and deletes, from a Delta table. When deletions occur in the source table, reading the CDF stream ensures downstream consumers receive the deletion records. The Lakeflow Declarative Pipelines API provides the apply_changes() function (or auto-CDC pipelines) with the apply_as_deletes parameter to correctly apply those deletions to the target table. This enables automatic synchronization between bronze and silver layers. Options A and D either require manual handling or complete rebuilds, and C incorrectly applies CDF to the target rather than the source. Therefore, enabling CDF on the bronze table and using apply_as_deletes=True is the correct, Databricks-supported configuration.
NEW QUESTION # 118
A data engineer inherits a Delta table with historical partitions by country that are badly skewed.
Queries often filter by high-cardinality customer_id and vary across dimensions over time. The engineer wants a strategy that avoids a disruptive full rewrite, reduces sensitivity to skewed partitions, and sustains strong query performance as access patterns evolve. Which two actions should the data engineer take? (Choose two.)
Answer: C,D
Explanation:
Liquid Clustering replaces traditional partitioning and ZORDER optimization by automatically organizing data according to clustering keys. It supports evolving clustering strategies without requiring a full table rewrite. To maintain cluster balance and improve performance, the OPTIMIZE command should be run periodically. OPTIMIZE groups data files by clustering keys and helps reduce small file overhead.
NEW QUESTION # 119
A table in the Lakehouse named customer_churn_params is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours.
Which approach would simplify the identification of these changed records?
Answer: C
Explanation:
The approach that would simplify the identification of the changed records is to replace the current overwrite logic with a merge statement to modify only those records that have changed, and write logic to make predictions on the changed records identified by the change data feed.
This approach leverages the Delta Lake features of merge and change data feed, which are designed to handle upserts and track row-level changes in a Delta table. By using merge, the data engineering team can avoid overwriting the entire table every night, and only update or insert the records that have changed in the source data. By using change data feed, the ML team can easily access the change events that have occurred in the customer_churn_params table, and filter them by operation type (update or insert) and timestamp. This way, they can only make predictions on the records that have changed in the past 24 hours, and avoid re-processing the unchanged records.
NEW QUESTION # 120
......
The Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) questions are available in three easy-to-use forms. The first one is a Certified-Data-Engineer-Professional Dumps PDF form, and it is printable and portable. You can print Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional)questions PDF or can access them by saving them on your smartphones, tablets, and laptops. The Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) dumps PDF format can be used anywhere, anytime and is essential for students who like to learn from their smart devices for Certified-Data-Engineer-Professional exam.
Certified-Data-Engineer-Professional Braindump Pdf: https://www.pdftorrent.com/Certified-Data-Engineer-Professional-exam-prep-dumps.html
DOWNLOAD the newest PDFTorrent Certified-Data-Engineer-Professional PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=17cnOx5liBz8NCdomlSi1OHPPaSw-FWp-