The software version of our AI-200 study engine is designed to simulate a real exam situation. You can install it to as many computers as you need as long as the computer is in Windows system. And our software of the AI-200 training material also allows different users to study at the same time. It's economical for a company to buy it for its staff. Friends or workmates can also buy and learn with our AI-200 Practice Guide together.
| Section | Objectives |
|---|---|
| Topic 1: Implement and monitor AI workloads | - Monitor performance and troubleshoot issues - Deploy AI models and services |
| Topic 2: Implement Azure AI solutions | - Implement generative AI solutions using Azure OpenAI - Implement natural language processing solutions - Implement computer vision solutions - Implement knowledge mining with Azure AI Search |
| Topic 3: Plan and manage Azure AI solutions | - Plan security and compliance requirements - Monitor and optimize AI solutions - Select appropriate Azure AI services |
>> New Soft AI-200 Simulations <<
In this era of the latest technology, we should incorporate interesting facts, figures, visual graphics, and other tools that can help people read the Developing AI Cloud Solutions on Azure (AI-200) exam questions with interest. DumpExam uses pictures that are related to the Developing AI Cloud Solutions on Azure (AI-200) certification exam and can even add some charts, and graphs that show the numerical values.
NEW QUESTION # 55
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
You need to improve throughput for concurrent application requests to PostgreSQL. What should you implement?
Answer: A
Explanation:
To improve throughput for highly concurrent application requests in this architecture, you should implement connection pooling.
PostgreSQL follows a process-based architecture where each client connection spawns a separate backend process. This consumes significant memory and CPU overhead during high concurrency. Connection pooling (using tools like PgBouncer or Azure's built-in pooler) allows containerized microservices to reuse a fixed set of database connections. This drastically reduces connection overhead, prevents database exhaustion, and maximizes throughput for short, rapid API queries like vector similarity searches.
Reference:
https://medium.com/@srajanpathak45/a-principal-engineers-guide-to-postgresql-and-modern-alternatives-e8920fd6269a
NEW QUESTION # 56
You are developing an AI application that retrieves database credentials from Key Vault by using the Azure SDK for Python.
The application must use managed identity for authentication.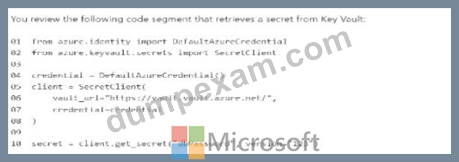
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.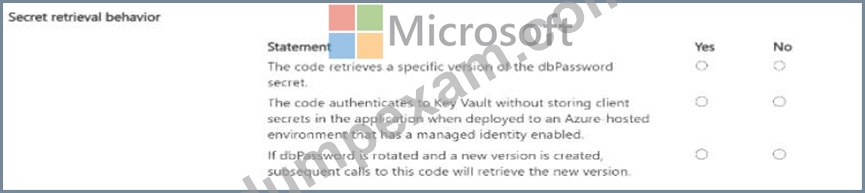
Answer:
Explanation: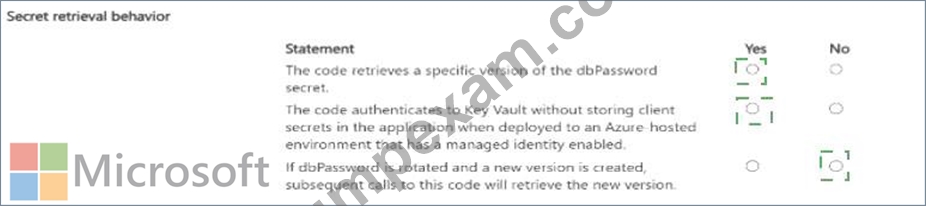
Explanation: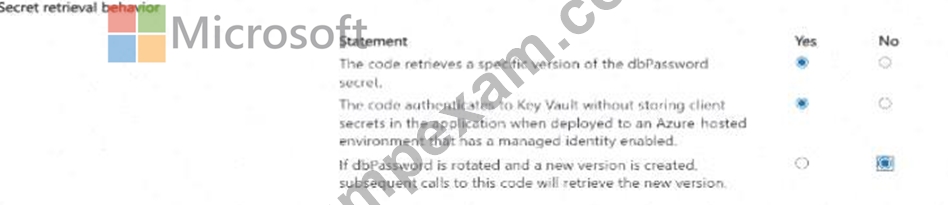
Verified Answer: Yes; Yes; No.
Detailed Explanation: The get_secret call supplies an explicit version value, so it retrieves that particular version of dbPassword. DefaultAzureCredential can authenticate to Key Vault by using the Azure-hosted application's managed identity without embedding a client secret in the application. Because the code requests a fixed version, later secret rotation creates a newer version but subsequent executions of this exact code continue to request the specified old version. To follow the latest version automatically, the version parameter must be omitted.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Managed identities for Azure resources | Use Key Vault references for App Service and Functions
NEW QUESTION # 57
You are deploying an AI service to Azure Container Apps.
The service must retrieve secrets securely from Key Vault by using managed identity.
You need to configure secure access.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.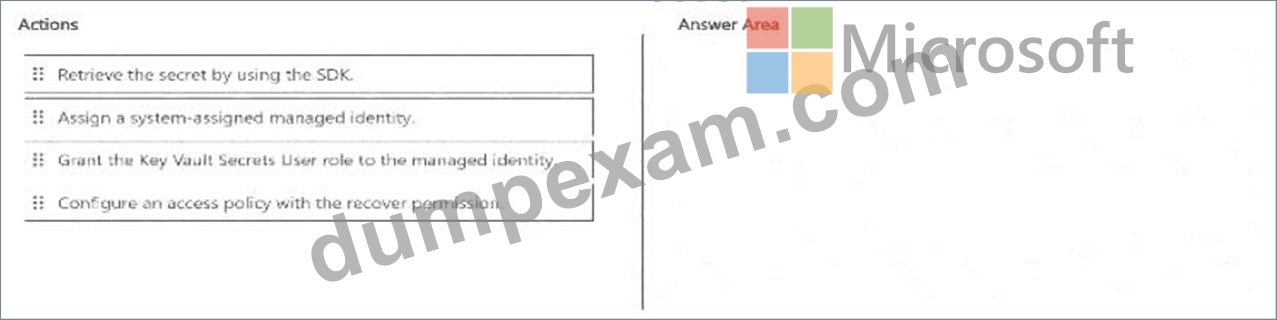
Answer:
Explanation: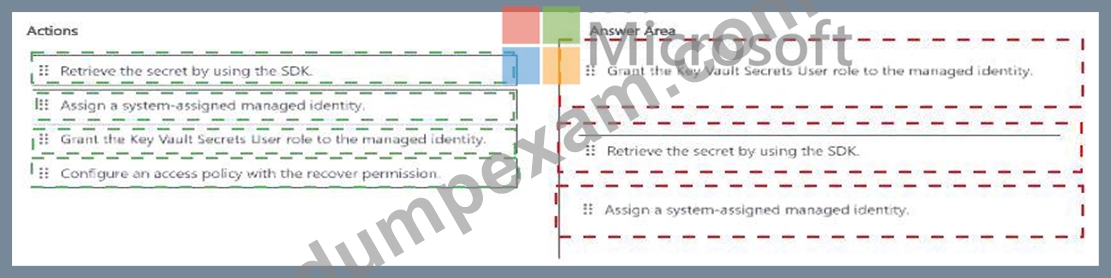
Explanation: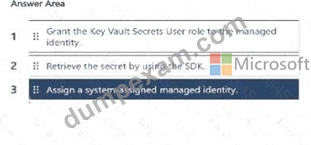
NEW QUESTION # 58
You have container source code stored in a Git repository.
The container registry must automatically build and store a new container image whenever a developer commits code to the Git repository.
You must minimize the use of an external build infrastructure.
You need to configure Azure Container Registry (ACR) to manage the build process natively and automatically.
Which two ACR components should you use? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,B
Explanation:
The two components that should be included in the solution are a Source-triggered task and a Webhook.
Source-triggered task: This component fulfills the requirement natively within Azure. An Azure Container Registry (ACR) Task can monitor a Git repository (like GitHub or Azure Repos).
Whenever a developer commits code, it automatically triggers a native build inside Azure without needing external CI/CD build infrastructure.
Webhook: This is the underlying mechanism that connects your Git repository to ACR. When a commit occurs, the Git repository sends a webhook notification to Azure Container Registry to signal the source-triggered task to start building the new image.
Reference:
https://learn.microsoft.com/en-us/azure/container-registry/container-registry-tutorial-build-task
NEW QUESTION # 59
You are building a semantic search feature for a chatbot. You store document embeddings in Redis.
You review the following Python code that connects to Redis and stores an embedding value: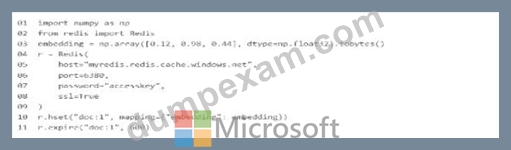
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.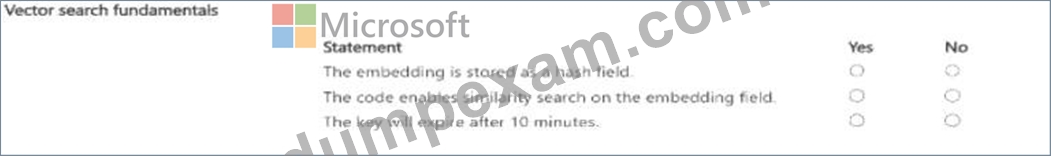
Answer:
Explanation: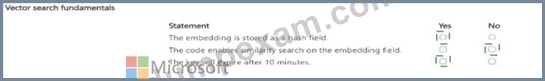
Explanation:
Verified answer: Yes; No; Yes.
Detailed Explanation: `HSET` stores the binary embedding as a field in the Redis hash keyed by `doc:1`, so the first statement is true. The code does not create a RediSearch/Redis Query Engine vector index or define a vector field schema; merely storing bytes does not enable similarity search, so the second statement is false.
`EXPIRE doc:1 600` sets a 600-second lifetime, which is ten minutes, making the third statement true.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Vector search in Azure Managed Redis
NEW QUESTION # 60
......
For this task, you need to update Microsoft AI-200 preparation material to get success. If applicants fail to find reliable material, they fail the Microsoft AI-200 examination. Failure leads to loss of money and time. You just need to rely on DumpExam to avoid these losses. DumpExam has launched three formats of real Microsoft AI-200 Exam Dumps.
Examcollection AI-200 Dumps: https://www.dumpexam.com/AI-200-valid-torrent.html