BTW, DOWNLOAD part of Actual4test DP-600 dumps from Cloud Storage: https://drive.google.com/open?id=14Yj4UF4DUxnbRUjlQu0brDmjbMcgkxSR
As a matter of fact, long-time study isn’t a necessity, but learning with high quality and high efficient is the key method to assist you to succeed. We provide several sets of DP-600 test torrent with complicated knowledge simplified and with the study content easy to master, thus limiting your precious time but gaining more important knowledge. Our study materials are cater every candidate no matter you are a student or office worker, a green hand or a staff member of many years' experience, DP-600 Certification Training is absolutely good choices for you. Therefore, you have no need to worry about whether you can pass the exam, because we guarantee you to succeed with our technology strength.
| Section | Objectives |
|---|---|
| Topic 1: Real-time analytics | - Streaming and event processing
|
| Topic 2: Get data into Microsoft Fabric | - Data ingestion and integration
|
| Topic 3: Implement data engineering solutions | - Lakehouse architecture
|
| Topic 4: Manage and secure Microsoft Fabric | - Governance and administration
|
| Topic 5: Implement analytics solutions | - Data warehousing and modeling
|
Our DP-600 exam braindumps are famous for its advantage of high efficiency and good quality which are carefully complied by the professionals. Our excellent professionals are furnishing exam candidates with highly effective DP-600 Study Materials, you can even get the desirable outcomes within one week. By concluding quintessential points into DP-600 actual exam, you can pass the exam with the least time while huge progress.
NEW QUESTION # 100
You have a Fabric tenant that contains a lakehouse named LH1.
You need to deploy a new semantic model. The solution must meet the following requirements:
* Support complex calculated columns that include aggregate functions, calculated tables, and Multidimensional Expressions (MDX) user hierarchies.
* Minimize page rendering times.
How should you configure the model? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.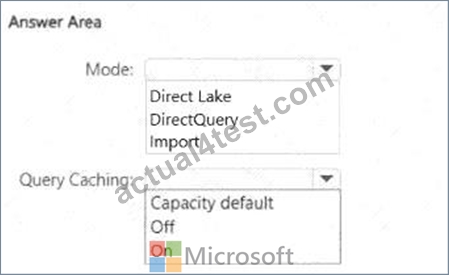
Answer:
Explanation: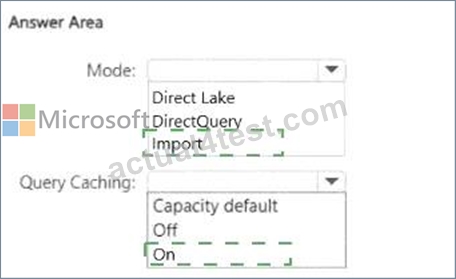
Explanation: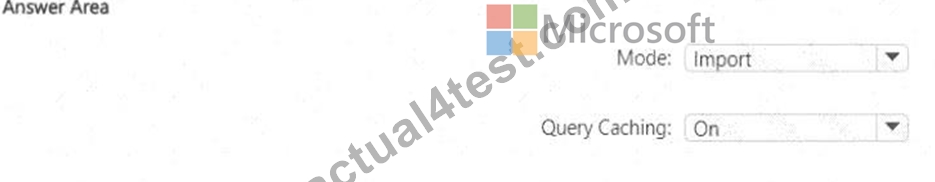
Supports complex calculated columns (with aggregate functions, calculated tables, MDX hierarchies).
Minimizes page rendering times .
Step 1 - Choosing the Mode
Direct Lake # Best for near real-time queries, avoids duplication, but has limitations (e.g., some complex calculated columns, MDX user hierarchies are not fully supported).
DirectQuery # Sends queries to the source each time. It supports complex expressions but is slow (not optimal for minimizing page rendering times).
Import # Data is loaded into VertiPaq in-memory engine, supports full DAX capabilities, calculated tables, MDX hierarchies, and provides fastest query performance .
# Correct choice: Import .
Step 2 - Choosing Query Caching
Capacity default # Relies on the workspace/capacity setting.
Off # Disables caching, which could slow down report rendering.
On # Ensures queries are cached for faster page rendering times.
# Correct choice: On .
Mode: Import
Query Caching: On
References:
Semantic model storage modes in Fabric
Query caching in Power BI / Fabric
NEW QUESTION # 101
You have a Fabric workspace that uses the default Spark starter pool and runtime version 1,2.
You plan to read a CSV file named Sales.raw.csv in a lakehouse, select columns, and save the data as a Delta table to the managed area of the lakehouse. Sales_raw.csv contains 12 columns.
You have the following code.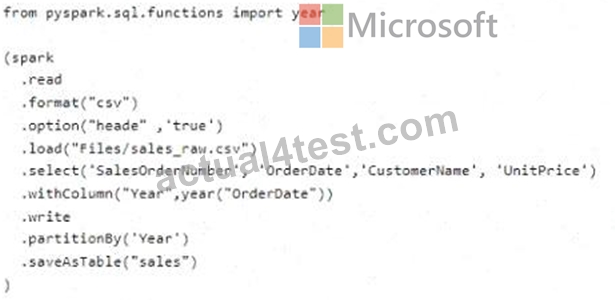
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.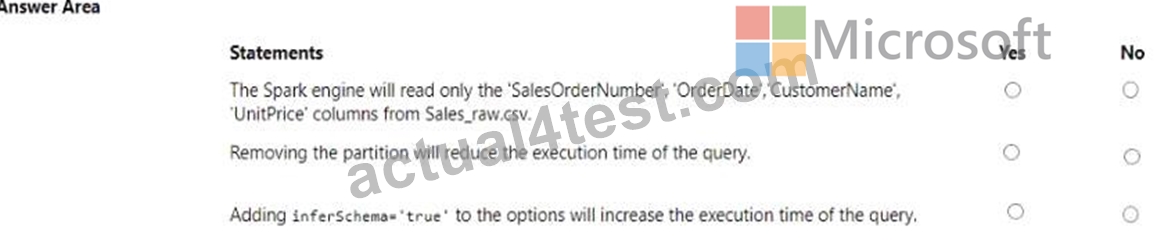
Answer:
Explanation: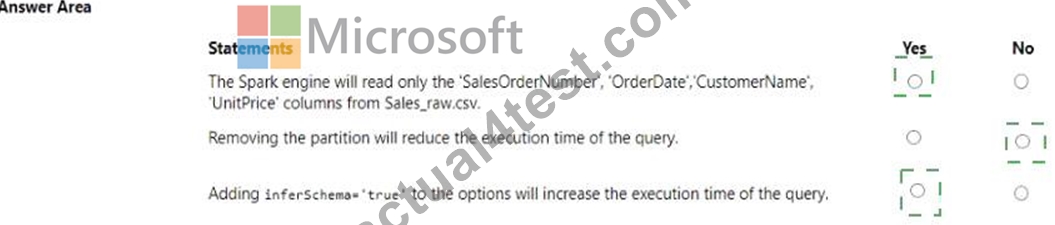
Explanation: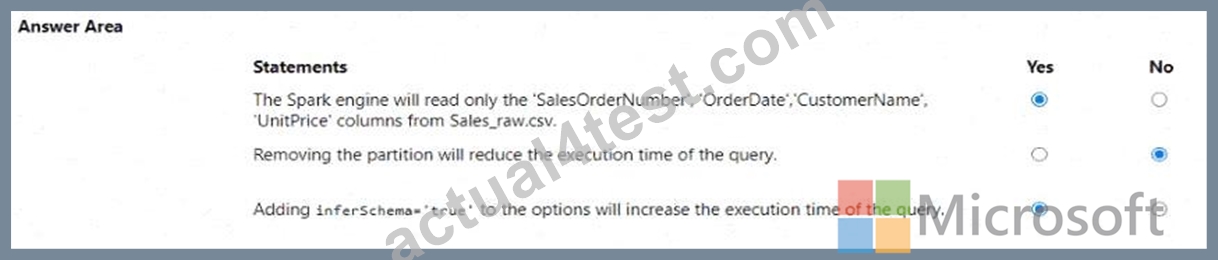
The Spark engine will read only the ' SalesOrderNumber ' , ' OrderDate ' , ' CustomerName ' , ' UnitPrice ' columns from Sales_raw.csv. - Yes Removing the partition will reduce the execution time of the query. - No Adding inferSchema= ' true ' to the options will increase the execution time of the query. - Yes The code specifies the selection of certain columns, which means only those columns will be read into the DataFrame. Partitions in Spark are a way to optimize the execution of queries by organizing the data into parts that can be processed in parallel. Removing the partition could potentially increase the execution time because Spark would no longer be able to process the data in parallel efficiently. The inferSchema option allows Spark to automatically detect the column data types, which can increase the execution time of the initial read operation because it requires Spark to read through the data to infer the schema.
NEW QUESTION # 102
You have a data warehouse that contains a table named Stage. Customers. Stage-Customers contains all the customer record updates from a customer relationship management (CRM) system. There can be multiple updates per customer You need to write a T-SQL query that will return the customer ID, name, postal code, and the last updated time of the most recent row for each customer ID.
How should you complete the code? To answer, select the appropriate options in the answer area, NOTE Each correct selection is worth one point.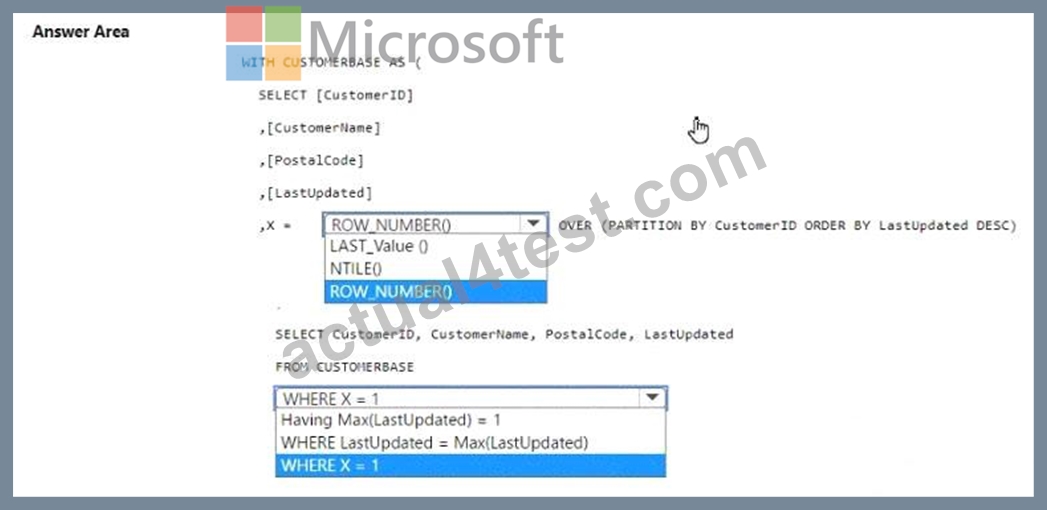
Answer:
Explanation: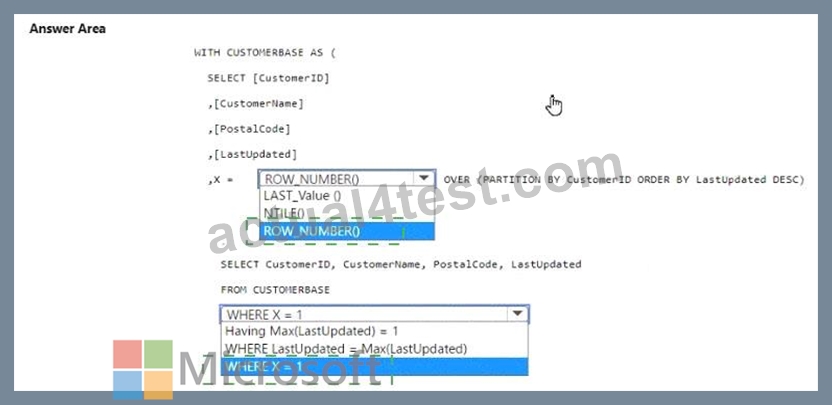
Explanation: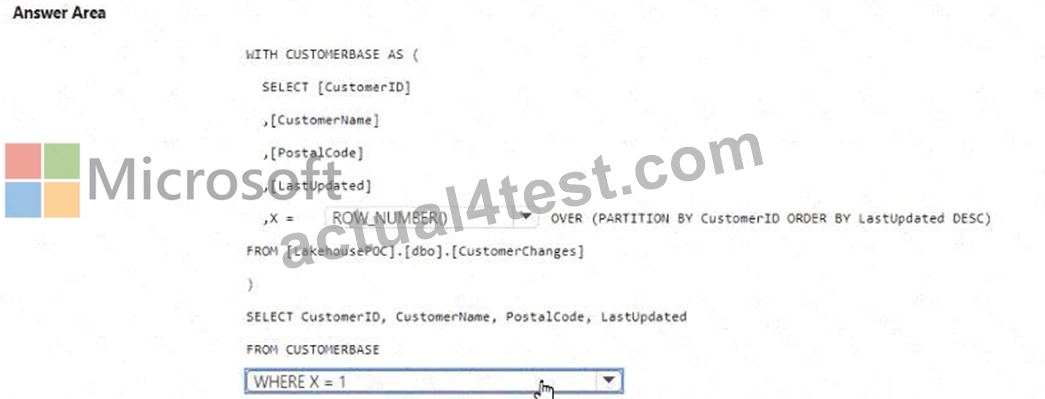
In the ROW_NUMBER() function, choose OVER (PARTITION BY CustomerID ORDER BY LastUpdated DESC).
In the WHERE clause, choose WHERE X = 1.
To select the most recent row for each customer ID, you use the ROW_NUMBER() window function partitioned by CustomerID and ordered by LastUpdated in descending order. This will assign a row number of 1 to the most recent update for each customer. By selecting rows where the row number (X) is 1, you get the latest update per customer.
References =
Use the OVER clause to aggregate data per partition
Use window functions
NEW QUESTION # 103
You have the following KQL query.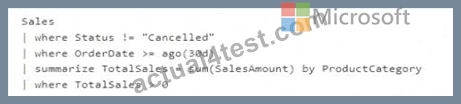
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.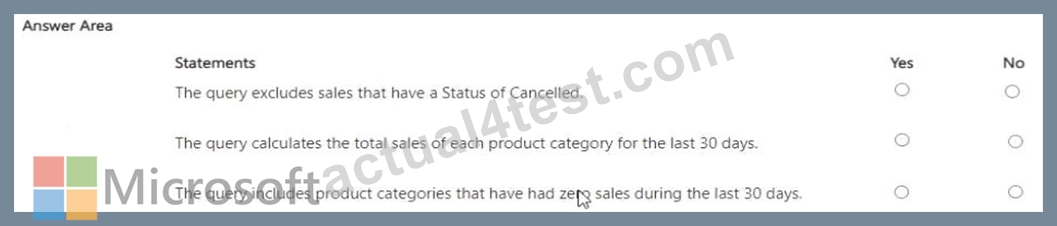
Answer:
Explanation:
Explanation: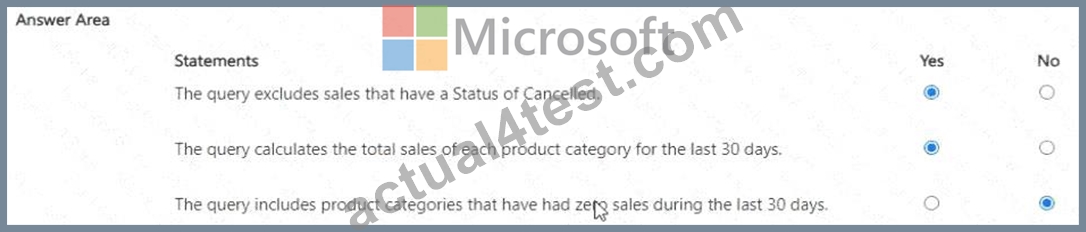
We are analyzing this KQL query:
Sales
| where Status != " Cancelled "
| where OrderDate > = ago(30d)
| summarize TotalSales = sum(SalesAmount) by ProductCategory
| where TotalSales > 0
Statement 1:
" The query excludes sales that have a Status of Cancelled. "
Yes # where Status != " Cancelled " filters them out.
Statement 2:
" The query calculates the total sales of each product category for the last 30 days. " Yes # where OrderDate > = ago(30d) ensures only last 30 days.
summarize TotalSales = sum(SalesAmount) by ProductCategory groups by category.
Statement 3:
" The query includes product categories that have had zero sales during the last 30 days. " No # The final filter where TotalSales > 0 excludes categories with zero sales.
Final Answer:
Excludes Cancelled sales # Yes
Calculates total sales by product category for last 30 days # Yes
Includes product categories with zero sales # No
References:
KQL where operator
KQL summarize operator
NEW QUESTION # 104
You have a Fabric eventhouse named Eventhousel that contains a table named Weatherdata. A sample of the data in Weatherdata is shown in the following table.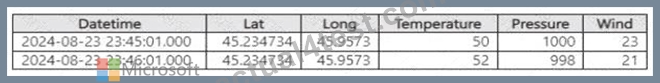
You plan to use a KQL queryset to manipulate the data in Eventhouse1. The result set must have the following columns.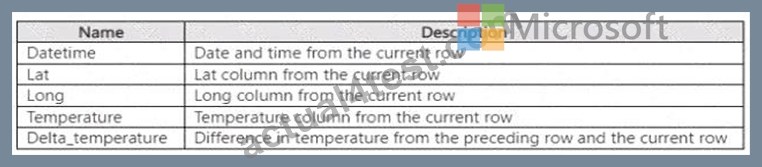
You need to build the query.
Which four KQL statements should you use in sequence? To answer, move the appropriate statements from the list of statements to the answer area and arrange them in the correct order.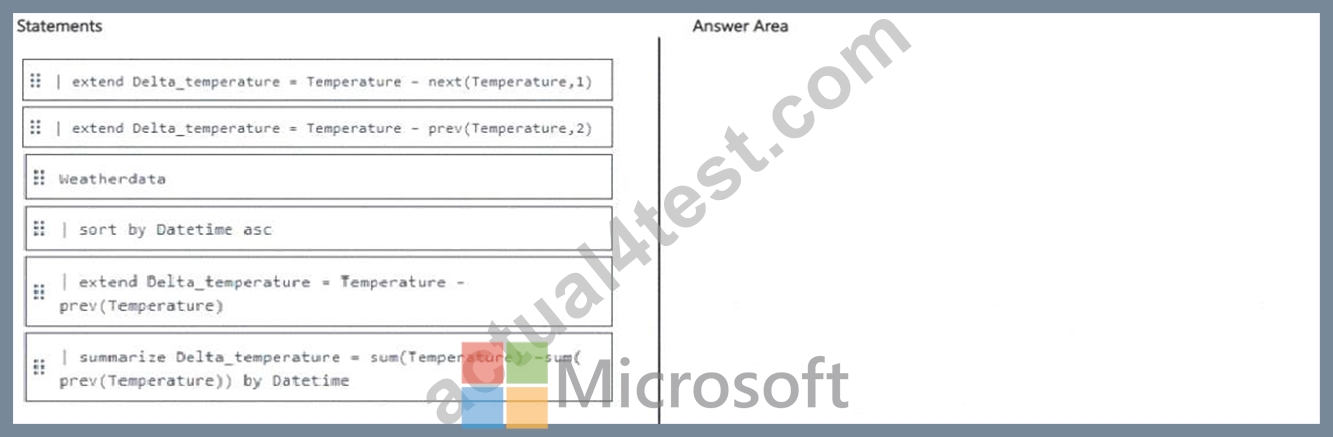
Answer:
Explanation: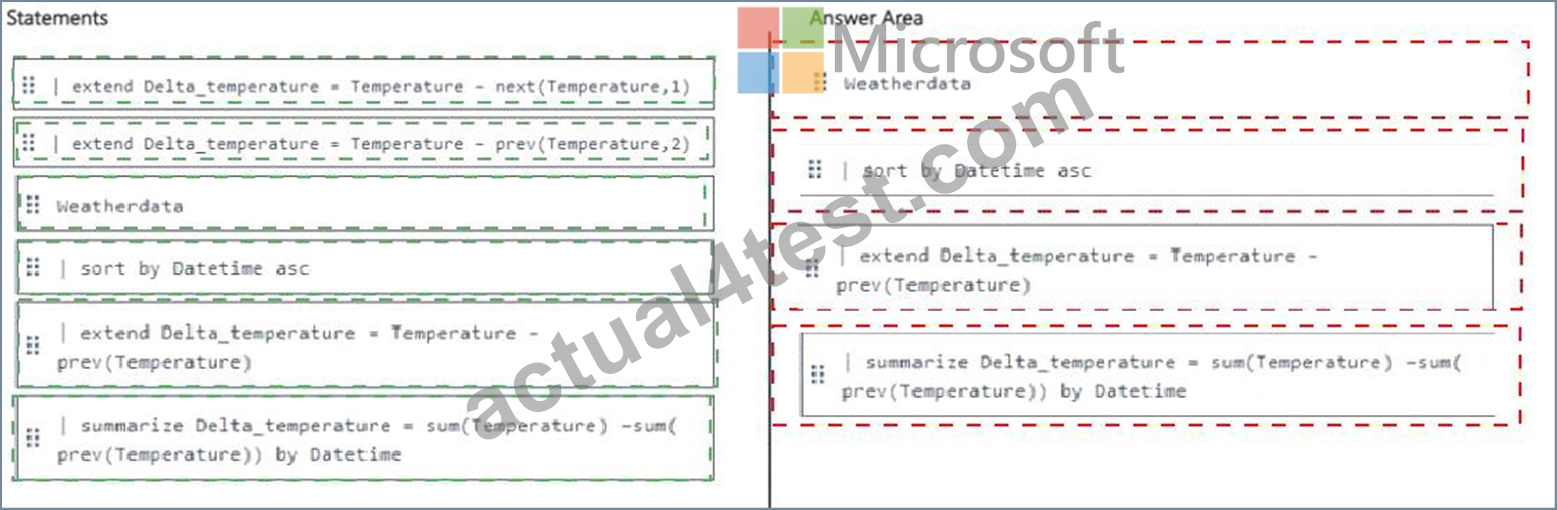
Explanation: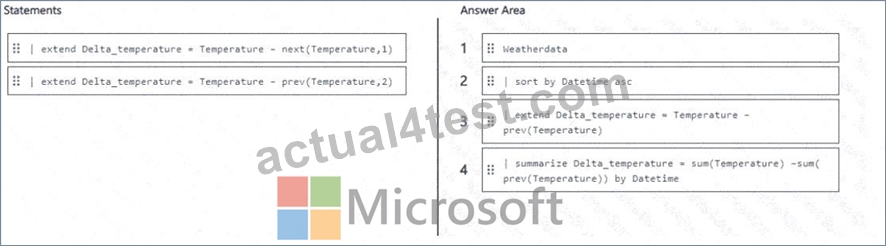
Comprehensive Detailed Explanation
Step 1: Understanding the requirement
We need a KQL query that:
Reads data from Weatherdata .
Orders by Datetime .
Calculates Delta_temperature as the difference between the current row and the preceding row .
Returns the final columns: Datetime, Lat, Long, Temperature, Delta_temperature .
Step 2: Evaluate the provided statements
Weatherdata # Starts the query with the source table.
| sort by Datetime asc # Ensures chronological order, required for prev() to work correctly.
| extend Delta_temperature = Temperature - prev(Temperature) # Computes difference between the current row and the previous row's temperature.
| project Datetime, Lat, Long, Temperature, Delta_temperature # Selects the required output columns.
Step 3: Incorrect choices (to avoid)
next(Temperature,1) # Would calculate the difference with the next row , not the previous.
prev(Temperature,2) # Would skip one row, giving the difference with two rows back, which is not needed.
summarize ... by Datetime # Aggregates the data; not required here since we just need row-level differences.
Step 4: Final Correct Sequence
Weatherdata
| sort by Datetime asc
| extend Delta_temperature = Temperature - prev(Temperature)
| project Datetime, Lat, Long, Temperature, Delta_temperature
References
prev() function in KQL
extend operator in KQL
project operator in KQL
NEW QUESTION # 105
......
In the era of rapid development in the IT industry, we have to look at those IT people with new eyes. They use their high-end technology to create many convenient place for us. And save a lot of manpower and material resources for the state and enterprises. And even reached unimaginable effect. Of course, their income must be very high. Do you want to be the kind of person? Do you envy them? Or you are also IT person, but you do not get this kind of success. Do not worry, Actual4test's Microsoft DP-600 Exam Material can help you to get what you want. To select Actual4test is equivalent to choose a success.
Interactive DP-600 Course: https://www.actual4test.com/DP-600_examcollection.html
P.S. Free & New DP-600 dumps are available on Google Drive shared by Actual4test: https://drive.google.com/open?id=14Yj4UF4DUxnbRUjlQu0brDmjbMcgkxSR