What's more, part of that ITExamSimulator DP-750 dumps now are free: https://drive.google.com/open?id=1HrFgUaERl3X2OjKtk38PIW70PdltQwyo
Passing an exam requires diligent practice, and using the right study Microsoft Certification Exams material is crucial for optimal performance. With this in mind, ITExamSimulator has introduced a range of innovative DP-750 Practice Test formats to help candidates prepare for their DP-750.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Data transformation and modeling
|
| Topic 2: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Topic 3: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Topic 4: Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
>> DP-750 Interactive Course <<
We try our best to provide the most efficient and intuitive learning methods to the learners and help them learn efficiently. Our DP-750 exam reference provides the instances to the clients so as to they can understand them intuitively. Based on the consideration that there are the instances to our DP-750 test guide to concretely demonstrate the knowledge points. Through the stimulation of the Real DP-750 Exam the clients can have an understanding of the mastery degrees of our DP-750 exam practice question in practice. Thus our clients can understand the abstract concepts in an intuitive way.
NEW QUESTION # 14
You need to configure compute for the ingestion of telemetry data. The solution must meet the data ingestion and processing requirements.
What should you do?
Answer: C
Explanation:
The correct answer is A. Photon is Azure Databricks ' native vectorized query engine, written in C++, designed to accelerate data ingestion and SQL-heavy workloads significantly over the standard Spark JVM path. Enabling it on a job compute cluster directly addresses Contoso ' s requirement for ' fast and consistent performance for BI workloads ' and ' production ingestion workloads that can scale automatically during telemetry spikes. ' Photon integrates transparently - no code changes are needed - and pairs well with autoscaling job clusters to handle the bursty 40,000-sensor telemetry load.
Option B contradicts the isolation requirement: Contoso explicitly needs production and development separated, not merged onto shared compute. Option C with a fixed large node gives peak capacity at all times, driving up costs even during quiet periods. Option D disabling autoscaling is the opposite of what ' s needed
- telemetry spikes require elastic scaling, not a locked node count.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/photon
NEW QUESTION # 15
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a table named Table1 by using a data quality validation rule named rule1.
You need to modify rule1 to meet the following requirements:
- Ensure that amount is always greater than 0.
- Prevent an update to Table1 from being committed when data that
violates rule1 is detected.
Which statement should you execute?
Answer: A
Explanation:
To ensure the data validation rule forces the pipeline update to abort and roll back transactions when data violates the condition, you must use a "fail" expectation operator. In Databricks Lakeflow Spark Declarative Pipelines (SDP), the command/syntax depends on whether your pipeline is written in Python or SQL.
Python Implementation
If your pipeline uses Python, apply the @dp.expect_or_fail decorator above your table definition (note: dp is the standard alias for the databricks.pipelines module in Lakeflow SDP):
dp.expect_or_fail("amount_greater_than_zero", "amount > 0")
Reference:
https://docs.databricks.com/aws/en/ldp/expectations
NEW QUESTION # 16
You use Declarative Automation Bundles to manage two jobs and an app.
You need to deploy the bundle to development and production environments. The solution must meet the following requirements:
* Deploy the app to both environments.
* Deploy only one job to development.
* Minimize administrative effort.
What should you use?
Answer: D
Explanation:
The targets mapping defines environment-specific deployment configurations within one databricks.yml file.
Development and production targets can apply different resource settings or exclusions while sharing the bundle's common definitions. This allows the app to be deployed to both environments and limits the development deployment to the required job without maintaining duplicate configuration files. Separate YAML files would duplicate shared settings and increase maintenance effort. The resources mapping declares jobs, pipelines, apps, and other Databricks resources but does not independently provide environment-specific deployment behavior. Variables provide reusable values and substitutions; they are not the primary mechanism for defining deployment environments. Declarative Automation Bundle targets are explicitly intended to model configurations such as development, staging, and production in a single bundle. Microsoft Learn
NEW QUESTION # 17
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 processes raw data files stored in Azure Storage.
New files arrive at unpredictable intervals.
You need to ensure that Job1 starts automatically when new files arrive and does NOT consume compute resources when no data is available.
Which type of job trigger should you use?
Answer: A
Explanation:
A file arrival trigger starts Job1 when new files are detected in the monitored Azure Storage location. Because the job is launched only after a qualifying arrival, compute does not remain active while the source is idle.
This is well suited to unpredictable file-delivery patterns and avoids the unnecessary executions produced by a fixed schedule. A continuous trigger keeps the workload running and therefore consumes compute even when no files are available. A scheduled trigger starts the job at predetermined times whether or not new data exists. A manual trigger cannot provide automatic processing. File arrival triggers consequently provide the required event-driven behavior while improving resource utilization and controlling cost during inactive periods. Microsoft Learn
NEW QUESTION # 18
Hotspot Question
You have an Azure Databricks workspace.
You have an Azure key vault named kv-secure that stores a secret named storageKey. The value of storageKey is managed and updated by the cloud security team at your company.
You need to enable a Databricks notebook named Notebook1 to retrieve the value of storageKey securely at runtime. The solution must follow the principle of least privilege and always retrieve the latest value.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.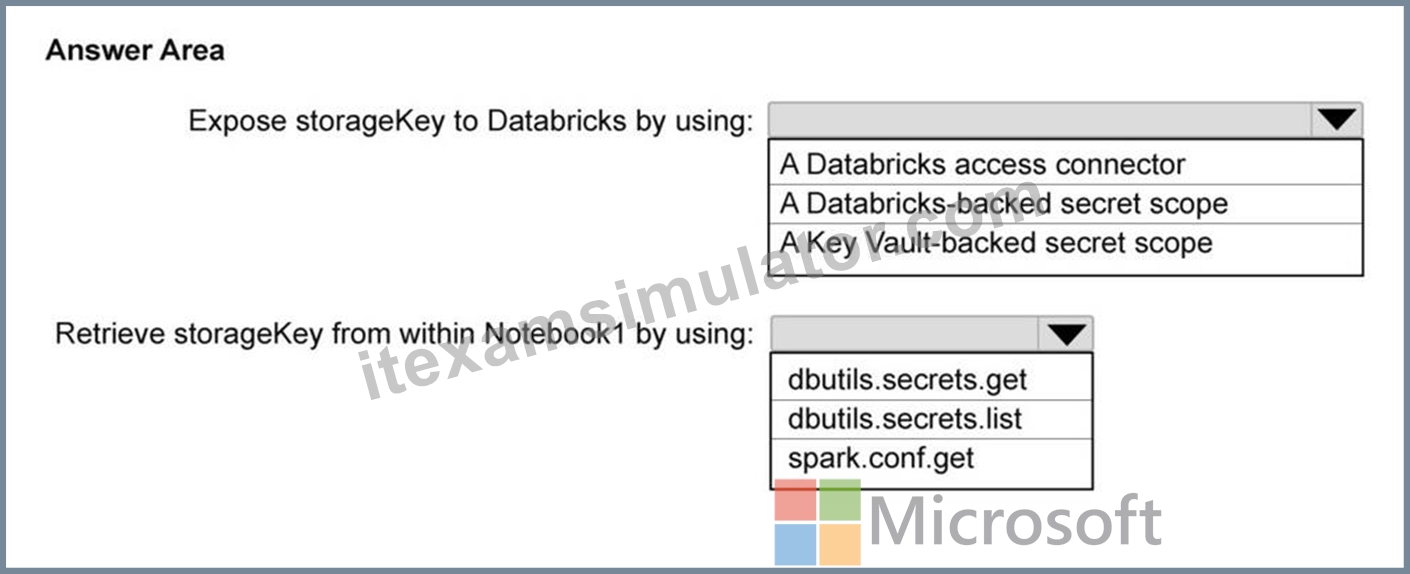
Answer:
Explanation: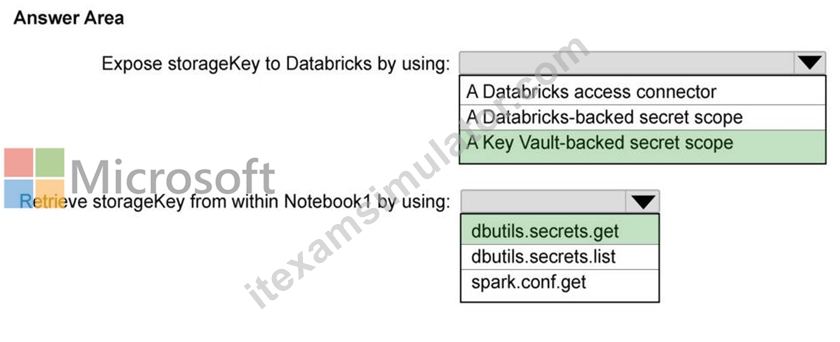
NEW QUESTION # 19
......
Our aim is to provide customers with actual Microsoft DP-750 questions so they pass their Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exams with confidence. We offer a free demos and up to 365 days of free Microsoft Dumps updates. One of the key elements of our approach is following the current exam content. Our DP-750 product is designed by experienced industry professionals and is regularly updated to reflect the latest changes in the DP-750 test content.
DP-750 Exam Study Guide: https://www.itexamsimulator.com/DP-750-brain-dumps.html
BTW, DOWNLOAD part of ITExamSimulator DP-750 dumps from Cloud Storage: https://drive.google.com/open?id=1HrFgUaERl3X2OjKtk38PIW70PdltQwyo