さらに、ShikenPASS Data-Engineer-Associateダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1j4qIhwDUWnoOnXLiBSJGsLL9-Gc6-STb
Data-Engineer-Associate認定を取得する意欲のある人には、主にオフィスワーカーが含まれます。彼らはより高い地位に着き、ハンサムな給料、さらには豊かな未来を手に入れることを期待しています。これらの要件はすべて、当社のData-Engineer-Associate試験材料が満たすことができます。 Data-Engineer-Associate学習教材は、試験の合格に役立ちます。 Data-Engineer-Associate試験トレントを購入する前に、Data-Engineer-Associate試験ガイドのいくつかの質問と回答を含むData-Engineer-Associate試験問題のShikenPASSデモを無料でダウンロードできます。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Operations and Support | 22% | - Automate data pipelines
|
| Topic 2: Data Ingestion and Transformation | 34% | - Transform and process data
|
| Topic 3: Data Security and Governance | 18% | - Apply authentication and authorization
|
| Topic 4: Data Store Management | 26% | - Design data models
|
>> Data-Engineer-Associateテスト模擬問題集 <<
Data-Engineer-Associate問題集を買うとき、支払いが成功したら、お客様は問題集をダウンロードできます。Data-Engineer-Associate問題集の有効性を確保する為に、AmazonはData-Engineer-Associate問題集のに対して、定期的に検査します。そうすれば、お客様にData-Engineer-Associate問題集の最新版を提供できます。
質問 # 81
A transportation company wants to track vehicle movements by capturing geolocation records. The records are 10 bytes in size. The company receives up to 10,000 records every second. Data transmission delays of a few minutes are acceptable because of unreliable network conditions.
The transportation company wants to use Amazon Kinesis Data Streams to ingest the geolocation data. The company needs a reliable mechanism to send data to Kinesis Data Streams. The company needs to maximize the throughput efficiency of the Kinesis shards.
Which solution will meet these requirements in the MOST operationally efficient way?
正解:A
解説:
Problem Analysis:
The company ingests geolocation records (10 bytes each) at 10,000 records per second into Kinesis Data Streams.
Data transmission delays are acceptable, but the solution must maximize throughput efficiency.
Key Considerations:
The Kinesis Producer Library (KPL) batches records and uses aggregation to optimize shard throughput.
Efficiently handles high-throughput scenarios with minimal operational overhead.
Solution Analysis:
Option A: Kinesis Agent
Designed for file-based ingestion; not optimized for geolocation records.
Option B: KPL
Aggregates records into larger payloads, significantly improving shard throughput.
Suitable for applications generating small, high-frequency records.
Option C: Kinesis Firehose
Firehose is for delivery to destinations like S3 or Redshift and is not optimized for direct ingestion to Kinesis Data Streams.
Option D: Kinesis SDK
The SDK lacks advanced features like aggregation, resulting in lower throughput efficiency.
Final Recommendation:
Use Kinesis Producer Library (KPL) for its built-in aggregation and batching capabilities.
Reference:
Kinesis Producer Library (KPL) Overview
質問 # 82
A company currently stores all of its data in Amazon S3 by using the S3 Standard storage class.
A data engineer examined data access patterns to identify trends. During the first 6 months, most data files are accessed several times each day. Between 6 months and 2 years, most data files are accessed once or twice each month. After 2 years, data files are accessed only once or twice each year.
The data engineer needs to use an S3 Lifecycle policy to develop new data storage rules. The new storage solution must continue to provide high availability.
Which solution will meet these requirements in the MOST cost-effective way?
正解:D
解説:
To achieve the most cost-effective storage solution, the data engineer needs to use an S3 Lifecycle policy that transitions objects to lower-cost storage classes based on their access patterns, and deletes them when they are no longer needed. The storage classes should also provide high availability, which means they should be resilient to the loss of data in a single Availability Zone1. Therefore, the solution must include the following steps:
Transition objects to S3 Standard-Infrequent Access (S3 Standard-IA) after 6 months. S3 Standard-IA is designed for data that is accessed less frequently, but requires rapid access when needed. It offers the same high durability, throughput, and low latency as S3 Standard, but with a lower storage cost and a retrieval fee2. Therefore, it is suitable for data files that are accessed once or twice each month. S3 Standard-IA also provides high availability, as it stores data redundantly across multiple Availability Zones1.
Transfer objects to S3 Glacier Deep Archive after 2 years. S3 Glacier Deep Archive is the lowest-cost storage class that offers secure and durable storage for data that is rarely accessed and can tolerate a 12-hour retrieval time. It is ideal for long-term archiving and digital preservation3. Therefore, it is suitable for data files that are accessed only once or twice each year. S3 Glacier Deep Archive also provides high availability, as it stores data across at least three geographically dispersed Availability Zones1.
Delete objects when they are no longer needed. The data engineer can specify an expiration action in the S3 Lifecycle policy to delete objects after a certain period of time. This will reduce the storage cost and comply with any data retention policies.
Option C is the only solution that includes all these steps. Therefore, option C is the correct answer.
Option A is incorrect because it transitions objects to S3 One Zone-Infrequent Access (S3 One Zone-IA) after 6 months. S3 One Zone-IA is similar to S3 Standard-IA, but it stores data in a single Availability Zone. This means it has a lower availability and durability than S3 Standard-IA, and it is not resilient to the loss of data in a single Availability Zone1. Therefore, it does not provide high availability as required.
Option B is incorrect because it transfers objects to S3 Glacier Flexible Retrieval after 2 years. S3 Glacier Flexible Retrieval is a storage class that offers secure and durable storage for data that is accessed infrequently and can tolerate a retrieval time of minutes to hours. It is more expensive than S3 Glacier Deep Archive, and it is not suitable for data that is accessed only once or twice each year3. Therefore, it is not the most cost-effective option.
Option D is incorrect because it combines the errors of option A and B. It transitions objects to S3 One Zone-IA after 6 months, which does not provide high availability, and it transfers objects to S3 Glacier Flexible Retrieval after 2 years, which is not the most cost-effective option.
Reference:
1: Amazon S3 storage classes - Amazon Simple Storage Service
2: Amazon S3 Standard-Infrequent Access (S3 Standard-IA) - Amazon Simple Storage Service
3: Amazon S3 Glacier and S3 Glacier Deep Archive - Amazon Simple Storage Service
[4]: Expiring objects - Amazon Simple Storage Service
[5]: Managing your storage lifecycle - Amazon Simple Storage Service
[6]: Examples of S3 Lifecycle configuration - Amazon Simple Storage Service
[7]: Amazon S3 Lifecycle further optimizes storage cost savings with new features - What's New with AWS
質問 # 83
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?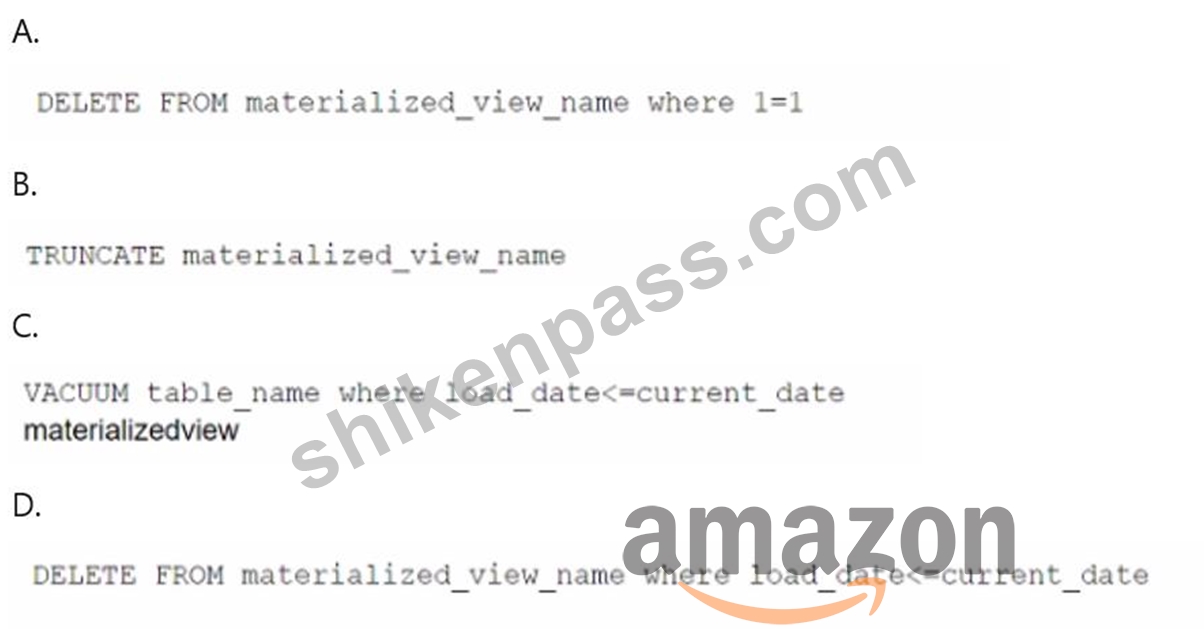
正解:C
解説:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use a DELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as 1=1. This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
Option A: DELETE FROM materialized_view_name WHERE 1=1;
This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
Reference:
Amazon Redshift Materialized Views Documentation
Deleting Data from Redshift
質問 # 84
A company implements a data mesh that has a central governance account. The company needs to catalog all data in the governance account. The governance account uses AWS Lake Formation to centrally share data and grant access permissions.
The company has created a new data product that includes a group of Amazon Redshift Serverless tables. A data engineer needs to share the data product with a marketing team. The marketing team must have access to only a subset of columns. The data engineer needs to share the same data product with a compliance team.
The compliance team must have access to a different subset of columns than the marketing team needs access to.
Which combination of steps should the data engineer take to meet these requirements? (Select TWO.)
正解:B、E
解説:
The company is using a data mesh architecture with AWS Lake Formation for governance and needs to share specific subsets of data with different teams (marketing and compliance) using Amazon Redshift Serverless.
Option A: Create views of the tables that need to be shared. Include only the required columns.Creating views in Amazon Redshift that include only the necessary columns allows for fine-grained access control. This method ensures that each team has access to only the data they are authorized to view.
Option E: Share the Amazon Redshift data share to the Amazon Redshift Serverless workgroup in the marketing team's account.Amazon Redshift data sharing enables live access to data across Redshift clusters or Serverless workgroups. By sharing data with specific workgroups, you can ensure that the marketing team and compliance team each access the relevant subset of data based on the views created.
Option B (creating a Redshift data share) is close but does not address the fine-grained column-level access.
Option C (creating a managed VPC endpoint) is unnecessary for sharing data with specific teams.
Option D (sharing with the Lake Formation catalog) is incorrect because Redshift data shares do not integrate directly with Lake Formation catalogs; they are specific to Redshift workgroups.
References:
Amazon Redshift Data Sharing
AWS Lake Formation Documentation
質問 # 85
A retail company is using an Amazon Redshift cluster to support real-time inventory management. The company has deployed an ML model on a real-time endpoint in Amazon SageMaker.
The company wants to make real-time inventory recommendations. The company also wants to make predictions about future inventory needs.
Which solutions will meet these requirements? (Select TWO.)
正解:B、D
解説:
The company needs to use machine learning models for real-time inventory recommendations and future inventory predictions while leveraging both Amazon Redshift and Amazon SageMaker.
Option A: Use Amazon Redshift ML to generate inventory recommendations.
Amazon Redshift ML allows you to build, train, and deploy machine learning models directly from Redshift using SQL statements. It integrates with SageMaker to train models and run inference. This feature is useful for generating inventory recommendations directly from the data stored in Redshift.
Option B: Use SQL to invoke a remote SageMaker endpoint for prediction.
You can use SQL in Redshift to call a SageMaker endpoint for real-time inference. By invoking a SageMaker endpoint from within Redshift, the company can get real-time predictions on inventory, allowing for integration between the data warehouse and the machine learning model hosted in SageMaker.
Option C (offline model training) and Option D (creating dashboards with SageMaker Autopilot) are not relevant to the real-time prediction and recommendation requirements.
Option E (archiving inventory reports in Redshift) is not related to making predictions or recommendations.
Reference:
Amazon Redshift ML Documentation
Invoking SageMaker Endpoints from SQL
質問 # 86
......
最高のData-Engineer-Associateテストトレントを提供する世界的なリーダーとして、私たちは大多数の消費者に包括的なサービスを提供し、統合サービスの構築に努めています。さらに、Data-Engineer-Associate認定トレーニングアプリケーションだけでなく、インタラクティブな共有およびアフターサービスでもブレークスルーを達成しました。実際のところ、当社では、すべてのクライアントの適切なソリューションの問題を考慮しています。ヘルプが必要な場合は、Data-Engineer-Associate試験トレントに関する問題に対処するための即時サポートを提供し、Data-Engineer-Associate試験の合格を支援します。
Data-Engineer-Associate模擬資料: https://www.shikenpass.com/Data-Engineer-Associate-shiken.html
BONUS!!! ShikenPASS Data-Engineer-Associateダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1j4qIhwDUWnoOnXLiBSJGsLL9-Gc6-STb