BTW, DOWNLOAD part of TestKingIT DEA-C02 dumps from Cloud Storage: https://drive.google.com/open?id=1wyPuTh7Iiw_XFxfsNDz59ts0R8bKUZIf
The punishment received by laziness is not only its own failure, but also the success of others. No one wants to be inferior to others. So, it's time to change yourself and make yourself better! Our DEA-C02 study materials want to give you some help on your dream journey. Believe me, the help you get is definitely what you need. On one hand, you can easily pass the DEA-C02 Exam and get the according DEA-C02 certification. On the other hand, you will be definitely encouraged to make better progress from now on.
| Section | Objectives |
|---|---|
| Data Engineering Fundamentals | - Data pipelines concepts and patterns - Snowflake architecture for data engineering |
| Data Ingestion and Integration | - Batch and streaming ingestion approaches - Snowpipe usage and automation - Staging data and loading mechanisms |
| Performance and Optimization | - Clustering and partition strategies - Warehouse sizing and scaling - Query optimization techniques |
| Data Transformation and Processing | - Handling semi-structured data (JSON, Avro, Parquet) - SQL-based transformations in Snowflake - Streams and Tasks for ELT pipelines |
| Security and Data Governance | - Role-based access control (RBAC) - Secure data sharing - Data masking and encryption |
>> DEA-C02 Test Engine Version <<
As a professional website, TestKingIT does not only guarantee you will receive a high score in your actual test, but also provide you with the most efficiency way to get success. Our DEA-C02 study torrent can help you enhance the knowledge and get further information about the DEA-C02 Actual Test. During the study and preparation for DEA-C02 actual test, you will be more confident, independent in your industry. Dear everyone, go and choose our DEA-C02 practice dumps as your preparation material.
NEW QUESTION # 11
You need to define a UDF in Snowflake that takes a date as input and returns the next business day (Monday-Friday). If the input date is a Friday, the UDF should return the following Monday. If the input date is a Saturday or Sunday, the function should return the following Monday as well. Which of the following UDF definitions correctly implements this logic?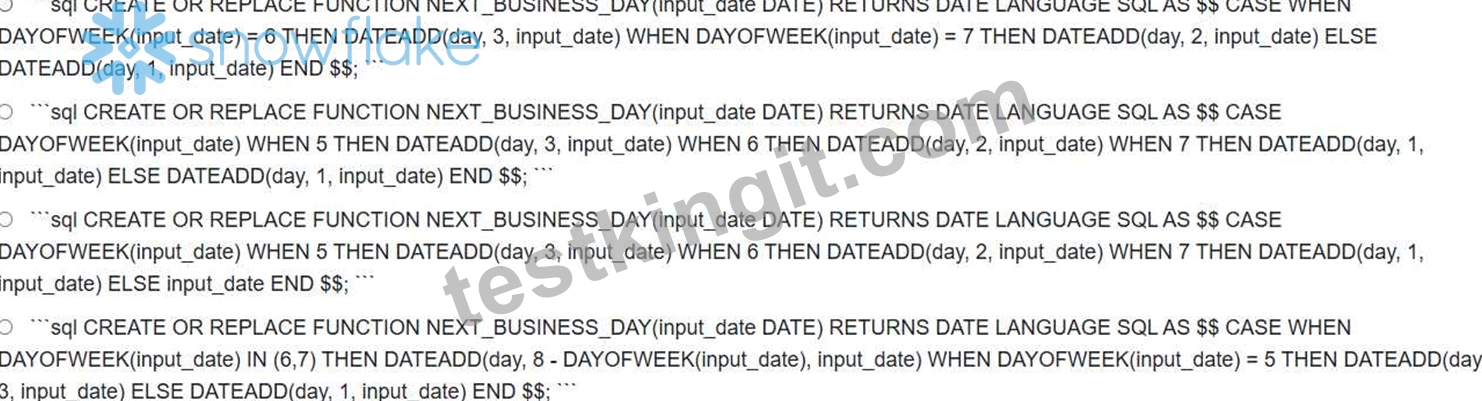
Answer: B
Explanation:
Option E correctly handles all the scenarios. It first checks if the day is a Friday (DAYOFWEEK = 5) and adds 3 days. Then, it checks if the day is a Saturday or Sunday (DAYOFWEEK IN (6, 7)) and calculates the correct number of days to add to reach Monday (8 - DAYOFWEEK(input_date)). If it's any other day, it simply returns the input date as the question only asks to move to the next business day and not the next date if its already a business day. Option A is wrong because it always adds 1 day to Monday-Thursday which does not meet the requirement, the same goes to option B as well. Option C is wrong because Monday - Thursday will return the same date. Option D doesn't return next business day, but the next day.
NEW QUESTION # 12
You're loading data into a Snowflake table using 'COPY INTO'. You notice that some rows are being rejected due to data validation errors (e.g., data type mismatch, uniqueness constraint violations). You want to implement a strategy to capture these rejected rows for further analysis and correction. Which of the following approaches offers the MOST efficient and reliable method for capturing and storing the rejected rows, minimizing performance impact during the data loading process? Assume no staging table exists before loading data to production table.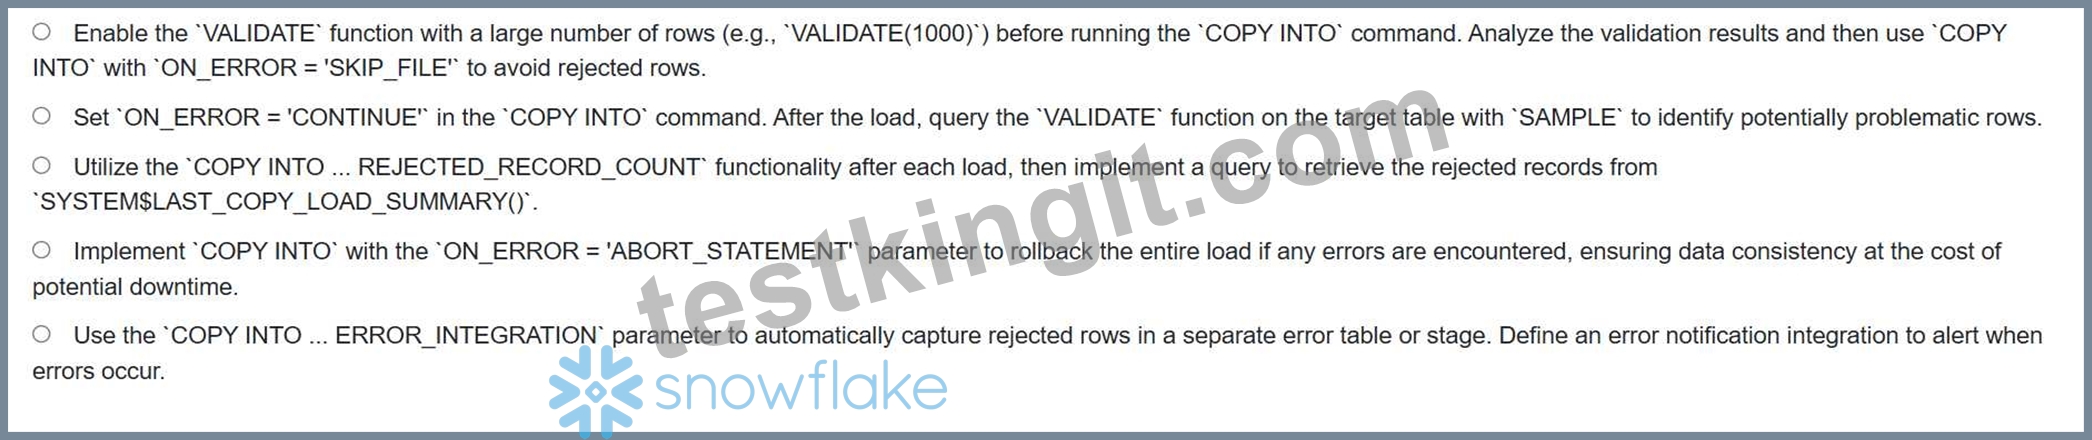
Answer: B
Explanation:
Option E, utilizing 'ERROR INTEGRATION', is the most efficient and reliable. It automatically captures rejected rows during the 'COPY INTO' process and stores them in a designated error table or stage, minimizing performance impact and providing a structured way to analyze and correct errors. Options A, B, C, and D have drawbacks. A requires pre-validation, adding overhead. B uses sampling, which might not identify all errors. C only provides a record count, not the actual rejected rows. D aborts the entire statement, impacting availability.
NEW QUESTION # 13
Which of the following statements are true regarding data masking policies in Snowflake? (Select all that apply)
Answer: A,C,D
Explanation:
A and D are correct. Masking policies can be applied to tables and views, and the function is essential for implementing role-based masking. B is incorrect because masking policies apply dynamically at query time and don't alter the underlying data. C is incorrect; different policies can be applied to different columns. E is correct, Data masking policies are also supported on external tables.
NEW QUESTION # 14
You're working on a data transformation pipeline in Snowflake. You need to create a SQL UDF called that accepts the following parameters: 'price' (NUMBER) (NUMBER) (BOOLEAN) The function should calculate the final price after applying the discount. If the customer , an additional 5% discount should be applied on top of the initial discount. Choose all the valid SQL UDF definitions that accurately implement the requirements. Only one Discount Percentage needs to apply to the base price.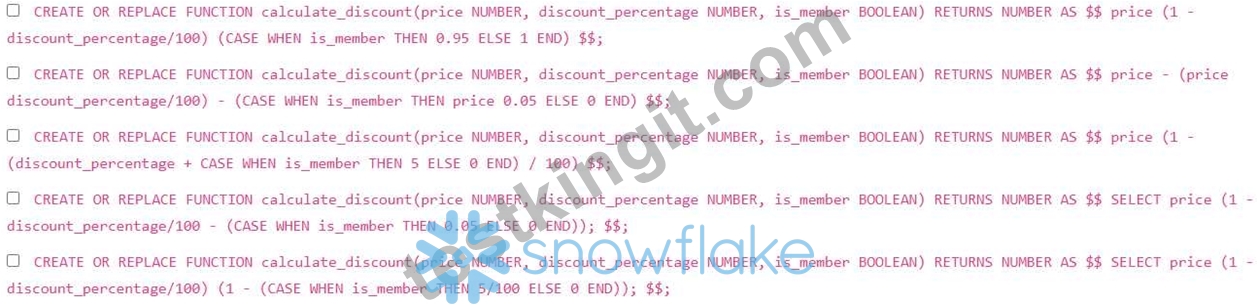
Answer: A,C,E
Explanation:
Options A, C and E are correct. Option A correctly calculates the discount by first applying the initial discount and then the additional member discount multiplicatively. Option C adds the member discount to the base discount and then applies it, which is mathematically correct. Option E follows the same as Option A but has more explicit calculations. Option B is incorrect because the additional 5% is calculated based on original price, not already discounted price. Option D is also wrong since the addition discount is already handled as one whole number. This tests understanding of conditional logic and discount calculations within SQL UDFs, as well as multiple ways to achieve the same correct outcome.
NEW QUESTION # 15
You have a Snowpark Python application that performs complex calculations on a large dataset stored in Snowflake. The application is currently running slowly. After profiling, you've identified that the UDFs you're using are the bottleneck. These UDFs perform custom data transformations using a third-party Python library which has a significant initialization overhead. Which of the following strategies would be MOST effective to optimize performance, minimizing both runtime and resource consumption?
Answer: D
Explanation:
Option C is the most effective. 'pandas_udf with 'vectorized=True' allows processing data in batches using pandas DataFrames, significantly reducing the overhead of invoking the UDF for each row. Pre-initializing the library within the UDF's closure avoids repeated initialization. Increasing warehouse size (A) might help but is not as targeted. UDF caching (B) only helps if the inputs are identical and doesn't address the initialization overhead. Rewriting in SQL (D) might not be feasible if the third-party library is essential. Converting to Java (E) could help, but optimizing the Python code first is generally a better starting point.
NEW QUESTION # 16
......
In order to help customers solve problems, our company always insist on putting them first and providing valued service. We deeply believe that our DEA-C02 question torrent will help you pass the exam and get your certification successfully in a short time. Maybe you cannot wait to understand our DEA-C02 Guide questions; we can promise that our products have a higher quality when compared with other study materials. At the moment you can free download the demo of our DEA-C02 guide torrents, and I can make a bet that you will be fond of our DEA-C02 exam questions if you understand it.
DEA-C02 Brain Exam: https://www.testkingit.com/Snowflake/latest-DEA-C02-exam-dumps.html
BTW, DOWNLOAD part of TestKingIT DEA-C02 dumps from Cloud Storage: https://drive.google.com/open?id=1wyPuTh7Iiw_XFxfsNDz59ts0R8bKUZIf