What's more, part of that GuideTorrent DAA-C01 dumps now are free: https://drive.google.com/open?id=1Vfm3UtSA9VnZ4Pu6L9EL79OC_t6AxtoS
Preparing for the DAA-C01 exam can be a daunting task, but with real DAA-C01 exam questions, it can be a lot easier. The importance of actual SnowPro Advanced: Data Analyst Certification Exam (DAA-C01) questions cannot be overemphasized. DAA-C01 Real Questions are crucial for passing the DAA-C01 exam. When candidates have access to the updated Snowflake DAA-C01 practice test questions, they are better prepared to succeed.
| Section | Objectives |
|---|---|
| Data Modeling and Performance Optimization | - Performance tuning
|
| Snowflake Architecture and Data Platform Fundamentals | - Data platform fundamentals
|
| Data Transformation and Analysis | - SQL-based transformations
|
| Security, Governance, and Data Sharing | - Data sharing and governance
|
| Data Loading and Unloading | - Data export
|
>> New DAA-C01 Braindumps Free <<
Our company is a professional certification exam materials provider, we have occupied in this field for over ten years, and we have rich experiences in offering exam materials. DAA-C01 exam materials are edited by professional experts, and they possess the skilled knowledge for the exam, therefore the quality can be guaranteed. In addition, we are pass guarantee and money guarantee for DAA-C01 Exam Materials, if you fail to pass the exam, we will give you refund. We provide you with free update for 365 days for you after purchasing, and the update version for DAA-C01 training materials will be sent to your email automatically.
NEW QUESTION # 50
You have a requirement to load semi-structured JSON data from an internal stage into a Snowflake table. The JSON data contains nested arrays and objects. You need to flatten specific elements from these nested structures into separate columns in the target table during the load process. Assuming the internal stage is already configured, which of the following 'COPY INTO' statement snippets would correctly extract and load the 'city' from the 'address' object within the JSON, and the first element (index 0) of the phoneNumbers' array into corresponding columns in the target table?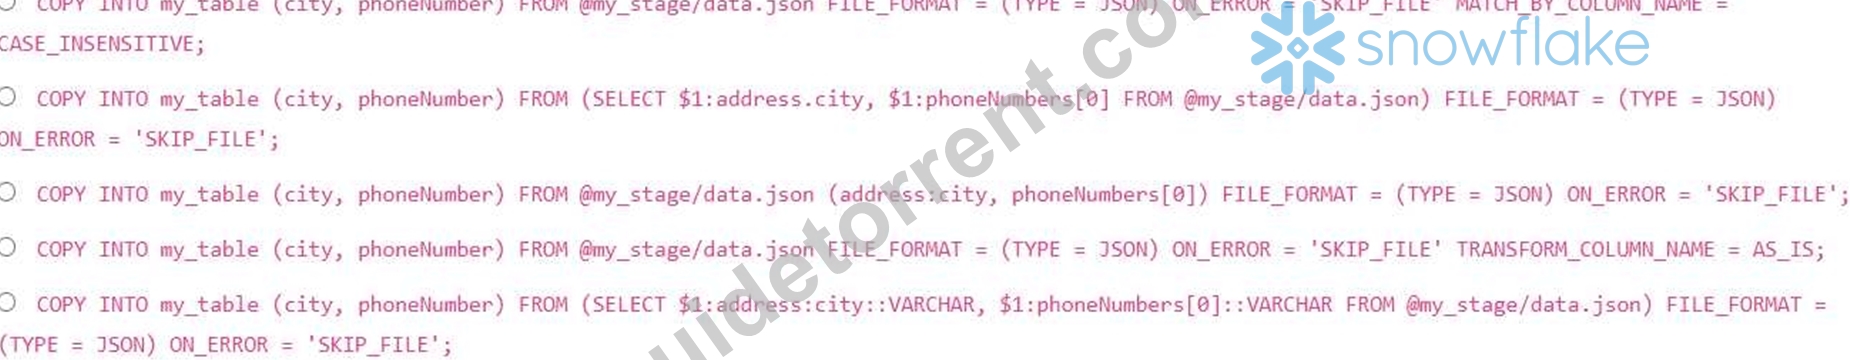
Answer: D
Explanation:
Option E is correct. It uses a SELECT statement within the 'COPY INTO' command to extract the desired nested elements. '$1 retrieves the 'city' value from the 'address' object and '$1 retrieves the first element of the 'phoneNumberS array. explicitly casts the extracted values to VARCHAR. Option B is similar, but misses the explicit cast to VARCHAR. Without the cast, Snowflake may infer a different data type, leading to errors during load. Option A will fail because it relies on column name matching, which won't work for nested JSON elements. Options C and D have incorrect syntax for extracting nested elements within the COPY INTO command.
NEW QUESTION # 51
You have been tasked with creating a reporting solution for a marketing campaign. The source data includes customer information (name, email, location), campaign details (campaign ID, name, start date, end date), and interaction data (customer ID, campaign ID, interaction type, timestamp). The business users want to analyze campaign performance based on customer segments, interaction types, and time periods. The data volume is expected to be moderately large (millions of records), and the reporting requirements are relatively stable. Which of the following data modeling and transformation strategies would be most efficient and maintainable?
Answer: C
Explanation:
Option B offers the most efficient and maintainable solution. A star schema provides a good balance between query performance and data maintainability. The fact table stores the interactions, while the dimension tables provide context for customers, campaigns, and time. Snowflake's clustering feature can be used to physically organize the data on disk based on common query patterns, further improving performance. A fully denormalized table (Option A) can lead to data redundancy and update anomalies. Option C makes reporting complex and inefficient. Option D adds complexity without significant performance benefits in this scenario. Option E is inefficient for this use case. Given that we expect stable reporting requirements and moderately large data, it is best to flatten the data using a well-defined data model.
NEW QUESTION # 52
Which approach is most suitable for making data-driven predictions?
Answer: C
NEW QUESTION # 53
A data analyst needs to forecast sales for the next quarter based on historical sales data'. The data is stored in a table named 'SALES DATA' with columns 'SALE DATE (DATE) and 'SALES_AMOUNT (NUMBER). The analyst wants to use the 'HOLT WINTERS function for forecasting, considering both trend and seasonality. However, the data contains some missing values for a few 'SALE DATE entries. Which of the following approaches is the MOST appropriate to handle missing data points while ensuring accurate forecasting with 'HOLT WINTERS in Snowflake?
Answer: A
Explanation:
HOLT_WINTERS function requires continuous data for time series analysis, and missing values will lead to inaccurate forecasts. Option E is the most appropriate because Interpolation method such as linear interpolation will give you more precise result. Other approaches like direct use or Exclusion will result in wrong forecasting results.
NEW QUESTION # 54
A table named STUDENT is created: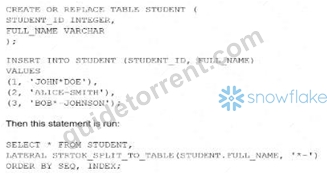
What will be the output?
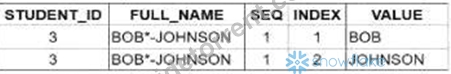
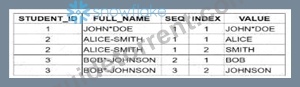
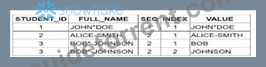
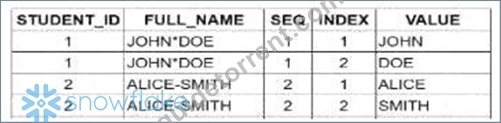
Answer: C
Explanation:
To determine the correct output, a Data Analyst must understand the behavior of the STRTOK_SPLIT_TO_TABLE table function and how it interacts with different delimiters.
1. Functionality of STRTOK_SPLIT_TO_TABLE:
The STRTOK_SPLIT_TO_TABLE function tokenizes a string based on a set of specified delimiters. Unlike simple SPLIT functions that often look for a literal string as a delimiter, STRTOK treats the delimiter string as a set of individual characters. Any character present in the delimiter string will trigger a split. Crucially, it skips empty tokens-if multiple delimiters appear consecutively, it does not produce a row for the space between them.
2. Evaluating the Data and Delimiters ('*-'):
* 'JOHN*DOE': The * character is a delimiter. This results in two tokens: JOHN and DOE.
* 'ALICE-SMITH': The - character is a delimiter. This results in two tokens: ALICE and SMITH.
* 'BOB*-JOHNSON': Both * and - are delimiters. Because they appear consecutively (*-), the function splits at each but ignores the empty space between them. This results in two tokens: BOB and JOHNSON.
3. Analyzing the Resulting Rows:
The LATERAL join produces a row for every token generated. The columns SEQ (identifying the source row sequence) and INDEX (position of the token within that sequence) are used for sorting.
* Student 1: 2 tokens (JOHN, DOE) $\rightarrow$ 2 rows.
* Student 2: 2 tokens (ALICE, SMITH) $\rightarrow$ 2 rows.
* Student 3: 2 tokens (BOB, JOHNSON) $\rightarrow$ 2 rows.
Evaluating the Options (image_8233d8.png):
* Option A incorrectly only shows results for Student 3.
* Option C incorrectly implies Student 1 and 2 produce three tokens each.
* Option D incorrectly interprets the consecutive delimiters in Student 3's name as creating a different sequence count.
* Option B is the 100% correct result set. It accurately shows that each student's name is split into exactly two parts, properly handling the varying delimiters and the consecutive characters in the third record.
NEW QUESTION # 55
......
Snowflake DAA-C01 study material of "GuideTorrent" is available in three different formats: PDF, desktop-based practice test software, and a browser-based practice DAA-C01 exam questions. SnowPro Advanced: Data Analyst Certification Exam (DAA-C01) practice tests are a great way to gauge your progress and identify weak areas for further study. Check out features of these formats.
DAA-C01 Flexible Testing Engine: https://www.guidetorrent.com/DAA-C01-pdf-free-download.html
BONUS!!! Download part of GuideTorrent DAA-C01 dumps for free: https://drive.google.com/open?id=1Vfm3UtSA9VnZ4Pu6L9EL79OC_t6AxtoS