誰想要獲得Microsoft DP-800認證?我們所知道的該考試是非常具有挑戰性的,隨著最新的DP-800考古題上線,您將更方便快捷的獲得認證。如果您不相信我們,可以先下載我們的免費PDF試用版的DP-800問題和答案,我們將保證您100%成功。對于擁有高品質的Microsoft DP-800題庫是絕對值得信賴的,為了配合當真正的考試,我們的專家在不斷的更新我們的問題和答案。如果使用我們的DP-800考古題沒有通過考試,我們將無條件的退款。
| 主題 | 簡介 |
|---|---|
| 主題 1 |
|
| 主題 2 |
|
| 主題 3 |
|
在如今競爭激烈的IT行業中,通過了Microsoft DP-800 認證考試是有很多好處的。因為有了Microsoft DP-800 認證證書就可以提高收入。拿到了Microsoft DP-800 認證證書的人往往要比沒有證書的同行工資高很多。可是Microsoft DP-800 認證考試不是很容易通過的,所以NewDumps是一個可以幫助你增長收入的網站.
問題 #43
Your development team uses GitHub Copilot Chat in Microsoft SQL Server Management Studio (SSMS) to generate and run Transact-SQL queries against an Azure SQL database named DB1 DB1 contains tables that store sensitive customer data.
You need to ensure that any Transact SQL queries that run from GitHub Copilot Chat In SSMS are restricted by the same permissions as the developer ' s database login.
What prevents the GitHub Copilot Chat-run queries from accessing data beyond the developer ' s access?
答案:A
解題說明:
The correct answer is B . Microsoft's SSMS Copilot documentation states that queries from Copilot in SSMS are executed under the context of the user's login and permissions , and that there are no separate permissions for Copilot in SSMS . That means Copilot-run Transact-SQL cannot access more data than the developer's own database principal is already allowed to access.
That is why the other options are incorrect:
* A is wrong because Copilot does not use a separate read-only sandbox in place of database permissions.
* C is wrong because enforcement is not a client-side filtering trick; it is enforced by the database security context of the current login.
* D is wrong because Copilot does not apply a different RLS model from the developer; it simply runs under the same login context.
So the security boundary is the developer's existing database identity and permissions .
問題 #44
You need to recommend a solution to lesolve the slow dashboard query issue. What should you recommend?
答案:A
解題說明:
The best recommendation is B because the slow query filters on FleetId and returns LastUpdatedUtc , EngineStatus , and BatteryHealth . A nonclustered index with FleetId as the key column allows the optimizer to perform an index seek instead of a clustered index scan, and including the other selected columns makes the index covering , which reduces extra lookups and I/O. Microsoft's SQL Server indexing guidance states that a nonclustered index with included columns can significantly improve performance when all query columns are available in the index, because the optimizer can satisfy the query directly from the index.
The query is:
SELECT VehicleId, LastUpdatedUtc, EngineStatus, BatteryHealth
FROM dbo.VehicleHealthSummary
WHERE FleetId = @FleetId
ORDER BY LastUpdatedUtc DESC;
Among the given choices, FleetId is the most important search argument because it appears in the WHERE predicate. Microsoft's index design guidance recommends putting columns used for searching in the key and using nonkey included columns to cover the rest of the query efficiently.
Why the other options are weaker:
* A is not appropriate because changing the clustered index to LastUpdatedUtc would not target the main filter predicate on FleetId, and a table can have only one clustered index.
* C makes LastUpdatedUtc the key, which is poor for a query whose primary filter is FleetId.
* D is not the right answer here because the query requirement does not specify only recent rows, and filtered indexes are meant for a well-defined subset; this option also uses a time-based expression that is not aligned to the stated query pattern.
Strictly speaking, the most optimal design for both filtering and ordering would usually be a composite key like (FleetId, LastUpdatedUtc), but since that is not one of the available options, B is the correct exam answer.
問題 #45
Case Study 2 - Fabrikam
Existing Environment
Azure Environment
Fabrikam has a single Azure subscription in the East US 2 Azure region. The subscription contains an Azure SQL database named DB1. DB1 contains the following tables:
* Patients
* Employees
* Procedures
* Transactions
* UsefulPrompts
* ProcedureDocuments
You store a column master key as a secret in Azure Key Vault.
You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Problem Statements
Users report that after executing a long-running stored procedure named sp_UpdateProcedureForPatient, updates to the underlying data are sometimes inconsistent.
Requirements
Planned Changes
Fabrikam plans to manage all changes to Azure SQL Database objects by using source control in GitHub. Every pull request submitted to production will be validated before it can be merged.
Deployments must use the Release configuration.
Security Requirements
Fabrikam identifies the following security requirements:
* The TransactionProcessing application must use a passwordless connection to DB1.
* The Employees table contains two columns named TaxID and Salary that must be encrypted at rest.
* Auditors must have a tamper-evident history of transactions with cryptographic proof of changes to the employee data.
Database Performance Requirements
Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
AI Search, Embeddings, and Vector Indexing
Fabrikam identifies the following AI-related requirements:
* Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
* Users must be able to query the data in DB1 by using prompts in Copilot in Microsoft Fabric.
* The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
Development Requirements
Fabrikam identifies the following development requirements:
* Provide the functionality to retrieve all the transactions of a given patient between two dates, showing a running total.
* Expose a Data API builder (DAB) configuration file to enable Azure services to perform the following operations over a REST API:
- Read data from the procedures table without authentication.
- Read and insert data into the Transactions table once authenticated.
- Execute the sp_UpdateProcedurePatient stored procedure.
* Provide the functionality to retrieve a list of the names of patients who underwent medical procedures during the last 30 days.
* Information for each medical procedure will be stored in a table. The table will be used with a large language model (LLM) for user querying and will have the following structure.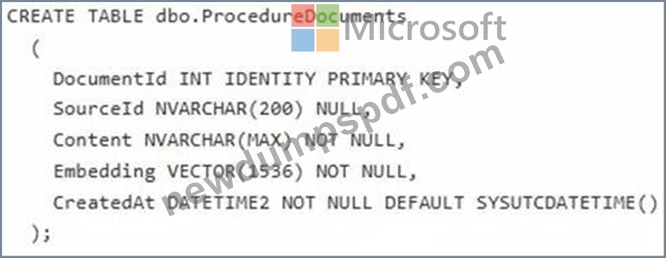
DAB
You create a DAB configuration file that meets the development requirements for DB1 and includes the following entities.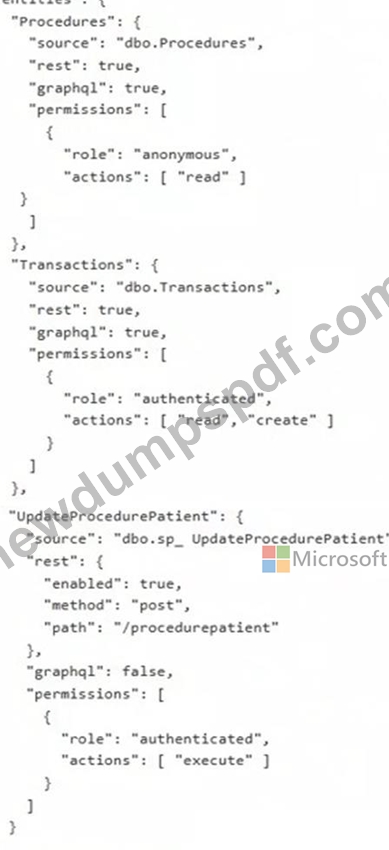
You implement ProcedureDocuments to support the planned changes.
When users consume data through the Retrieval Augmented Generation (RAG) pattern, they experience data retrieval delays.
You need to improve the data retrieval performance and reduce the number of tokens per retrieval.
What should you implement?
答案:D
解題說明:
Scenario: Fabrikam identifies the following AI-related requirements: Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
To remedy data retrieval delays in a Retrieval Augmented Generation (RAG) pattern using Reciprocal Rank Fusion (RRF) on an Azure SQL Database table, you should use embeddings.
In a RAG architecture, retrieval delays often stem from inefficient or computationally heavy search processes. While RRF is excellent for merging results from multiple sources (like combining keyword and vector searches), the core of the speed problem typically lies in how the initial data is indexed and retrieved.
Role of Embeddings
Vector Search Acceleration: Embeddings convert text into high-dimensional vectors. Azure SQL Database can perform similarity searches on these vectors much faster than complex semantic text matching.
Hybrid Search Synergy: RRF is most effective when it fuses results from a keyword search (fast) and a vector search (powered by embeddings). Using embeddings ensures that the "semantic" side of the retrieval is streamlined.
Pre-computation: Since embeddings are generated once during ingestion, the retrieval phase only requires a distance calculation (e.g., Cosine Similarity), which is significantly faster than real- time natural language parsing during each query.
Reference:
https://pratikbarjatya.medium.com/unlocking-the-power-of-language-with-retrieval-augmented- generation-rag-14123cc275e6
問題 #46
You have a GitHub Codespaces environment that has GitHub Copilot Chat installed and is connected to a SQL database in Microsoft Fabric named DB1. DB1 contains tables named Sales.Orders and Sales.Customers.
You use GitHub Copilot Chat in the context of DB1.
A company policy prohibits sharing customer Personally Identifiable Information (PII), secrets, and query result sets with any AI service.
You need to use GitHub Copilot Chat to write and review Transact-SQL code for a new stored procedure that will join Sales.Orders to Sales.Customers and return customer names and email addresses. The solution must NOT share the actual data in the tables with GitHub Copilot Chat.
What should you do?
答案:D
解題說明:
To use GitHub Copilot Chat effectively in this environment without exposing sensitive data, you should focus your prompts entirely on the schema and logic rather than the data itself.
Since Copilot Chat can "see" your open files, the best approach is to provide the table structures as DDL (Data Definition Language) statements or a simplified description.
Steps to generate the stored procedure:
Define the Schema: Open a new SQL file in your Codespace. Paste the CREATE TABLE scripts (without any data) for your two tables.
Prompt Copilot: Use the Chat view to request the procedure.
Example Prompt: "Based on the table definitions in my open file, write a T-SQL stored procedure that joins TableA and TableB on [Join Column]. Include logic to filter by [Parameter] and ensure no PII columns are included in the SELECT statement." Review for PII/Secrets: Before executing, manually verify that the generated code doesn't include hardcoded secrets or call PII columns you intended to omit.
Security Check: Because you are in a Codespace, ensure your .env files or connection strings are in your .gitignore so they aren't indexed by Copilot.
Reference:
https://github.com/orgs/community/discussions/141924
問題 #47
You have an Azure SQL database that has Query Store enabled
Query Performance Insight shows that one stored procedure has the longest runtime. The procedure runs the following parameterized query.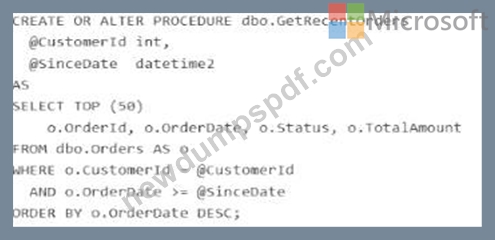
The dbo.orders table has approximately 120 million rows. Customer-id is highly selective, and orderOate is used for range filtering and sorting.
Vou have the following indexes:
* Clustered index: PK_Orders on (Orderld)
* Nonclustered index: lx_0rders_order-Date on (OrderDate) with no included columns An actual execution plan captured from Query Store for slow runs shows the following:
* An index seek on ixordersorderDate followed by a Key Lookup (Clustered) on PKOrders for customerid, status, and TotalAnount
* A sort operator before top (50), because the results are ordered by orderDate DESC For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.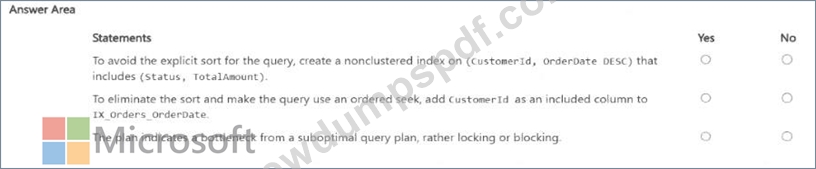
答案:
解題說明: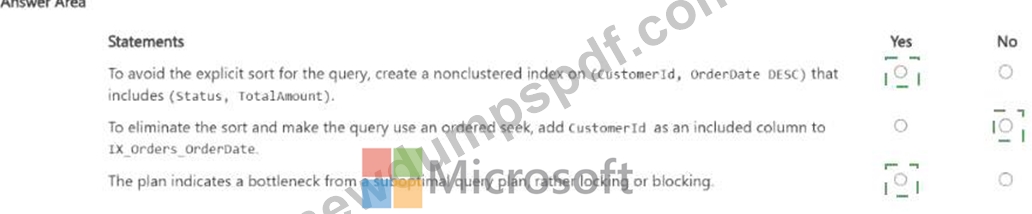
Explanation: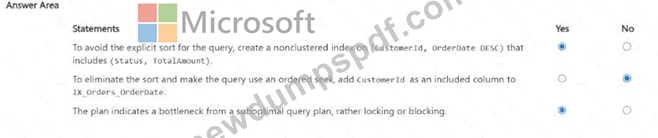
The first statement is Yes . The query filters on CustomerId, applies a range predicate on OrderDate, and sorts by OrderDate DESC. Microsoft's index design guidance recommends putting equality predicates first in the key, followed by columns used for ordering/range access, because the order of key columns determines seek and sort support. A nonclustered index on (CustomerId, OrderDate DESC) can support an ordered seek for this query and avoid the explicit sort. Including Status and TotalAmount helps cover the query, and OrderId is already available because the clustered key is stored with nonclustered index rows.
The second statement is No . Adding CustomerId as an included column to IX_Orders_OrderDate does not make it part of the index's navigational structure. Microsoft states that included columns are nonkey columns used to cover queries; they do not provide the seek and ordering characteristics that key columns do. So an index keyed only on OrderDate still is not the right ordered access path for WHERE CustomerId =
@CustomerId ... ORDER BY OrderDate DESC.
The third statement is Yes . The described actual plan shows an index seek on the wrong access path for the workload, followed by clustered key lookups and an explicit sort before TOP (50). That is characteristic of a suboptimal query/index plan . Query Store and Query Performance Insight are designed to surface plan- related performance regressions, while locking/blocking problems are typically identified through waits
/DMVs and blocking-session indicators, not from a plan shape like seek + lookup + sort alone.
問題 #48
......
想獲得Microsoft DP-800認證,就來NewDumps網站!為您提供最好的學習資料,讓您不僅可以通過DP-800考試,還可以在短時間內獲得良好的成績。我們已經幫助很多的考生順利順利通過DP-800考試,獲取證書,這是一個難得的機會。現在,購買Microsoft DP-800題庫之后,您的郵箱會收到我們的郵件,您可以及時下載您購買的DP-800題庫并訪問,這樣可以全面地了解詳細的考試試題以及答案。
DP-800題庫最新資訊: https://www.newdumpspdf.com/DP-800-exam-new-dumps.html