P.S. Free 2026 Google Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by DumpStillValid: https://drive.google.com/open?id=1Eo5HNeJs3PYEULY2KIKz3PFcJF6QVz9_
If you have some doubts about the accuracy of Professional-Machine-Learning-Engineer top questions. There are free demo of latest exam cram for you to download. Besides, you can free updating Google braindumps torrent one-year after you purchase. We adhere to the principle of No Help, Full Refund, if you failed the exam with our Professional-Machine-Learning-Engineer Valid Dumps, we will full refund you.
| Certification Vendor: | Google Cloud |
|---|---|
| Exam Name: | Google Cloud Certified - Professional Machine Learning Engineer |
| Exam Number: | Professional-Machine-Learning-Engineer |
| Real Exam Qty: | 50-60 |
| Passing Score: | Not publicly disclosed (Pass/Fail) |
| Related Certifications: | Google Cloud Certified - Professional Data Engineer |
| Available Languages: | English, Japanese |
| Exam Duration: | 120 minutes |
| Certificate Validity Period: | 2 years |
| Exam Format: | Multiple select, Multiple choice |
| Exam Price: | $200 USD |
| Sample Questions: | Google Professional-Machine-Learning-Engineer Sample Questions |
| Exam Way: | Online (proctored) or Test center (Kryterion) |
| Pre Condition: | Recommended 3+ years of industry experience with ML models and 1+ year of experience using Google Cloud. |
| Official Syllabus URL: | https://cloud.google.com/learn/certification/machine-learning-engineer |
>> Dumps Google Professional-Machine-Learning-Engineer Free Download <<
During the process of using our Professional-Machine-Learning-Engineer study materials, you focus yourself on the exam bank within the given time, and we will refer to the real exam time to set your Professional-Machine-Learning-Engineer practice time, which will make you feel the actual exam environment and build up confidence. Not only that you can get to know the real questins and answers of the Professional-Machine-Learning-Engineer Exam, but also you can adjust yourself to the real pace of the Professional-Machine-Learning-Engineer exam.
Google Professional Machine Learning Engineer Certification Exam is a highly sought-after credential for individuals seeking to demonstrate their proficiency in designing and implementing machine learning models and systems on the Google Cloud Platform. Google Professional Machine Learning Engineer certification is designed for professionals with a solid foundation in machine learning concepts and practical experience in building and deploying machine learning models.
NEW QUESTION # 90
Your data science team has requested a system that supports scheduled model retraining, Docker containers, and a service that supports autoscaling and monitoring for online prediction requests. Which platform components should you choose for this system?
Answer: B
Explanation:
https://cloud.google.com/vertex-ai/docs/training/containers-overview
NEW QUESTION # 91
You are an ML engineer in the contact center of a large enterprise. You need to build a sentiment analysis tool that predicts customer sentiment from recorded phone conversations. You need to identify the best approach to building a model while ensuring that the gender, age, and cultural differences of the customers who called the contact center do not impact any stage of the model development pipeline and results. What should you do?
Answer: B
Explanation:
To ensure that gender, age, and cultural differences of the customers who called the contact center do not impact any stage of the model development pipeline and results, it is important to focus on the meaning and context of the conversation, rather than the characteristics of the speaker.
Converting the speech to text and then using syntactical analysis to extract sentiment will allow you to focus on the meaning and context of the conversation, rather than characteristics of the speaker. This approach will also give you more data to work with, as you can analyze the entire conversation, rather than just the voice recordings.
NEW QUESTION # 92
Your organization's call center has asked you to develop a model that analyzes customer sentiments in each call. The call center receives over one million calls daily, and data is stored in Cloud Storage. The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. You need to select components for data processing and for analytics. How should the data pipeline be designed?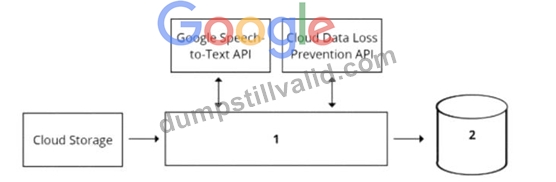
Answer: B
Explanation:
A data pipeline is a set of steps or processes that move data from one or more sources to one or more destinations, usually for the purpose of analysis, transformation, or storage. A data pipeline can be designed using various components, such as data sources, data processing tools, data storage systems, and data analytics tools1 To design a data pipeline for analyzing customer sentiments in each call, one should consider the following requirements and constraints:
* The call center receives over one million calls daily, and data is stored in Cloud Storage. This implies that the data is large, unstructured, and distributed, and requires a scalable and efficient data processing tool that can handle various types of data formats, such as audio, text, or image.
* The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. This implies that the data is sensitive and subject to data privacy and compliance regulations, and requires a secure and reliable data storage system that can enforce data encryption, access control, and regional policies.
* The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. This implies that the data analytics tool is external and independent of the data pipeline, and requires a standard and compatible data interface that can support SQL queries and operations.
One of the best options for selecting components for data processing and for analytics is to use Dataflow for data processing and BigQuery for analytics. Dataflow is a fully managed service for executing Apache Beam pipelines for data processing, such as batch or stream processing, extract-transform-load (ETL), or data integration. BigQuery is a serverless, scalable, and cost-effective data warehouse that allows you to run fast and complex queries on large-scale data23 Using Dataflow and BigQuery has several advantages for this use case:
* Dataflow can process large and unstructured data from Cloud Storage in a parallel and distributed manner, and apply various transformations, such as converting audio to text, extracting sentiment scores, or anonymizing PII. Dataflow can also handle both batch and stream processing, which can enable real-time or near-real-time analysis of the call data.
* BigQuery can store and analyze the processed data from Dataflow in a secure and reliable way, and enforce data encryption, access control, and regional policies. BigQuery can also support SQL ANSI-2011 compliant interface, which can enable the data science team to use their third-party tool for visualization and access. BigQuery can also integrate with various Google Cloud services and tools, such as AI Platform, Data Studio, or Looker.
* Dataflow and BigQuery can work seamlessly together, as they are both part of the Google Cloud ecosystem, and support various data formats, such as CSV, JSON, Avro, or Parquet. Dataflow and BigQuery can also leverage the benefits of Google Cloud infrastructure, such as scalability, performance, and cost-effectiveness.
The other options are not as suitable or feasible. Using Pub/Sub for data processing and Datastore for analytics is not ideal, as Pub/Sub is mainly designed for event-driven and asynchronous messaging, not data processing, and Datastore is mainly designed for low-latency and high-throughput key-value operations, not analytics.
Using Cloud Function for data processing and Cloud SQL for analytics is not optimal, as Cloud Function has limitations on the memory, CPU, and execution time, and does not support complex data processing, and Cloud SQL is a relational database service that may not scale well for large-scale data. Using Cloud Composer for data processing and Cloud SQL for analytics is not relevant, as Cloud Composer is mainly designed for orchestrating complex workflows across multiple systems, not data processing, and Cloud SQL is a relational database service that may not scale well for large-scale data.
References: 1: Data pipeline 2: Dataflow overview 3: BigQuery overview : [Dataflow documentation] :
[BigQuery documentation]
NEW QUESTION # 93
You work for a retail company. You have been tasked with building a model to determine the probability of churn for each customer. You need the predictions to be interpretable so the results can be used to develop marketing campaigns that target at-risk customers. What should you do?
Answer: A
NEW QUESTION # 94
Your team has been tasked with creating an ML solution in Google Cloud to classify support requests for one of your platforms. You analyzed the requirements and decided to use TensorFlow to build the classifier so that you have full control of the model's code, serving, and deployment. You will use Kubeflow pipelines for the ML platform. To save time, you want to build on existing resources and use managed services instead of building a completely new model. How should you build the classifier?
Answer: B
Explanation:
Transfer learning is a technique that leverages the knowledge and weights of a pre-trained model and adapts them to a new task or domain1. Transfer learning can save time and resources by avoiding training a model from scratch, and can also improve the performance and generalization of the model by using a larger and more diverse dataset2. AI Platform provides several established text classification models that can be used for transfer learning, such as BERT, ALBERT, or XLNet3. These models are based on state-of-the-art natural language processing techniques and can handle various text classification tasks, such as sentiment analysis, topic classification, or spam detection4. By using one of these models on AI Platform, you can customize the model's code, serving, and deployment, and use Kubeflow pipelines for the ML platform. Therefore, using an established text classification model on AI Platform to perform transfer learning is the best option for this use case.
Reference:
Transfer Learning - Machine Learning's Next Frontier
A Comprehensive Hands-on Guide to Transfer Learning with Real-World Applications in Deep Learning Text classification models Text Classification with Pre-trained Models in TensorFlow
NEW QUESTION # 95
......
Professional-Machine-Learning-Engineer Reliable Exam Price: https://www.dumpstillvalid.com/Professional-Machine-Learning-Engineer-prep4sure-review.html
What's more, part of that DumpStillValid Professional-Machine-Learning-Engineer dumps now are free: https://drive.google.com/open?id=1Eo5HNeJs3PYEULY2KIKz3PFcJF6QVz9_