
BTW, DOWNLOAD part of Itcerttest Data-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=16hDB0krlKDgC6pkNDaVAZFz5e88o0f33
Web-based AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) practice exam is a convenient format to evaluate and improve preparation for the exam. It is a Data-Engineer-Associate browser-based application, which means you can access it from any operating system with an internet connection and a web browser. Unlike the desktop-based exam simulation software, the AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) browser-based practice test requires no plugins and software installation. It makes the Amazon Data-Engineer-Associate online practice exam a perfect tool for those who do not want to go through complicated software installation on their device.
| Section | Weight | Objectives |
|---|---|---|
| Data Operations and Support | 22% | - Monitor and troubleshoot data pipelines
- Automate operational tasks - Ensure reliability and scalability |
| Data Store Management | 26% | - Design and implement data storage solutions
- Manage data lifecycle and storage tiers |
| Data Security and Governance | 18% | - Enforce compliance and data governance
- Protect sensitive data |
| Data Ingestion and Transformation | 34% | - Ingest data from various sources
|
>> Data-Engineer-Associate Test Labs <<
At the Itcerttest offer students Amazon Data-Engineer-Associate practice test questions, and 24/7 support to ensure they do comprehensive preparation for the AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) exam. Itcerttest AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) practice test material covers all the key topics and areas of knowledge necessary to master the Amazon Certification Exam.
NEW QUESTION # 144
A healthcare company uses Amazon Kinesis Data Streams to stream real-time health data from wearable devices, hospital equipment, and patient records.
A data engineer needs to find a solution to process the streaming data. The data engineer needs to store the data in an Amazon Redshift Serverless warehouse. The solution must support near real-time analytics of the streaming data and the previous day's data.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: C
Explanation:
The streaming ingestion feature of Amazon Redshift enables you to ingest data from streaming sources, such as Amazon Kinesis Data Streams, into Amazon Redshift tables in near real-time. You can use the streaming ingestion feature to process the streaming data from the wearable devices, hospital equipment, and patient records. The streaming ingestion feature also supports incremental updates, which means you can append new data or update existing data in the Amazon Redshift tables. This way, you can store the data in an Amazon Redshift Serverless warehouse and support near real-time analytics of the streaming data and the previous day's data. This solution meets the requirements with the least operational overhead, as it does not require any additional services or components to ingest and process the streaming data. The other options are either not feasible or not optimal. Loading data into Amazon Kinesis Data Firehose and then into Amazon Redshift (option A) would introduce additional latency and cost, as well as require additional configuration and management. Loading data into Amazon S3 and then using the COPY command to load the data into Amazon Redshift (option C) would also introduce additional latency and cost, as well as require additional storage space and ETL logic. Using the Amazon Aurora zero-ETL integration with Amazon Redshift (option D) would not work, as it requires the data to be stored in Amazon Aurora first, which is not the case for the streaming data from the healthcare company. References:
Using streaming ingestion with Amazon Redshift
AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide, Chapter 3: Data Ingestion and Transformation, Section 3.5: Amazon Redshift Streaming Ingestion
NEW QUESTION # 145
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?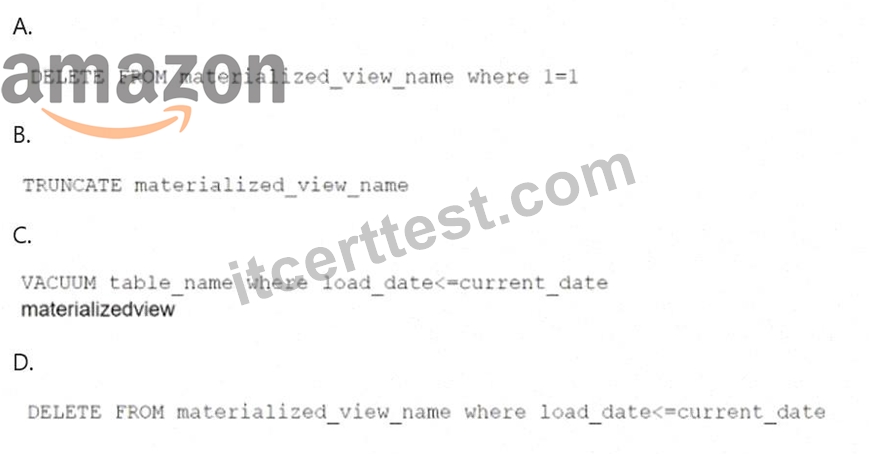
Answer: B
Explanation:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use a DELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as 1=1. This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
* Option A: DELETE FROM materialized_view_name WHERE 1=1;This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
References:
Amazon Redshift Materialized Views Documentation
Deleting Data from Redshift
NEW QUESTION # 146
A sales company uses AWS Glue ETL to collect, process, and ingest data into an Amazon S3 bucket. The AWS Glue pipeline creates a new file in the S3 bucket every hour. File sizes vary from 200 KB to 300 KB.
The company wants to build a sales prediction model by using data from the previous 5 years. The historic data includes 44,000 files.
The company builds a second AWS Glue ETL pipeline by using the smallest worker type. The second pipeline retrieves the historic files from the S3 bucket and processes the files for downstream analysis. The company notices significant performance issues with the second ETL pipeline.
The company needs to improve the performance of the second pipeline.
Which solution will meet this requirement MOST cost-effectively?
Answer: C
Explanation:
When processingmany small files, the overhead of managing partitions can degrade performance. Rather than scaling workers manually, enablingAWS Glue auto scalingdynamically adjusts worker count based on resource requirements, which iscost-effectiveand addresses the performance concern.
"AWS Glue auto scaling automatically adds or removes workers based on the workload, which is efficient for handling performance bottlenecks when working with many small files."
-Ace the AWS Certified Data Engineer - Associate Certification - version 2 - apple.pdf Manually scaling up workers or increasing their size (A, B) can be more expensive and less adaptive.
NEW QUESTION # 147
A company is planning to use a provisioned Amazon EMR cluster that runs Apache Spark jobs to perform big data analysis. The company requires high reliability. A big data team must follow best practices for running cost-optimized and long-running workloads on Amazon EMR. The team must find a solution that will maintain the company's current level of performance.
Which combination of resources will meet these requirements MOST cost-effectively? (Choose two.)
Answer: B,D
Explanation:
The best combination of resources to meet the requirements of high reliability, cost-optimization, and performance for running Apache Spark jobs on Amazon EMR is to use Amazon S3 as a persistent data store and Graviton instances for core nodes and task nodes.
Amazon S3 is a highly durable, scalable, and secure object storage service that can store any amount of data for a variety of use cases, including big data analytics1. Amazon S3 is a better choice than HDFS as a persistent data store for Amazon EMR, as it decouples the storage from the compute layer, allowing for more flexibility and cost-efficiency. Amazon S3 also supports data encryption, versioning, lifecycle management, and cross-region replication1. Amazon EMR integrates seamlessly with Amazon S3, using EMR File System (EMRFS) to access data stored in Amazon S3 buckets2. EMRFS also supports consistent view, which enables Amazon EMR to provide read-after-write consistency for Amazon S3 objects that are accessed through EMRFS2.
Graviton instances are powered by Arm-based AWS Graviton2 processors that deliver up to 40% better price performance over comparable current generation x86-based instances3. Graviton instances are ideal for running workloads that are CPU-bound, memory-bound, or network-bound, such as big data analytics, web servers, and open-source databases3. Graviton instances are compatible with Amazon EMR, and can be used for both core nodes and task nodes. Core nodes are responsible for running the data processing frameworks, such as Apache Spark, and storing data in HDFS or the local file system. Task nodes are optional nodes that can be added to a cluster to increase the processing power and throughput. By using Graviton instances for both core nodes and task nodes, you can achieve higher performance and lower cost than using x86-based instances.
Using Spot Instances for all primary nodes is not a good option, as it can compromise the reliability and availability of the cluster. Spot Instances are spare EC2 instances that are available at up to 90% discount compared to On-Demand prices, but they can be interrupted by EC2 with a two-minute notice when EC2 needs the capacity back. Primary nodes are the nodes that run the cluster software, such as Hadoop, Spark, Hive, and Hue, and are essential for the cluster operation. If a primary node is interrupted by EC2, the cluster will fail or become unstable. Therefore, it is recommended to use On-Demand Instances or Reserved Instances for primary nodes, and use Spot Instances only for task nodes that can tolerate interruptions. Reference:
Amazon S3 - Cloud Object Storage
EMR File System (EMRFS)
AWS Graviton2 Processor-Powered Amazon EC2 Instances
[Plan and Configure EC2 Instances]
[Amazon EC2 Spot Instances]
[Best Practices for Amazon EMR]
NEW QUESTION # 148
A data engineer needs to query data from multiple sources to generate an annual report. The analytics team uses Amazon Redshift for analysis. The data engineer needs to integrate Amazon Redshift data with 10 years of historical data from Amazon RDS for PostgreSQL and RDS for MySQL. All the databases are in the same VPC. The data engineer needs a solution that provides seamless data integration with Amazon Redshift.
Which solution will meet these requirements in the MOST cost-effective way?
Answer: B
Explanation:
Option A is the most cost-effective because it enables seamless integration by allowing analysts to access and join external relational data directly from within Amazon Redshift for reporting, without building and operating a separate ingestion pipeline for a one-time (annual) workload. The study material frames Amazon Redshift as the centralized analytics store for complex queries and reporting, making it the natural place to perform the final transformations and analysis.
The alternatives introduce extra operational steps and recurring costs. Option B requires exporting large historical datasets to S3 and then loading them into Redshift, which increases data movement and operational complexity. Option C adds ETL job development, scheduling, retries, and monitoring overhead that is unnecessary if the primary goal is integrated querying for an annual report. Option D (DMS) is best when you need ongoing migration or continuous replication; it is typically more operationally heavy than needed for
"query across sources" use cases and still requires additional setup and maintenance.
Because all databases are already in the same VPC and the analytics platform is Redshift, federated querying provides the most direct, lowest-operations path to integrate and analyze the data where it already needs to be consumed.
NEW QUESTION # 149
......
The Data-Engineer-Associate PDF questions file is the third format of AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) exam practice questions. This format contains the real, valid, and updated Amazon Data-Engineer-Associate exam questions. You can download Itcerttest exam questions PDF on your desktop computer, laptop, tabs, or even on your smartphones. The Data-Engineer-Associate Questions Pdf file is very easy to use and compatible with all smart devices. Download the Itcerttest exam questions after paying affordable price and start preparation without wasting further time.
Dump Data-Engineer-Associate Collection: https://www.itcerttest.com/Data-Engineer-Associate_braindumps.html
BONUS!!! Download part of Itcerttest Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=16hDB0krlKDgC6pkNDaVAZFz5e88o0f33