What's more, part of that UpdateDumps Databricks-Certified-Data-Analyst-Associate dumps now are free: https://drive.google.com/open?id=1ee-UGt62Eqdp2YQ5jVhICy2dRj3Ueb2N
The client can try out and download our Databricks-Certified-Data-Analyst-Associate training materials freely before their purchase so as to have an understanding of our Databricks-Certified-Data-Analyst-Associate exam questions and then decide whether to buy them or not. The website pages of our product provide the details of our Databricks-Certified-Data-Analyst-Associate learning questions. You can see the demos of our Databricks-Certified-Data-Analyst-Associate Study Guide, which are part of the all titles selected from the test bank and the forms of the questions and answers and know the form of our software on the website pages of our Databricks-Certified-Data-Analyst-Associate study materials.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Managing Data | 8% | - Data Management
|
| Topic 2: Executing Queries Using Databricks SQL and SQL Warehouses | 20% | - SQL Querying
|
| Topic 3: Data Modeling with Databricks SQL | 5% | - Modeling Concepts
|
| Topic 4: Securing Data | 8% | - Security and Access Control
|
| Topic 5: Understanding of Databricks Data Intelligence Platform | 11% | - Platform Components
|
| Topic 6: Analyzing Queries | 15% | - Query Analysis
|
| Topic 7: Creating Dashboards and Visualizations | 16% | - Visualization
|
| Topic 8: Developing AI/BI Genie Spaces | 12% | - AI and BI Features
|
| Topic 9: Importing Data | 5% | - Data Import
|
>> Databricks Databricks-Certified-Data-Analyst-Associate Valid Test Vce <<
The Databricks-Certified-Data-Analyst-Associate exam dumps are real and updated Databricks-Certified-Data-Analyst-Associate exam questions that are verified by subject matter experts. They work closely and check all Databricks-Certified-Data-Analyst-Associate exam dumps one by one. They maintain and ensure the top standard of UpdateDumps Databricks Certified Data Analyst Associate Exam (Databricks-Certified-Data-Analyst-Associate) exam questions all the time. The Databricks-Certified-Data-Analyst-Associate practice test is being offered in three different formats. These Databricks-Certified-Data-Analyst-Associate exam questions formats are PDF dumps files, web-based practice test software, and desktop practice test software.
NEW QUESTION # 63
A data organization has a team of engineers developing data pipelines following the medallion architecture using Delta Live Tables. While the data analysis team working on a project is using gold-layer tables from these pipelines, they need to perform some additional processing of these tables prior to performing their analysis.
Which of the following terms is used to describe this type of work?
Answer: C
Explanation:
Last-mile ETL is the term used to describe the additional processing of data that is done by data analysts or data scientists after the data has been ingested, transformed, and stored in the lakehouse by data engineers. Last-mile ETL typically involves tasks such as data cleansing, data enrichment, data aggregation, data filtering, or data sampling that are specific to the analysis or machine learning use case. Last-mile ETL can be done using Databricks SQL, Databricks notebooks, or Databricks Machine Learning. Reference: Databricks - Last-mile ETL, Databricks - Data Analysis with Databricks SQL
NEW QUESTION # 64
A data analyst has opened the SQL Editor page and written a new SQL statement. The data analyst now wants to save that statement to easily refer back to it later and add it to a dashboard. The results of the SQL statement must be able to be displayed as a counter, table, or data visualization.
Which approach should the data analyst use to accomplish this task?
Answer: D
Explanation:
The correct answer is C because Databricks SQL Editor is used to create and save SQL queries. A saved query can later be opened, reused, shared, visualized, and added to a dashboard. A dashboard is not the saved SQL statement itself; it is a reporting object that can contain query results and visualizations. Query History stores past executions, but it is not the correct object for saving a reusable SQL statement.
Official documentation extract used: Databricks states that the SQL editor can be used to "author queries" and
"create visualizations." It also states that the Save button "saves your query," and query results can be added to a dashboard.
NEW QUESTION # 65
A managed table and an unmanaged external table were both created in Databricks SQL, and data was ingested into each table. Later, both tables were dropped.
What is the status of data for each of those tables?
Answer: A
Explanation:
Option B is correct. In Databricks, when a managed table is dropped, Databricks removes the table and its associated managed storage location. For an external table, Databricks removes only the table metadata; the underlying external data files are not deleted. Therefore, dropping both tables deletes the managed table's data but leaves the external table's data untouched. Official Databricks documentation states that DROP TABLE
"deletes the table and removes the directory associated with the table from the file system if the table is not an EXTERNAL table," and for external tables, Unity Catalog "removes the table metadata but does not delete the underlying data files."
NEW QUESTION # 66
The stakeholders.customers table has 15 columns and 3,000 rows of data. The following command is run: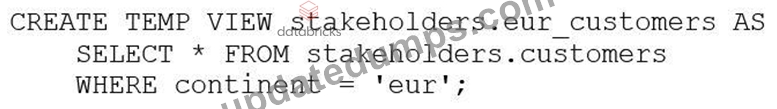
After running SELECT * FROM stakeholders.eur_customers, 15 rows are returned. After the command executes completely, the user logs out of Databricks.
After logging back in two days later, what is the status of the stakeholders.eur_customers view?
Answer: D
Explanation:
The command you sent creates a TEMP VIEW, which is a type of view that is only visible and accessible to the session that created it. When the session ends or the user logs out, the TEMP VIEW is automatically dropped and cannot be queried anymore. Therefore, after logging back in two days later, the status of the stakeholders.eur_customers view is that it has been dropped and SELECT * FROM stakeholders.eur_customers will result in an error. The other options are not correct because:
A) The view does not remain available, as it is a TEMP VIEW that is dropped when the session ends or the user logs out.
C) The view is not available in the metastore, as it is a TEMP VIEW that is not registered in the metastore. The underlying data cannot be accessed with SELECT * FROM delta. stakeholders.eur_customers, as this is not a valid syntax for querying a Delta Lake table. The correct syntax would be SELECT * FROM delta.dbfs:/stakeholders/eur_customers, where the location path is enclosed in backticks. However, this would also result in an error, as the TEMP VIEW does not write any data to the file system and the location path does not exist.
D) The view does not remain available, as it is a TEMP VIEW that is dropped when the session ends or the user logs out. Data in views are not automatically deleted after logging out, as views do not store any data. They are only logical representations of queries on base tables or other views.
E) The view has not been converted into a table, as there is no automatic conversion between views and tables in Databricks. To create a table from a view, you need to use a CREATE TABLE AS statement or a similar command. Reference: CREATE VIEW | Databricks on AWS, Solved: How do temp views actually work? - Databricks - 20136, temp tables in Databricks - Databricks - 44012, Temporary View in Databricks - BIG DATA PROGRAMMERS, Solved: What is the difference between a Temporary View an ...
NEW QUESTION # 67
A data analyst at an e-commerce company needs to process daily sales data. The data consists of approximately 50,000 records stored in a single CSV file, totaling about 20 MB. The analyst needs to perform aggregations and generate a summary report.
Which approach could the data analyst use in this situation?
Answer: D
Explanation:
Option B is correct. A 20 MB CSV file with about 50,000 records is small enough for a local pandas workflow. A real-time streaming solution, a distributed Spark cluster, or Hadoop MapReduce would add unnecessary complexity for a small single-file batch analysis. Databricks documentation explains that pandas is available in Databricks Runtime and can be used for data analysis, while pandas API on Spark is useful when pandas-style workloads need to scale beyond smaller datasets. Databricks also notes that pandas does not scale out to big data, which is exactly why Spark or pandas API on Spark is used for larger workloads, not for a small 20 MB file.
NEW QUESTION # 68
......
After the user has purchased our Databricks-Certified-Data-Analyst-Associate learning materials, we will discover in the course of use that our product design is extremely scientific and reasonable. Details determine success or failure, so our every detail is strictly controlled. For example, our learning material's Windows Software page is clearly, our Databricks-Certified-Data-Analyst-Associate Learning material interface is simple and beautiful. There are no additional ads to disturb the user to use the Databricks Certified Data Analyst Associate Exam qualification question. Once you have submitted your practice time, Databricks-Certified-Data-Analyst-Associate study tool system will automatically complete your operation.
Free Databricks-Certified-Data-Analyst-Associate Exam Dumps: https://www.updatedumps.com/Databricks/Databricks-Certified-Data-Analyst-Associate-updated-exam-dumps.html
P.S. Free 2026 Databricks Databricks-Certified-Data-Analyst-Associate dumps are available on Google Drive shared by UpdateDumps: https://drive.google.com/open?id=1ee-UGt62Eqdp2YQ5jVhICy2dRj3Ueb2N