No doubt the Nutanix NCP-BC-7.5 certification exam is a challenging exam that always gives a tough time to their candidates. However, with the help of Lead2PassExam Nutanix Exam Questions, you can prepare yourself quickly to pass the Nutanix NCP-BC-7.5 Exam. The Lead2PassExam Nutanix NCP-BC-7.5 exam dumps are real, valid, and updated Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 (NCP-BC-7.5) practice questions that are ideal study material for quick Nutanix NCP-BC-7.5 exam dumps preparation.
| Section | Objectives |
|---|---|
| Disaster Recovery Fundamentals | - Business Continuity Principles - DR Concepts (RPO, RTO, SLAs) |
| Prism Central Management | - Cluster and Site Management - DR Monitoring and Operations |
| Nutanix Disaster Recovery Architecture | - Protection Domains - Nutanix Leap Overview - Replication Types (Sync/Async) |
| Data Protection and Backup Integration | - Snapshot Management - Backup Solutions Integration |
| Recovery Operations | - Recovery Plans and Orchestration - Test Recovery Workflows - Failover and Failback Procedures |
>> NCP-BC-7.5 Reliable Exam Cost <<
Many students often start to study as the exam is approaching. Time is very valuable to these students, and for them, one extra hour of study may mean 3 points more on the test score. If you are one of these students, then Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 exam tests are your best choice. Because students often purchase materials from the Internet, there is a problem that they need transport time, especially for those students who live in remote areas. When the materials arrive, they may just have a little time to read them before the exam. However, with NCP-BC-7.5 Exam Questions, you will never encounter such problems, because our materials are distributed to customers through emails.
NEW QUESTION # 55
Which combination of Replication Schedules within the same Recovery Plan will cause the recovery to fail?
Answer: D
Explanation:
A Recovery Plan in Nutanix is the orchestration engine that defines the power-on sequence, network mappings, and script execution for disaster recovery. While a single cluster can support various types of replication-Asynchronous, NearSync, and Synchronous-there are strict architectural limits on how these can be mixed within a single automated plan.
The primary conflict arises when mixing Synchronous (0 RPO) schedules with snapshot-based Asynchronous or NearSync schedules. Synchronous replication is an " Active-Standby " or " Active-Active " storage state where the destination site already has the data in a " mounted " but inactive container. In contrast, Asynchronous and NearSync recovery involve " restoring " a VM from a specific recovery point (snapshot), which includes registering the VM and attaching the disks during the failover process. Because the orchestration logic for a Zero-RPO synchronous failover is fundamentally different from a snapshot restoration, Nutanix prevents placing them in the same Recovery Plan. Attempting to do so will cause validation errors and lead to execution failure, as the orchestrator cannot simultaneously manage real-time failover and snapshot-based restoration for the same logical group. To successfully protect an environment with both types of RPO requirements, administrators must create separate Recovery Plans: one dedicated to Synchronous workloads and another for snapshot-based Asynchronous/NearSync workloads, ensuring that each set of VMs follows its appropriate recovery workflow.
NEW QUESTION # 56
After a failover and stabilization of workloads at the recovery AZ, an administrator removes several VMs from the protection policy because they are no longer required. Which action should be performed as part of post-failover cleanup to prevent unnecessary storage consumption?
Answer: D
Explanation:
Post-failover cleanup is a vital operational step to ensure that the environment remains optimized and that resources are not being wasted on workloads that are no longer part of the production environment. When virtual machines are removed from a Protection Policy after a failover, the orchestration engine stops creating new recovery points for them; however, the existing schedule metadata and historical snapshots may still consume space on both the primary and recovery clusters. Reconfiguring the replication schedule (Option B) is the specific task that refreshes the policy ' s state and forces the system to re-evaluate the storage requirements for the remaining entities. This action ensures that the background cleanup processes (managed by Cerebro and Curator) can properly identify and purge the snapshots associated with the removed VMs once their retention period has passed. Failing to reconfigure the schedule or the associated protection policy can leave " orphaned " snapshots in the storage tier, leading to a steady increase in storage utilization over time. By reconfiguring the schedule, the administrator confirms the new steady-state of the DR environment, ensuring that storage is only consumed by the active, required workloads.
NEW QUESTION # 57
An administrator has received the following alert: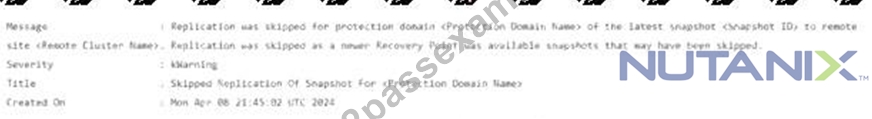
Replication was skipped for protection domain < Protection Domain Name > of the latest snapshot < Snapshot ID > to remote site < Remote Cluster Name > . Replication was skipped as a newer Recovery Point was available snapshots that may have been skipped.
The administrator begins gathering troubleshooting information and determines the following:
* The VM has been replicating to this cluster successfully for at least 6 months
* The bandwidth has been sufficient to this point and hasn ' t caused an issue before
* Network connectivity is good and all necessary ports remain open and reachable
* There aren ' t hardware issues, and software is up to date
What else could have caused this alert?
Answer: A
Explanation:
The Nutanix Cerebro service manages replication by scheduling snapshots and transferring the delta changes to the remote site. In an asynchronous replication schedule, if a new snapshot is taken before the previous one has finished replicating, the system faces a choice. To ensure that the most current data is available at the recovery site as quickly as possible, Nutanix may " skip " the replication of an older pending snapshot in favor of starting the replication of the newest one.
In this scenario, all infrastructure components (bandwidth, ports, hardware) are verified as healthy and have supported successful replication for months. This points toward a data-level issue rather than a connectivity issue. A " significant one-time surge in change rate " (Option D) means the VM generated a massive amount of new data blocks (churn) in a short period. Because the " Snapshot-on-wire " transfer size is directly tied to the number of changed blocks, this specific snapshot would take much longer than usual to replicate. If the transfer time exceeds the RPO interval, the next scheduled snapshot will trigger. The Cerebro service will see that it has a newer recovery point ready to go and will skip the " stuck " or slow-moving older snapshot to maintain the most recent RPO possible at the target. This behavior generates the " Replication was skipped " warning to notify the administrator that the historical sequence was interrupted due to a temporary imbalance between data churn and available throughput.
NEW QUESTION # 58
An administrator configures a VM-VM Anti-Affinity policy for a web application cluster to ensure high availability. The application is protected by a Protection Policy in Prism Central. A failover occurs, moving the VMs to the recovery site.
What determines whether the VM-VM Anti-Affinity rules are active on the recovery site?
Answer: C
Explanation:
VM-VM Anti-Affinity rules are used in Nutanix to ensure that specific virtual machines (such as the nodes of a database cluster or redundant web servers) never run on the same physical host, thereby protecting the application from a single host failure. These rules are typically managed through Prism Central (PC) in a modern deployment.
However, in the context of Disaster Recovery (DR) between two different clusters or availability zones, there is a technical limitation regarding the replication of these affinity policies. While the virtual machine ' s data and primary metadata (CPU, RAM, Disks) are replicated by the Cerebro service, the affinity rules are often considered local cluster constraints. In many versions of Nutanix Disaster Recovery (specifically the initial iterations of Leap/Prism Central-based DR), these affinity policies are not natively " synchronized " or enforced at the recovery site during a failover. This means that when the VMs are recovered at the destination cluster, the hypervisor ' s dynamic scheduler (ADS) may place them on the same host if that host has the most available resources. To maintain anti-affinity at the recovery site, an administrator would typically need to manually recreate the affinity policies at the destination AZ or use specialized orchestration scripts.
Understanding this limitation is vital for ensuring that high-availability requirements are still met after a disaster recovery event has occurred.
NEW QUESTION # 59
An administrator is preparing to configure DR between an on-prem AZ and Nutanix Cloud AZ. Replication fails immediately after configuration. Which prerequisite should be verified?
Answer: C
Explanation:
Establishing disaster recovery between an on-premises data center and a Nutanix Cloud Availability Zone (AZ) requires a robust communication path that can traverse different network boundaries. Unlike local replication within a single site, cross-site replication-especially to a public cloud environment-relies on the ability of the clusters to identify and reach one another over an external network. Nutanix Disaster Recovery requires that both the on-premises cluster and the Nutanix Cloud AZ instance have external IP addresses configured for their respective Controller VMs (CVMs) and virtual interfaces.
These external IP addresses allow the Cerebro service at the source site to establish a secure handshake with the Cerebro service at the cloud site. Without these routable external IPs, the replication traffic is unable to find its destination, leading to the immediate failure of the configuration as observed in this scenario. While identical hypervisors (Option A) are often preferred for simplicity, Nutanix supports Cross-Hypervisor DR (CHDR). Furthermore, deduplication status (Option C) does not prevent the establishment of a replication link. Synchronous replication (Option D) is restricted by latency requirements and is not a fundamental prerequisite for basic connectivity to a cloud AZ. Therefore, verifying the presence of external, reachable IP addresses is the mandatory first step in troubleshooting cross-site connectivity issues between on-premises and cloud environments.
NEW QUESTION # 60
......
Lead2PassExam Nutanix NCP-BC-7.5 test answers are the most effective and we guarantee your success in the first attempt. If you do not pass Nutanix NCP-BC-7.5 exam, we will give you a FULL REFUND of your purchasing fee. Failure in exam will not affect your finance. On request we can provide you with another exam of your choice absolutely free of cost. Think you! What do you have to lose? Nutanix NCP-BC-7.5 Test Answers are the latest and 100% guarantee to pass your NCP-BC-7.5 exam.
NCP-BC-7.5 Dumps Free: https://www.lead2passexam.com/Nutanix/valid-NCP-BC-7.5-exam-dumps.html