BONUS!!! Download part of TrainingDumps SPLK-2002 dumps for free: https://drive.google.com/open?id=14bUTIyQMeeZKZXC8pGcDT1y5FmNxq6r4
Do you want to improve your IT skills in a shorter time as soon as possible but lacking of proper training materials? Don't worry, with TrainingDumps SPLK-2002 exam training materials, any IT certification exam can be easily coped with. Our SPLK-2002 Exam Training materials is the achievement that TrainingDumps's experienced IT experts worked out through years of constant exploration and practice. TrainingDumps will be your best choice.
The SPLK-2002 Exam is a comprehensive exam that covers a wide range of topics related to Splunk Enterprise. These topics include architecture and deployment, data ingestion and management, search and reporting, data visualization, and troubleshooting and optimization. Candidates are required to have a deep understanding of each of these topics in order to pass the exam.
>> Top SPLK-2002 Exam Dumps <<
The desktop Splunk SPLK-2002 exam simulation software works only on Windows, but the web-based Splunk SPLK-2002 practice exam is compatible with all operating systems. You can take the online Splunk SPLK-2002 Mock Test without software installation via Chrome, Opera, Firefox, or another popular browser.
The Splunk SPLK-2002 Exam measures the ability of candidates to design and implement complex Splunk Enterprise architectures, develop advanced Splunk Enterprise configurations, and integrate Splunk Enterprise with other systems. Splunk Enterprise Certified Architect certification is recognized as a valuable credential for IT professionals who work with Splunk Enterprise. It demonstrates that an individual has the skills and knowledge required to design and implement Splunk Enterprise solutions that meet the needs of organizations.
NEW QUESTION # 13
Which of the following server. conf stanzas indicates the Indexer Discovery feature has not been fully configured (restart pending) on the Master Node?
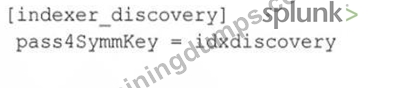



Answer: C
Explanation:
The Indexer Discovery feature enables forwarders to dynamically connect to the available peer nodes in an indexer cluster. To use this feature, the manager node must be configured with the [indexer_discovery] stanza and a pass4SymmKey value. The forwarders must also be configured with the same pass4SymmKey value and the master_uri of the manager node. The pass4SymmKey value must be encrypted using the splunk
_encrypt command. Therefore, option A indicates that the Indexer Discovery feature has not been fully configured on the manager node, because the pass4SymmKey value is not encrypted. The other options are not related to the Indexer Discovery feature. Option B shows the configuration of a forwarder that is part of an indexer cluster. Option C shows the configuration of a manager node that is part of an indexer cluster. Option D shows an invalid configuration of the [indexer_discovery] stanza, because the pass4SymmKey value is not encrypted and does not match the forwarders' pass4SymmKey value12
1: https://docs.splunk.com/Documentation/Splunk/9.1.2/Indexer/indexerdiscovery 2: https://docs.splunk.com
/Documentation/Splunk/9.1.2/Security
/Secureyourconfigurationfiles#Encrypt_the_pass4SymmKey_setting_in_server.conf
NEW QUESTION # 14
What is the best method for sizing or scaling a search head cluster?
Answer: D
Explanation:
According to the Splunk blog1, the best method for sizing or scaling a search head cluster is to estimate the maximum concurrent number of searches and divide by the number of CPU cores per search head. This gives you an idea of how many search heads you need to handle the peak search load without overloading the CPU resources. The other options are false because:
* Estimating the maximum daily ingest volume in gigabytes and dividing by the number of CPU cores per search head is not a good method for sizing or scaling a search head cluster, as it does not account for the complexity and frequency of the searches. The ingest volume is more relevant for sizing or scaling the indexers, not the search heads2.
* Estimating the total number of searches per day and dividing by the number of CPU cores available on the search heads is not a good method for sizing or scaling a search head cluster, as it does not account for the concurrency and duration of the searches. The total number of searches per day is an average metric that does not reflect the peak search load or the search performance2.
* Dividing the number of indexers by three to achieve the correct number of search heads is not a good method for sizing or scaling a search head cluster, as it does not account for the search load or the search head capacity. The number of indexers is not directly proportional to the number of search heads, as different types of data and searches may require different amounts of resources2.
NEW QUESTION # 15
A multi-site indexer cluster can be configured using which of the following? (Select all that apply.)
Answer: C,D
Explanation:
A multi-site indexer cluster can be configured by directly editing SPLUNK_HOME/etc/system/local/server.
conf or running a splunk edit cluster-config command from the CLI. These methods allow the administrator to specify the site attribute for each indexer node and the site_replication_factor and site_search_factor for the cluster. Configuring a multi-site indexer cluster via Splunk Web or directly editing SPLUNK_HOME/etc
/system/default/server.conf are not supported methods. For more information, see Configure the indexer cluster with server.conf in the Splunk documentation.
NEW QUESTION # 16
A customer plans to ingest 600 GB of data per day into Splunk. They will have six concurrent users, and they also want high data availability and high search performance. The customer is concerned about cost and wants to spend the minimum amount on the hardware for Splunk. How many indexers are recommended for this deployment?
Answer: D
NEW QUESTION # 17
(Which indexes.conf attribute would prevent an index from participating in an indexer cluster?)
Answer: D
Explanation:
The repFactor (replication factor) attribute in the indexes.conf file determines whether an index participates in indexer clustering and how many copies of its data are replicated across peer nodes.
When repFactor is set to 0, it explicitly instructs Splunk to exclude that index from participating in the cluster replication and management process. This means:
* The index is not replicated across peer nodes.
* It will not be managed by the Cluster Manager.
* It exists only locally on the indexer where it was created.
Such indexes are typically used for local-only storage, such as _internal, _audit, or other custom indexes that store diagnostic or node-specific data.
By contrast:
* repFactor=auto allows the index to inherit the cluster-wide replication policy from the Cluster Manager.
* available_sites and site_mappings relate to multisite configurations, controlling where copies of the data are stored, but they do not remove the index from clustering.
Setting repFactor=0 is the only officially supported way to create a non-clustered index within a clustered environment.
References (Splunk Enterprise Documentation):
* indexes.conf Reference - repFactor Attribute Explanation
* Managing Non-Clustered Indexes in Clustered Deployments
* Indexer Clustering: Index Participation and Replication Policies
* Splunk Enterprise Admin Manual - Local-Only and Clustered Index Configurations
NEW QUESTION # 18
......
SPLK-2002 Reliable Exam Test: https://www.trainingdumps.com/SPLK-2002_exam-valid-dumps.html
DOWNLOAD the newest TrainingDumps SPLK-2002 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=14bUTIyQMeeZKZXC8pGcDT1y5FmNxq6r4