BONUS!!! Download part of Dumpexams SPS-C01 dumps for free: https://drive.google.com/open?id=1UskXSTNZpdKs-Cf_Le6wVPBWoF1sjCb3
By choosing a good training site, you can achieve remarkable results. Dumpexams has committed to provide all real Snowflake SPS-C01 practice tests. Dumpexams Snowflake SPS-C01 exam dumps authorized by the supplier, with wide coverage can save a lot of time for you. Guarantee your success in the first attempt. If you do not pass the Snowflake Business Solutions SPS-C01 Exam on your first attempt we will give you a FULL REFUND of your purchasing fee. Failing an Exam won't damage you financially as we provide 100% refund on claim.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark Concepts | 15% | - Snowpark architecture and core concepts - Transformations vs. Actions - Client-side vs. Server-side execution - Snowpark Sessions and connection management - Snowpark DataFrames and query plans - Stored procedures and conditional logic |
| Topic 2: Data Transformations and DataFrame Operations | 35% | - Complex data pipelines - Persisting transformed data - Using built-in functions - Filtering, Aggregating, and Joining DataFrames - Window functions |
| Topic 3: Performance Optimization and Best Practices | 20% | - Query pushdown and optimization - Caching strategies - Minimizing data transfer - Warehouse sizing for Snowpark - Debugging and explain plans - Vectorized UDFs |
| Topic 4: Snowpark API for Python | 30% | - User-Defined Functions (UDFs) and Stored Procedures - DataFrame creation and manipulation - Working with Semi-structured data - Establishing connections and session management - Reading and writing data |
In order to pass the exam and fight for a brighter future, these people who want to change themselves need to put their ingenuity and can do spirit to work. More importantly, it is necessary for these people to choose the convenient and helpful SPS-C01 study materials as their study tool in the next time. Because their time is not enough to prepare for the exam, and a lot of people have difficulty in preparing for the exam, so many people who want to pass the SPS-C01 Exam and get the related certification in a short time have to pay more attention to the study materials.
NEW QUESTION # 47
Consider a Snowflake table 'orders' with columns 'order_id', 'customer_id', 'order_date', and 'status'. You need to update the 'status' of all orders placed before January 1, 2023, to 'Archived'. Which of the following approaches is the most efficient and idiomatic way to achieve this using Snowpark DataFrames, assuming 'orders df DataFrame represents the 'orders' table?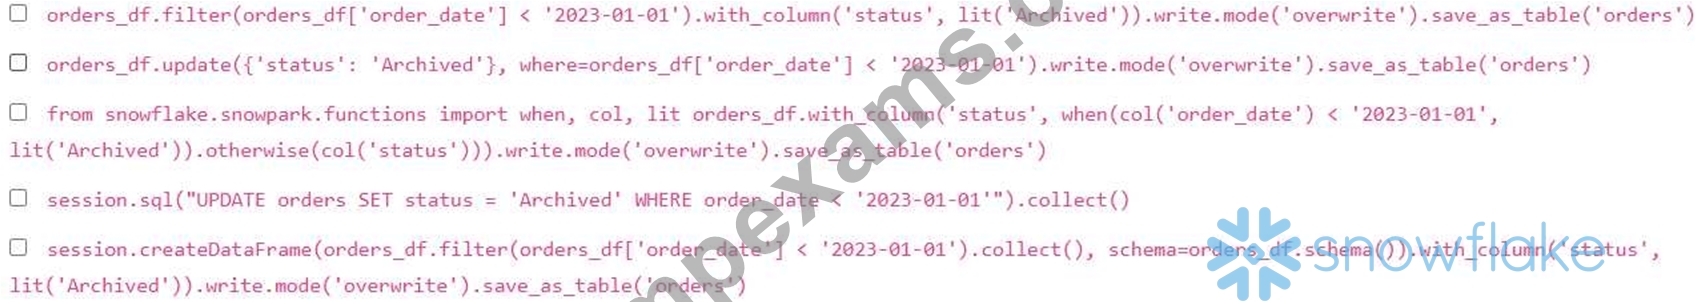
Answer: B,E
Explanation:
Options C and D are both valid and efficient solutions. Option C leverages Snowpark's 'with_column' and 'when' functions to conditionally update the 'status' column within the DataFrame and persists the changes back to the table using 'save_as_table'. Using lit function makes sure that 'Archived' status is passed as a literal. Option D uses a direct SQL update statement executed through the Snowpark session. This bypasses DataFrame operations but directly modifies the table, which can sometimes be more efficient for simple update operations. Option A is almost correct but the with_column and filter are applied separately. Option B doesn't work due to the way update functions are implemented in Snowpark. Option E unnecessarily collects the filtered data back to the driver, creating a new DataFrame from the collected data, then applying 'with_column'. This is an inefficient approach.
NEW QUESTION # 48
You are working with Snowpark and need to persist the results of a DataFrame 'df to a Snowflake stage named 'my_stage'. You want to achieve the following: 1. Write the data in JSON format. 2. Use snappy compression. 3. Handle potential write errors gracefully. 4. Overwrite any existing files with the same name. Which of the following approaches can achieve these requirements? (Select all that apply)
Answer: A,C,E
Explanation:
Option A directly utilizes the .json(V method for writing JSON files with snappy compression, specifying the 'overwrite' mode, and the 'try-except block adds error handling. Option C specifies the format to JSON using format('json') with snappy compression and specifying the 'overwrite' mode, and using a 'try-except' block for error handling. Option E deals with write errors by wrapping the entire process inside try-except block. Options D is not correct since creating a UDF just for this purpose introduces unnecessary overhead compared to the simple and direct approaches provided by A and C. Option B is incorrect, while configuring the stage with a default file format is useful, it won't apply in this specific write operation using DataFrameWriter. We need to explicitly define format and compression for the operation.
NEW QUESTION # 49
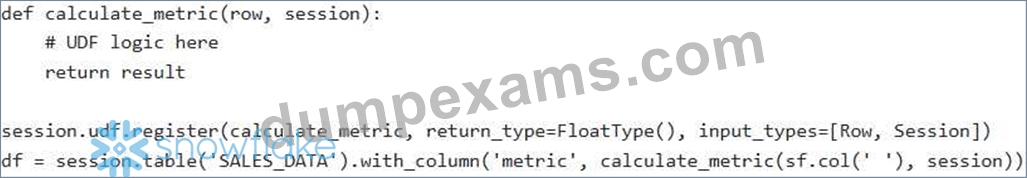
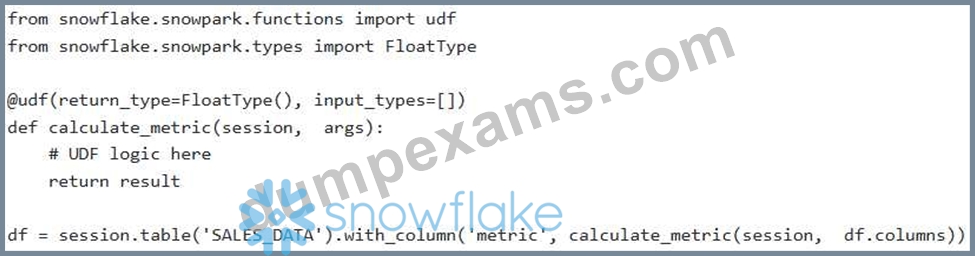
You are using Snowpark Python to create a DataFrame from an existing Snowflake table "SALES DATA'. You want to apply a user- defined function (UDF) to each row of the DataFrame to calculate a custom sales metric. The UDF requires access to the 'session' object. Which of the following approaches is correct for defining and applying the UDF in Snowpark?
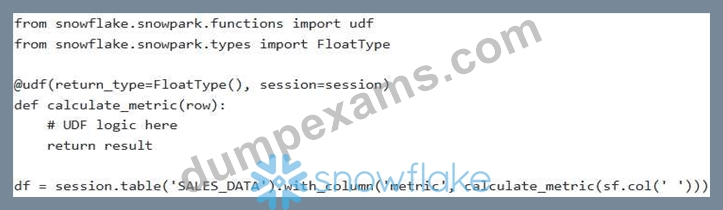
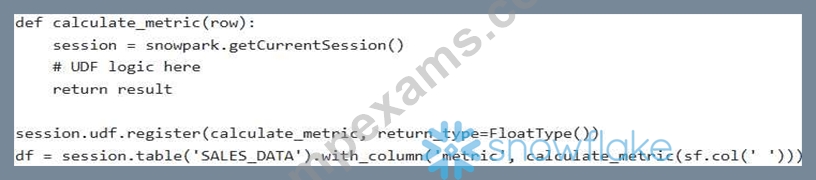
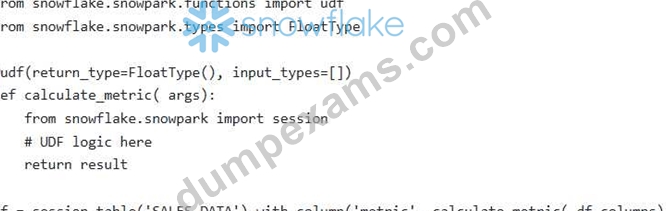
Answer: C
Explanation:
Option E is the correct approach. To access the session object from within the UDF, you can import it when registering the UDF with the session. It should be imported inside the function and use the decorator. The input_types parameter should be set to 0, since this allows for session access.
NEW QUESTION # 50
You're using Snowpark in Python and need to execute a complex SQL query. The query involves several joins and aggregations, and you want to optimize its performance. You are using "session.sql(query)' to execute the query. Which of the following strategies, applied before executing 'session.sql(query)' , would likely lead to the most significant performance improvement for a very large dataset?
Answer: D
Explanation:
Option A provides the most significant improvement because Snowpark DataFrame operations allow Snowflake's query optimizer to leverage pushdown optimizations. When you express your logic as DataFrame operations, Snowpark translates these into SQL that is specifically tailored for Snowflake's engine. This gives Snowflake more control over the execution plan compared to simply passing in a pre-written SQL query via 'session.sql(queryy. DataFrame operations allow the query optimizer to push down operations such as filters and aggregations to the data source, significantly reducing the amount of data transferred and processed. Option B is incorrect because comments only improve readability, not performance. Option C, , can help if the DataFrame is used multiple times, but it doesn't address the initial optimization of the query itself. Option D could help, but converting to DataFrame operations provides more comprehensive optimization. Option E can assist, but often DataFrame creation and optimal query plan generation can be better using Option A.
NEW QUESTION # 51
You are developing a Snowpark Python application that reads data from a Snowflake table, performs several transformations including filtering, aggregation, and joining with another DataFrame, and then writes the results back to a new table. You want to optimize the execution plan to minimize data movement and processing time. Which of the following strategies would be MOST effective in leveraging Snowpark's lazy evaluation capabilities to achieve this optimization?
Answer: A
Explanation:
Chaining transformations and delaying execution until the final action allows Snowpark to optimize the entire query plan. Caching the initial DataFrame might improve performance in some cases, but it can also introduce unnecessary materialization. Defining transformations in a single SQL query string bypasses Snowpark's optimization capabilities. Calling 'collect()' after each transformation defeats the purpose of lazy evaluation. Python multiprocessing does not directly interact with Snowpark's query optimization.
NEW QUESTION # 52
......
Eliminates confusion while taking the Snowflake SPS-C01 certification exam. Prepares you for the format of your Snowflake SPS-C01 exam dumps, including multiple-choice questions and fill-in-the-blank answers. Comprehensive, up-to-date coverage of the entire Snowflake SPS-C01 Certification curriculum.
SPS-C01 Free Exam Questions: https://www.dumpexams.com/SPS-C01-real-answers.html
BTW, DOWNLOAD part of Dumpexams SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1UskXSTNZpdKs-Cf_Le6wVPBWoF1sjCb3