When preparing for the test NCP-BC-7.5 certification, most clients choose our products because our NCP-BC-7.5 learning file enjoys high reputation and boost high passing rate. Our products are the masterpiece of our company and designed especially for the certification. Our NCP-BC-7.5 latest study question has gone through strict analysis and verification by the industry experts and senior published authors. The clients trust our products and place great hopes on our NCP-BC-7.5 Exam Dump. They treat our products as the first choice and the total amounts of the clients and the sales volume of our NCP-BC-7.5 learning file is constantly increasing.
| Section | Weight | Objectives |
|---|---|---|
| Test BCDR Solutions | 25% | - Verify site connectivity and replication throughput - Execute planned, unplanned, and test failovers - Perform disaster recovery validation procedures - Validate recovery plan execution and outcomes |
| Perform BCDR Operational Tasks | 25% | - Self-service restore operations - Snapshot-based VM and volume recovery - Migrate legacy protection domains to modern policies - Execute failover and failback workflows - Post-failover cleanup and re-protection |
| Troubleshoot BCDR Failures | 20% | - Resolve storage and snapshot errors - Troubleshoot replication and protection policy issues - Fix third-party backup integration problems - Resolve misconfigurations in DR environments - Diagnose network-related replication failures |
| Interpret and Configure BCDR Requirements | 30% | - Configure network and storage for BCDR - Create and configure recovery plans - Select replication types: Async, NearSync, Synchronous, Metro - Design secure BCDR environments: segmentation, RBAC, approval policies - Determine prerequisites for BCDR configuration - Translate business requirements into RPO/RTO objectives - Configure snapshot policies and retention |
>> Braindump NCP-BC-7.5 Pdf <<
Similarly, the TopExamCollection Nutanix NCP-BC-7.5 practice test creates an actual exam scenario on each and every step so that you may be well prepared before your actual Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 examination time. Hence, it saves you time and money. TopExamCollection provides three months of free updates if you purchase the Nutanix NCP-BC-7.5 Questions and the content of the examination changes after that.
NEW QUESTION # 101
An administrator is concerned about the operational overhead of manually creating and managing categories across both the primary and recovery sites to ensure Recovery Plans function correctly during failover and failback. What Nutanix Disaster Recovery behavior minimizes this concern?
Answer: C
Explanation:
Nutanix Disaster Recovery (formerly known as Leap) utilizes Prism Central-based " Categories " to group virtual machines for protection. These categories are used within Protection Policies to determine replication schedules and within Recovery Plans to determine power-on sequences and network mappings. A common operational concern is the need to manually replicate these category definitions across different availability zones (AZs).
To reduce this operational overhead, Nutanix has implemented an automatic synchronization mechanism.
When an administrator creates a Recovery Plan in Prism Central and specifies certain categories for failover, the system automatically synchronizes the definition and metadata of those categories to the paired recovery AZ. This ensures that if the primary Prism Central instance becomes unavailable, the recovery site already possesses the necessary grouping logic to identify and recover the correct virtual machines . This " policy- driven " approach ensures consistency across sites and eliminates the risk of human error associated with manual configuration (Option B). By automating the lifecycle of categories between paired sites, Nutanix ensures that the disaster recovery environment is always aligned with the production environment, allowing for seamless failover and failback operations without the need for repetitive administrative tasks.
NEW QUESTION # 102
An administrator managing critical VMs has been tasked with designing a Disaster Recovery solution where the VMs are brought up on the target cluster if the source cluster experience any issues. The failover needs to be triggered without any user intervention and with minimal downtime. What automatic failure execution solution is best suited?
Answer: B
Explanation:
To achieve the goal of " minimal downtime " and " no user intervention, " a zero-RPO solution with automated failover capabilities is required. In the Nutanix ecosystem, this is accomplished through Synchronous Replication. Unlike Asynchronous or NearSync replication, which rely on snapshot intervals and manual failover triggers, Synchronous replication ensures that data is written to both the local and remote clusters simultaneously. This architecture provides the foundation for zero data loss during a site failure.
However, the " automatic " part of the requirement is fulfilled by the addition of a Witness VM. Without a Witness, a secondary cluster cannot independently determine if the primary cluster has actually failed or if there is merely a network partition. In a " no witness " scenario (Option C), the secondary cluster stays in a passive state to prevent " split-brain " data corruption, requiring an administrator to manually promote the storage. By deploying a Witness VM at a third, independent site, the secondary cluster can communicate with the Witness to " acquire the lock " on the protection domain. Once the Witness confirms the primary site is unreachable, the orchestrator automatically promotes the secondary container and powers on the VMs. This combined solution of a Synchronous Protection Policy and a Witness VM provides the highest level of availability and the fastest possible recovery without requiring human action during the disaster event.
NEW QUESTION # 103
An administrator protects workloads between two ESXi clusters using asynchronous (async) replication. After failover, VMs power on successfully but are placed in the default folder and resource pool instead of their original vSphere folders. Why did this occur?
Answer: D
Explanation:
Nutanix Asynchronous (Async) replication is a foundational data protection technology that allows for the periodic transfer of virtual machine snapshots from a primary cluster to a remote site. When using Async replication between two ESXi-based Nutanix clusters, the primary objective is data persistence rather than deep integration with the vSphere management hierarchy. Because Async replication operates at the storage level, it captures the virtual disk (vDisk) data and the VM ' s configuration files (.vmx) but does not natively synchronize the logical inventory metadata maintained by the vCenter Server, such as VM folders, resource pools, or specific vApp configurations.
When a failover is executed, the Nutanix cluster registers the VM to the remote ESXi host and vCenter. Since the inventory mapping details (original folder and resource pool) are not part of the standard Async replication payload, the vCenter Server treats the failing-over VM as a new registration and places it into the default root folder and the default cluster resource pool. To maintain consistent organizational structures during a disaster recovery event, administrators typically rely on Prism Central-based " Recovery Plans. " Recovery Plans offer advanced orchestration that allows for the manual definition of inventory mappings, ensuring that VMs are placed in the correct folders and resource pools upon recovery. Understanding this limitation of legacy Async replication is crucial for administrators designing BCDR solutions that require high levels of organizational consistency post-failover.
NEW QUESTION # 104
Exhibit: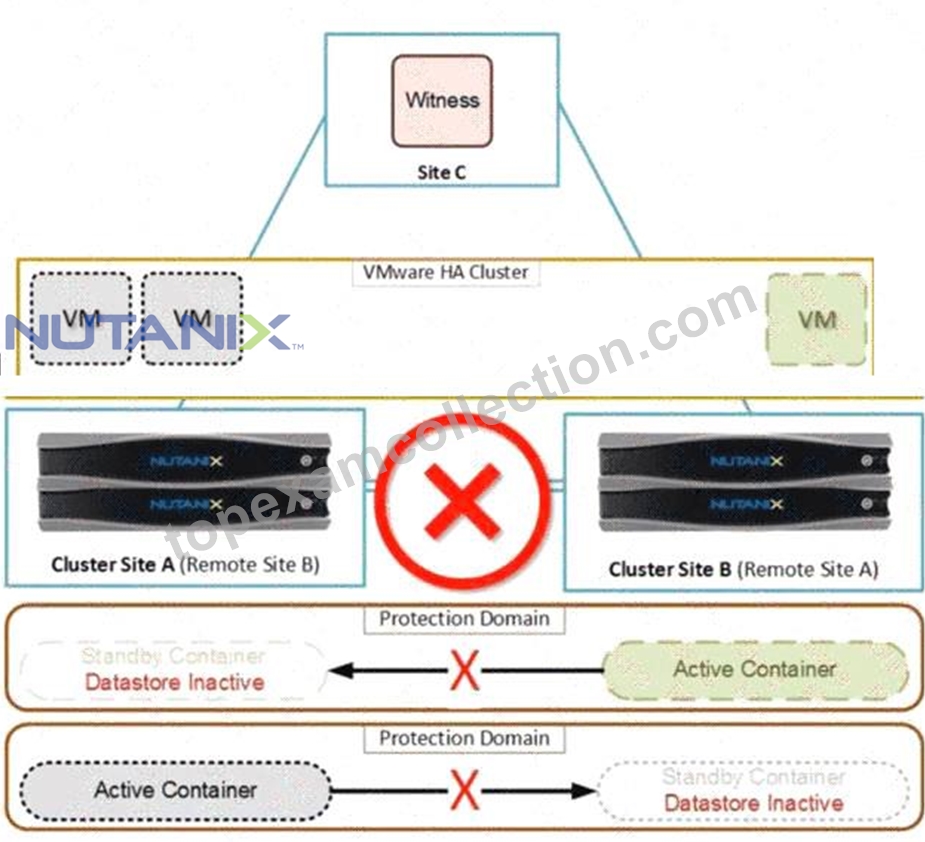
An administrator wants to protect the snapshots created on the cluster. Only authorized users should be allowed to modify or delete the snapshots on the cluster. How can the administrator harden the security of the snapshots?
Answer: C
Explanation:
Security hardening for BCDR is focused on protecting the integrity of recovery points against accidental deletion, administrative errors, or malicious intent such as ransomware. While infrastructure-level hardening like SSH keys (Option C) or host-level security (Option A) is important, they do not prevent a user with valid administrative credentials in Prism from deleting a snapshot. To address the specific requirement of ensuring only " authorized " and verified actions can modify or delete snapshots, the administrator should implement an " Approval Policy " .
An Approval Policy introduces a " four-eyes " principle for critical management tasks. When this policy is active, any attempt to delete or modify a recovery point does not execute immediately. Instead, it triggers a request in the Prism Central " Task " console and enters a " Pending Approval " state. A separate authorized user-an " Approver " -must then review the request and explicitly grant permission before the deletion can occur. This creates a vital procedural safeguard, ensuring that no single individual has the unilateral power to destroy the organization ' s backup data. By configuring this policy, the administrator hardens the DR environment against both internal threats and external actors who might gain access to a single set of admin credentials, providing a robust layer of defense for critical data assets.
NEW QUESTION # 105
An administrator executes an Unplanned Failover of web server VMs from an on-premises AZ to a Nutanix Cloud Cluster (NC2) on AWS. The Recovery Plan completes, and the VMs are running. However, external users cannot access the websites hosted on these VMs. The administrator verifies that the firewall rules are set correctly. What specific configuration is required for these VMs to be reachable from the external network after failover to NC2?
Answer: B
Explanation:
Failing over to Nutanix Cloud Clusters (NC2) on AWS involves moving workloads from a local, on-premises networking environment into a cloud-native Virtual Private Cloud (VPC). While Nutanix Flow Virtual Networking (FVN) allows the VMs to keep their internal IP addresses using overlay networks, external visibility requires integration with AWS networking components.
Standard internal IP addresses in an overlay network are not natively routable from the public internet or from the AWS VPC outside of the NC2 cluster. To bridge this gap, Nutanix uses " Floating IPs " . A Floating IP is an AWS Elastic IP that is mapped to the internal IP of the guest VM. When an external user attempts to reach the website, the traffic hits the AWS public-facing Floating IP, which is then translated and routed through the NC2 bare-metal nodes to the specific guest VM. This mapping can be automated as part of the Recovery Plan or configured manually post-failover. Without this configuration, the VMs will remain " isolated " from external traffic, even if the application is running perfectly and internal cluster connectivity is healthy. This demonstrates the importance of cloud-native networking knowledge when extending on-premises BCDR plans into public cloud environments like NC2.
NEW QUESTION # 106
......
Our NCP-BC-7.5 practice materials are your best choice for their efficiency in different aspects: first of all, do not need to wait, you can get them immediately if you pay for it and download as your wish. Clear-arranged content is our second advantage. Some exam candidates are prone to get anxious about the NCP-BC-7.5 Exam Questions, but with clear and points of necessary questions within our NCP-BC-7.5 study guide, you can master them effectively in limited time.
Exams NCP-BC-7.5 Torrent: https://www.topexamcollection.com/NCP-BC-7.5-vce-collection.html