Databricks Databricks-Certified-Data-Analyst-Associate Test Review & Databricks-Certified-Data-Analyst-Associate New Guide Files

DOWNLOAD the newest RealExamFree Databricks-Certified-Data-Analyst-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1uvXhL8I8R3Y7ef4JMyJL6OL4dJpwMp7l
We have tens of thousands of supporters around the world eager to pass the exam with our Databricks-Certified-Data-Analyst-Associate learning guide which are having a steady increase on the previous years. Exam candidates around the world are longing for learning from our practice materials. If you want to have an outline and brief understanding of our Databricks-Certified-Data-Analyst-Associate Preparation materials we offer free demos for your reference. You can have a look of our Databricks-Certified-Data-Analyst-Associate exam questions for realistic testing problems in them.
| Topic | Details |
|---|
| Topic 1 | - Analytics applications: It describes key moments of statistical distributions, data enhancement, and the blending of data between two source applications. Moroever, the topic also explains last-mile ETL, a scenario in which data blending would be beneficial, key statistical measures, descriptive statistics, and discrete and continuous statistics.
|
| Topic 2 | - Data Management: The topic describes Delta Lake as a tool for managing data files, Delta Lake manages table metadata, benefits of Delta Lake within the Lakehouse, tables on Databricks, a table owner’s responsibilities, and the persistence of data. It also identifies management of a table, usage of Data Explorer by a table owner, and organization-specific considerations of PII data. Lastly, the topic it explains how the LOCATION keyword changes, usage of Data Explorer to secure data.
|
| Topic 3 | - SQL in the Lakehouse: It identifies a query that retrieves data from the database, the output of a SELECT query, a benefit of having ANSI SQL, access, and clean silver-level data. It also compares and contrasts MERGE INTO, INSERT TABLE, and COPY INTO. Lastly, this topic focuses on creating and applying UDFs in common scaling scenarios.
|
| Topic 4 | - Data Visualization and Dashboarding: Sub-topics of this topic are about of describing how notifications are sent, how to configure and troubleshoot a basic alert, how to configure a refresh schedule, the pros and cons of sharing dashboards, how query parameters change the output, and how to change the colors of all of the visualizations. It also discusses customized data visualizations, visualization formatting, Query Based Dropdown List, and the method for sharing a dashboard.
|
| Topic 5 | - Databricks SQL: This topic discusses key and side audiences, users, Databricks SQL benefits, complementing a basic Databricks SQL query, schema browser, Databricks SQL dashboards, and the purpose of Databricks SQL endpoints
- warehouses. Furthermore, the delves into Serverless Databricks SQL endpoint
- warehouses, trade-off between cluster size and cost for Databricks SQL endpoints
- warehouses, and Partner Connect. Lastly it discusses small-file upload, connecting Databricks SQL to visualization tools, the medallion architecture, the gold layer, and the benefits of working with streaming data.
|
>> Databricks Databricks-Certified-Data-Analyst-Associate Test Review <<
Databricks Databricks-Certified-Data-Analyst-Associate New Guide Files, Databricks-Certified-Data-Analyst-Associate Examcollection Questions Answers
before making a choice, you can download a trial version of Databricks-Certified-Data-Analyst-Associate preparation materials. After you use it, you will have a more complete understanding of this Databricks-Certified-Data-Analyst-Associate exam questions. In this way, you can use our Databricks-Certified-Data-Analyst-Associate study materials in a way that suits your needs and professional opinions. We hope you will have a great experience with Databricks-Certified-Data-Analyst-Associate Preparation materials. At the same time, we also hope that you can realize your dreams with our help. We will be honored.
Databricks Certified Data Analyst Associate Exam Sample Questions (Q42-Q47):
NEW QUESTION # 42
Which statement describes descriptive statistics?
- A. A branch of statistics that uses summary statistics to categorically describe and summarize data.
- B. A branch of statistics that uses quantitative variables that must take on a finite or countably infinite set of values.
- C. A branch of statistics that uses summary statistics to quantitatively describe and summarize data.
- D. A branch of statistics that uses a variety of data analysis techniques to infer properties of an underlying distribution of probability.
Answer: C
Explanation:
Descriptive statistics refer to statistical methods used to describe and summarize the basic features of data in a study. They provide simple summaries about the sample and the measures, often including metrics such as mean, median, mode, range, and standard deviation. Databricks learning materials highlight that descriptive statistics use summary statistics to quantitatively describe and summarize data, providing insight into data distributions without making inferences or predictions.
NEW QUESTION # 43
A data analyst wants to generate insights from large, complex datasets. The analyst needs to quickly understand the meaning of various data columns, ask questions in natural language, and receive AI-driven recommendations for optimizing data queries and workflows.
Which Databricks component is primarily responsible for enabling these capabilities?
- A. Genie Spaces
- B. Data Intelligence Engine
- C. Unity Catalog
- D. Databricks Assistant
Answer: B
Explanation:
Option A is correct. The Data Intelligence Engine is the platform-level intelligence layer that understands the semantics and uniqueness of an organization's data and enables AI-assisted experiences across Databricks.
Unity Catalog provides governance and metadata management, Genie Spaces provide a natural-language interface for curated business data, and Databricks Assistant is a user-facing assistant for code/query help.
However, the question asks which component is primarily responsible for enabling these capabilities across the platform; that is the Data Intelligence Engine. Databricks describes the platform as powered by a Data Intelligence Engine that understands the uniqueness and semantics of data and helps optimize performance.
References: Databricks Data Intelligence Platform documentation and Data Analyst Associate Exam Guide.
NEW QUESTION # 44
In which of the following situations should a data analyst use higher-order functions?
- A. When built-in functions need to run through the Catalyst Optimizer
- B. When custom logic needs to be applied at scale to array data objects
- C. When custom logic needs to be applied to simple, unnested data
- D. When custom logic needs to be converted to Python-native code
- E. When built-in functions are taking too long to perform tasks
Answer: B
Explanation:
Higher-order functions are a simple extension to SQL to manipulate nested data such as arrays. A higher-order function takes an array, implements how the array is processed, and what the result of the computation will be. It delegates to a lambda function how to process each item in the array. This allows you to define functions that manipulate arrays in SQL, without having to unpack and repack them, use UDFs, or rely on limited built-in functions. Higher-order functions provide a performance benefit over user defined functions. Reference: Higher-order functions | Databricks on AWS, Working with Nested Data Using Higher Order Functions in SQL on Databricks | Databricks Blog, Higher-order functions - Azure Databricks | Microsoft Learn, Optimization recommendations on Databricks | Databricks on AWS
NEW QUESTION # 45
Delta Lake stores table data as a series of data files, but it also stores a lot of other information.
Which of the following is stored alongside data files when using Delta Lake?
- A. Table metadata, data summary visualizations, and owner account information
- B. Data summary visualizations
- C. None of these
- D. Owner account information
- E. Table metadata
Answer: E
Explanation:
Delta Lake stores table data as a series of data files in a specified location, but it also stores table metadata in a transaction log. The table metadata includes the schema, partitioning information, table properties, and other configuration details. The table metadata is stored alongside the data files and is updated atomically with every write operation. The table metadata can be accessed using the DESCRIBE DETAIL command or the DeltaTable class in Scala, Python, or Java. The table metadata can also be enriched with custom tags or user-defined commit messages using the TBLPROPERTIES or userMetadata options. Reference:
Enrich Delta Lake tables with custom metadata
Delta Lake Table metadata - Stack Overflow
Metadata - The Internals of Delta Lake
NEW QUESTION # 46
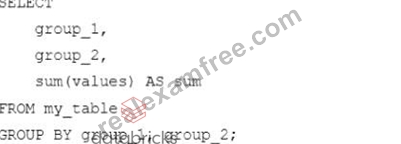
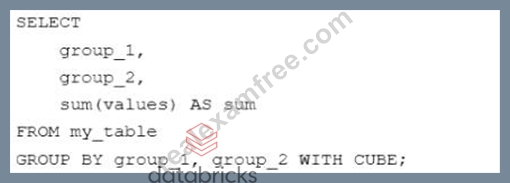
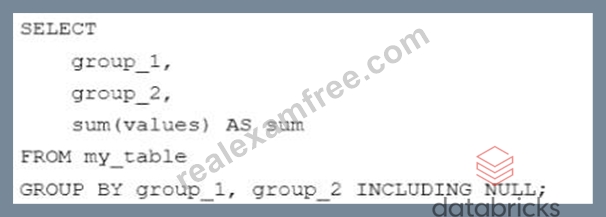
A data analyst is processing a complex aggregation on a table with zero null values and the query returns the following result:
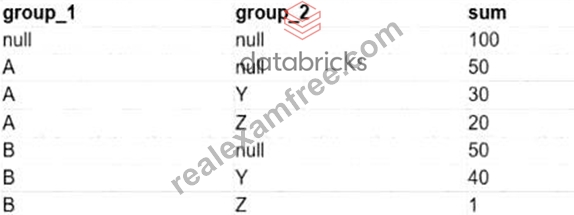
Which query did the analyst execute in order to get this result?
Answer: B
Explanation:
Option D is correct because the table has zero real null values, but the result contains null values representing subtotal and grand-total rows. That behavior is produced by WITH CUBE, which creates aggregations for combinations of grouping columns, including (group_1, group_2), (group_1), (group_2), and the grand total ().
The Databricks SQL documentation states that GROUP BY supports advanced aggregations through CUBE, and that CUBE is shorthand for grouping sets. Option A only returns detailed groups. Options B and C use invalid syntax in Databricks SQL. Reference: Databricks GROUP BY clause documentation.
NEW QUESTION # 47
......
Our Databricks-Certified-Data-Analyst-Associate learning materials provide multiple functions and considerate services to help the learners have no inconveniences to use our product. We guarantee to the clients if only they buy our Databricks-Certified-Data-Analyst-Associate study materials and learn patiently for some time they will be sure to pass the Databricks-Certified-Data-Analyst-Associate test with few failure odds. The pass rate of our Databricks-Certified-Data-Analyst-Associate exam questions is high as 98% to 100%, which is unique in the market. And the data also proved and tested the high-quality of our Databricks-Certified-Data-Analyst-Associate practice guide.
Databricks-Certified-Data-Analyst-Associate New Guide Files: https://www.realexamfree.com/Databricks-Certified-Data-Analyst-Associate-real-exam-dumps.html
- Actual Databricks Databricks-Certified-Data-Analyst-Associate Exam Questions and Answers 🥻 Search for 「 Databricks-Certified-Data-Analyst-Associate 」 and obtain a free download on ☀ www.prep4sures.top ️☀️ 🔀Valid Databricks-Certified-Data-Analyst-Associate Real Test
- Actual Databricks Databricks-Certified-Data-Analyst-Associate Exam Questions and Answers ✊ Search on ➠ www.pdfvce.com 🠰 for 《 Databricks-Certified-Data-Analyst-Associate 》 to obtain exam materials for free download 🍽Valid Braindumps Databricks-Certified-Data-Analyst-Associate Free
- Databricks-Certified-Data-Analyst-Associate Examcollection Dumps Torrent 🌑 Valid Databricks-Certified-Data-Analyst-Associate Exam Tutorial ♥ Valid Databricks-Certified-Data-Analyst-Associate Exam Tutorial 🍰 Search for ▷ Databricks-Certified-Data-Analyst-Associate ◁ and download it for free immediately on 【 www.vceengine.com 】 🌮Databricks-Certified-Data-Analyst-Associate Trustworthy Dumps
- Databricks-Certified-Data-Analyst-Associate Test Review Exam | Databricks-Certified-Data-Analyst-Associate New Guide Files – 100% free 🤘 Search for ☀ Databricks-Certified-Data-Analyst-Associate ️☀️ on ▛ www.pdfvce.com ▟ immediately to obtain a free download 👪Valid Test Databricks-Certified-Data-Analyst-Associate Bootcamp
- Valid Braindumps Databricks-Certified-Data-Analyst-Associate Free ⚓ Databricks-Certified-Data-Analyst-Associate Valid Exam Test 🦯 Reliable Databricks-Certified-Data-Analyst-Associate Exam Tutorial 📔 Copy URL ➽ www.exam4labs.com 🢪 open and search for ⮆ Databricks-Certified-Data-Analyst-Associate ⮄ to download for free 🃏Exam Databricks-Certified-Data-Analyst-Associate Questions Answers
- Top Databricks-Certified-Data-Analyst-Associate Test Review | Professional Databricks Databricks-Certified-Data-Analyst-Associate: Databricks Certified Data Analyst Associate Exam 100% Pass ⌨ Search for ➥ Databricks-Certified-Data-Analyst-Associate 🡄 and download it for free immediately on ▛ www.pdfvce.com ▟ 🏜Databricks-Certified-Data-Analyst-Associate Examcollection Dumps Torrent
- 100% Pass Quiz Databricks - Databricks-Certified-Data-Analyst-Associate - Perfect Databricks Certified Data Analyst Associate Exam Test Review 🐾 Search for [ Databricks-Certified-Data-Analyst-Associate ] and obtain a free download on ⏩ www.practicevce.com ⏪ 🐐Databricks-Certified-Data-Analyst-Associate Valid Test Book
- 100% Pass Quiz Databricks - Databricks-Certified-Data-Analyst-Associate - Perfect Databricks Certified Data Analyst Associate Exam Test Review ❕ Search for ➥ Databricks-Certified-Data-Analyst-Associate 🡄 and easily obtain a free download on ⇛ www.pdfvce.com ⇚ 🌘Exam Databricks-Certified-Data-Analyst-Associate Questions Answers
- Databricks-Certified-Data-Analyst-Associate Exam Reviews ➖ Exam Databricks-Certified-Data-Analyst-Associate Objectives Pdf 🛵 Databricks-Certified-Data-Analyst-Associate Official Cert Guide 🚧 Download “ Databricks-Certified-Data-Analyst-Associate ” for free by simply searching on ➡ www.testkingpass.com ️⬅️ 🎻Valid Databricks-Certified-Data-Analyst-Associate Exam Tutorial
- Databricks-Certified-Data-Analyst-Associate exam practice material - Databricks-Certified-Data-Analyst-Associate study training pdf - Databricks-Certified-Data-Analyst-Associate online test engine 🔩 Open “ www.pdfvce.com ” enter ⏩ Databricks-Certified-Data-Analyst-Associate ⏪ and obtain a free download 😗Databricks-Certified-Data-Analyst-Associate Valid Test Book
- Databricks-Certified-Data-Analyst-Associate Test Review Exam | Databricks-Certified-Data-Analyst-Associate New Guide Files – 100% free 📽 Search for ⏩ Databricks-Certified-Data-Analyst-Associate ⏪ on ⏩ www.exam4labs.com ⏪ immediately to obtain a free download 🌋Databricks-Certified-Data-Analyst-Associate Valid Test Book
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, mahsaamini5421.blogspot.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026 Latest RealExamFree Databricks-Certified-Data-Analyst-Associate PDF Dumps and Databricks-Certified-Data-Analyst-Associate Exam Engine Free Share: https://drive.google.com/open?id=1uvXhL8I8R3Y7ef4JMyJL6OL4dJpwMp7l