BONUS!!! Download part of Itexamguide DP-800 dumps for free: https://drive.google.com/open?id=1VIkLAPobnON5Ae-g6bl2p6yNt8u1X4jy
Living in such a world where competitiveness is a necessity that can distinguish you from others, every one of us is trying our best to improve ourselves in every way. It has been widely recognized that the DP-800 exam can better equip us with a newly gained personal skill, which is crucial to individual self-improvement in today’s computer era. With the certified advantage admitted by the test Microsoft certification, you will have the competitive edge to get a favorable job in the global market. Here our DP-800 Study Materials are tailor-designed for you.
| Section | Objectives |
|---|---|
| Topic 1: Design and implement data solutions | - Design database solutions using Azure data services - Implement data storage and data processing solutions |
| Topic 2: Monitor, troubleshoot, and maintain solutions | - Monitoring database health and performance - Troubleshooting data pipeline issues |
| Topic 3: Integrate AI capabilities with database systems | - Use Azure AI services with database workloads - Implement AI-assisted data processing |
| Topic 4: Develop and manage database solutions | - Optimize performance and scalability - Ensure security and compliance of data solutions |
>> DP-800 Updated Test Cram <<
DP-800 exam dumps save your study and preparation time. Our experts have added hundreds of Developing AI-Enabled Database Solutions (DP-800) questions similar to the real exam. You can prepare for the Developing AI-Enabled Database Solutions (DP-800) exam dumps during your job. You don't need to visit the market or any store because Itexamguide Developing AI-Enabled Database Solutions (DP-800) exam questions are easily accessible from the website.
NEW QUESTION # 85
Hotspot Question
You have a SQL database in Microsoft Fabric named SalesDB that contains a table named dbo.Products.
You need to modify SalesDB to meet the following requirements:
- Create a vector index on the appropriate column.
- Use a supplied natural language query vector.
How should you complete the Transact-SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.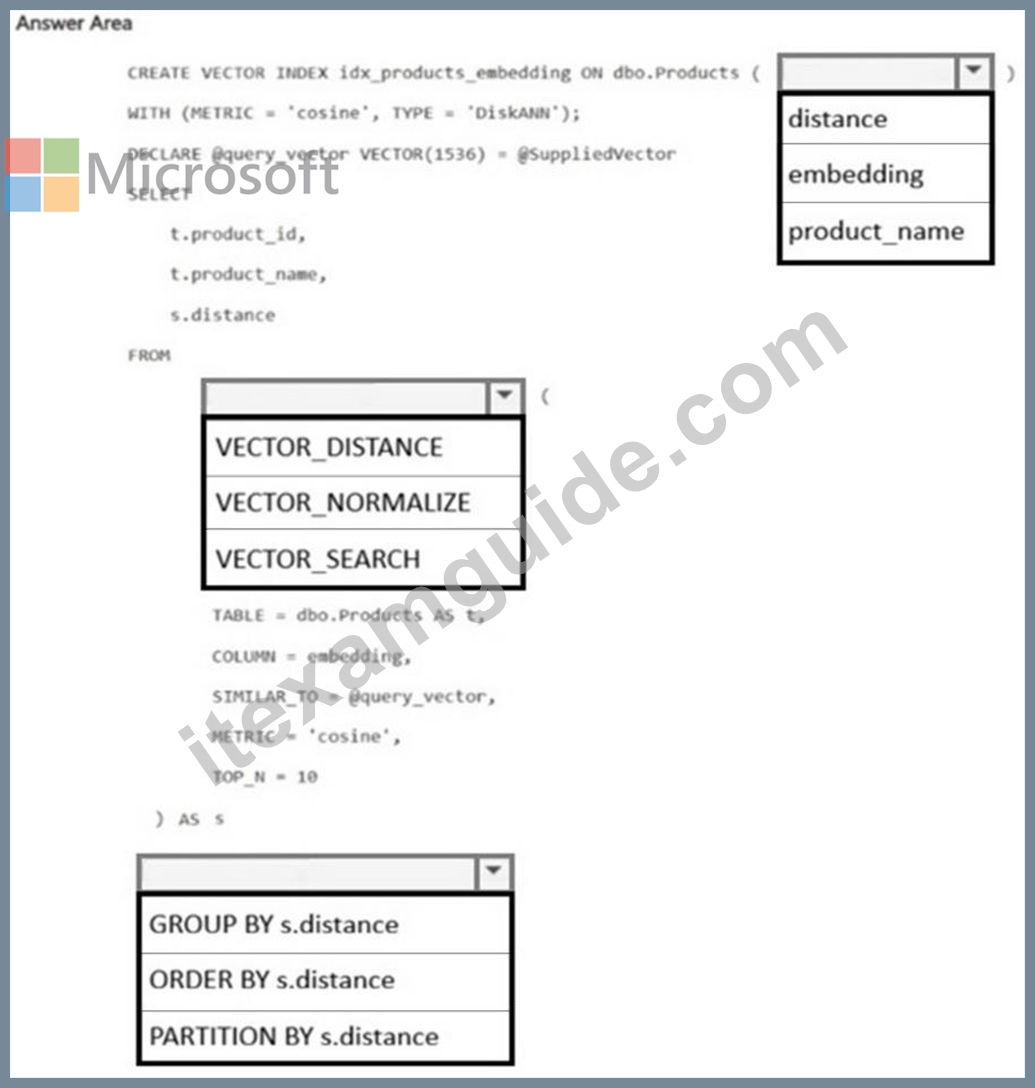
Answer:
Explanation: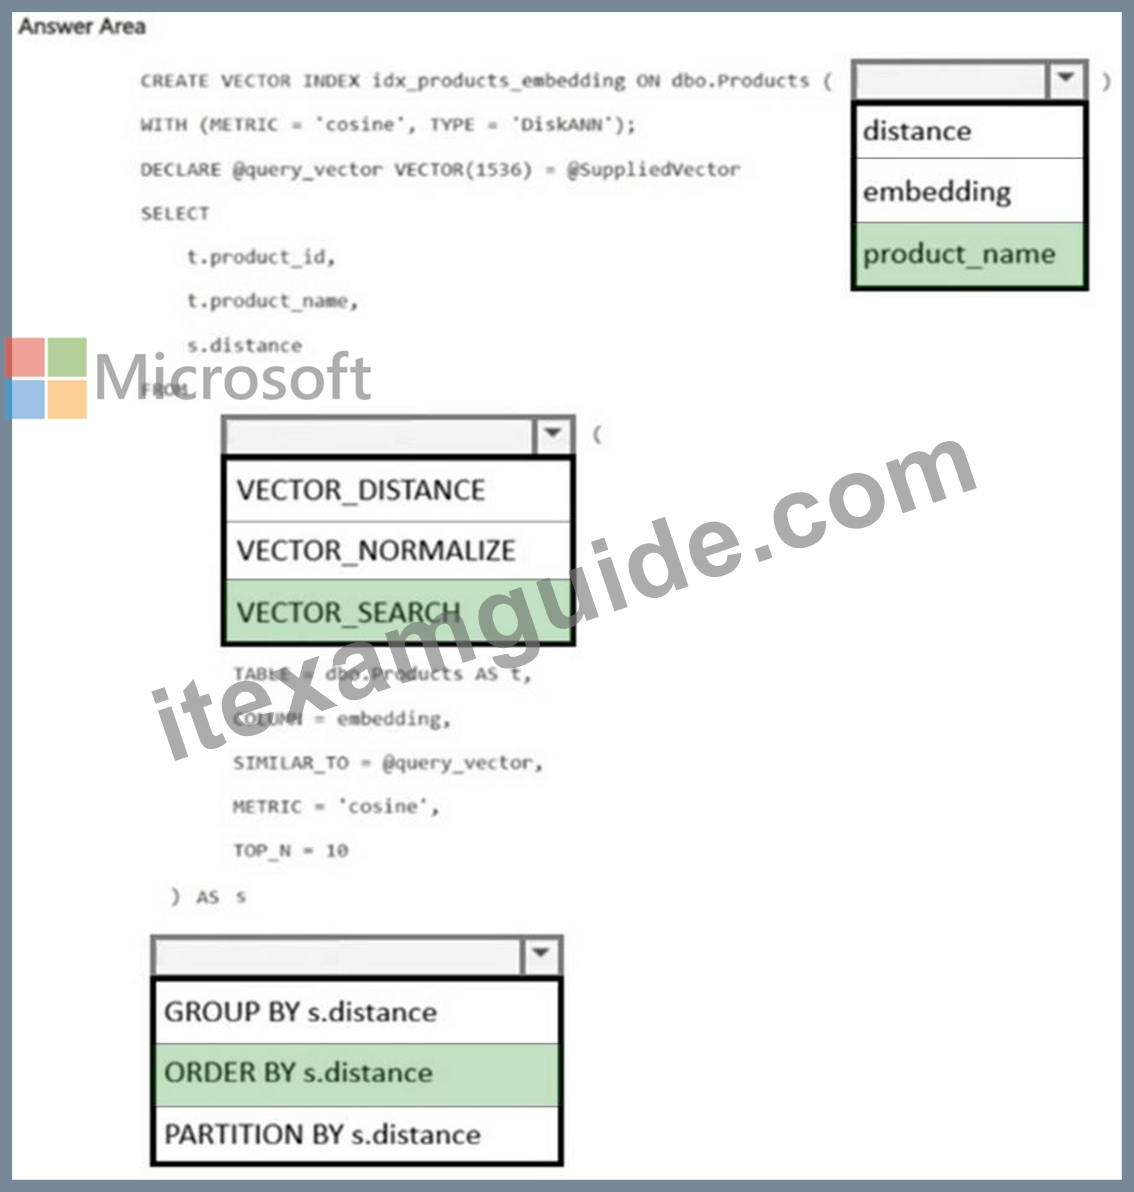
NEW QUESTION # 86
You need to create a solution that meets the development requirements for retrieving the patient lists.
How should you complete the Transact-SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.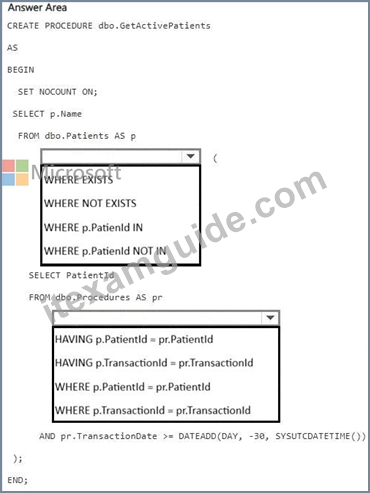
Answer:
Explanation: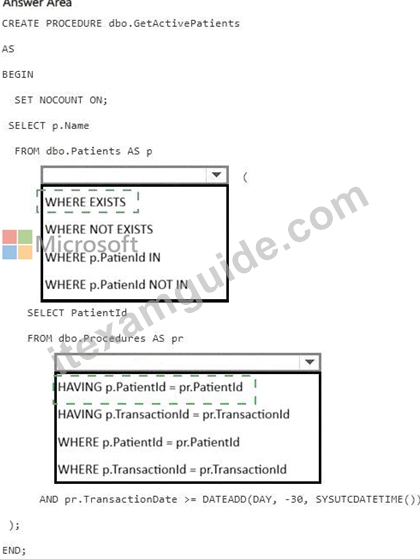
Explanation:
where exists 2. where p.PatientID = pr.PatientID Otherwise we filter PatientID twice. Having in the subquery does not work without group by and the date filter does not work without where.
NEW QUESTION # 87
You need to enable similarity search to provide the analysts with the ability to retrieve the most relevant health summary reports. The solution must minimize latency.
What should you include in the solution?
Answer: A
Explanation:
The correct answer is D because the requirement is to enable similarity search over embedding vectors and to minimize latency . Microsoft documents that CREATE VECTOR INDEX is specifically used to create an index on vector data for approximate nearest neighbor (ANN) search , which is designed to accelerate vector similarity queries compared to exact k-nearest-neighbor scans.
This matches the scenario exactly. The VehicleHealthSummary table already includes an Embeddings (vector (1536)) column. In Microsoft SQL platforms, embeddings are stored in vector columns and queried for semantic similarity. To improve performance and reduce response time, Microsoft recommends a vector index , not a regular B-tree nonclustered index and not a full-text index. A vector index is purpose-built for finding the most similar vectors efficiently.
The other options are not appropriate:
* A would require manual comparison logic and would increase latency rather than minimize it.
* B is incorrect because a standard nonclustered index is not the index type used for vector similarity operations.
* C is incorrect because full-text indexes are for textual token-based search, not numeric vector embeddings.
Microsoft's current documentation is explicit that vector indexes support approximate nearest neighbor search , and that the optimizer can use the ANN index automatically for vector queries. That is the exam- aligned design choice when the goal is fast retrieval of the most relevant health summary reports from an embeddings column.
Topic 2, Fabrikam Case
- To display the first question in this case study, click the Next button. Use the buttons in the left pane to explore the content of the case study before you answer the questions. Clicking these buttons displays information such as business requirements, existing environment and problem statements. If the case study has an All Information tab, note that the information displayed is identical to the information displayed on the subsequent tabs. When you are ready to answer a question, click the Question button to return to the question.
Existing Environment - Azure Environment - Fabrikam has a single Azure subscription in the East US 2 Azure region. The subscription contains an Azure SQL database named DB1. DB1 contains the following tables: * Patients * Employees * Procedures * Transactions * UsefulPrompts * ProcedureDocuments You store a column master key as a secret in Azure Key Vault. You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Problem Statements - Users report that after executing a long-running stored procedure named sp_UpdateProcedureForPatient, updates to the underlying data are sometimes inconsistent. Requirements - Planned Changes - Fabrikam plans to manage all changes to Azure SQL Database objects by using source control in GitHub. Every pull request submitted to production will be validated before it can be merged.
Deployments must use the Release configuration. Security Requirements - Fabrikam identifies the following security requirements: * The TransactionProcessing application must use a passwordless connection to DB1. * The Employees table contains two columns named TaxID and Salary that must be encrypted at rest. * Auditors must have a tamper-evident history of transactions with cryptographic proof of changes to the employee data. Database Performance Requirements Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
AI Search, Embeddings, and Vector Indexing Fabrikam identifies the following AI-related requirements: * Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF). * Users must be able to query the data in DB1 by using prompts in Copilot in Microsoft Fabric. * The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
Development Requirements - Fabrikam identifies the following development requirements: * Provide the functionality to retrieve all the transactions of a given patient between two dates, showing a running total. * Expose a Data API builder (DAB) configuration file to enable Azure services to perform the following operations over a REST API: o Read data from the procedures table without authentication. o Read and insert data into the Transactions table once authenticated. o Execute the sp_UpdateProcedurePatient stored procedure. * Provide the functionality to retrieve a list of the names of patients who underwent medical procedures during the last 30 days. * Information for each medical procedure will be stored in a table. The table will be used with a large language model (LLM) for user querying and will have the following structure.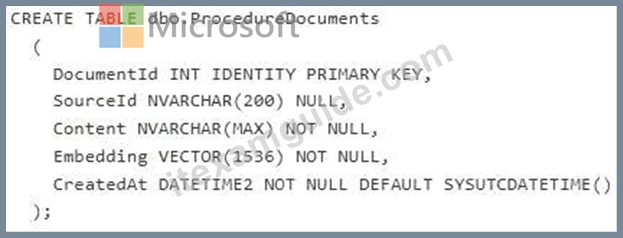
DAB
You create a DAB configuration file that meets the development requirements for DB1 and includes the following entities.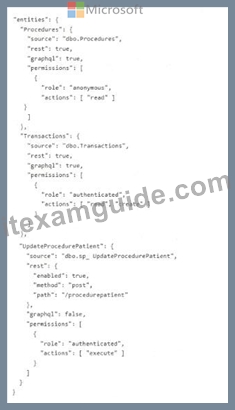
NEW QUESTION # 88
You have an Azure SQL database that contains a table named Sales.Orders. Sales.Orders contains the following columns.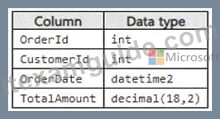
Reporting queries frequently repeat logic to calculate the number of days since an order was placed.
You need to create a scalar user-defined function (UDF) that returns the number of days between an input value of @OrderDate and the current date and time.
How should you complete the Transact-SQL code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.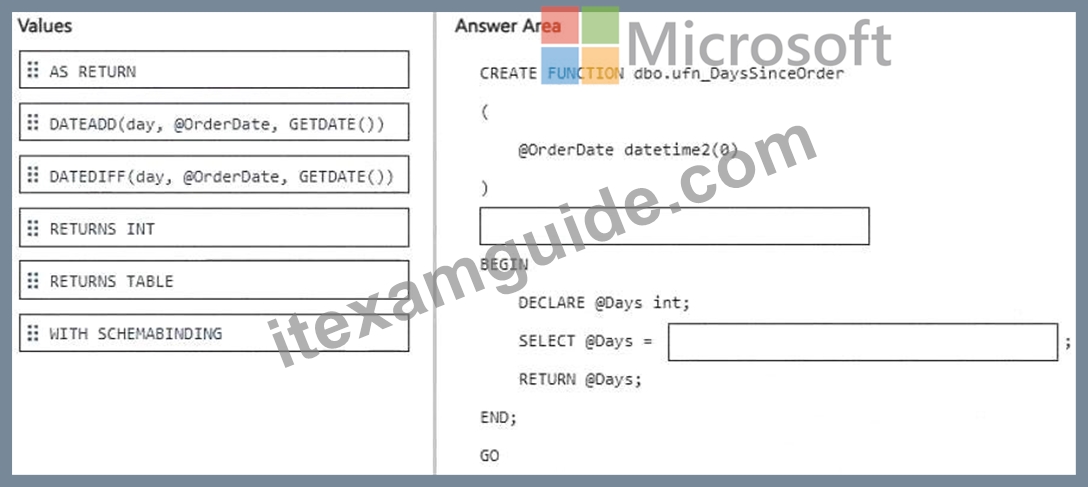
Answer:
Explanation: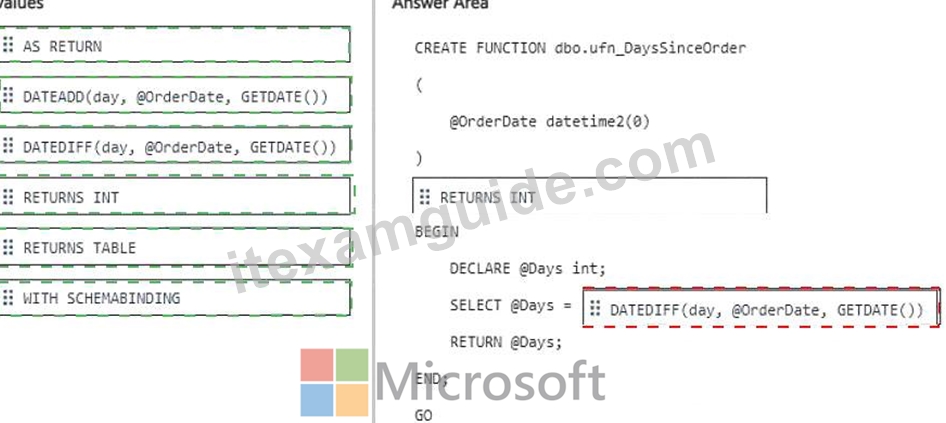
Explanation:
* Function return type # RETURNS INT
* Calculation # DATEDIFF(day, @OrderDate, GETDATE())
Comprehensive and Detailed Explanation with all Developing AI-Enabled Database Solutions documents : = The first correct selection is RETURNS INT because the requirement is to create a scalar UDF that returns a single integer representing the number of days since the order date. Microsoft documents that scalar user- defined functions return a single scalar value, and DATEDIFF returns an int value.
The second correct selection is:
DATEDIFF(day, @OrderDate, GETDATE())
Microsoft defines DATEDIFF(datepart, startdate, enddate) as returning the number of specified datepart boundaries crossed between two dates. Therefore, placing @OrderDate as the start date and GETDATE() as the end date returns the number of elapsed day boundaries from the order date to the current date and time.
GETDATE() is valid inside a Transact-SQL UDF. Microsoft explicitly lists GETDATE among the nondeterministic built-in functions that can be used in T-SQL user-defined functions . Its nondeterministic nature means the result changes over time, but it does not prevent creation of this scalar UDF.
The completed code is:
CREATE FUNCTION dbo.ufn_DaysSinceOrder
(
@OrderDate datetime2(0)
)
RETURNS INT
BEGIN
DECLARE @Days int;
SELECT @Days =
DATEDIFF(day, @OrderDate, GETDATE());
RETURN @Days;
END;
GO
So the drag-and-drop answers are:
* First target: RETURNS INT
* Second target: DATEDIFF(day, @OrderDate, GETDATE())
NEW QUESTION # 89
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.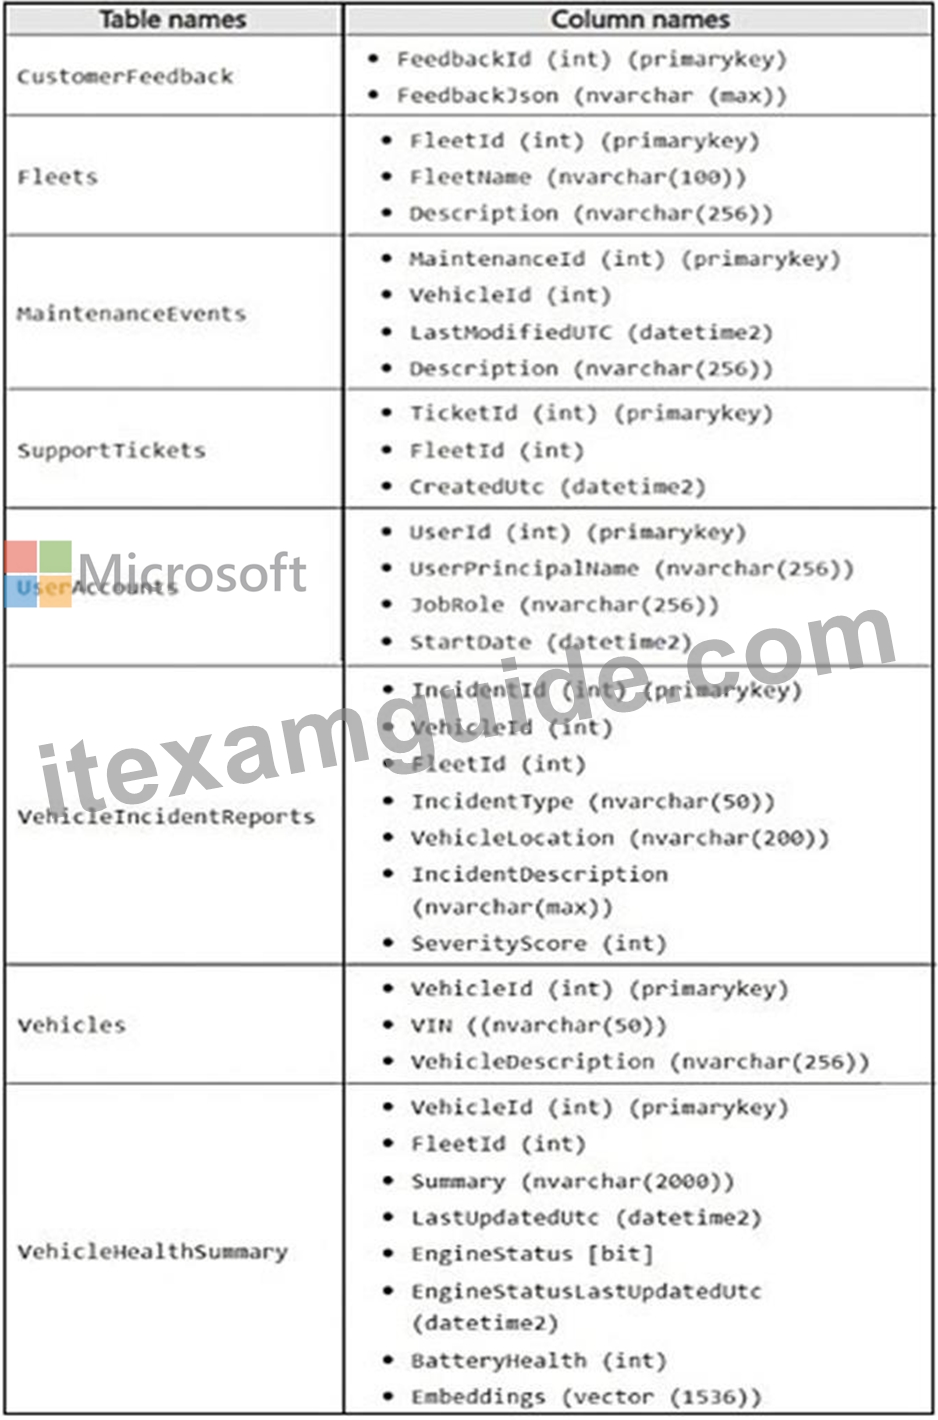
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.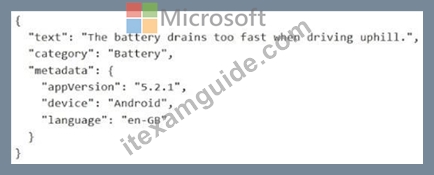
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.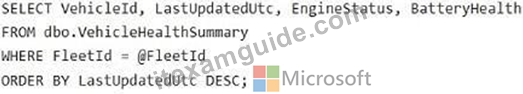
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
You need to recommend a solution that will resolve the ingestion pipeline failure issues.
Which two actions should you recommend? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,D
Explanation:
Scenario: Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
Adding a CHECK constraint with ISJSON and creating a unique index on a computed hash of the payload are effective measures in Azure SQL Database to handle malformed JSON and duplicate payloads.
[E]
JSON Validation with a CHECK Constraint
You can use a CHECK constraint in conjunction with the built-in ISJSON function to ensure that only valid JSON text is stored in a VARCHAR or NVARCHAR column. The constraint automatically rejects any insert or update operation that contains malformed JSON data, preventing pipeline failures due to invalid formatting at the database level.
[D]
Deduplication with a Unique Index on a Hashed Payload
To prevent duplicate payloads, you can create a unique index on a computed column that stores a hash of the entire JSON payload or relevant business keys within the JSON.
Reference:
https://www.shaped.ai/blog/10-best-practices-in-data-ingestion
NEW QUESTION # 90
......
You will need to pass the Developing AI-Enabled Database Solutions (DP-800) exam to achieve the Developing AI-Enabled Database Solutions (DP-800) certification. Due to extremely high competition, passing the Microsoft DP-800 exam is not easy; however, possible. You can use Itexamguide products to pass the DP-800 Exam on the first attempt. The Developing AI-Enabled Database Solutions (DP-800) practice exam gives you confidence and helps you understand the criteria of the testing authority and pass the Microsoft DP-800 exam on the first attempt.
DP-800 Test Topics Pdf: https://www.itexamguide.com/DP-800_braindumps.html
BONUS!!! Download part of Itexamguide DP-800 dumps for free: https://drive.google.com/open?id=1VIkLAPobnON5Ae-g6bl2p6yNt8u1X4jy