Test DP-700 Simulator Free, DP-700 Valid Exam Topics

BONUS!!! Download part of TestsDumps DP-700 dumps for free: https://drive.google.com/open?id=14VNO0FzGKZjmW3pw8JBCfq4Ym9A9djYW

This way you can get knowledge about the Microsoft DP-700 exam environment beforehand. Windows computers support the Microsoft DP-700 desktop practice exam software. It works offline whereas the web-based DP-700 Practice Test requires an active internet connection. Major browsers and operating systems support the online DP-700 mock exam.

Microsoft DP-700 Exam Syllabus Topics:

SectionWeightObjectives
Monitor and optimize an analytics solution30โ€“35%- Monitor analytics solutions
  • 1. Monitor Fabric items and activities
    • 2. Configure alerts and notifications
      • 3. Monitor data ingestion and transformation
        • 4. Monitor semantic model refreshes
          - Troubleshoot issues
          • 1. Identify and resolve storage and query errors
            • 2. Identify and resolve Dataflow errors
              • 3. Identify and resolve pipeline errors
                • 4. Identify and resolve notebook and Spark errors
                  - Optimize performance
                  • 1. Optimize storage efficiency
                    • 2. Optimize Spark and query performance
                      • 3. Optimize Lakehouse and data warehouse performance
                        • 4. Optimize pipelines and data flows
                          Ingest and transform data30โ€“35%- Ingest data
                          • 1. Ingest data using Eventstreams
                            • 2. Ingest data using Dataflows Gen2
                              • 3. Ingest data using pipelines
                                - Design and implement data loading patterns
                                • 1. Prepare data for dimensional models
                                  • 2. Design streaming data loading patterns
                                    • 3. Design full and incremental data loads
                                      - Transform data
                                      • 1. Clean, denormalize, and aggregate data
                                        • 2. Transform data using PySpark
                                          • 3. Transform data using KQL
                                            • 4. Transform data using SQL
                                              - Orchestrate data operations
                                              • 1. Implement schedules and triggers
                                                • 2. Orchestrate with notebooks and pipelines
                                                  • 3. Use parameters and dynamic expressions
                                                    Implement and manage an analytics solution30โ€“35%- Manage data storage
                                                    • 1. Choose appropriate data stores
                                                      • 2. Create and manage OneLake shortcuts
                                                        • 3. Implement data mirroring
                                                          - Manage data lifecycle and governance
                                                          • 1. Manage data access and security
                                                            • 2. Implement data governance with Microsoft Purview
                                                              • 3. Implement data retention and archiving
                                                                - Configure workspace settings
                                                                • 1. Configure OneLake workspace settings
                                                                  • 2. Configure Spark workspace settings
                                                                    • 3. Configure Microsoft Fabric workspace settings
                                                                      • 4. Configure domain workspace settings
                                                                        • 5. Configure Dataflows Gen2 settings

                                                                          >> Test DP-700 Simulator Free <<

                                                                          DP-700 Valid Exam Topics | Study DP-700 Material

                                                                          Obtaining an IT certification shows you are an ambitious individual who is always looking to improve your skill set. Most companies think highly of this character. Our DP-700 exam original questions will help you clear exam certainly in a short time. You don't need to worry about how difficulty the exams are. TestsDumps release the best high-quality DP-700 Exam original questions to help you most candidates pass exams and achieve their goal surely.

                                                                          Microsoft Implementing Data Engineering Solutions Using Microsoft Fabric Sample Questions (Q77-Q82):

                                                                          NEW QUESTION # 77
                                                                          DRAG DROP
                                                                          You have a Fabric eventhouse that contains a KQL database. The database contains a table named TaxiData.
                                                                          The following is a sample of the data in TaxiData.
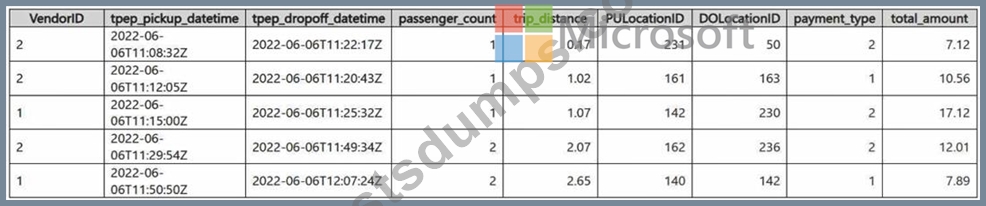
                                                                          You need to build two KQL queries. The solution must meet the following requirements:
                                                                          One of the queries must partition RunningTotalAmount by VendorID.
                                                                          The other query must create a column named FirstPickupDateTime that shows the first value of each hour from tpep_pickup_datetime partitioned by payment_type.
                                                                          How should you complete each query? To answer, drag the appropriate values the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
                                                                          NOTE: Each correct selection is worth one point.

                                                                          Answer:

                                                                          Explanation:
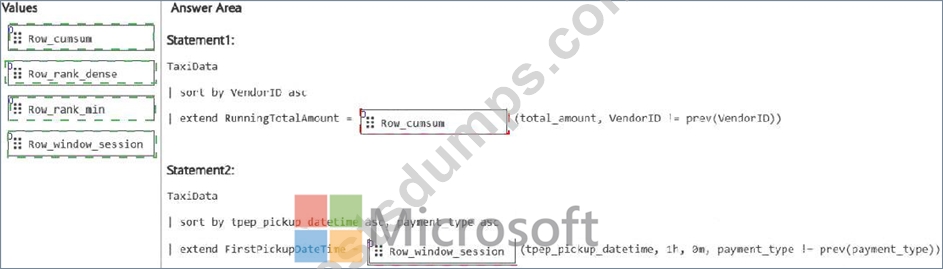
                                                                          Explanation:
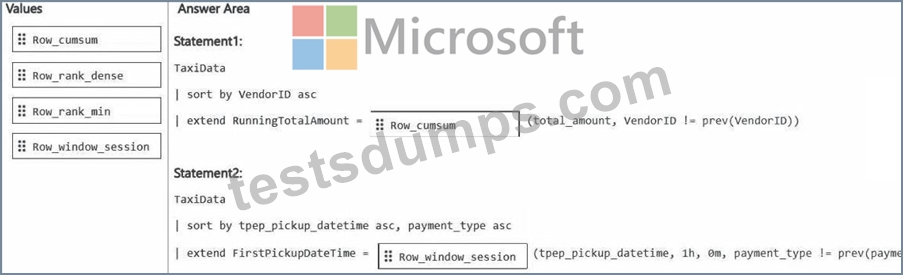
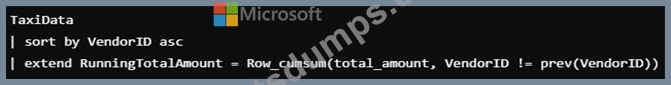
                                                                          Partition the RunningTotalAmount by VendorID. - Row_cumsum
                                                                          The Row_cumsum function computes the cumulative sum of a column while optionally restarting the accumulation based on a condition. In this case, it calculates the cumulative sum of total_amount for each VendorID, restarting when the VendorID changes (VendorID != prev(VendorID)).
                                                                          Create a column FirstPickupDateTime that shows the first value of each hour from tpep_pickup_datetime, partitioned by payment_type - Row_window_session


                                                                          NEW QUESTION # 78
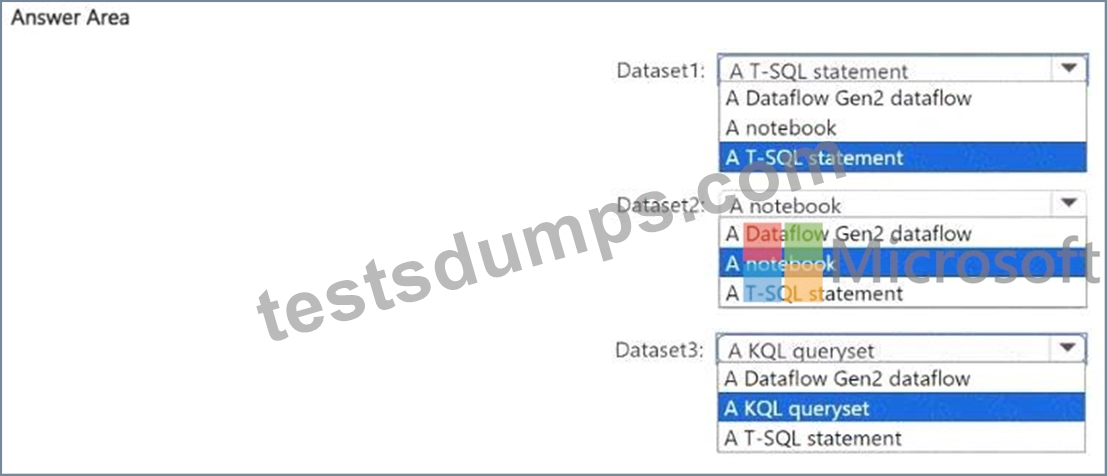
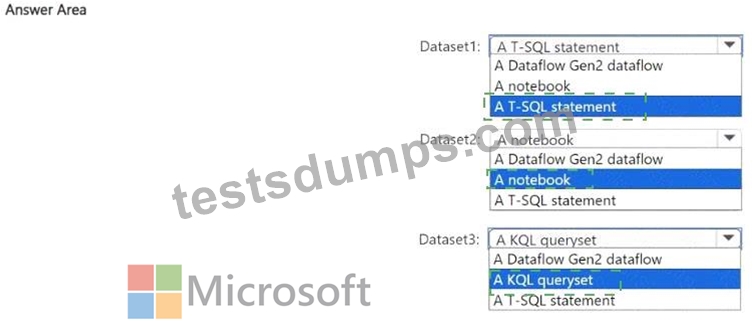
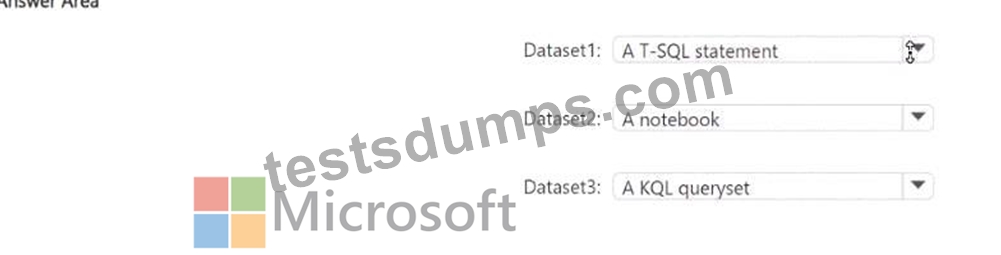
                                                                          You plan to process the following three datasets by using Fabric:
                                                                          * Dataset1: This dataset will be added to Fabric and will have a unique primary key between the source and the destination. The unique primary key will be an integer and will start from 1 and have an increment of 1.
                                                                          * Dataset2: This dataset contains semi-structured data that uses bulk data transfer. The dataset must be handled in one process between the source and the destination. The data transformation process will include the use of custom visuals to understand and work with the dataset in development mode.
                                                                          * Dataset3. This dataset is in a takehouse. The data will be bulk loaded. The data transformation process will include row-based windowing functions during the loading process.
                                                                          You need to identify which type of item to use for the datasets. The solution must minimize development effort and use built-in functionality, when possible. What should you identify for each dataset? To answer, select the appropriate options in the answer area.
                                                                          NOTE: Each correct selection is worth one point.
                                                                          Answer:

                                                                          Explanation:
                                                                          Explanation:

                                                                          NEW QUESTION # 79
                                                                          You have an Azure Data Lake Storage Gen2 account named storage1 and an Amazon S3 bucket named storage2.
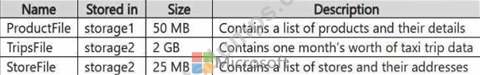
                                                                          You have the Delta Parquet files shown in the following table.
                                                                          You have a Fabric workspace named Workspace1 that has the cache for shortcuts enabled. Workspace1 contains a lakehouse named Lakehouse1. Lakehouse1 has the following shortcuts:
                                                                          The data from which shortcuts will be retrieved from the cache?

                                                                          Answer: E

                                                                          Explanation:
                                                                          When the cache for shortcuts is enabled in Fabric, the data retrieval is governed by the caching behavior, which generally retains data for a specific period after it was last accessed. The data from the shortcuts will be retrieved from the cache if the data is stored in locations that support caching. Here's a breakdown based on the data's location:
                                                                          Products: The ProductFile is stored in Azure Data Lake Storage Gen2 (storage1). Since Azure Data Lake is a supported storage system in Fabric and the file is relatively small (50 MB), this data is most likely cached and can be retrieved from the cache.
                                                                          Stores: The StoreFile is stored in Amazon S3 (storage2), and even though it is stored in a different cloud provider, Fabric can cache data from Amazon S3 if caching is enabled. This data (25 MB) is likely cached and retrievable.
                                                                          Trips: The TripsFile is stored in Amazon S3 (storage2) and is significantly larger (2 GB) compared to the other files. While Fabric can cache data from Amazon S3, the larger size of the file (2 GB) may exceed typical cache sizes or retention windows, causing this file to likely be retrieved directly from the source instead of the cache.


                                                                          NEW QUESTION # 80
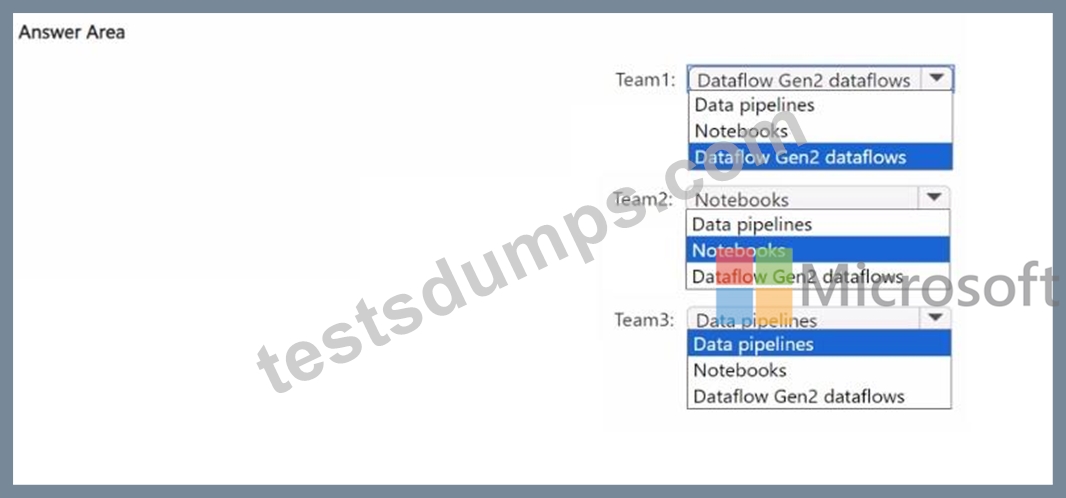
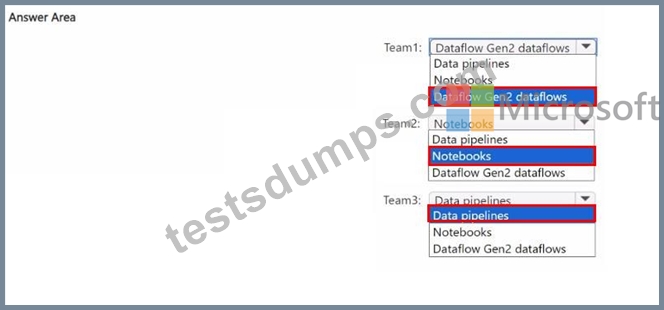
                                                                          Your company has three newly created data engineering teams named Team1, Team2, and Team3 that plan to use Fabric. The teams have the following personas:
                                                                          * Team1 consists of members who currently use Microsoft Power BI. The team wants to transform data by using by a low-code approach.
                                                                          * Team2 consists of members that have a background in Python programming. The team wants to use PySpark code to transform data.
                                                                          * Team3 consists of members who currently use Azure Data Factory. The team wants to move data between source and sink environments by using the least amount of effort.
                                                                          You need to recommend tools for the teams based on their current personas.
                                                                          What should you recommend for each team? To answer, select the appropriate options in the answer area.
                                                                          NOTE: Each correct selection is worth one point.
                                                                          Answer:

                                                                          Explanation:

                                                                          NEW QUESTION # 81
                                                                          You have a Fabric warehouse named DW1 that loads data by using a data pipeline named Pipeline1. Pipeline1 uses a Copy data activity with a dynamic SQL source. Pipeline1 is scheduled to run every 15 minutes.
                                                                          You discover that Pipeline1 keeps failing.
                                                                          You need to identify which SQL query was executed when the pipeline failed.
                                                                          What should you do?

                                                                          Answer: A

                                                                          Explanation:
                                                                          The input JSON contains the configuration details and parameters passed to the Copy data activity during execution, including the dynamically generated SQL query.
                                                                          Viewing the input JSON for the failed pipeline run provides direct insight into what query was executed at the time of failure.


                                                                          NEW QUESTION # 82
                                                                          ......

                                                                          Knowledge makes prominent contributions to human civilization and progress. In the 21st century, the rate of unemployment is increasing greatly. Many jobs are replaced by intelligent machines. You must learn practical knowledge such as our DP-700 actual test guide, which cannot be substituted by artificial intelligence. Now, our DP-700 learning prep can meet your demands. You will absorb the most useful knowledge with the assistance of our study materials. The DP-700 certificate is valuable in the job market. But you need professional guidance to pass the exam. For instance, our DP-700 exam questions fully accords with your requirements.

                                                                          DP-700 Valid Exam Topics: https://www.testsdumps.com/DP-700_real-exam-dumps.html

                                                                          DOWNLOAD the newest TestsDumps DP-700 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=14VNO0FzGKZjmW3pw8JBCfq4Ym9A9djYW