BONUS!!! Download part of DumpsMaterials Professional-Machine-Learning-Engineer dumps for free: https://drive.google.com/open?id=1cwZ5sGBCJqmxB9Ru8ZAYQkCWspHPvWmo
I know you must want to get a higher salary, but your strength must match your ambition! The opportunity is for those who are prepared! Professional-Machine-Learning-Engineer exam questions can help you improve your strength! You will master the most practical knowledge in the shortest possible time. It is also very easy if you want to get the Professional-Machine-Learning-Engineer certificate. As long as you buy our Professional-Machine-Learning-Engineer study braindumps and practice step by step, you are bound to pass the exam.
Google Professional Machine Learning Engineer Exam is a certification program offered by Google to individuals who possess the necessary skills and expertise in machine learning. Google Professional Machine Learning Engineer certification is designed to assess a candidate's ability to apply machine learning techniques to real-world problems and develop scalable, reliable, and efficient machine learning systems. Professional-Machine-Learning-Engineer Exam is intended for those who are already proficient in machine learning and are looking to validate their skills and knowledge in this field.
>> Valid Professional-Machine-Learning-Engineer Exam Voucher <<
We all harness talents with processional skills. Mastering the certificate of the Professional-Machine-Learning-Engineer practice exam is essential for you. With all instability of the society, those knowledge and profession certificate mean a lot for you. So it is unquestionable the Professional-Machine-Learning-Engineer learning questions of ours can do a big favor. And we have become the most popular exam braindumps provider in this career and supported by numerous of our loyal customers. You will be satisfied with our Professional-Machine-Learning-Engineer study guide as well.
The Google Professional-Machine-Learning-Engineer exam consists of multiple-choice and multiple-select questions, as well as case studies and hands-on labs. Professional-Machine-Learning-Engineer exam duration is two hours, and the passing score is 70%. Professional-Machine-Learning-Engineer Exam Fee is $200, and it can be taken remotely or at a testing center.
NEW QUESTION # 177
You have recently created a proof-of-concept (POC) deep learning model. You are satisfied with the overall architecture, but you need to determine the value for a couple of hyperparameters.
You want to perform hyperparameter tuning on Vertex AI to determine both the appropriate embedding dimension for a categorical feature used by your model and the optimal learning rate.
You configure the following settings:
- For the embedding dimension, you set the type to INTEGER with a
minValue of 16 and maxValue of 64.
- For the learning rate, you set the type to DOUBLE with a minValue of
10e-05 and maxValue of 10e-02.
You are using the default Bayesian optimization tuning algorithm, and you want to maximize model accuracy. Training time is not a concern. How should you set the hyperparameter scaling for each hyperparameter and the maxParallelTrials?
Answer: D
NEW QUESTION # 178
You trained a model on data stored in a Cloud Storage bucket. The model needs to be retrained frequently in Vertex AI Training using the latest data in the bucket. Data preprocessing is required prior to retraining. You want to build a simple and efficient near-real-time ML pipeline in Vertex AI that will preprocess the data when new data arrives in the bucket. What should you do?
Answer: C
Explanation:
Cloud Run can be triggered on new data arrivals, which makes it ideal for near-real-time processing. The function then initiates the Vertex AI Pipeline for preprocessing and storing features in Vertex AI Feature Store, aligning with the retraining needs. Cloud Scheduler (Option A) is suitable for scheduled jobs, not event- driven triggers. Dataflow (Option C) is better suited for batch processing or ETL rather than ML preprocessing pipelines.
NEW QUESTION # 179
You are designing an architecture with a serverless ML system to enrich customer support tickets with informative metadata before they are routed to a support agent. You need a set of models to predict ticket priority, predict ticket resolution time, and perform sentiment analysis to help agents make strategic decisions when they process support requests. Tickets are not expected to have any domain-specific terms or jargon.
The proposed architecture has the following flow: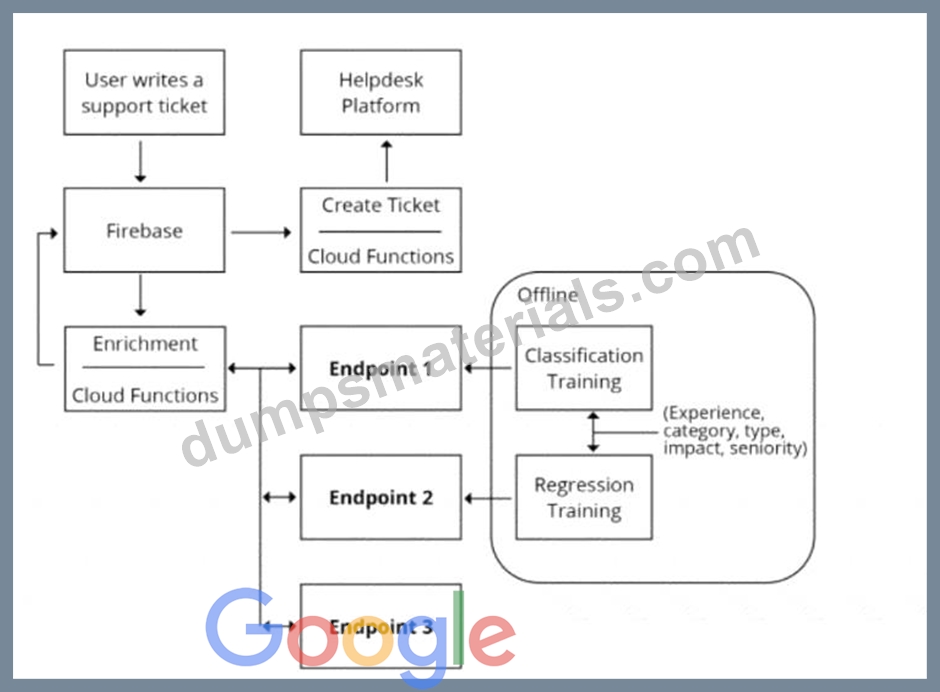
Which endpoints should the Enrichment Cloud Functions call?
Answer: D
Explanation:
Vertex AI is a unified platform for building and deploying ML models on Google Cloud. It supports both custom and AutoML models, and provides various tools and services for ML development, such as Vertex Pipelines, Vertex Vizier, Vertex Explainable AI, and Vertex Feature Store. Vertex AI can be used to create models for predicting ticket priority and resolution time, as these are domain-specific tasks that require custom training data and evaluation metrics. Cloud Natural Language API is a pre-trained service that provides natural language understanding capabilities, such as sentiment analysis, entity analysis, syntax analysis, and content classification. Cloud Natural Language API can be used to perform sentiment analysis on the support tickets, as this is a general task that does not require domain-specific knowledge or jargon. The other options are not suitable for the given architecture. AutoML Natural Language and AutoML Vision are services that allow users to create custom natural language and vision models using their own data and labels. They are not needed for sentiment analysis, as Cloud Natural Language API already provides this functionality. Cloud Vision API is a pre-trained service that provides image analysis capabilities, such as object detection, face detection, text detection, and image labeling. It is not relevant for the support tickets, as they are not expected to have any images. References:
* Vertex AI documentation
* Cloud Natural Language API documentation
NEW QUESTION # 180
You are working on a binary classification ML algorithm that detects whether an image of a classified scanned document contains a company's logo. In the dataset, 96% of examples don't have the logo, so the dataset is very skewed. Which metrics would give you the most confidence in your model?
Answer: C
Explanation:
* Option A is correct because using F-score where recall is weighed more than precision is a suitable metric for binary classification with imbalanced data. F-score is a harmonic mean of precision and recall, which are two metrics that measure the accuracy and completeness of the positive class1. Precision is the fraction of true positives among all predicted positives, while recall is the fraction of true positives among all actual positives1. When the data is imbalanced, the positive class is the minority class, which is usually the class of interest. For example, in this case, the positive class is the images that contain the company's logo, which are rare but important to detect. By weighing recall more than precision, we can emphasize the importance of finding all the positive examples, even if some false positives are included2.
* Option B is incorrect because using RMSE (root mean squared error) is not a valid metric for binary classification with imbalanced data. RMSE is a metric that measures the average magnitude of the errors between the predicted and actual values3. RMSE is suitable for regression problems, where the target variable is continuous, not for classification problems, where the target variable is discrete4.
* Option C is incorrect because using F1 score is not the best metric for binary classification with imbalanced data. F1 score is a special case of F-score where precision and recall are equally weighted1. F1 score is suitable for balanced data, where the positive and negative classes are equally important and frequent5. However, for imbalanced data, the positive class is more important and less frequent than the negative class, so F1 score may not reflect the performance of the model well2.
* Option D is incorrect because using F-score where precision is weighed more than recall is not a good metric for binary classification with imbalanced data. By weighing precision more than recall, we can emphasize the importance of minimizing the false positives, even if some true positives are missed2. However, for imbalanced data, the true positives are more important and less frequent than the false positives, so this metric may not reflect the performance of the model well2.
References:
* Precision, recall, and F-measure
* F-score for imbalanced data
* RMSE
* Regression vs classification
* F1 score
* [Imbalanced classification]
* [Binary classification]
NEW QUESTION # 181
You are using Kubeflow Pipelines to develop an end-to-end PyTorch-based MLOps pipeline. The pipeline reads data from BigQuery, processes the data, conducts feature engineering, model training, model evaluation, and deploys the model as a binary file to Cloud Storage. You are writing code for several different versions of the feature engineering and model training steps, and running each new version in Vertex Al Pipelines.
Each pipeline run is taking over an hour to complete. You want to speed up the pipeline execution to reduce your development time, and you want to avoid additional costs. What should you do?
Answer: D
Explanation:
Kubeflow Pipelines allows for efficient use of compute resources through parallel task execution and caching, which eliminates redundant executions1. By enabling caching in all the steps of the Kubeflow pipeline, you can avoid re-running the same steps when you execute the pipeline multiple times. This can significantly speed up the pipeline execution and reduce your development time without incurring additional costs
NEW QUESTION # 182
......
Professional-Machine-Learning-Engineer Latest Exam Preparation: https://www.dumpsmaterials.com/Professional-Machine-Learning-Engineer-real-torrent.html
P.S. Free & New Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by DumpsMaterials: https://drive.google.com/open?id=1cwZ5sGBCJqmxB9Ru8ZAYQkCWspHPvWmo