DOWNLOAD the newest PDFDumps SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1rnJcnY0B-nd2eOAtlZY8VJMaQTyk0nys
Cracking the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam brings high-paying jobs, promotions, and validation of talent. Dozens of Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam applicants don't get passing scores in the real SPS-C01 exam because of using invalid Snowflake SPS-C01 exam dumps. Failure in the SPS-C01 Exam leads to a loss of time, money, and confidence. If you are an applicant for the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam, you can prevent these losses by using the latest real SPS-C01 exam questions of PDFDumps.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Transformations and DataFrame Operations | 35% | - Filtering, Aggregating, and Joining DataFrames - Complex data pipelines - Window functions - Using built-in functions - Persisting transformed data |
| Topic 2: Snowpark Concepts | 15% | - Client-side vs. Server-side execution - Snowpark DataFrames and query plans - Transformations vs. Actions - Snowpark architecture and core concepts - Snowpark Sessions and connection management - Stored procedures and conditional logic |
| Topic 3: Performance Optimization and Best Practices | 20% | - Warehouse sizing for Snowpark - Vectorized UDFs - Debugging and explain plans - Query pushdown and optimization - Caching strategies - Minimizing data transfer |
| Topic 4: Snowpark API for Python | 30% | - User-Defined Functions (UDFs) and Stored Procedures - Working with Semi-structured data - Establishing connections and session management - DataFrame creation and manipulation - Reading and writing data |
>> Reliable SPS-C01 Real Exam <<
PDFDumps provides you with free demos of its Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 exam product. You can try a free demo to eliminate any confusion regarding the authenticity of our Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 PDF and practice tests (web-based & desktop software). It is also our policy to facilitate you with SPS-C01 free actual dumps updates in case of new Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 test changes within three months of your shopping. Contact us any time, if you need any guidance about our Snowflake SPS-C01 exam product. There is only one way to get all these amazing SPS-C01 exam dumps offers and that is purchasing our product today.
NEW QUESTION # 301
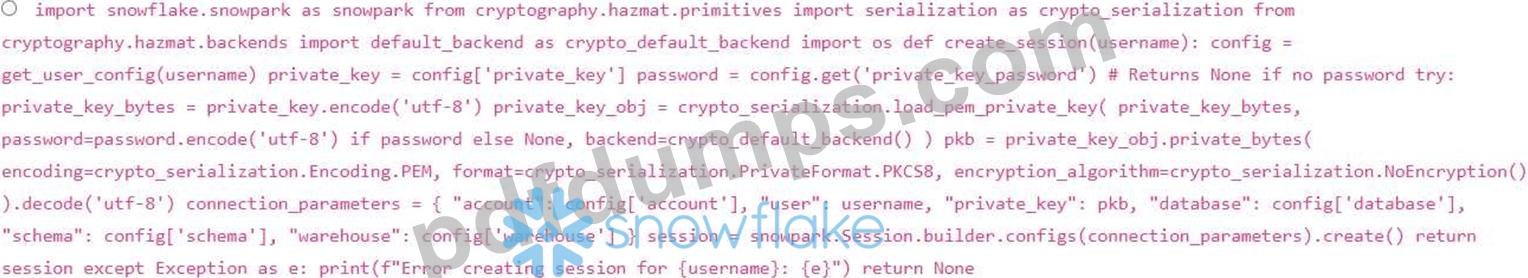
You are tasked with automating the creation of Snowpark sessions using key pair authentication for multiple users. You have a function that retrieves connection parameters (account, user, private key, etc.) for each user from a secure configuration file. The private keys are stored in PEM format. However, some users' private keys are password-protected. Which of the following approaches ensures the secure and correct establishment of Snowpark sessions for all users, including those with password-protected private keys? Assume get_user config(username)' retrieves the user's configuration, including the private key and password (if any).

Answer: A
Explanation:
Option C is the most secure and correct approach. It handles both password-protected and non-password-protected private keys gracefully using the 'cryptography' library, without storing passwords in memory or requiring users to compromise their security. It attempts to load the private key with the password (if provided), and if no password is provided, it defaults to 'None'. Options A and D have security vulnerabilities associated with storing or prompting for passwords. Option B forces users to weaken security. Option E doesn't consider password protected private keys.
NEW QUESTION # 302
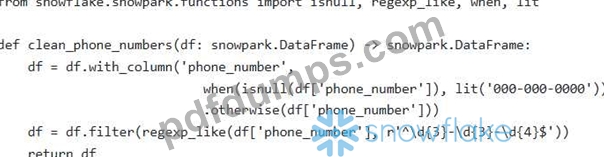
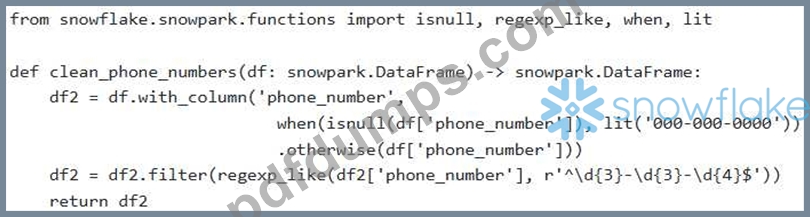
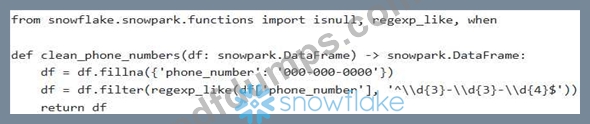
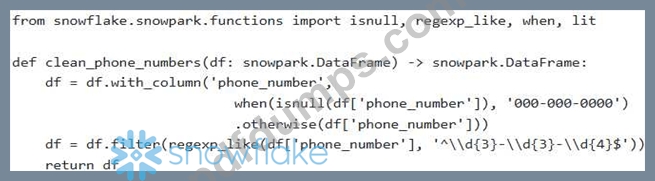
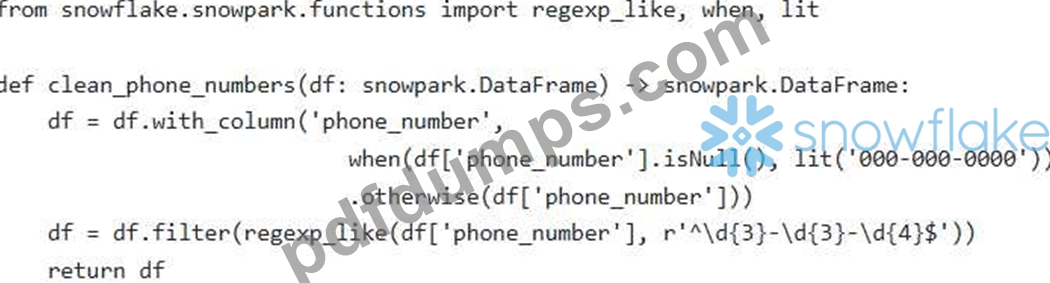
You are working with a Snowpark DataFrame containing customer data, including a 'phone_number' column. Some phone numbers are missing or have incorrect formats. You want to impute missing values with a default phone number '000-000-0000' and remove any phone numbers that do not match the pattern 'XXX-XXX-XXXX' using Snowpark Python. Which of the following code snippets achieves this most efficiently?
Answer: A
Explanation:
Option E is correct. It uses 'when' with 'isnull' to impute missing phone numbers and 'regexp_like' to filter out invalid formats. Options A and B are similar but less explicit. Option C omits 'lit', which makes the code incorrect as it won't work with Snowpark. Option D does not use 'lit' and also 'fillna' will give an exception if datatypes doesnt match
NEW QUESTION # 303
You are working with a Snowpark DataFrame representing sensor data. The DataFrame contains columns like 'timestamp', 'sensor id' , and 'value'. You need to perform a complex windowing operation to calculate the moving average of the 'value' for each 'sensor id' over a 5-minute window, but only for data points where the 'value' is greater than a threshold. The window should be defined based on the 'timestamp' column. What is the most efficient and correct approach to implement this using Snowpark DataFrames?
Answer: D
Explanation:
The most efficient and correct approach is to use Snowpark's built-in windowing functions. Applying the threshold using 'filter' before the windowing operation reduces the amount of data processed by the window function, improving performance. Using 'Window.partitionBy' and 'Window.orderBy' correctly defines the window based on 'sensor_id' and 'timestamp', respectively. Using 'avg' window function calculates the moving average within the defined window. Options B, C, and D are less efficient because they involve transferring data to the client side (Pandas) or using UDFs, which can introduce overhead. Option E reverses the correct process.
NEW QUESTION # 304
You have a Snowpark Python application that reads data from a Snowflake table, performs a complex transformation using a User- Defined Table Function (UDTF), and then writes the transformed data back to a new Snowflake table. The UDTF is defined as follows: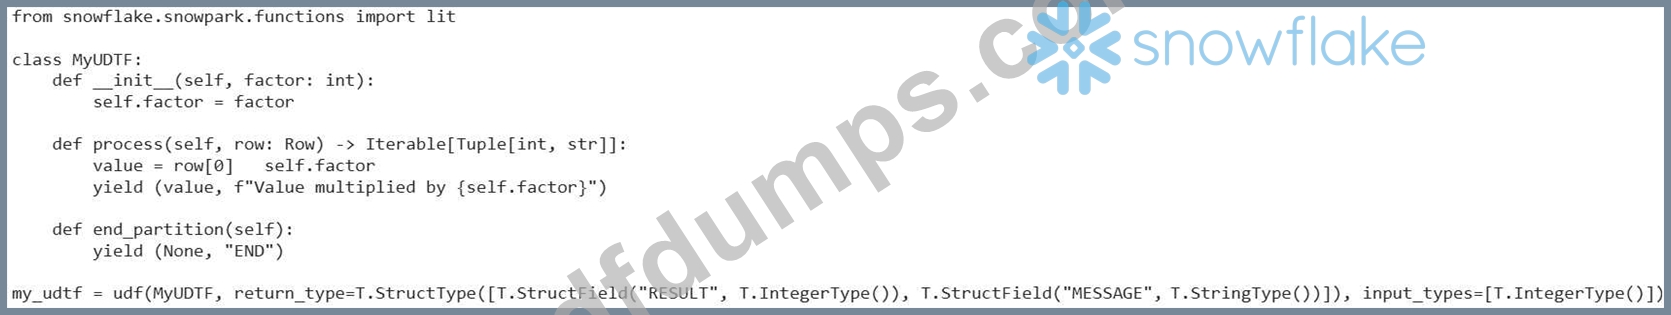
You need to optimize the performance of this application. Which of the following strategies would be MOST effective in reducing the execution time of the UDTF?
Answer: E
Explanation:
Vectorized UDTFs process data in batches, which can significantly improve performance compared to processing each row individually. This is especially true for complex transformations. Increasing warehouse size (A) can help but might not be as efficient as vectorization. Reducing input data (B) is always a good practice, but vectorization provides a more direct performance boost to the UDTF execution. Standard UDFs (D) are not generally faster than UDTFs, especially when dealing with table transformations. Caching (E) can help if the DataFrame is reused multiple times, but it doesn't directly optimize the UDTF's performance.
NEW QUESTION # 305
You are working with a Snowpark DataFrame named containing information about products, including 'CATEGORY , 'SUBCATEGORY , and 'PRICE'. You want to determine the maximum price for each subcategory within each category. Furthermore, you need to filter the results to only include categories that have more than 5 subcategories. Which of the following Snowpark Python code snippets accomplishes this task? (Select all that apply)





Answer: C,D
Explanation:
The correct options are D and E. They both address the requirement and count distinct subcategories within each category. Option D: Correctly calculates the maximum price for each subcategory within each category. Then separately calculates the count of DISTINCT subcategories for each category. Filters the categories to include only those with more than 5 subcategories. Joins the two resulting DataFrames to provide the final output. This is a standard and explicit way to accomplish the task. Using countDistinct to ensure each subcategory is only counted once. Option E: Aggregates Max Price and CountDistinct of subcategory into same dataframe, this addresses all requirements in a more concise manner. Option A: Does not give the right result since 'count' will not give the countDistinct. Also using 'COUNT(SUBCATEGORYV in category_countS dataframe results in count of all rows in the group instead of the number of groups (number of Subcategories). Option B: Window functions is irrelevant here, and requires more coding while can be handled efficiently by aggregating and countDistinct combination Option C: Option C doesn't aggregate maximum price for each subcategory within each category as the question mentions.
NEW QUESTION # 306
......
For one thing, the most advanced operation system in our company which can assure you the fastest delivery speed, and your personal information will be encrypted automatically by our operation system. For another thing, with the online app version of our SPS-C01 actual exam, you can just feel free to practice the questions in our training materials on all kinds of electronic devices. In addition, under the help of our SPS-C01 Exam Questions, the pass rate among our customers has reached as high as 98% to 100%. We are look forward to become your learning partner in the near future.
Reliable Exam SPS-C01 Pass4sure: https://www.pdfdumps.com/SPS-C01-valid-exam.html
DOWNLOAD the newest PDFDumps SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1rnJcnY0B-nd2eOAtlZY8VJMaQTyk0nys