Our AI-500 study materials are willing to stand by your side and provide attentive service, and to meet the majority of customers, we sincerely recommend our study materials to all customers, for our rich experience and excellent service are more than you can imagine. There are a lot of advantages of AI-500 training guide for your reference. And there are three versions of different AI-500 exam questions for you to choose: the PDF, Soft and APP online. You can free download the demos to decide which one to choose.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Topic 2: Develop multi-agent solutions in Azure | 30-35% | - Design and implement agent memory, context management, and knowledge integration
|
| Topic 3: Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement security
|
| Topic 4: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Evaluate solution quality
|
>> AI-500 Exam Passing Score <<
As a busy working person it will cost a lot of time and energy to prepare for upcoming test, what's to be done? You can try our latest Microsoft AI-500 practice exam online materials. You can know more about exam information and master all valid exam key knowledge points. AI-500 Practice Exam Online is excellent product of all examination questions with high passing rate. It will improve your studying efficiency and low exam cost.
NEW QUESTION # 73
You have a Microsoft Foundry multi-agent solution that includes the following agents:
* An orchestration agent
* An external risk-review agent operated by a partner organization
The partner agent runs in a different framework, exposes its own endpoint, and manages long-running review tasks. You need to identify an integration approach for the partner agent. The solution must meet the following requirements:
* Use authenticated and auditable access for structured tools and data
* Support capability discovery and task tracking for the partner agent.
* Prevent coupling the solution to the partner agent implementation.
What should you identify?
Answer: A
Explanation:
The partner component is an independently hosted agent running a different framework and managing long- running tasks. Agent-to-Agent (A2A) is designed for exactly this inter-agent boundary. It exposes a standards- based endpoint, supports capability discovery through agent cards, and provides task/context identifiers for long-running interactions without requiring the calling solution to know the partner ' s internal implementation. MCP primarily exposes tools and resources to an agent rather than representing a remote autonomous agent with its own task lifecycle. Platform-native subagent orchestration and in-process agent-as- tool composition would also couple the solution to a specific runtime or process boundary. Because the requirement is interoperable agent communication plus capability discovery and task tracking, A2A is the correct integration approach. This choice also keeps the design composable as more agents are introduced.
Clear interfaces, trust boundaries, and state ownership let a team change one domain without forcing unrelated agents to adopt the same permissions, context, or execution model.
Official Microsoft reference: Microsoft Agent Framework - Agent-to-Agent provider
NEW QUESTION # 74
You have a Microsoft Foundry multi-agent assistant that uses a Retrieval-Augmented Generation (RAG)- enabled workflow. A retrieval agent returns document chunks to an answer agent, and the answer agent produces the final response.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in RAG evaluators that meet the following requirements:
* Identify final responses that include content that is NOT supported by the retrieved context.
* Assess whether the retrieved context chunks and final responses support the user query.
Which evaluator should you use for each requirement? To answer, drag the appropriate evaluators to the correct requirements. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.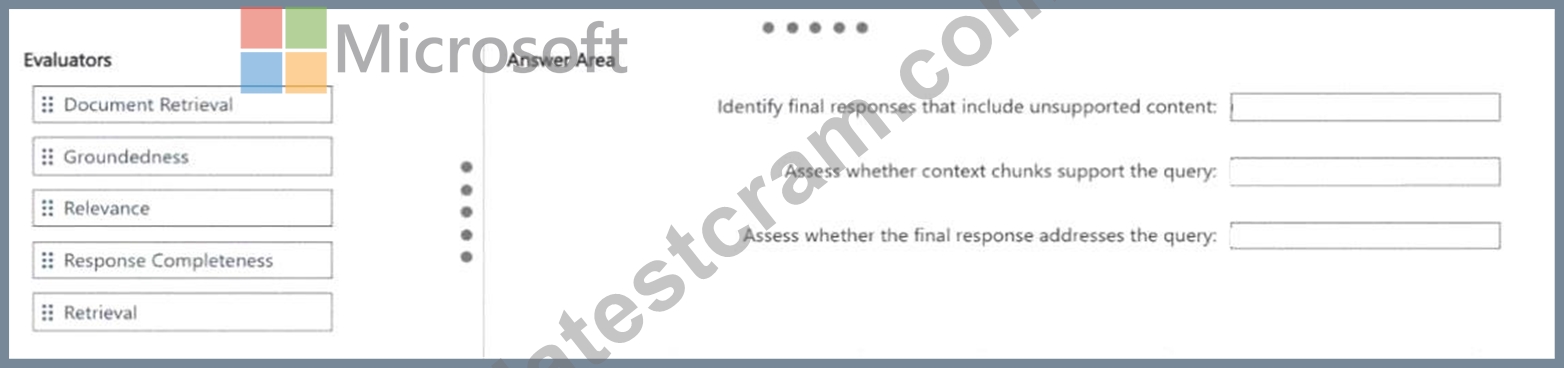
Answer:
Explanation: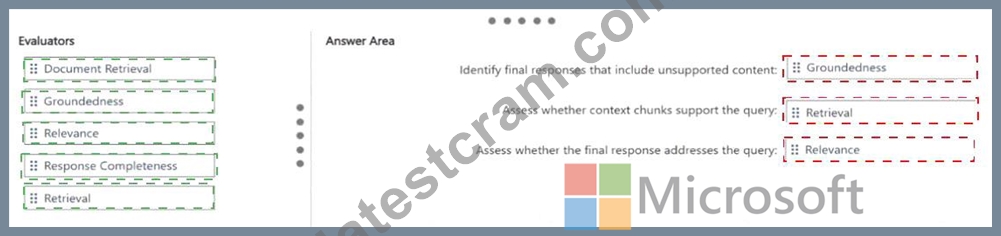
Explanation:
Unsupported final-response content: Groundedness; Context support for the query: Retrieval; Final- response support for the query: Relevance.
Groundedness detects whether the generated response contains claims that are not supported by the retrieved context, which directly matches the first requirement. Retrieval evaluates how relevant the provided context chunks are to the query when no document relevance ground truth is available. Relevance evaluates whether the final response directly and adequately answers the query. Microsoft Foundry separates these metrics so teams can diagnose whether a poor RAG result originated in retrieval or generation. Document Retrieval would require labeled retrieval ground truth, which the question explicitly says is absent. Response Completeness likewise depends on expected/ground-truth information. The supplied Groundedness, Retrieval, and Relevance mapping therefore matches the documented evaluator inputs and purposes. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
NEW QUESTION # 75
You have a Microsoft Foundry ticket-triage solution that uses connected agents. Each subagent prompt includes instructions for allowed tools and a JSON handoff.
You need to add automated prompt evaluations. The solution must identify changes that cause the subagents to do the following:
* Skip mandated evidence gathering.
* Return payloads that downstream agents cannot process.
* Handle work outside their assigned responsibilities.
How should you configure the evaluation suite? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.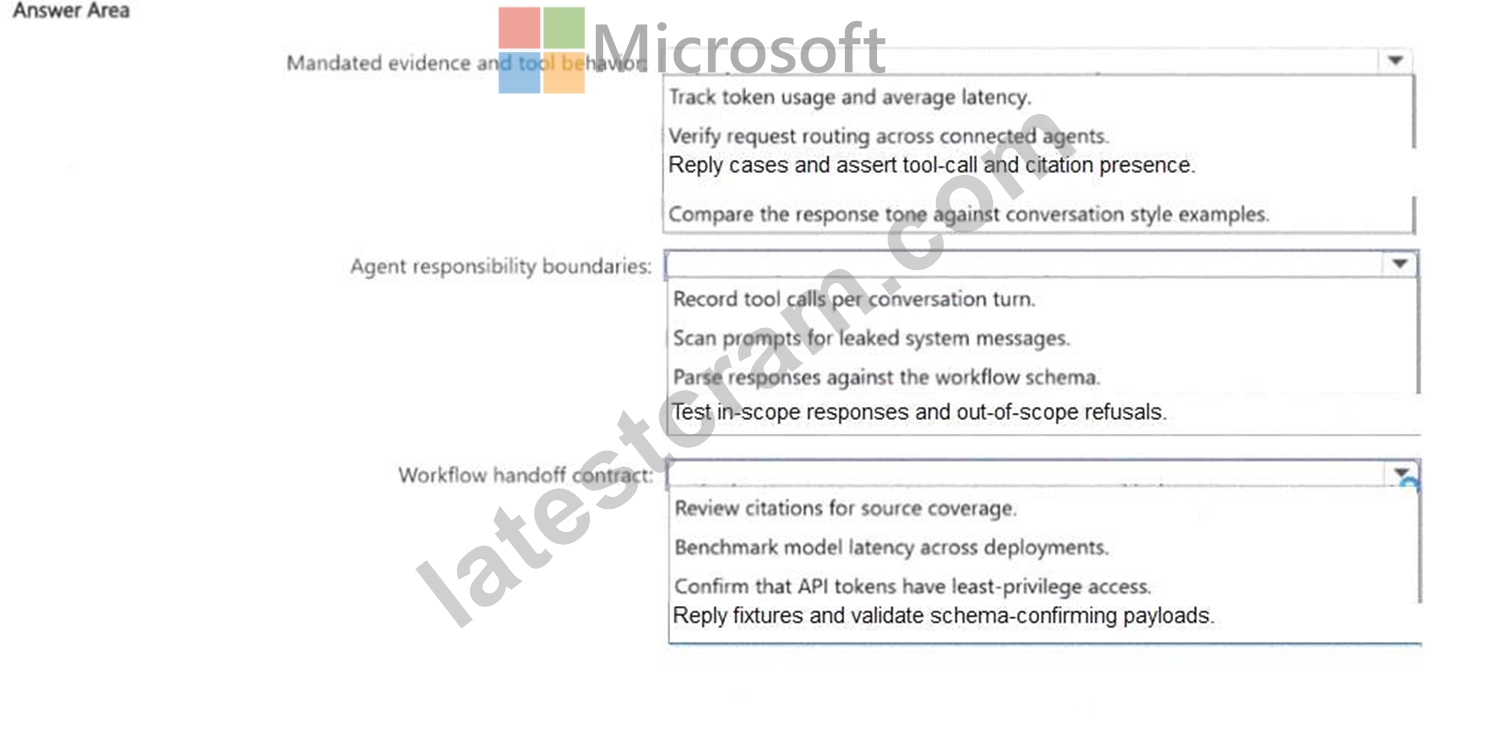
Answer:
Explanation: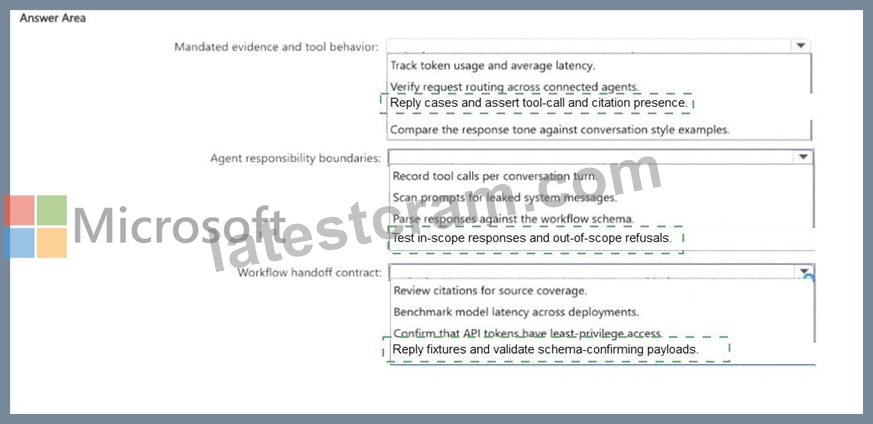
Explanation:
Mandated evidence/tool behavior: Replay cases and assert tool-call and citation presence; Agent responsibility boundaries: Test in-scope responses and out-of-scope refusals; Workflow handoff contract: Replay fixtures and validate schema-conforming payloads.
The three regressions target different interfaces and should be evaluated with tests that directly observe those interfaces. Required evidence gathering is a process behavior, so replayed cases should assert that mandated tool calls and citations occur. Responsibility boundaries are best tested with both positive and negative prompts: in-scope cases must be handled, while out-of-scope work should be refused or redirected. The JSON handoff is an interface contract, so replay fixtures should be validated against the expected schema to catch missing fields, renamed properties, and type changes before downstream agents fail. Microsoft Foundry ' s agent evaluators and evaluation datasets support process-level tool checks, task-adherence checks, and structured regression testing. The supplied mappings therefore correctly align each evaluation technique with the failure it is intended to detect. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - built-in evaluators and evaluation datasets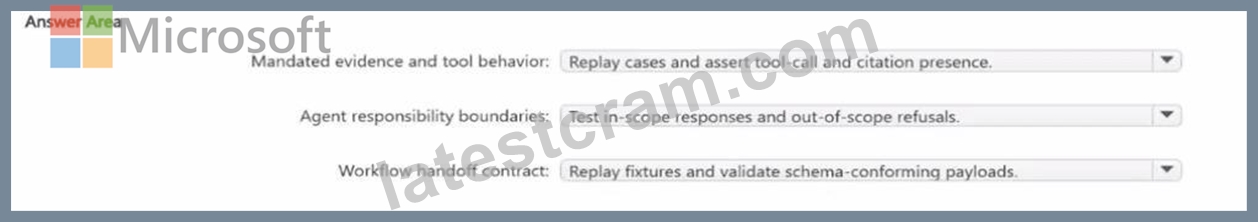
NEW QUESTION # 76
You have a Microsoft Foundry multi-agent solution for loan applications. Each agent scores a full application independently and does NOT require output from other agents.
You need to recommend an orchestration pattern that meets the following requirements:
Produces one aggregated recommendation
Preserves independent scoring -
Minimizes end-to-end latency -
Minimize development effort -
What should you recommend?
Answer: D
Explanation:
The scoring agents do not depend on each other ' s output, so their work should be fanned out in parallel and aggregated afterward. Microsoft Agent Framework concurrent orchestration is intended for independent participants that can process the same input simultaneously. That minimizes end-to-end latency because completion time approaches the slowest individual scorer instead of the sum of all scorers. The concurrent workflow also provides a fan-in stage that can aggregate the separate scores into one recommendation without requiring a complex custom conversation protocol. Sequential orchestration wastes time by serializing independent work. Group chat and Magentic-style collaboration introduce unnecessary coordination and planning overhead when the agents simply need independent scoring. Therefore D, concurrent, is the simplest and fastest orchestration pattern. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Microsoft Agent Framework - Concurrent orchestration
NEW QUESTION # 77
You have a multi-agent customer support solution in a Microsoft Foundry project.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in evaluators that provide 1 to-5 scores with pass/fail labels for the following metrics:
* The quality of the retrieved context
* How directly a response answers a query
Which evaluator should you use for each metric? To answer, drag the appropriate evaluators to the correct metrics. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.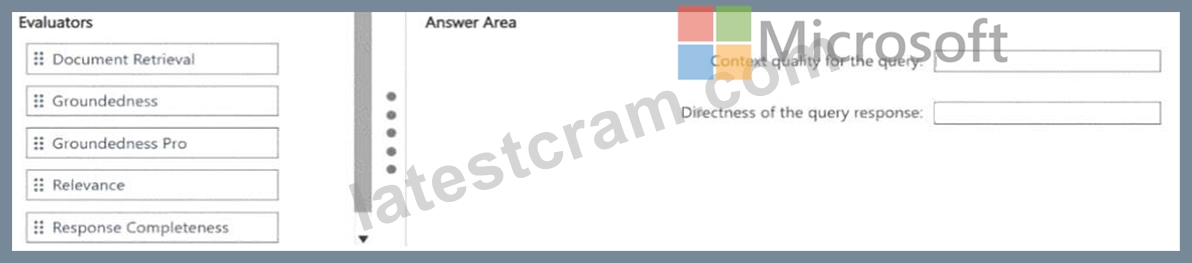
Answer:
Explanation: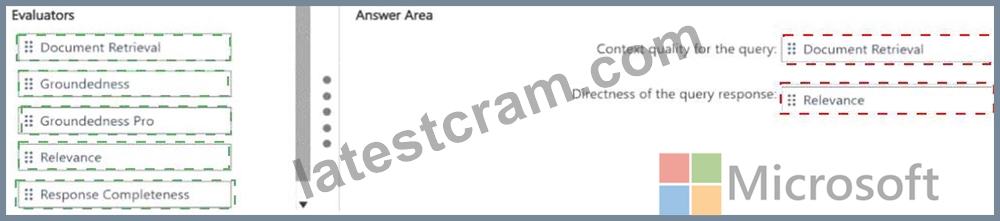
Explanation:
Quality of retrieved context: Retrieval evaluator; Directness of response to query: Relevance evaluator.
The dataset contains query, context, and response but does not contain document relevance labels. Microsoft ' s Retrieval evaluator is designed for exactly that situation: it uses an LLM judge to rate how relevant the retrieved context chunks are to the query and returns a 1-to-5 score with pass/fail behavior. The Relevance evaluator operates on the final response and measures whether the answer accurately, completely, and directly addresses the query. Document Retrieval is not appropriate because it requires retrieval ground truth such as known relevant documents or qrels. Groundedness answers a different question: whether response claims are supported by the provided context. Therefore the correct mapping is Retrieval for context quality and Relevance for response directness. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators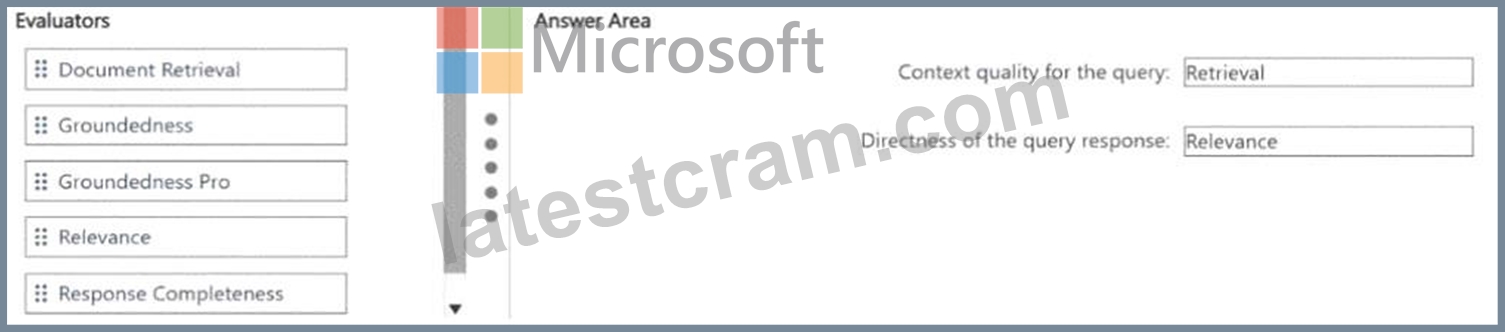
NEW QUESTION # 78
......
LatestCram provide you with the comprehensive Microsoft AI-500 Exam information to help you to succeed. Our training materials are the latest study materials which bring by experts. We help you achieve your success. You can get the most detailed and accurate exam questions and answers from us. Our Training Tools are updated in a timely manner in accordance with the changing of Exam Objectives. In fact, the success is not far away, go down along with LatestCram, then you will come to the road to success.
AI-500 Latest Study Materials: https://www.latestcram.com/AI-500-exam-cram-questions.html