Certified-Data-Engineer-Professional Deutsch Prüfung & Certified-Data-Engineer-Professional Trainingsunterlagen

Um unsere PrüfungFrage eine der zuverlässigen Merken im Gebiet der IT zu werden, bieten wir Sie die vollständigsten und die neusten Prüfungsaufgaben der Databricks Certified-Data-Engineer-Professional. Mit Hilfe unserer Softwaren bestanden fast alle Käufer Databricks Certified-Data-Engineer-Professional, die als eine sehr schwere Prüfung gilt, mit Erfolg. Deshalb haben wir Konfidenz, Ihnen unseren Produkten zu empfehlen. Wir können noch garantieren, falls Sie die Databricks Certified-Data-Engineer-Professional mit Hilfe unserer Software noch nicht bestehen, geben wir Ihnen die volle Gebühren zurück. Alles in allem hoffen wir, dass Sie sich beruhigt vorbereiten.
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
- Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use row filters and column masks to protect sensitive table data
|
| Topic 2: Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Create pipeline components using control flow operators such as if/else and foreach
- 2. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 3. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 4. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 5. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 6. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 7. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 8. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- Using Python and Tools for Development
- 1. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
|
| Topic 3: Monitoring and Alerting | - Monitoring
- 1. Use Query Profile and Spark UI to monitor workloads
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use system tables for observability of resource utilization, cost, auditing, and workloads
- Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
|
| Topic 4: Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Simplify data layout decisions and optimize query performance using liquid clustering
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Design dimensional models for analytical workloads with efficient querying and aggregation
|
| Topic 5: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
|
| Topic 6: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Topic 7: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 8: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Topic 9: Cost & Performance Optimization | - Optimize cost and performance
- 1. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 2. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Apply Change Data Feed to address streaming table limitations and improve latency
- 5. Understand Delta optimization techniques such as deletion vectors and liquid clustering
|
| Topic 10: Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
>> Certified-Data-Engineer-Professional Deutsch Prüfung <<
Neuester und gültiger Certified-Data-Engineer-Professional Test VCE Motoren-Dumps und Certified-Data-Engineer-Professional neueste Testfragen für die IT-Prüfungen
PrüfungFrage ist eine Website, die Bequemlichkeiten für die Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung bietet. Nach den Forschungen über die Fragen und Antworten in den letzten Jahren kann PrüfungFrage die Themen zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung effektiv erfassen. Die Databricks Certified-Data-Engineer-Professional Prüfungsübungen haben eine große Ähnlichkeit mit realen Prüfungen.
Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional Prüfungsfragen mit Lösungen (Q246-Q251):
246. Frage
A data ingestion task requires a one-TB JSON dataset to be written out to Parquet with a target part-file size of 512 MB. Because Parquet is being used instead of Delta Lake, built-in file-sizing features such as Auto-Optimize & Auto-Compaction cannot be used.
Which strategy will yield the best performance without shuffling data?
- A. Set spark.sql.adaptive.advisoryPartitionSizeInBytes to 512 MB bytes, ingest the data, execute the narrow transformations, coalesce to 2,048 partitions (1TB*1024*1024/512), and then write to parquet.
- B. Ingest the data, execute the narrow transformations, repartition to 2,048 partitions (1TB*
1024*1024/512), and then write to parquet. - C. Set spark.sql.shuffle.partitions to 2,048 partitions (1TB*1024*1024/512), ingest the data, execute the narrow transformations, optimize the data by sorting it (which automatically repartitions the data), and then write to parquet.
- D. Set spark.sql.shuffle.partitions to 512, ingest the data, execute the narrow transformations, and then write to parquet.
- E. Set spark.sql.files.maxPartitionBytes to 512 MB, ingest the data, execute the narrow transformations, and then write to parquet.
Antwort: C
Begründung:
The key to efficiently converting a large JSON dataset to Parquet files of a specific size without shuffling data lies in controlling the size of the output files directly. Setting spark.sql.files.maxPartitionBytes to 512 MB configures Spark to process data in chunks of 512 MB. This setting directly influences the size of the part-files in the output, aligning with the target file size.
Narrow transformations (which do not involve shuffling data across partitions) can then be applied to this data.
Writing the data out to Parquet will result in files that are approximately the size specified by spark.sql.files.maxPartitionBytes, in this case, 512 MB. The other options involve unnecessary shuffles or repartitions (B, C, D) or an incorrect setting for this specific requirement (E).
247. Frage
A table is registered with the following code:
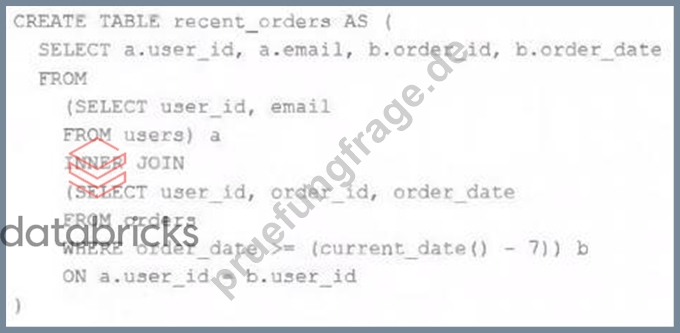
Both users and orders are Delta Lake tables. Which statement describes the results of querying recent_orders?
- A. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query began.
- B. All logic will execute when the table is defined and store the result of joining tables to the DBFS; this stored data will be returned when the table is queried.
- C. Results will be computed and cached when the table is defined; these cached results will incrementally update as new records are inserted into source tables.
- D. The versions of each source table will be stored in the table transaction log; query results will be saved to DBFS with each query.
- E. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query finishes.
Antwort: B
Begründung:
Table is created and data of join will be stored on DBFS and it will be returned on query time.
248. Frage
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).
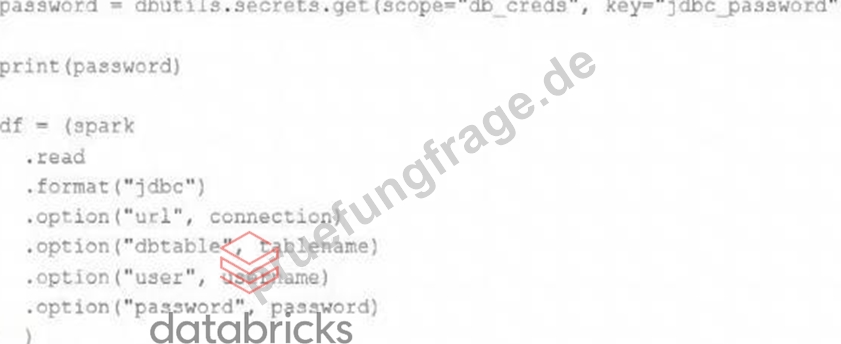
Which statement describes what will happen when the above code is executed?
- A. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the encoded password will be saved to DBFS.
- B. The connection to the external table will succeed; the string value of password will be printed in plain text.
- C. The connection to the external table will fail; the string "redacted" will be printed.
- D. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the password will be printed in plain text.
- E. The connection to the external table will succeed; the string "redacted" will be printed.
Antwort: E
Begründung:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks.
249. Frage
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in the geo_lookup table.
Before executing the code, running SHOW TABLES on the current database indicates the database contains only two tables: geo_lookup and sales.
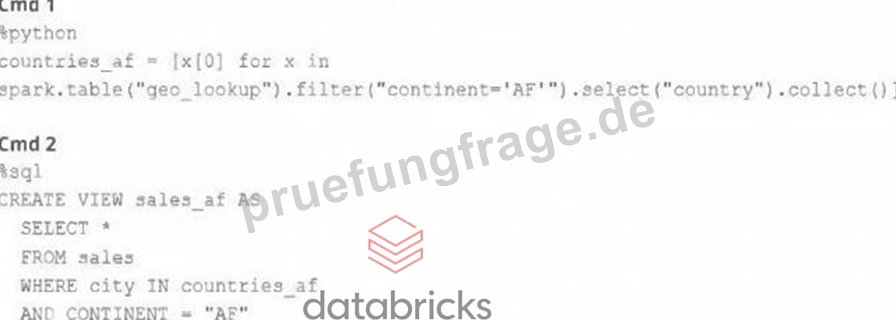
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
- A. Both commands will fail. No new variables, tables, or views will be created.
- B. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable representing a PySpark DataFrame.
- C. Cmd 1 will succeed. Cmd 2 will search all accessible databases for a table or view named countries af: if this entity exists, Cmd 2 will succeed.
- D. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable containing a list of strings.
- E. Both commands will succeed. Executing show tables will show that countries at and sales at have been registered as views.
Antwort: D
Begründung:
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view.
Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variable as a parameter.
250. Frage
Which statement describes the default execution mode for Databricks Auto Loader?
- A. Webhook trigger Databricks job to run anytime new data arrives in a source directory; new data automatically merged into target tables using rules inferred from the data.
- B. Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; new files are incrementally and impotently into the target Delta Lake table.
- C. New files are identified by listing the input directory; new files are incrementally and idempotently loaded into the target Delta Lake table.
- D. Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; the target table is materialized by directly querying all valid files in the source directory.
- E. New files are identified by listing the input directory; the target table is materialized by directory querying all valid files in the source directory.
Antwort: C
Begründung:
Databricks Auto Loader simplifies and automates the process of loading data into Delta Lake.
The default execution mode of the Auto Loader identifies new files by listing the input directory. It incrementally and idempotently loads these new files into the target Delta Lake table. This approach ensures that files are not missed and are processed exactly once, avoiding data duplication. The other options describe different mechanisms or integrations that are not part of the default behavior of the Auto Loader.
251. Frage
......
Sie brauchen nicht die komplizierte Ordnungsarbeit machen. Sie brauchen nicht für eine lange Zeit warten. Auf unserer Webseite können Sie die neueste und zuverlässigste Prüfungsunterlagen für Databricks Certified-Data-Engineer-Professional erhalten. Unterschiedliche Versionen bieten Ihnen unterschiedliche Emfindungen. Was zweifellos ist, dass alle Versionen von Databricks Certified-Data-Engineer-Professional sind effektiv. Bezahlen Sie mit gesichertem Zahlungsmittel Paypal! Dann können Sie gleich die Databricks Certified-Data-Engineer-Professional Prüfungsunterlagen herunterlagen und benutzen!
Certified-Data-Engineer-Professional Trainingsunterlagen: https://www.pruefungfrage.de/Certified-Data-Engineer-Professional-dumps-deutsch.html
- Certified-Data-Engineer-Professional Trainingsmaterialien: Databricks Certified Data Engineer Professional - Certified-Data-Engineer-Professional Lernmittel - Databricks Certified-Data-Engineer-Professional Quiz 🏵 URL kopieren “ www.pass4test.de ” Öffnen und suchen Sie ( Certified-Data-Engineer-Professional ) Kostenloser Download 🧞Certified-Data-Engineer-Professional Trainingsunterlagen
- Aktuelle Databricks Certified-Data-Engineer-Professional Prüfung pdf Torrent für Certified-Data-Engineer-Professional Examen Erfolg prep ⚗ Erhalten Sie den kostenlosen Download von 【 Certified-Data-Engineer-Professional 】 mühelos über ⏩ www.itzert.com ⏪ 💧Certified-Data-Engineer-Professional Echte Fragen
- Die anspruchsvolle Certified-Data-Engineer-Professional echte Prüfungsfragen von uns garantiert Ihre bessere Berufsaussichten! 🔐 Suchen Sie auf ➡ www.it-pruefung.com ️⬅️ nach kostenlosem Download von “ Certified-Data-Engineer-Professional ” 🧕Certified-Data-Engineer-Professional Praxisprüfung
- Certified-Data-Engineer-Professional Trainingsunterlagen 🦯 Certified-Data-Engineer-Professional Prüfungsmaterialien 🕡 Certified-Data-Engineer-Professional Übungsmaterialien 🧿 Öffnen Sie die Webseite ☀ www.itzert.com ️☀️ und suchen Sie nach kostenloser Download von ⮆ Certified-Data-Engineer-Professional ⮄ 🟫Certified-Data-Engineer-Professional Fragen&Antworten
- Certified-Data-Engineer-Professional Prüfungsfragen Prüfungsvorbereitungen 2026: Databricks Certified Data Engineer Professional - Zertifizierungsprüfung Databricks Certified-Data-Engineer-Professional in Deutsch Englisch pdf downloaden ☢ Suchen Sie jetzt auf ⇛ www.deutschpruefung.com ⇚ nach 「 Certified-Data-Engineer-Professional 」 um den kostenlosen Download zu erhalten 🛐Certified-Data-Engineer-Professional Musterprüfungsfragen
- Certified-Data-Engineer-Professional Testantworten 🔭 Certified-Data-Engineer-Professional Trainingsunterlagen 💙 Certified-Data-Engineer-Professional Prüfungsfragen ⛅ Suchen Sie jetzt auf ⮆ www.itzert.com ⮄ nach ➤ Certified-Data-Engineer-Professional ⮘ um den kostenlosen Download zu erhalten 🦺Certified-Data-Engineer-Professional Testantworten
- Kostenlose Databricks Certified Data Engineer Professional vce dumps - neueste Certified-Data-Engineer-Professional examcollection Dumps 🔍 URL kopieren ➥ www.pruefungfrage.de 🡄 Öffnen und suchen Sie ⮆ Certified-Data-Engineer-Professional ⮄ Kostenloser Download 😖Certified-Data-Engineer-Professional Deutsche
- Certified-Data-Engineer-Professional Dumps 🔑 Certified-Data-Engineer-Professional Musterprüfungsfragen 🪁 Certified-Data-Engineer-Professional Deutsche 🦽 Sie müssen nur zu ⏩ www.itzert.com ⏪ gehen um nach kostenloser Download von “ Certified-Data-Engineer-Professional ” zu suchen ⏮Certified-Data-Engineer-Professional Zertifizierungsprüfung
- Certified-Data-Engineer-Professional Zertifizierungsprüfung 💖 Certified-Data-Engineer-Professional Dumps 🎽 Certified-Data-Engineer-Professional Quizfragen Und Antworten 🧱 Öffnen Sie die Webseite “ www.examfragen.de ” und suchen Sie nach kostenloser Download von ➥ Certified-Data-Engineer-Professional 🡄 🚗Certified-Data-Engineer-Professional Echte Fragen
- Aktuelle Databricks Certified-Data-Engineer-Professional Prüfung pdf Torrent für Certified-Data-Engineer-Professional Examen Erfolg prep 🚢 Sie müssen nur zu ➤ www.itzert.com ⮘ gehen um nach kostenloser Download von ➤ Certified-Data-Engineer-Professional ⮘ zu suchen 🥭Certified-Data-Engineer-Professional Deutsche
- Databricks Certified-Data-Engineer-Professional Prüfung Übungen und Antworten 🎐 Suchen Sie jetzt auf “ www.zertpruefung.ch ” nach [ Certified-Data-Engineer-Professional ] und laden Sie es kostenlos herunter 🤹Certified-Data-Engineer-Professional PDF Demo
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, ifidir.com, mayagriffiths253.blogspot.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes