BTW, DOWNLOAD part of PassTestking DP-800 dumps from Cloud Storage: https://drive.google.com/open?id=1RKqleCrT-qpH5ND0XWbZRonB7yJMP1l3
DP-800 questions & answers cover all the key points of the real test. With the DP-800 training pdf, you can get the knowledge you want in the actual test, so you do not need any other study material. If the DP-800 exam is coming and the time is tense, it is better to choose our DP-800 Test Engine dumps. DP-800 test engine can simulate the actual test during the preparation and record the wrong questions for our reviewing. You just need 20-30 hours for preparation and feel confident to face the DP-800 actual test.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Reliable DP-800 Exam Review <<
If you want to pass the exam quickly, our DP-800 practice engine is your best choice. We know that many users do not have a large amount of time to learn. In response to this, we have scientifically set the content of the DP-800 exam questions. On one hand, we have collected the most important keypoints which will definitely show up in the real exam to the content of the DP-800 learning guide. On the other hand, we have simplified the content and make it better to be understood by all of the customers.
NEW QUESTION # 36
You have a SQL database in Microsoft Fabric that contains a table named WebSite. Logs. WebSite.Logs stores application telemetry data. Website.Logs contains a nvarehar(iMx) column named log that stores JSON documents You have a daily report that filters by the $.severity JSON property and returns Logld. LogDateTime, and log.
The report frequently causes full table scans.
You need to modify Website. Logs to support efficient filtering by $. severity and avoid key lookups for the columns returned by the report.
How should you complete the Transact-SQL code to avoid full table scans? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.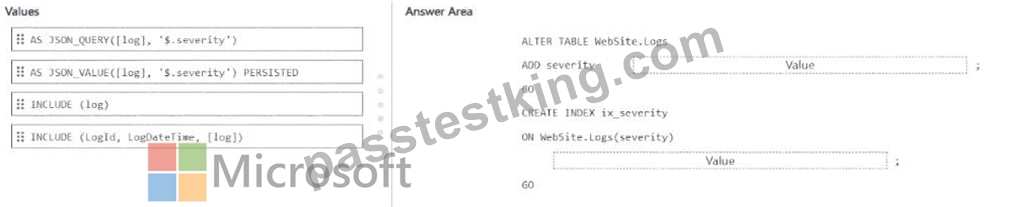
Answer:
Explanation: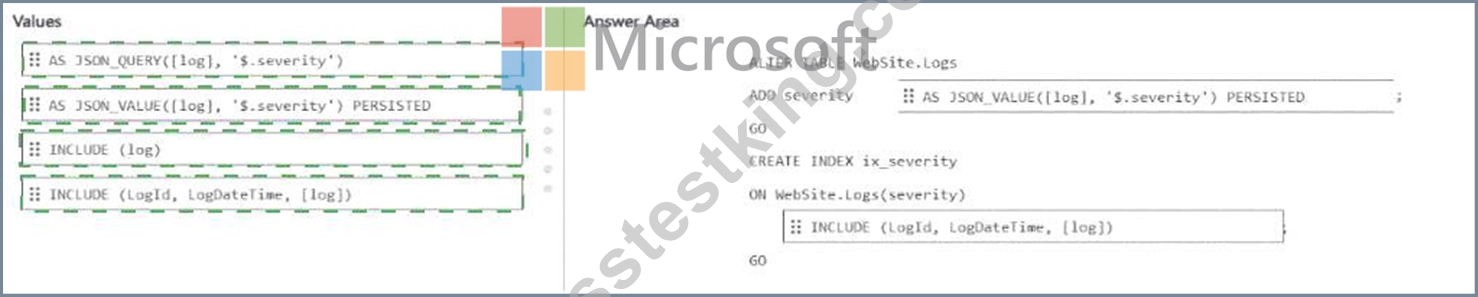
Explanation: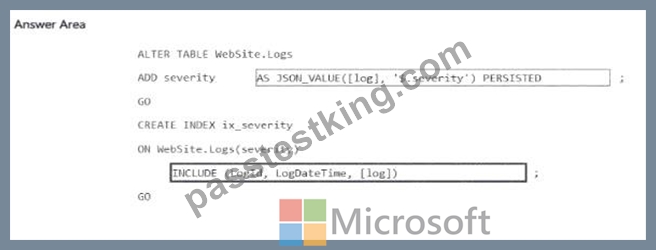
The correct way to avoid full table scans here is to add a computed column that extracts the JSON scalar property with JSON_VALUE , and then create a nonclustered index on that computed column with the report's returned columns in the INCLUDE list. Microsoft's JSON indexing guidance specifically recommends creating a computed column that exposes the JSON property you filter on, using the same expression as in the query, and then indexing that computed column.
So the computed column must be:
AS JSON_VALUE([log], ' $.severity ' ) PERSISTED
This is correct because $.severity is a scalar JSON value, so JSON_VALUE is the proper function.
JSON_QUERY would be for extracting an object or array, not a scalar property. Microsoft also notes that persisted computed columns can improve access speed for JSON-derived values.
The index should then include:
INCLUDE (LogId, LogDateTime, [log])
That is the right covering strategy because the report filters by severity but returns LogId, LogDateTime, and log. Microsoft's guidance on included columns explains that nonkey included columns let a nonclustered index cover more queries and reduce extra lookups to the base table.
So the completed code is:
ALTER TABLE WebSite.Logs
ADD severity AS JSON_VALUE([log], ' $.severity ' ) PERSISTED;
GO
CREATE INDEX ix_severity
ON WebSite.Logs(severity)
INCLUDE (LogId, LogDateTime, [log]);
GO
NEW QUESTION # 37
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders, dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.orders.
Solution: Identify the partition number for the oldest month, and then run the following Transact-SQL statement.
TRUNCATE TABIE dbo.Orders
WITH (PARTITIONS (partition number));
Does this meet the goal?
Answer: A
Explanation:
Yes, this meets the goal. Microsoft documents that on a partitioned table , you can use TRUNCATE TABLE ... WITH (PARTITIONS (...)) to remove data from a specific partition, and that this is an efficient maintenance operation that targets only that data subset rather than the whole table. Microsoft's partitioning guidance explicitly lists truncating a single partition as an example of a fast partition-level maintenance or retention operation.
That matches the requirement to remove the oldest month while minimizing impact on other queries.
Because the table is already partitioned by month on OrderDate , identifying the partition number for that oldest month and truncating only that partition is the correct low-impact approach, assuming the table and indexes are aligned as required for partition truncation.
NEW QUESTION # 38
You have an Azure SQL database that contains a table named Table1. Table1 contains 25,000,000 rows of data and a datetime2 column named DateKey. The data in Table1 spans the years 2020 through 2021.
You need to partition the data in Table1 by year. The solution must minimize how long it takes to rebuild or reindex the table.
How should you complete the Transact-SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.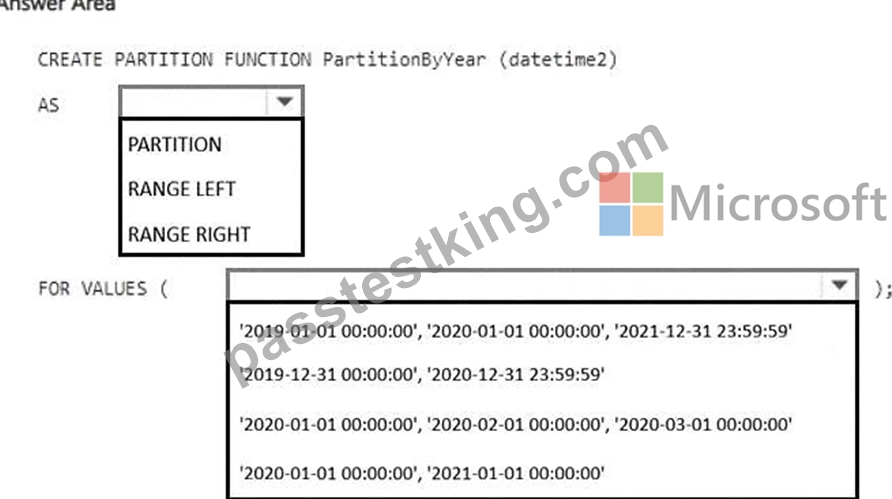
Answer:
Explanation: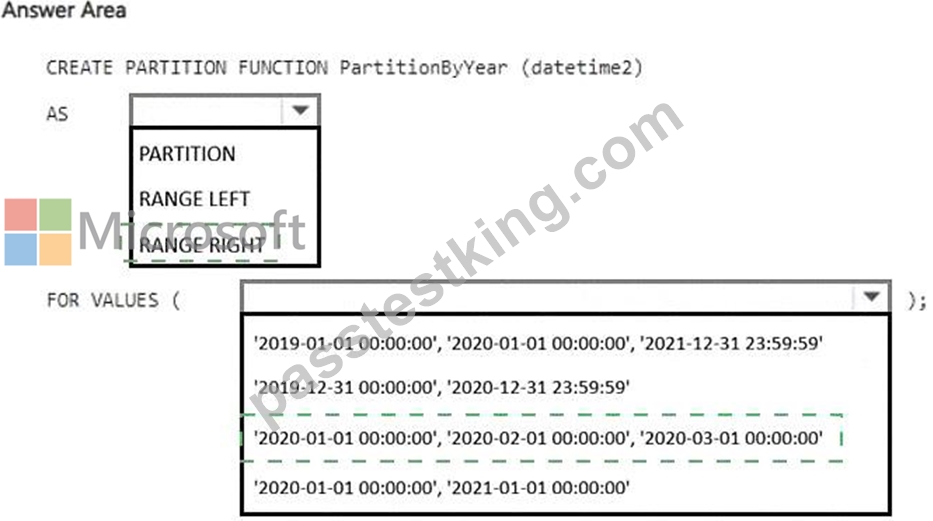
Explanation:
* Partition range # RANGE RIGHT
* Boundary values # ' 2020-01-01 00:00:00 ' , ' 2021-01-01 00:00:00 '
Comprehensive and Detailed Explanation with all Developing AI-Enabled Database Solutions documents : = The correct configuration is to use RANGE RIGHT with boundary values at the start of each year :
CREATE PARTITION FUNCTION PartitionByYear (datetime2)
AS RANGE RIGHT
FOR VALUES (
' 2020-01-01 00:00:00 ' ,
' 2021-01-01 00:00:00 '
);
Microsoft documents that with RANGE RIGHT , each boundary value belongs to the partition on its right .
For date-based partitioning, this is the natural pattern because a boundary such as 2021-01-01 becomes the lower boundary of the 2021 partition.
With these boundaries, the resulting ranges are effectively:
* Partition 1: dates before 2020-01-01
* Partition 2: 2020-01-01 through before 2021-01-01
* Partition 3: 2021-01-01 and later
This cleanly separates the 2020 and 2021 data into year-aligned partitions. Microsoft specifically recommends RANGE RIGHT for date-based boundaries because the first day of a period remains in the same partition as the rest of that period.
The other boundary choices are incorrect or less appropriate:
* Using year-end timestamps with RANGE LEFT is more cumbersome and can be sensitive to datetime2 precision.
* Monthly boundaries would partition by month, not year.
* Including 2019 and a 2021-12-31 23:59:59 boundary creates unnecessary partitions and is not the cleanest year-based design.
Therefore:
* First dropdown: RANGE RIGHT
* Second dropdown: ' 2020-01-01 00:00:00 ' , ' 2021-01-01 00:00:00 '
NEW QUESTION # 39
You have an Azure SQL database that contains a table named knowledgebase, knowledgebase stores human resources (HR) policy documents and contains columns named title, content, category, and embedding.
You have an application named App1. App1 queries two relational tables named employee_pnofiles and benefits_enrollnent that contain HR data. App1 hosts a chatbot that calls a large language model (LLM) directly.
Users report that the chatbot answers general HR questions correctly but provides outdated or incorrect answers when policies change. The chatbot also fails to answer questions that reference internal policy documents by title or category.
You need to recommend a Retrieval Augmented Generation (RAG) solution to resolve the chatbot issues.
What should you recommend? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation: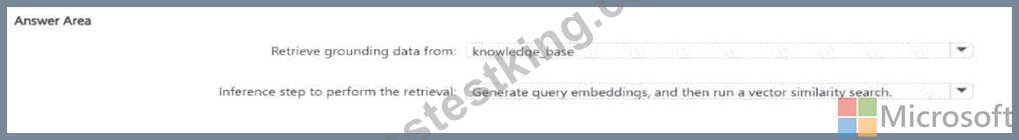
The correct recommendation is to retrieve grounding data from knowledge_base and, at inference time, generate query embeddings and run a vector similarity search .
The chatbot currently answers some general HR questions but fails when policies change and when users ask about internal policy documents by title or category . That is exactly the kind of problem RAG is meant to solve: ground the LLM in the organization's proprietary content instead of relying on the model's training data or unrelated transactional tables. Microsoft's RAG guidance states that RAG extends LLMs by grounding responses in your own content and that, for agentic retrieval, knowledge bases unify knowledge sources for retrieval.
So the grounding data should come from knowledge_base , because that table stores the HR policy documents and already includes fields like title, content, category, and embedding. Those are the fields directly tied to the missing and outdated policy answers. By contrast:
* employee_profiles and benefits_enrollment are operational HR tables, not the authoritative store for policy-document grounding.
* PDF exports of the policies would be inferior to querying the indexed/structured knowledge base already prepared for retrieval.
* The LLM training data is specifically the wrong source when the issue is outdated internal content.
For the retrieval step, Microsoft's guidance says to use embeddings for vector queries and notes that vector similarity search matches concepts, not exact terms . This is especially important because users ask about policy documents by title or category and also phrase questions in ways that might not exactly match document wording. Generating a query embedding and then running a vector similarity search is the appropriate retrieval step in a RAG pipeline.
NEW QUESTION # 40
You have a SQL database in Microsoft Fabric that contains a table named WebSite. Logs. WebSite.Logs stores application telemetry data. Website.Logs contains a nvarehar(iMx) column named log that stores JSON documents You have a daily report that filters by the $.severity JSON property and returns Logld. LogDateTime, and log.
The report frequently causes full table scans.
You need to modify Website. Logs to support efficient filtering by $. severity and avoid key lookups for the columns returned by the report.
How should you complete the Transact-SQL code to avoid full table scans? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.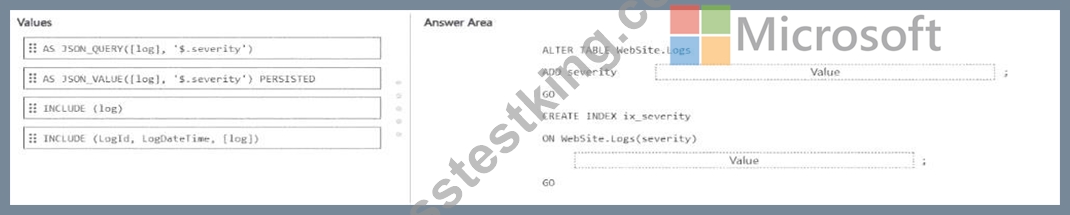
Answer:
Explanation: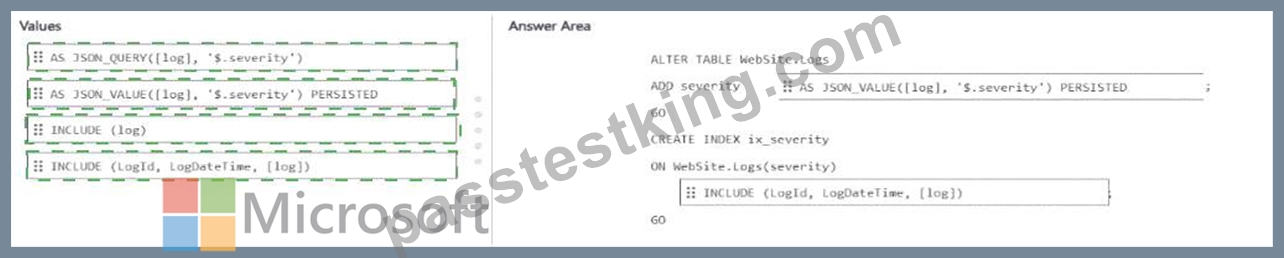
Explanation: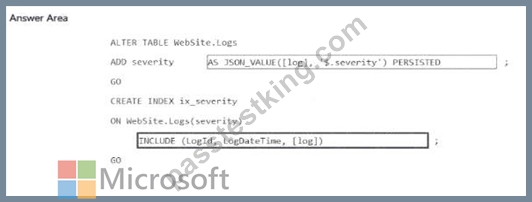
The correct way to avoid full table scans here is to add a computed column that extracts the JSON scalar property with JSON_VALUE, and then create a nonclustered index on that computed column with the report' s returned columns in the INCLUDE list. Microsoft's JSON indexing guidance specifically recommends creating a computed column that exposes the JSON property you filter on, using the same expression as in the query, and then indexing that computed column.
So the computed column must be:
AS JSON_VALUE([log], ' $.severity ' ) PERSISTED
This is correct because $.severity is a scalar JSON value, so JSON_VALUE is the proper function.
JSON_QUERY would be for extracting an object or array, not a scalar property. Microsoft also notes that persisted computed columns can improve access speed for JSON-derived values.
The index should then include:
INCLUDE (LogId, LogDateTime, [log])
That is the right covering strategy because the report filters by severity but returns LogId, LogDateTime, and log. Microsoft's guidance on included columns explains that nonkey included columns let a nonclustered index cover more queries and reduce extra lookups to the base table.
So the completed code is:
ALTER TABLE WebSite.Logs
ADD severity AS JSON_VALUE([log], ' $.severity ' ) PERSISTED;
GO
CREATE INDEX ix_severity
ON WebSite.Logs(severity)
INCLUDE (LogId, LogDateTime, [log]);
GO
NEW QUESTION # 41
......
All our three versions are paramount versions. PDF version of DP-800 practice questions - it is legible to read and remember, and support customers’ printing request, so you can have a print and practice in papers. Software version of DP-800 guide materials - It support simulation test system, and times of setup has no restriction. Remember this version support Windows system users only. App online version of DP-800 study quiz - Be suitable to all kinds of equipment or digital devices.
DP-800 Latest Study Materials: https://www.passtestking.com/Microsoft/DP-800-practice-exam-dumps.html
P.S. Free 2026 Microsoft DP-800 dumps are available on Google Drive shared by PassTestking: https://drive.google.com/open?id=1RKqleCrT-qpH5ND0XWbZRonB7yJMP1l3