BTW, DOWNLOAD part of ITExamDownload Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1zCVo0ee5Rf48mw7lh7QndtHf9B77bZNp
It is known to us that the Professional-Machine-Learning-Engineer exam has been increasingly significant for modern people in this highly competitive word, because the Professional-Machine-Learning-Engineer test certification can certify whether you have the competitive advantage in the global labor market or have the ability to handle the job in a certain area, especial when we enter into a newly computer era. Therefore our Professional-Machine-Learning-Engineer practice torrent is tailor-designed for these learning groups, thus helping them pass the Professional-Machine-Learning-Engineer exam in a more productive and efficient way and achieve success in their workplace.
| Section | Objectives |
|---|---|
| Topic 1: Collaborating within and across teams to manage data and models | - Collaboration between Data Scientists, Data Engineers, and ML Engineers - Version control and reproducibility (e.g., DVC, MLOps) - Data management and governance |
| Topic 2: Serving and scaling models | - Batch prediction - Hardware accelerators (GPU/TPU) in serving - Model optimization (Quantization, Distillation) - Online prediction (Vertex AI Prediction) |
| Topic 3: Monitoring ML solutions | - Model retraining strategies - Performance monitoring and drift detection - Logging and alerting (Cloud Monitoring) |
| Topic 4: Automating and orchestrating ML pipelines | - Vertex AI Pipelines (Kubeflow Pipelines) - Triggering and scheduling pipelines - CI/CD for ML systems |
| Topic 5: Architecting low-code ML solutions | - Leveraging pre-built ML models as a service (e.g., Vision AI, Speech-to-Text, Recommendations AI) - AutoML capabilities and implementation - Implementing BigQuery ML for basic models |
| Topic 6: Scaling prototypes into ML models | - Training at scale (Distributed training, TPUs) - Frameworks (TensorFlow, PyTorch, JAX, Scikit-learn) - Hyperparameter tuning |
>> Test Professional-Machine-Learning-Engineer Answers <<
Our ITExamDownload's Professional-Machine-Learning-Engineer exam training material is the leader of Professional-Machine-Learning-Engineer certification exam. Our Professional-Machine-Learning-Engineer exam training materials is the result of ITExamDownload's experienced IT experts with constant exploration, practice and research for many years. It has high accuracy and wide coverage. If you buy our Professional-Machine-Learning-Engineer Dumps PDF, we guarantee that we will provide one year free renewal service.
NEW QUESTION # 205
You are developing a machine learning pipeline using the Kubeflow Pipelines (KFP) SDK that will run on Agent Platform Pipelines. The pipeline includes a preprocessing component that takes two hours to transform a large dataset. You are currently iterating on the code for the subsequent model_training component and need to re-submit the pipeline frequently for testing. You need to ensure that the preprocessing component only re-runs if its inputs or parameters have changed.
You want to minimize effort, costs, and total execution time. What should you do?
Answer: D
Explanation:
Execution caching reuses the preprocessing component's previous successful output when its inputs, parameters, and component definition have not changed. This prevents the two-hour transformation from running during repeated pipeline tests, reducing both execution time and compute cost.
NEW QUESTION # 206
Your organization's call center has asked you to develop a model that analyzes customer sentiments in each call. The call center receives over one million calls daily, and data is stored in Cloud Storage. The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. You need to select components for data processing and for analytics. How should the data pipeline be designed?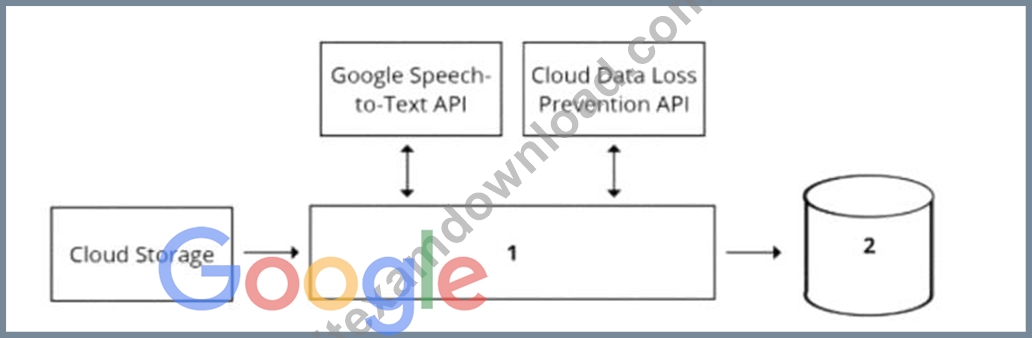
Answer: D
Explanation:
A data pipeline is a set of steps or processes that move data from one or more sources to one or more destinations, usually for the purpose of analysis, transformation, or storage. A data pipeline can be designed using various components, such as data sources, data processing tools, data storage systems, and data analytics tools1 To design a data pipeline for analyzing customer sentiments in each call, one should consider the following requirements and constraints:
* The call center receives over one million calls daily, and data is stored in Cloud Storage. This implies that the data is large, unstructured, and distributed, and requires a scalable and efficient data processing tool that can handle various types of data formats, such as audio, text, or image.
* The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. This implies that the data is sensitive and subject to data privacy and compliance regulations, and requires a secure and reliable data storage system that can enforce data encryption, access control, and regional policies.
* The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. This implies that the data analytics tool is external and independent of the data pipeline, and requires a standard and compatible data interface that can support SQL queries and operations.
One of the best options for selecting components for data processing and for analytics is to use Dataflow for data processing and BigQuery for analytics. Dataflow is a fully managed service for executing Apache Beam pipelines for data processing, such as batch or stream processing, extract-transform-load (ETL), or data integration. BigQuery is a serverless, scalable, and cost-effective data warehouse that allows you to run fast and complex queries on large-scale data23 Using Dataflow and BigQuery has several advantages for this use case:
* Dataflow can process large and unstructured data from Cloud Storage in a parallel and distributed manner, and apply various transformations, such as converting audio to text, extracting sentiment scores, or anonymizing PII. Dataflow can also handle both batch and stream processing, which can enable real-time or near-real-time analysis of the call data.
* BigQuery can store and analyze the processed data from Dataflow in a secure and reliable way, and enforce data encryption, access control, and regional policies. BigQuery can also support SQL
* ANSI-2011 compliant interface, which can enable the data science team to use their third-party tool for visualization and access. BigQuery can also integrate with various Google Cloud services and tools, such as AI Platform, Data Studio, or Looker.
* Dataflow and BigQuery can work seamlessly together, as they are both part of the Google Cloud ecosystem, and support various data formats, such as CSV, JSON, Avro, or Parquet. Dataflow and BigQuery can also leverage the benefits of Google Cloud infrastructure, such as scalability, performance, and cost-effectiveness.
The other options are not as suitable or feasible. Using Pub/Sub for data processing and Datastore for analytics is not ideal, as Pub/Sub is mainly designed for event-driven and asynchronous messaging, not data processing, and Datastore is mainly designed for low-latency and high-throughput key-value operations, not analytics.
Using Cloud Function for data processing and Cloud SQL for analytics is not optimal, as Cloud Function has limitations on the memory, CPU, and execution time, and does not support complex data processing, and Cloud SQL is a relational database service that may not scale well for large-scale data. Using Cloud Composer for data processing and Cloud SQL for analytics is not relevant, as Cloud Composer is mainly designed for orchestrating complex workflows across multiple systems, not data processing, and Cloud SQL is a relational database service that may not scale well for large-scale data.
References: 1: Data pipeline 2: Dataflow overview 3: BigQuery overview : [Dataflow documentation] :
[BigQuery documentation]
NEW QUESTION # 207
You recently deployed a scikit-learn model to a Vertex AI endpoint. You are now testing the model on live production traffic. While monitoring the endpoint, you discover twice as many requests per hour than expected throughout the day. You want the endpoint to efficiently scale when the demand increases in the future to prevent users from experiencing high latency. What should you do?
Answer: D
NEW QUESTION # 208
You work for a biotech startup that is experimenting with deep learning ML models based on properties of biological organisms. Your team frequently works on early-stage experiments with new architectures of ML models, and writes custom TensorFlow ops in C++. You train your models on large datasets and large batch sizes. Your typical batch size has 1024 examples, and each example is about 1 MB in size. The average size of a network with all weights and embeddings is 20 GB. What hardware should you choose for your models?
Answer: C
NEW QUESTION # 209
Your team is training a large number of ML models that use different algorithms, parameters and datasets.
Some models are trained in Vertex Ai Pipelines, and some are trained on Vertex Al Workbench notebook instances. Your team wants to compare the performance of the models across both services. You want to minimize the effort required to store the parameters and metrics What should you do?
Answer: D
Explanation:
Vertex AI Experiments is a service that allows you to track, compare, and manage experiments with Vertex AI. You can use Vertex AI Experiments to record the parameters, metrics, and artifacts of each model training run, and compare them in a graphical interface. Vertex AI Experiments supports models trained in Vertex AI Pipelines, Vertex AI Custom Training, and Vertex AI Workbench notebooks. To use Vertex AI Experiments, you need to create an experiment and submit your pipeline runs or custom training jobs as experiment runs.
For models trained on notebooks, you need to use the Vertex AI SDK to log the parameters and metrics to the experiment. This way, you can minimize the effort required to store and compare the model performance across different services. References : Track, compare, manage experiments with Vertex AI Experiments
, Vertex AI Pipelines: Metrics visualization and run comparison using the KFP SDK , [Vertex AI SDK for Python]
NEW QUESTION # 210
......
As everybody knows, competitions appear ubiquitously in current society. In order to live a better live, people improve themselves by furthering their study, as well as increase their professional Professional-Machine-Learning-Engineer skills. With so many methods can boost individual competitiveness, people may be confused, which can really bring them a glamorous work or brighter future? We are here to tell you that a Professional-Machine-Learning-Engineer Certification definitively has everything to gain and nothing to lose for everyone.
Professional-Machine-Learning-Engineer Test Lab Questions: https://www.itexamdownload.com/Professional-Machine-Learning-Engineer-valid-questions.html
BTW, DOWNLOAD part of ITExamDownload Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1zCVo0ee5Rf48mw7lh7QndtHf9B77bZNp